Neo4j
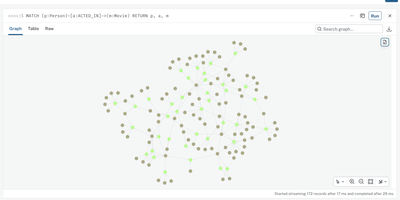
Some questions are really about how things connect, and Neo4j is the graph database that stores your data as nodes and relationships so those connections become the thing you query. Model people, products, accounts, devices, or transactions as labeled nodes with properties, then draw typed, directed relationships between them and traverse multi-hop paths in a single Cypher query instead of stacking SQL joins. The built-in Neo4j Browser renders query results as interactive node diagrams, so you can expand a fraud ring, a dependency chain, or a recommendation neighborhood visually and share the picture with your team. Cypher reads like the picture it queries: MATCH patterns describe shapes in the graph, filters narrow them, and aggregations roll up counts, sums, and shortest paths. Store embeddings as node properties and build vector indexes over them, then combine similarity search with graph traversal so matches can be filtered by owner, connections, or freshness. Full-text indexes search names, descriptions, and documents, while uniqueness constraints keep identifiers honest at write time. Bulk-load millions of nodes from CSV files with the offline import tool, then keep data flowing in through official drivers for Python, JavaScript, Java, Go, and .NET applications. Fraud teams trace shared phones and cards between accounts, platform teams map microservice dependencies before a migration, and security analysts hunt lateral movement through identity graphs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
SurrealDB
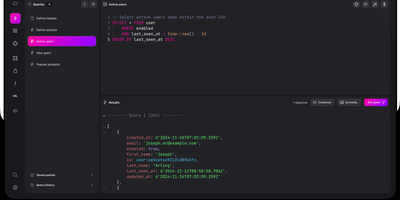
With 32,800 GitHub stars, 180 contributors, and version 3.2 shipping in July 2026, SurrealDB eliminates the database zoo by unifying document, graph, relational, time-series, geospatial, and key-value data models into a single Rust binary queried through SurrealQL — an intuitive SQL-like language that handles graph traversals, record links, subqueries, and computed fields without switching between multiple database engines. Purpose-built for AI applications, it integrates vector indexing, full-text search, and hybrid retrieval that blends semantic similarity with graph and relational intelligence for context-aware RAG pipelines and recommendation engines. Real-time subscriptions and event-driven triggers push live data changes to connected clients without requiring external message brokers like Kafka. Multi-row, multi-table ACID transactions guarantee consistency while incrementally computed views deliver pre-calculated analytics without batch processing. Role-based access control with record-level permissions, JWT authentication, and multi-tenant isolation enables backend-as-a-service usage where client applications connect directly with fine-grained security. SDKs for JavaScript, Python, Go, Rust, .NET, and Java connect via WebSocket or HTTP APIs. Storage and compute separation allows deployment as an embedded library, a single-node server, or a highly-scalable distributed cluster with TiKV or FoundationDB backends. Deploy via Docker with persistent volumes on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Source-available licensed.
RushDB
RushDB is a database your AI agents can actually understand, because it remembers the shape of everything you write. Send nested JSON and each object becomes a record, automatically linked to its parent, while field names, types, and values are cataloged on every write. Agents introspect that catalog before querying, so they ask questions the data can answer instead of hallucinating tables that never existed. The same records answer five query styles: a JSON query language, SQL over the PostgreSQL wire protocol, Cypher over HTTP or Bolt, Gremlin, and Mongo-style document queries. Vector, full-text, and hybrid search run against the same store, so an agent can find the record that mentions a phrase and the records merely similar to it. Everything ships as one binary with one data directory, speaking HTTP on port 3000, PostgreSQL on 5432, and Bolt on 7687 to the drivers and tools you already use. Point your SDKs, SQL clients, BI tools, or local MCP-connected agents at it, and back it up, replicate it, or restore to a point in time with the engine's own tooling. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.