Higress
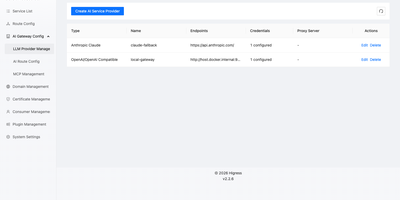
Send every AI request through one gateway that holds your model providers, API keys, and access rules. The web console starts with a first-run admin setup, then an LLM Provider page where OpenAI-compatible endpoints, Anthropic Claude, Azure OpenAI, Tongyi Qianwen, Moonshot, Zhipu, and other services are added with their tokens. AI Route Config maps path prefixes and model match rules to weighted target services, with token failover and first-packet timeouts to keep traffic moving when a key fails. Consumer Management issues key, OAuth2, and JWT credentials, and each route can limit access to named consumers. Plugin Management lists ready-made AI plugins for caching, context limits, data masking, prompt templates, prompt decorators, load balancing, and intent checks, plus traffic and security plugins that can be configured per route. MCP Management hosts MCP servers behind the same authentication and rate limits so agents call tools through one governed address. Service Sources import backends from Nacos, Zookeeper, Consul, Eureka, static addresses, or domains, and domain and certificate pages handle HTTPS, including free automatic certificates from Let's Encrypt. An LLM proxy for a product team, a shared model endpoint for several agents, or a replacement for an ingress controller all fit this console. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Nyro
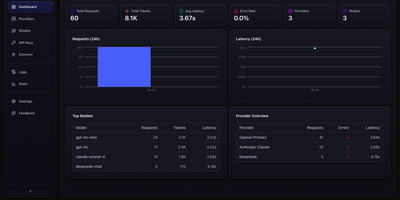
Point Claude Code, Codex CLI, Gemini CLI, or any OpenAI, Anthropic, or Gemini SDK at one address and Nyro routes every request to whichever model provider you choose. The gateway translates protocols on the fly, including streaming, reasoning blocks, and tool calls, so a tool built for one API can run on a model from another. Define virtual model names, bind each to one or more providers, and pick weighted load balancing or priority failover; unhealthy targets are skipped and recover automatically. Issue API keys with limits on requests and tokens per minute and per day, and bind each key only to the models it may call. Exact and semantic caching return repeated answers instantly. A request log records provider, model, token counts, latency, and streaming speed, and usage charts break traffic down by model and provider. The Connect page generates ready-to-paste samples in Python, TypeScript, and cURL, plus one-click configuration for popular coding CLIs. Choose an embedded database for a single host or an external PostgreSQL or MySQL server for production, and run the gateway, the admin UI, or both as separate processes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.