Apache DolphinScheduler
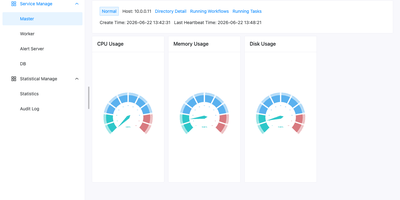
When nightly SQL, Spark, and Python jobs outgrow cron, Apache DolphinScheduler replaces the tangle with a visual workflow orchestrator where every dependency is a line on a drag-and-drop canvas. More than 30 built-in task types cover Shell, SQL, Python, HTTP, Spark, Flink, Kubernetes, SeaTunnel, and Jupyter, while logic nodes add sub-workflows, conditions, switches, and dependencies across projects. Workflows can also be written as code through a Python SDK, YAML, or the Open API and run on timezone-aware cron schedules. Backfill reruns a workflow across a date range or a hand-picked list of dates, in serial or parallel, and any instance can be modified, rolled back, and rerun without touching the saved template. Kill, pause, and resume running tasks, and choose whether a failure ends the run or lets parallel branches continue. Alert groups route results to Email, Slack, Telegram, PagerDuty, Feishu, DingTalk, webhooks, or custom scripts. Tenants, worker groups, and environments isolate teams on shared infrastructure, with project and data source permissions. A Resource Center stores scripts and task files locally or on HDFS, MinIO, and cloud object storage, and the monitor page shows master, worker, and database health at a glance. Standalone, Cluster, Docker, and Kubernetes deployments scale from one node to many masters and workers that can join or leave a running cluster. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Dagster
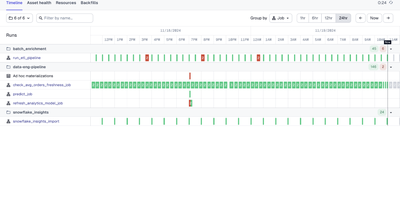
With nearly 16,000 GitHub stars, 5.7 million monthly PyPI downloads, and 400+ contributors, Dagster is the most widely adopted asset-centric data orchestration platform — replacing task-oriented schedulers like Apache Airflow with a declarative model where every pipeline is defined as Python functions producing data assets such as tables, datasets, machine learning models, and reports. The built-in asset graph provides automatic lineage tracking across your entire data platform, showing exactly how data flows from ingestion through transformation to downstream consumption in a single unified view. Declarative Automation goes beyond cron scheduling with event-driven conditions that intelligently trigger materializations based on upstream freshness, data quality signals, and dependency state. The integrated data catalog auto-generates documentation from asset metadata, ensuring it never drifts out of sync with production. Native first-class integrations connect dbt, Snowflake, BigQuery, Databricks, Fivetran, Airbyte, Spark, Great Expectations, Tableau, Power BI, AWS, GCP, and Azure without custom glue code. The web UI visualizes asset graphs, run history, schedules, sensors, and partitioned materializations with built-in alerting via Slack and PagerDuty. Dagster Pipes enables executing arbitrary code in external environments including Spark clusters, Kubernetes Jobs, and cloud functions. Deploy via Docker Compose on a single VM with separate containers for the webserver, daemon, and code locations, or use official Helm charts for production Kubernetes with K8sRunLauncher scaling each run as an independent Job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.