MuckScraper
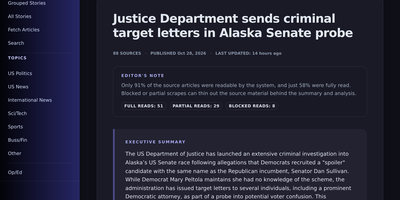
Reading the news should not mean opening twelve tabs about the same event, so MuckScraper folds every outlet's version into one story and shows you how the coverage differs. A scheduler fetches RSS feeds several times a day, with optional NewsAPI and GNews keys adding more sources, and each article is embedded and matched against recent stories so wire copies and follow-ups land together instead of flooding your feed. Every story carries a bias balance: how many left, center, and right outlets covered it, with each outlet rated from AllSides data or scored by the model where no rating exists. Local language models write the story summary and a deeper report comparing how each side frames the event, what is contested, and what nobody is mentioning, while guardrails reject cut-off summaries and figures that never appeared in the sources. Opinion columns stay in their own lane, linked to the stories they argue about and rounded up separately, never counted as news coverage. Twice a day the system publishes a balanced edition of twenty stories, and every past edition stays readable alongside full-text search across your whole archive. Reader, scraper, and admin roles decide who can simply read, who can trigger fetches, and who manages feeds, prompts, and users. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy