Portkey Gateway
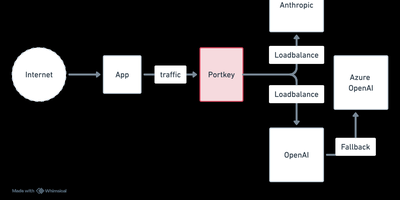
One OpenAI-compatible endpoint, 1,600+ models behind it: Portkey Gateway sits between your app and every major LLM provider, deciding in real time where each request should go. When a provider times out or returns errors, automatic retries with exponential backoff kick in, and fallback rules quietly move traffic to your second-choice model before users notice anything. Load balancing spreads calls across multiple API keys and providers by weight, conditional routing sends each request down a different path based on its content or metadata, and per-request timeouts cut off providers that hang. Guardrails inspect inputs and outputs as traffic passes through: block banned words, screen for sensitive content, and enforce the checks your compliance team asked for, with dozens of pre-built rules ready to attach. Text is only the start: the same API shape reaches vision models, speech-to-text, text-to-speech, image generation, and realtime websocket APIs, so multimodal features stop multiplying your integration work. Routing policies live in JSON configs you attach per request or per client, which means experiments, cost controls, and provider migrations ship as configuration changes, not redeploys. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy