Anysub
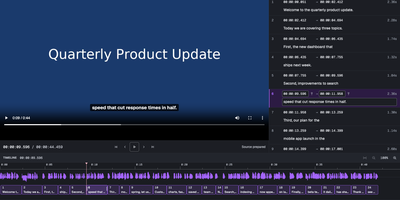
Need subtitles but not a cloud upload? Anysub transcribes audio and video with Whisper on your own server and hands back editable cues. Drop in a video or audio recording, pick a Whisper model from tiny to large, and the worker transcribes it with word-level timing. The studio then puts the video, the cue list, and a zoomable waveform timeline side by side, so every subtitle can be dragged, trimmed, split, merged, or retyped. Warnings flag cues that run too fast, too long, or overlap a neighbor, and autosave with undo keeps edits safe. Long uploads resume after a dropped connection, and the searchable library finds projects by name or by the words spoken inside them. Finished tracks export as SRT, WebVTT, plain text, or JSON with words and metadata. Administration pages manage model downloads, transcription defaults, upload limits, disk usage, and connected workers, and a first-run setup code protects the owner account. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
ScribeCrate
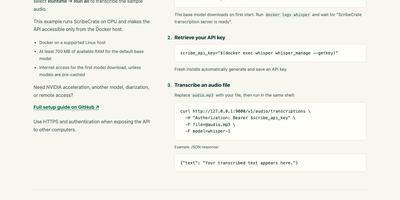
ScribeCrate is a self-hosted speech-to-text API that turns recordings into transcripts, subtitles, and English translations on your own server. It speaks the OpenAI Whisper API fluently: point any compatible client at your server's address, swap in your API key, and uploads come back as text. Ask for plain text, JSON with timestamps, or ready-to-publish SRT and WebVTT subtitle files, and for long recordings the segments can stream back over SSE as they are decoded. Turn on speaker diarization and every segment is labeled with who is speaking, which makes interview and meeting transcripts readable at a glance. Choose the model that fits the job, from tiny for quick drafts to large-v3 for maximum accuracy, and run it on a modest CPU, a Raspberry Pi class ARM board, or an NVIDIA GPU. Almost any recording works: MP3, M4A, WAV, WebM, OGG, and FLAC are all accepted, and with models cached in advance the server keeps transcribing with no internet connection at all. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Subarr
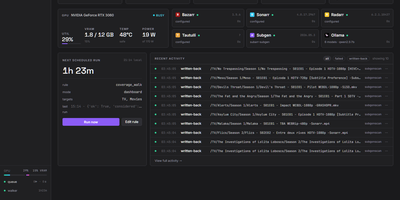
Subarr is the coordination, measurement, and quality layer for Whisper subtitle generation, sitting between Bazarr, Sonarr, Radarr, and subgen to decide what gets transcribed, in what order, and whether the result is any good. Its Coverage walk scans your whole library and scores every subtitle gap with a reason: no track, embedded-only, Bazarr-wanted, audio mislabeled, or low quality. Queue a file, a folder, or an entire series from the Library tab and watch it move through probing, transcribing, and write-back on the dashboard. The Review queue plays you the actual dialogue, picked out by voice-activity detection, so you can verify a subtitle really matches the audio language before it lands. It flags files whose default audio track is not the original language and swaps tracks in place, heading off the double-translation trap. A provider leaderboard records which subtitle sources actually deliver for your library, and the Tuning Lab lets you tune Whisper recipes against your own media. Rules and scheduled walks keep the work flowing, with Tautulli now-playing signals boosting whatever you are about to watch. Finished subtitles are written next to your media, and your Plex or Jellyfin library refreshes the moment one lands. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.