Open SEO Crawler
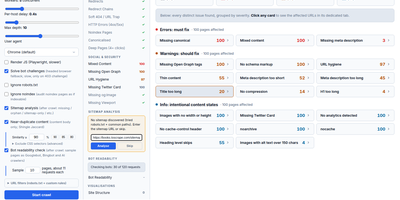
The audit starts with one URL: Open SEO Crawler spiders the entire site from your own server and groups every technical issue by severity. It crawls concurrently with per-host politeness and backoff retries, and presets adapt automatically to WordPress, Shopify, Webflow, and seven other detected CMS platforms. Every page gets checked for missing or duplicate titles, meta descriptions, H1s, and canonicals, plus thin content, redirect chains, broken links, hreflang gaps, and images without alt text. Afterwards, sample pages are fetched again as Googlebot, Bingbot, Applebot, GPTBot, and PerplexityBot, and any page a bot cannot read in full gets flagged. The Summary groups issues into errors, warnings, and info with affected page counts, and the sidebar opens bulk reports for titles, metas, canonicals, duplicates, response codes, and deep pages. Each report exports to an XLSX workbook, and the Crawl Budget page turns parameter traps into ready-to-paste robots.txt rules that stop phantom URLs from eating your budget. One click packs the crawl into a Markdown brief for any AI assistant, and the bundled MCP server lets Claude or Cursor start crawls and read issues directly. Saved crawls reopen any time, dark mode is built in, and a daily auto-update keeps the tool current with rollback if a pull ever breaks it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy