MimirQ
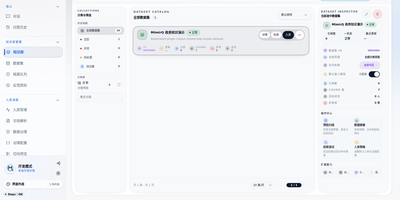
When a knowledge base gives a wrong answer, MimirQ shows which stage let it down. Documents move through a pipeline that teams can open at every step: parsing, cleaning, chunking, indexing, retrieval, reranking, and cited answers. A dataset catalog tracks documents, chunks, and ingestion status, and an execution monitor charts throughput, retries, parser queues, and run logs. The governance workbench previews each file, scores quality, and supports cleaning and labeling before chunks are cut by headings, records, or parent-child structure. Retrieval blends keyword and vector search with reranking, and every reply lists its source evidence with feedback scoring. A graph view maps entities, events, and relationships on one canvas for exploration. Golden-set evaluation stores standard questions and answers, runs them against the current pipeline, and reports recall and ranking metrics, so a release can be blocked when quality slips. Settings pages manage model providers, parsers, and retrieval options, and a Dify-compatible external knowledge API lets existing workflows call it. Role-based access and document permissions keep restricted material hidden from the wrong users. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy