Langfuse
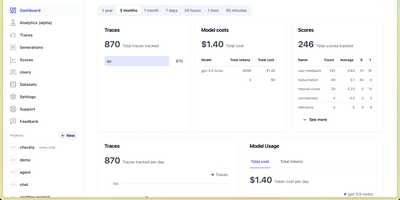
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LangWatch
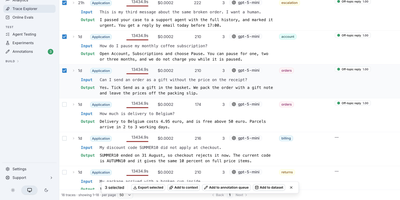
Every call your AI agents make becomes a searchable trace in LangWatch, and the same platform tests and scores those agents before a new prompt or model reaches users. The Trace Explorer filters by origin, user, model, cost, and evaluator, reads each run as a waterfall, flame graph, topology, or sequence diagram, and takes traces from the Python, TypeScript, and Go SDKs or any OpenTelemetry source. Agent Testing sends simulated users, in text or beta voice calls, through your agent while a judge passes or fails every criterion with its reasoning, adds multi-turn red teaming, and compares two agents side by side. The Experiments workbench scores prompts and agents on datasets with LLM judges, exact match, and RAG checks, then compares runs on cost, latency, and pass rate, while online evaluations monitor live traffic and guardrails block unsafe replies. Prompts keep version history and staging or production tags, Workflows wire prompts, Python code, and HTTP calls on a visual canvas, and annotation queues route traces to human reviewers. Alerts fire when a graph crosses a threshold, automations post to Slack, email, or webhooks, and scheduled reports go out by email or Slack. Claude Code, Codex, Copilot, Gemini CLI, and opencode report session cost, pull request cost, and terminal replays, and an MCP server exposes trace search and prompt management to coding assistants. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.