Latitude
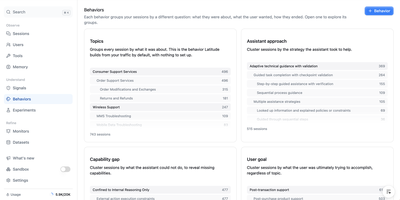
Production AI agents fail in quiet ways, and Latitude records every trace, session, and tool call so each failure can be found, grouped, and fixed. One line of telemetry from the TypeScript or Python SDK, or any OpenTelemetry exporter, sends traces from OpenAI, Anthropic, LangChain, LlamaIndex, CrewAI, and dozens of other providers and frameworks. Failing traces are clustered into signals with status, size, and trend, and flaggers and annotation queues let reviewers score outputs by hand. Evaluations are generated from those judgments and tracked with an alignment score. Semantic and exact-text search covers every trace, and saved searches, filters, and behavior groupings keep recurring questions one click away. Dashboards report cost per session, tool failure rates, and agent score across outcome, reliability, speed, and safety. Memory views show how an agent's stored memory changes over time, with diffs and the trace behind each edit. Monitors raise alerts, regression datasets replay fixes against the traces that failed, and Agent Dispatch hands the evidence to a coding agent. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy