OpenVoiceUI
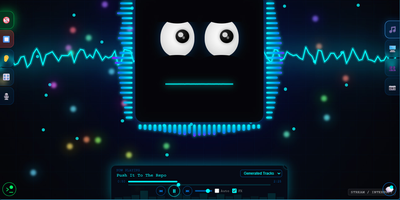
OpenVoiceUI is the voice-first front end for a self-hosted AI agent that lives entirely on your own hardware; you talk, it answers out loud, and it builds live pages on screen while the conversation runs. Hold a hands-free conversation with wake word, push-to-talk, and the ability to interrupt, or switch to text when the room is quiet. Speech recognition runs in the browser for free or through Deepgram, Groq Whisper, or your own Whisper server, while nine speech providers from local Supertonic to ElevenLabs give the agent its voice, cloned voices included. As it talks, the agent opens live canvas pages, dashboards, galleries, reports, and tools, and files them on an OS-style desktop you can reopen from the start menu. Ask for music and it generates songs with a built-in player and playlists; ask for images and it creates those too, alongside an audio clip maker and a soundboard. Profiles swap the agent's persona, voice, and model provider, animated faces react while it speaks, and sub-agents and workspace files stay visible in the admin dashboard. The agent itself runs in the OpenClaw gateway with your choice of model provider, so your keys, conversations, and files never leave your server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy