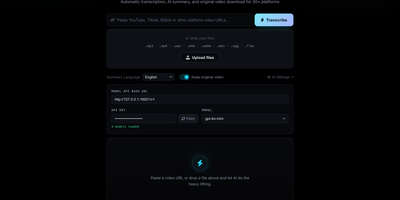
AI Video Transcriber
A two-hour podcast becomes a page of takeaways with AI Video Transcriber, a self-hosted web app that turns links and uploads into clean transcripts and short summaries. Paste a URL from YouTube, TikTok, Bilibili, Apple Podcasts, SoundCloud, or any of 30+ other platforms, or drag in an mp3, mp4, wav, or plain text file. When a video already carries subtitles, the transcript arrives in seconds with no audio download at all, and Whisper takes over only when captions are missing. A badge shows which path each job took, and live progress streams to the page as the job runs. Summaries come out in 11 languages, and a Translation tab appears whenever the transcript language differs from the one you picked. The original video or audio stays beside the results with an inline player and a one-click download, and every tab has its own download icon. Models are your choice: enter any OpenAI-compatible base URL and key in the interface, press Fetch to list what is available, and pick one. Agents get a command line tool, an MCP server, a Claude Code skill, and a Codex plugin. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
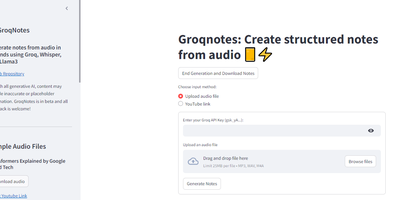
ScribeWizard
Audio lectures become structured, Markdown-formatted notes in about a minute with ScribeWizard (also known as GroqNotes). Upload an MP3, WAV, or M4A file - or paste a YouTube link - and the app runs a three-stage pipeline on Groq's LPU inference hardware: Whisper Large v3 transcribes the audio, a larger Llama model drafts a comprehensive outline of the material, and a faster Llama model fills each section with detailed content. This scaffolded prompting strategy is the core idea: the strong model handles structure where quality matters most, the fast model handles volume, and Groq's 1200+ tokens-per-second inference keeps the whole process near real time. Output renders as clean Markdown with support for tables and code blocks, and finished notes download as text or PDF. Model selection is configurable - swap in other Groq-hosted open models like Mixtral or Gemma to trade speed against quality or work around rate limits. Built as a single Streamlit app by Benjamin Klieger at Groq, it needs only a Groq API key to run, making it one of the simplest self-hosted AI tools to operate.
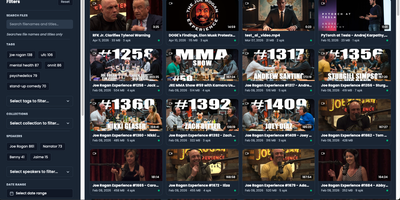
OpenTranscribe
OpenTranscribe is a self-hosted transcription platform that converts your audio and video library into searchable, speaker-labeled transcripts, then lets you summarize and chat with those recordings. Upload files up to 15 GB, record from the browser microphone, or paste a link from YouTube and a thousand other sites, and playlists queue up for batch processing automatically. WhisperX produces word-level timestamps in over 100 languages, while the diarization engine works out who spoke when, corrects turn boundaries, and recognizes the same voice again across different recordings. Speaker profiles accumulate a voice fingerprint, speaking-time analytics, and merged identities, so a regular guest is named correctly in every episode without relabeling. Point it at an LLM and recordings gain structured summaries with action items, suggested tags and collections, and a chat interface that answers questions about your transcripts with citations, grouped into projects that pin their source recordings and standing instructions. Leave the model unconfigured and transcription, diarization, full-text and semantic search, and redaction still run entirely on local models. Watch folders, S3 buckets, and network shares import new media on a schedule with three-layer deduplication and automatic stitching of split recordings, and everything exports as subtitles, Word or PDF documents with citeable numbered lines, or Markdown. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
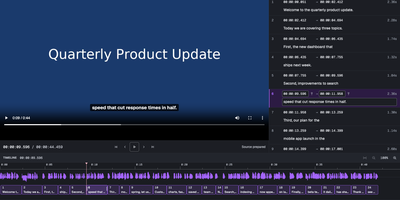
Anysub
Need subtitles but not a cloud upload? Anysub transcribes audio and video with Whisper on your own server and hands back editable cues. Drop in a video or audio recording, pick a Whisper model from tiny to large, and the worker transcribes it with word-level timing. The studio then puts the video, the cue list, and a zoomable waveform timeline side by side, so every subtitle can be dragged, trimmed, split, merged, or retyped. Warnings flag cues that run too fast, too long, or overlap a neighbor, and autosave with undo keeps edits safe. Long uploads resume after a dropped connection, and the searchable library finds projects by name or by the words spoken inside them. Finished tracks export as SRT, WebVTT, plain text, or JSON with words and metadata. Administration pages manage model downloads, transcription defaults, upload limits, disk usage, and connected workers, and a first-run setup code protects the owner account. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.

Vexa
Vexa is the only Apache 2.0 meeting bot API that self-hosts the complete transcription pipeline, from bot dispatch to Whisper speech-to-text to knowledge agents, with zero audio leaving your infrastructure. A single POST /bots request sends a transcription bot into any Google Meet, Microsoft Teams, or Zoom call, where it captures audio, runs speaker-attributed transcription through faster-whisper or any OpenAI-compatible endpoint, and streams results to your application via real-time WebSocket with sub-second latency. The built-in agent framework watches live transcripts and your accumulated workspace context, answering mid-call questions grounded in your own meeting history and wiki. An MCP server connects Vexa to Claude, Cursor, and other compatible AI tools, turning every captured meeting into queryable context for external agents. The Terminal, a bundled Next.js web workbench, lets you send bots, watch live transcripts, manage users and API tokens, and chat with your meeting archive from a browser. Docker Compose brings the full stack up on one Linux host in five minutes; the Helm chart scales to thousands of users on Kubernetes with a Pod-per-bot architecture and built-in RBAC. Recordings persist in MinIO or any S3-compatible store, transcripts in Postgres, with Redis handling queues and scheduling. Deploy on RepoCloud for a dedicated VPS with full root SSH access and browser console. Apache 2.0 licensed.
Speakr
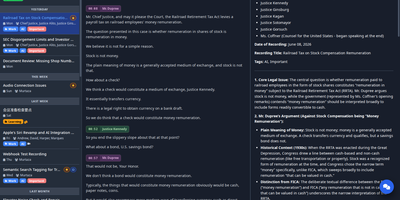
Speakr transforms audio recordings into organized, searchable, AI-enhanced notes with speaker recognition that identifies who said what across your entire recording library. The Python/Flask backend with Vue.js 3 and Tailwind CSS frontend deploys via Docker on port 8899, offering multiple transcription engines through auto-detected connectors: WhisperX for local processing with speaker diarization and voice embeddings, OpenAI Whisper and GPT-4o-transcribe, Mistral Voxtral for cloud diarization, AssemblyAI for multi-hour files, and any custom ASR webservice. Speaker voice profiles use embedding comparison to recognize individuals across different recordings automatically, while custom vocabulary biases the transcriber toward domain-specific jargon. The AI layer goes well beyond transcription: customizable summaries with per-recording, per-tag, and per-folder prompt templates; event extraction surfacing action items and calendar events; per-recording chat with streaming responses; and Inquire Mode for semantic search and natural-language queries across your entire library simultaneously. Smart tags execute custom AI prompts on transcripts for automatic categorization. The REST API with Swagger documentation supports signed webhooks integrating with n8n, Zapier, and Make. Auto-export pushes to Obsidian and Logseq, auto-processing watches directories, and the installable PWA provides mobile-first, offline-capable access with share-target support. 3,600+ stars since May 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
MeetDo
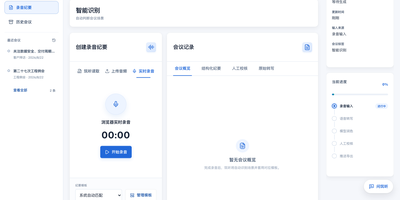
The meeting ends and, instead of a raw transcript, you get minutes you can file: MeetDo is an open-source meeting-to-action system that hosts the meeting, captions it locally, and finishes the record for you. Start a browser meeting with video, screen sharing, and chat, and watch captions stream from a speech model running on the same infrastructure, so no audio is sent to a cloud note-taker. When the call ends, the transcript becomes structured minutes: summary, agenda flow, conclusions, and action items with owners, instead of a wall of raw text. Five meeting types, from management reviews and project weeklies to interviews and customer calls, shape the record, and custom templates export to DOCX or PDF with your original layout preserved. Domain vocabulary is corrected after recognition, so names, units, and industry terms survive transcription instead of turning into near-miss words. Past meetings stay searchable in a local history, and questions can be asked across them without anything leaving the machine. Editable transcripts let a human fix the record before it is filed, and the whole pipeline works offline after the first model download. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Nojoin
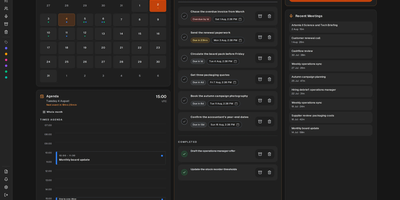
Nojoin takes notes on your Meet, Teams, and Zoom calls without sending a bot into the meeting: it records from your browser and transcribes on your own server. Nothing extra joins the call and nothing announces itself to the room; you meet as usual, press record, and the browser captures the audio. Transcription runs locally with Whisper or Parakeet, so the audio never leaves your hardware, and speaker recognition matches voiceprints across calls, so a person you name once is labelled correctly in later meetings too. AI notes can come from an API provider, your existing Claude or ChatGPT subscription, or Ollama on the same machine for fully local processing. During the call, Meeting Edge suggests questions, flags points you may have missed, and explains unfamiliar terms in real time. Afterward, analytics measured from the audio report talk-time share, turn-taking, and overlapping speech. A built-in MCP server hands Claude or ChatGPT 32 tools over your library, 19 of them writable, so an assistant can search every meeting, correct a misheard line, turn action items into tasks, and reconcile attendees with your CRM. Google and Outlook calendars sync automatically, every meeting carries its own chat, and finished notes export to PDF, Word, or plain text. Stored credentials are encrypted with a key you control, and anonymous telemetry can be switched off entirely. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.