Stars
Forks
Watchers
Developer links
OpenTranscribe
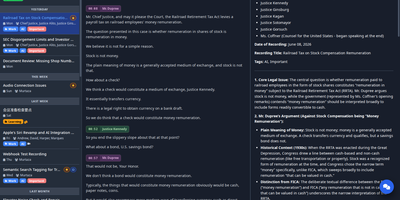
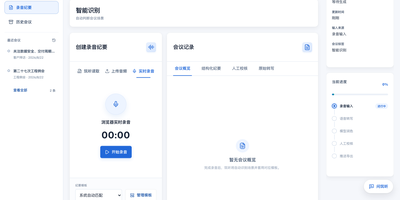
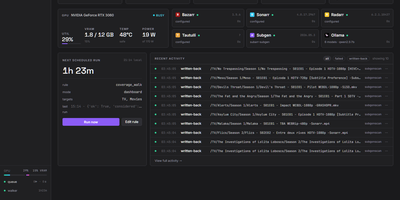
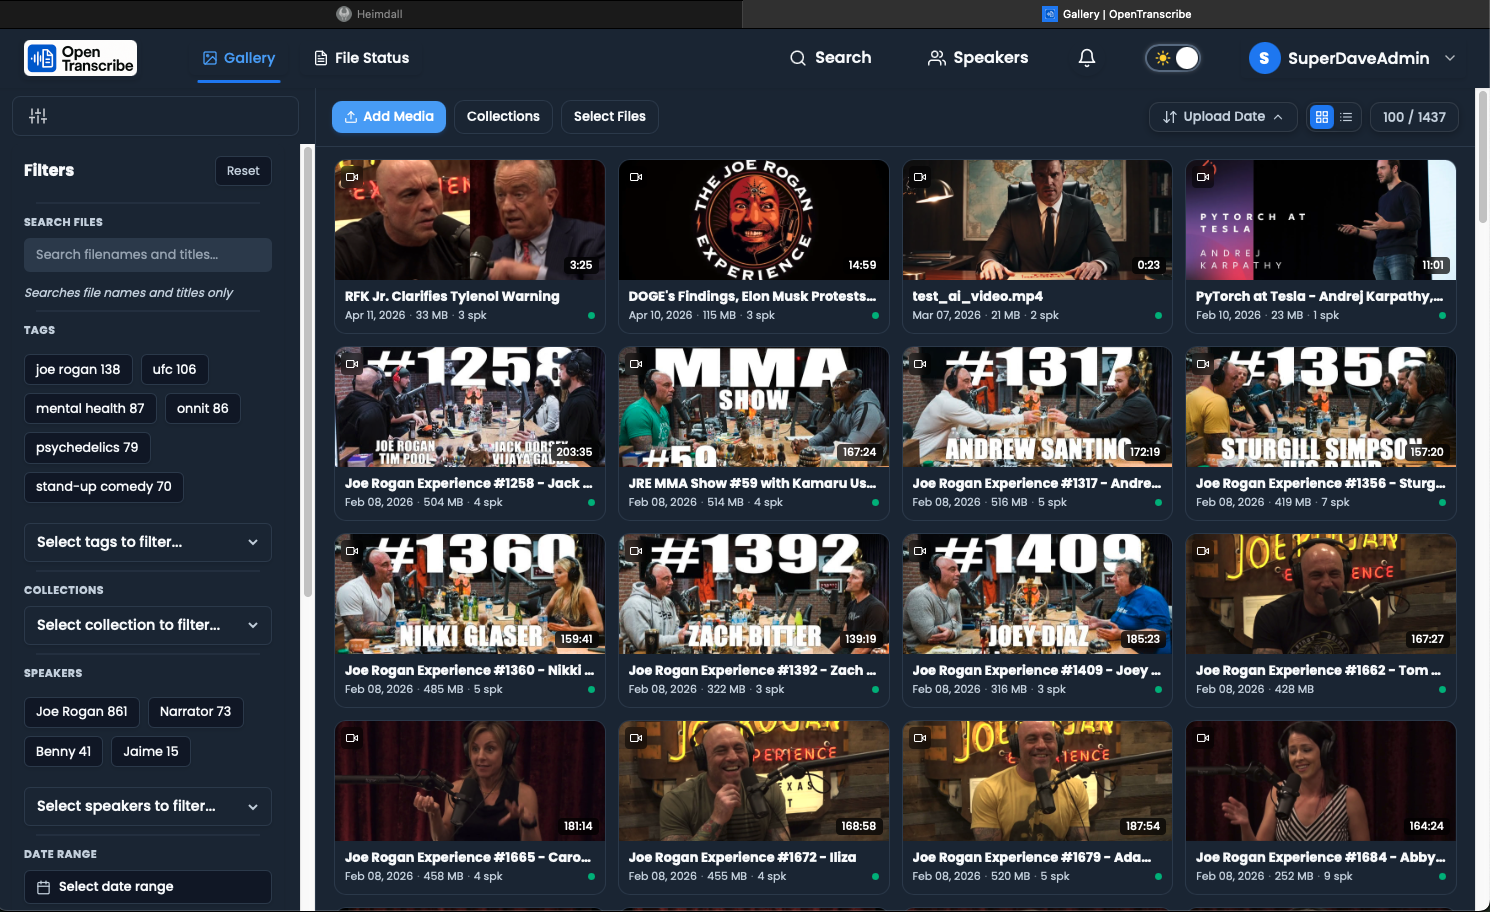
OpenTranscribe is a self-hosted transcription platform that converts your audio and video library into searchable, speaker-labeled transcripts, then lets you summarize and chat with those recordings. Upload files up to 15 GB, record from the browser microphone, or paste a link from YouTube and a thousand other sites, and playlists queue up for batch processing automatically. WhisperX produces word-level timestamps in over 100 languages, while the diarization engine works out who spoke when, corrects turn boundaries, and recognizes the same voice again across different recordings. Speaker profiles accumulate a voice fingerprint, speaking-time analytics, and merged identities, so a regular guest is named correctly in every episode without relabeling. Point it at an LLM and recordings gain structured summaries with action items, suggested tags and collections, and a chat interface that answers questions about your transcripts with citations, grouped into projects that pin their source recordings and standing instructions. Leave the model unconfigured and transcription, diarization, full-text and semantic search, and redaction still run entirely on local models. Watch folders, S3 buckets, and network shares import new media on a schedule with three-layer deduplication and automatic stitching of split recordings, and everything exports as subtitles, Word or PDF documents with citeable numbered lines, or Markdown. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
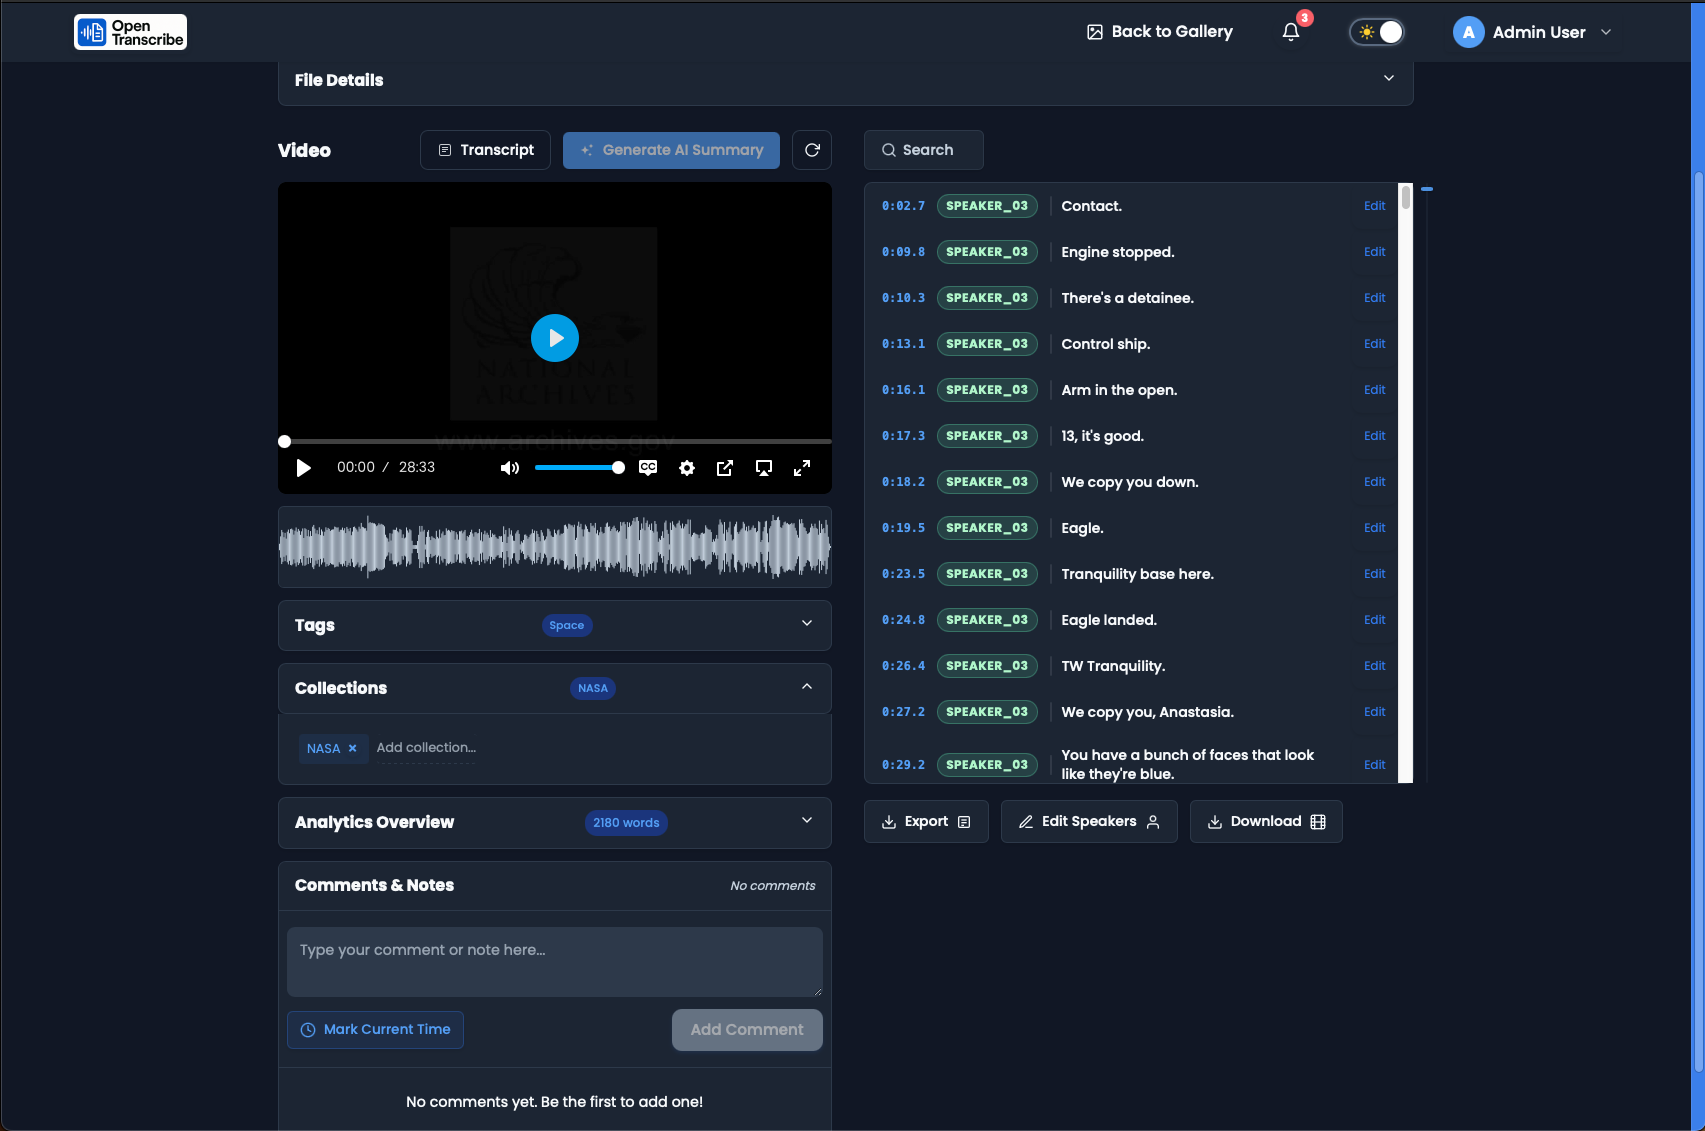
- Transcripts that know speakers
- Automatic diarization separates speakers, voice fingerprints recognize them again in other recordings, and profiles track speaking time and appearances across your entire media library.
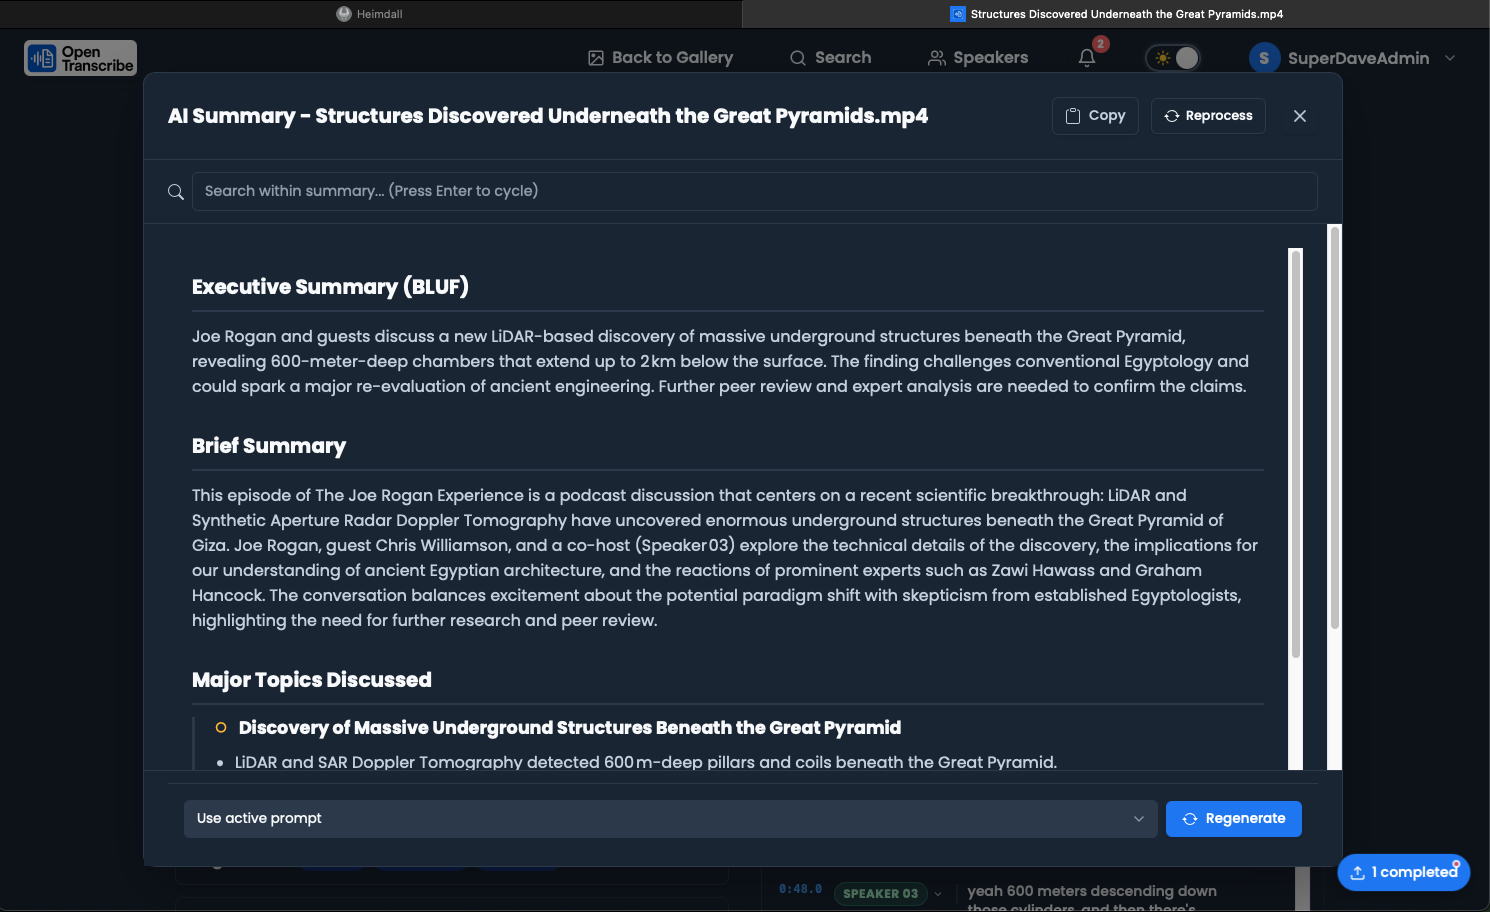
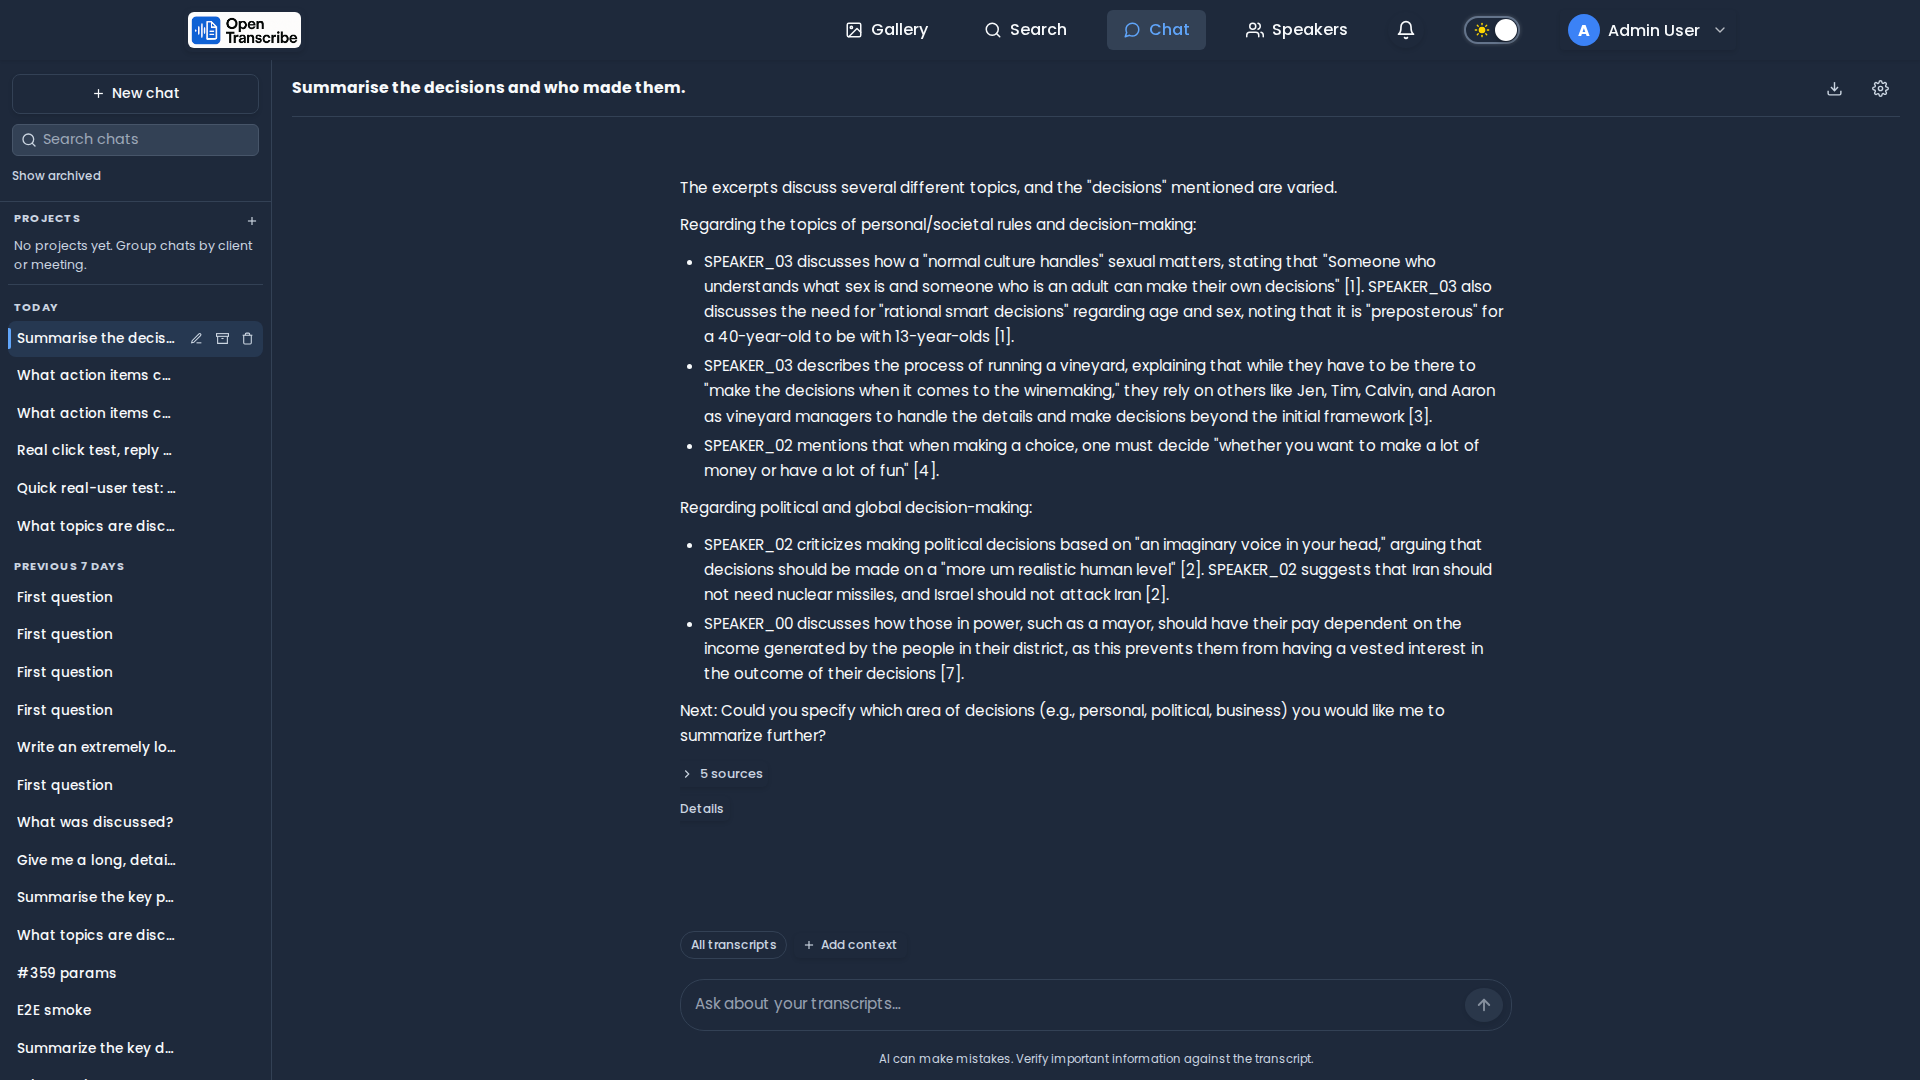
- Chat with your recordings
- AI chat answers questions across one transcript or a whole project of recordings with citations, while summaries extract action items in a structured Bottom Line Up Front format.
- Ingest from anywhere automatically
- Watch folders, S3 buckets, and SMB shares import new media on a schedule, deduplicate it three ways, stitch split recordings back together, and tag everything on arrival.
- Private by architecture
- Transcription, diarization, search, and redaction run on local models with no account or API key, and an LLM from Ollama, vLLM, OpenAI, Anthropic, or Bedrock is optional.
Features
- WhisperX transcription engine
- faster-whisper with the large-v3-turbo default model produces word-level timestamps in 100+ languages at up to 40x realtime on an RTX A6000.
- Speaker diarization and fingerprints
- A native diarization engine with PyAnnote failover assigns every word a speaker, corrects boundaries, and matches voices across recordings at 75% similarity or better.
- URL and playlist import
- yt-dlp integration pulls media from YouTube, Dailymotion, TikTok, X, and 1,000+ other sites, extracting and queueing whole playlists for batch transcription.
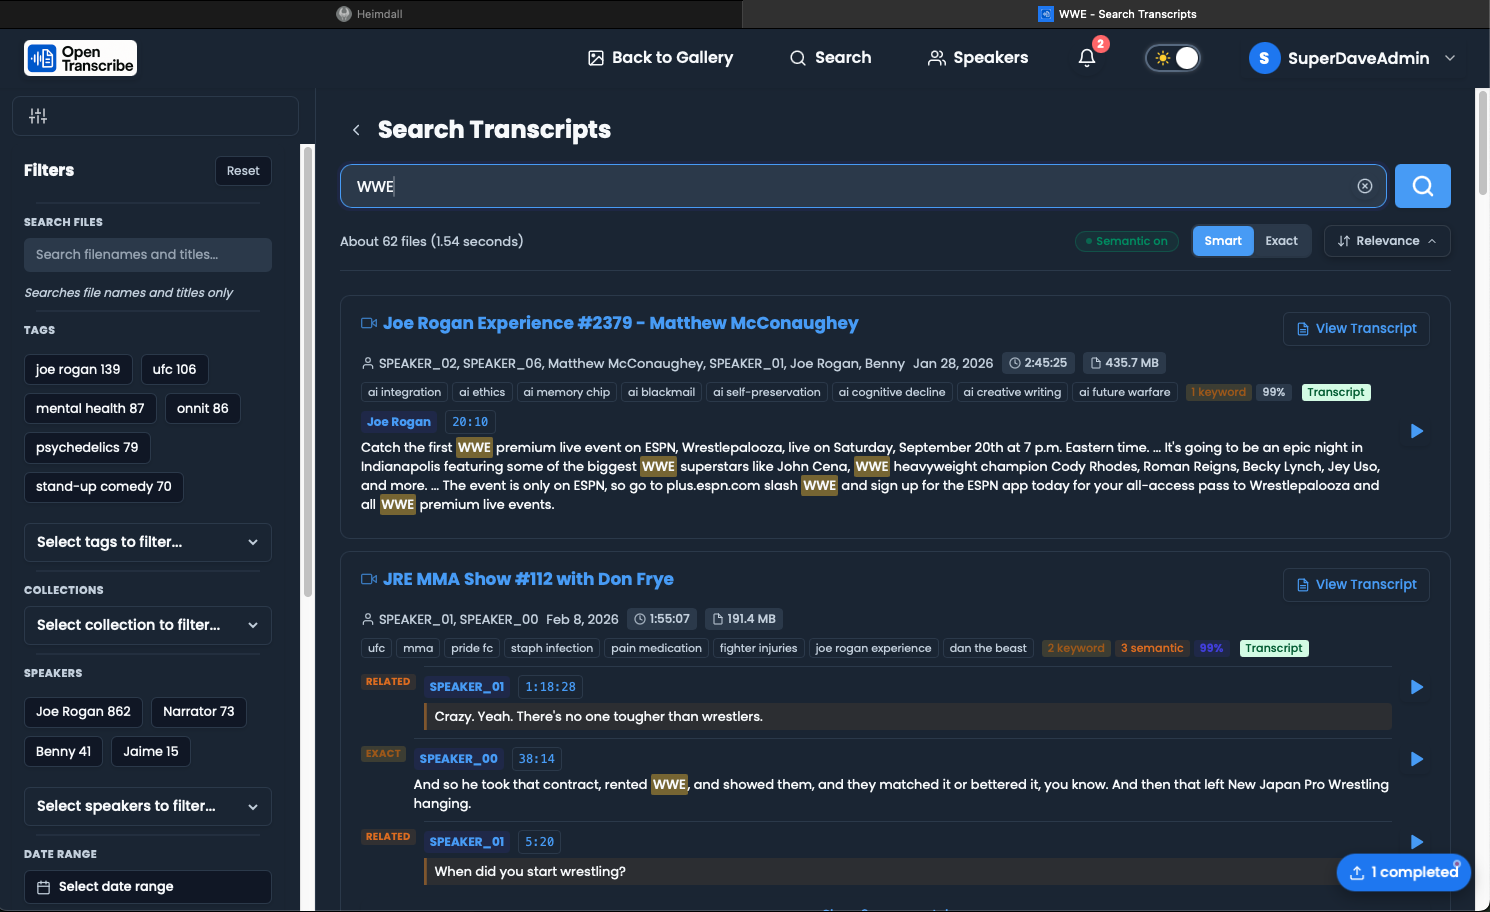
- Search across everything
- OpenSearch indexes titles, transcripts, summaries, and speakers for fast full-text queries, with semantic search that finds passages by meaning rather than exact words.
- Citeable document exports
- Export subtitles in SRT or VTT, or transcripts as Word and PDF documents with numbered lines you can cite by page and line, plus Markdown.