Kokoro FastAPI
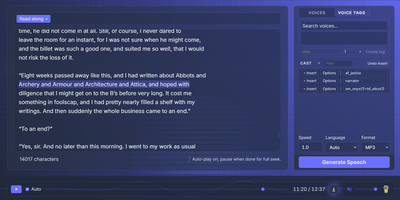
Kokoro-FastAPI turns text into natural-sounding speech across eight languages by serving the 82-million-parameter Kokoro-82M model through an OpenAI-compatible REST API, so any existing OpenAI SDK client can generate audio by just changing the base URL. With over 5,300 GitHub stars since December 2024, the fully Dockerized FastAPI server covers American English, British English, Spanish, French, Hindi, Italian, Japanese, Brazilian Portuguese, and Mandarin Chinese with language-specific phoneme processing. Inline voice mixing blends multiple profiles using weighted ratios like af_bella(2)+af_heart(1), automatically normalizing weights and caching combined voicepacks as PyTorch tensor files for reuse. Audio streams in real time over HTTP with configurable chunk sizes, or generates complete files in MP3, WAV, OPUS, FLAC, AAC, or PCM formats with speed control from 0.25x to 4.0x. Per-word timestamped captions with speaker-tagged voice labels enable subtitle generation for podcasts, audiobooks, and accessibility workflows. Pre-built Docker images support NVIDIA GPU acceleration via CUDA, experimental AMD GPU inference via ROCm, and CPU-only deployment on linux/amd64 and linux/arm64 architectures, with Apple Silicon MPS support available through direct UV execution. The integrated web interface at port 8880 provides browser-based speech generation, while the Swagger UI at /docs exposes the full API reference. Debug endpoints report system statistics for monitoring inference load. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Deploy