Profilarr
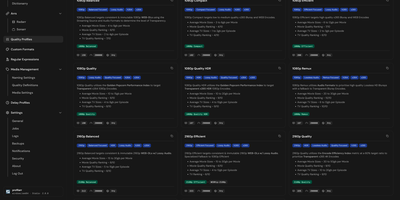
Profilarr orchestrates media library quality profiles, custom formats, and release matching rules across all your Radarr and Sonarr servers from a single centralized management console. Instead of manually copying regex strings and scoring tables between home server instances, you can link community configuration databases like TRaSH Guides and Dictionarry to automate standardization. The visual pattern workbench lets you test regular expressions directly against real-world media release titles, highlighting matches for audio codecs, HDR formats, and release group tags. You can simulate release scoring before deploying, inspecting exactly why a candidate download gets accepted or rejected based on your custom ranking conditions. Media managers can define custom delay profiles, establishing protocol priorities and minimum score thresholds to prevent premature grabs before high-quality releases surface. Granular synchronization tools push updated profiles and formatting rules to multiple production Arr instances simultaneously while preserving your local server overrides. When indexers publish new release naming conventions, you can update conditions once in your central database and roll out updates across your entire infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPLv3 licensed.
Lingarr
When international movies and series arrive in a Radarr or Sonarr library without native-language captions, Lingarr automatically translates subtitle files across dozens of languages using local AI models or cloud translation engines. Connect your existing movie and television directories to scan media folders, identify missing target-language subtitles, and generate translated caption files alongside the original video streams. Administrators can configure an ordered chain of 13 translation backends, pairing a primary engine such as OpenAI, Anthropic, Gemini, DeepSeek, Mistral, xAI, or DeepL with automatic fallback to self-hosted LibreTranslate or local Ollama models whenever rate limits occur. Context-aware prompt templates inject preceding and following dialogue lines into each AI request so idioms, speaker tone, and timing remain natural across scene transitions, while batch translation mode processes multi-line blocks in a single call. From the web dashboard, users can browse indexed movies and episodes, trigger manual single-file or library-wide translations, and monitor active queues, progress percentages, and historical logs in real time. Scheduled background tasks and a documented REST API allow media servers to automate caption generation completely hands-free as new releases finish downloading. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.