llmfit
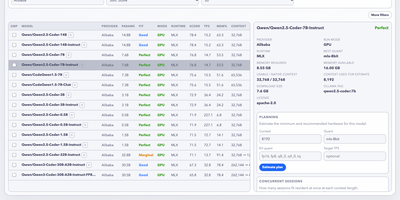
llmfit tells you which open LLMs will actually run on your machine, and how fast, before you download a single gigabyte. Guessing wrong means a huge download that crawls or never loads, so it reads your CPU, RAM, and GPU and scores thousands of models on memory fit, estimated tokens per second, quality, and context length. Start llmfit serve and a browser dashboard opens on port 8787, with a sortable fit table, filters for runtime, use case, and provider, and a detail panel that names the best quantization, the memory required, and the download size. Thinking of renting a bigger box? Type a RAM, VRAM, and core count and every score recalculates for that imaginary machine. The planner estimates minimum and recommended hardware for a chosen context and quantization, shows how many concurrent sessions fit at each context length, and sizes the SSD for a whole library of models. Tick a few rows to compare them side by side. Scripts can pull system info and ranked models from JSON endpoints, and cluster mode checks whether a model splits across several Ray nodes before you launch vLLM. The bench command measures real speed against Ollama, llama.cpp, MLX, or LM Studio, and the interface offers ten themes and a Chinese translation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy