Guard Spec
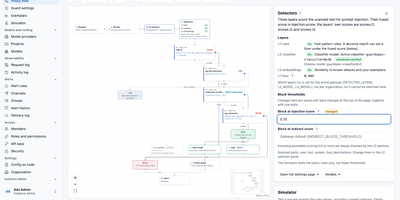
Any web page, document, or tool result your LLM reads can carry hidden orders, so Guard Spec sits between your app and the model and blocks prompt injection before it arrives. Change one base URL and the gateway accepts OpenAI-style chat completions, the Responses API, embeddings, and Anthropic's Messages API for Claude Code, then routes clean traffic to OpenAI, Azure OpenAI, Anthropic, Gemini, vLLM, or Ollama. Each request is sanitized, scored by pattern rules, an in-process classifier, and similarity to known attack examples, and judged against your policies; an injection gets an HTTP 400 and the model is never called. Tool results, retrieved documents, and MCP tool descriptions are scored one by one, so hidden instructions and poisoned tool definitions are caught. An output guard checks answers, including streamed ones, for exfiltration links, personal data, and a leaked canary. Policies per organization and project are written as text or in a visual editor, tested in a simulator, and edited as YAML with a diff. Rules see through Vietnamese diacritics, teencode, leetspeak, and homoglyphs, because detection was built for English and Vietnamese. Alerts reach Slack, Microsoft Teams, Telegram, email, PagerDuty, Opsgenie, or signed SIEM webhooks, and single sign-on works with OpenID Connect or SAML 2.0 plus SCIM provisioning and TOTP two-factor. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy