Containarium
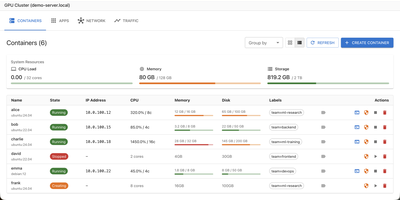
Containarium gives every AI agent a persistent Linux box of its own, reachable over SSH and driven through structured tools instead of a fragile terminal session. One command creates a named sandbox, syncs the SSH configuration, and wires the box into Claude Code, Codex, Gemini or Cursor through an MCP server that runs inside the container. From there the agent can execute shell commands, read and write files, install services, and expose a port on a public hostname with TLS terminated by a Caddy sentinel. Detached code runs keep working after a laptop sleeps or a connection drops, and the operator reattaches to the same byte-exact log later, checks status, or stops the run without losing output. An optional per-tenant eBPF egress policy limits outbound traffic per box, logs denied attempts for audit, and keeps provider API keys inside a model gateway rather than inside the agent environment. Boxes run on LXC or Kubernetes, keep state between agent sessions, support GPU passthrough for local model work, and stay separate from the host operating system and the cluster control plane. The dashboard presents containers, traffic, security events, audit records, GPU state and monitoring in one place. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
AKB
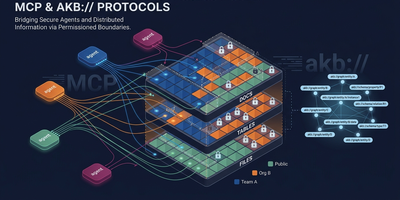
Achieving 98.4% Recall@5 on LongMemEval-S without a reranker, AKB is the agent-native knowledge infrastructure giving Claude Code, Cursor, Windsurf, and any MCP-aware agent persistent organizational memory — a drop-in replacement for Confluence or Notion where AI agents read and write directly rather than scraping human-formatted pages. Documents are stored as Markdown with YAML frontmatter in Git bare repositories (full version history, branching, diff), while PostgreSQL 16 serves as source of truth for chunk text, metadata, and BM25 vocabulary, with dense embeddings handled by a pluggable vector store (pgvector default, Qdrant optional, or managed Seahorse). Agents interact through 20+ MCP tools — akb_put, akb_search, akb_browse, akb_relations, akb_sql, akb_edit, akb_history — performing hybrid dense plus BM25 search fused via Reciprocal Rank Fusion in one call. The URI graph (depends_on, related_to, implements relations) lets agents traverse knowledge connections without external graph databases. Multi-tenant vault isolation is enforced at the PostgreSQL ACL level with per-user roles and SET LOCAL ROLE for SQL sandboxing. Event fanout streams structured events to Redis Streams for external consumers (synthesis bots, digest agents, audit trails), and a hash-chained append-only audit log integrates with enterprise SIEMs. Ships with agent plugins for Claude Code and Codex (session capture, wiki ingest, lifecycle hooks), Kubernetes kustomize manifests, and Open Knowledge Format export. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed (free under 100 seats, auto-converts to Apache 2.0 after four years).
Searcharvester
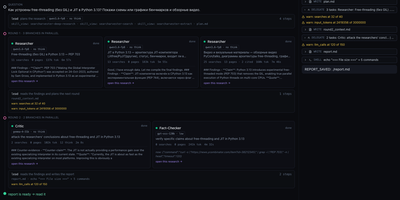
Searcharvester gives your AI agents a private search and research backend that runs entirely on your server, with a web UI where you watch every research job unfold. The search endpoint speaks the Tavily schema, so existing agent code points at your host and queries more than a hundred SearXNG engines without API keys or quotas. Send a URL to the extract endpoint and it returns clean markdown with navigation, footers, and ads stripped, sized in presets from five thousand characters to fully paginated long documents. Three extractors compete on each page and a quality gate keeps the best result, so hard pages still yield readable text. For bigger questions, the research endpoint runs a team of agents: a lead plans sub-questions, researchers gather in parallel, a critic tries to disprove the findings, and a fact-checker re-verifies numbers and dates before the final report arrives with clickable citations. You assign a different model and reasoning level to each role, follow agent branches, the reading graph, sources, and media live, then read the finished report in the same UI. Search settings let you toggle engines per category, test proxies, and apply changes with a targeted restart. A loop guard enforces budgets for calls, tokens, searches, and page reads across the whole job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
AGenUI Studio
AGenUI Studio turns a written description into a working interface card: an AI agent generates the UI, binds it to your APIs and data, and packages it so it runs anywhere, no Studio required. Bring your own model by entering any OpenAI-compatible or Anthropic Messages endpoint and key in the console settings, and generation proceeds contract-first, steered by design rules you publish as versioned Markdown revisions. You preview each card live as it is generated, then refine it over multiple turns while every component, binding, and action you did not target stays protected from accidental edits. The console also manages the supporting cast: a local knowledge base, API definitions, and reusable operators, all starting from bundled demo data you can swap for real services whenever you are ready. When a card is finished, download it as a self-contained Runtime Package carrying its data sources, bindings, actions, and operators, and execute it with the bundled Card Runtime inside your own application, or register a delivery target and publish straight from the workbench over a callback or a message queue. Applications subscribe to native run events over HTTP and SSE, and production deployments can replace the local defaults piece by piece, MySQL for storage, Redis for hot state, MCP services for knowledge and data, while the packages keep the same contracts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Magec
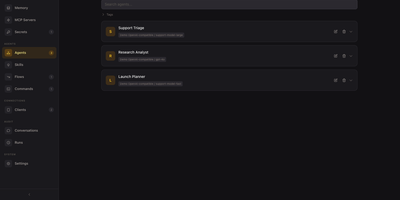
One self-hosted admin console runs a team of AI agents you can reach by voice, chat, webhook, or schedule. Each agent gets its own model backend, system prompt, memory, tools, and voice, with OpenAI, Anthropic, Gemini, Ollama, or any OpenAI-compatible API behind it. A visual flow editor chains agents with routers, joins, loops, parallel fan-out, templates, and small code blocks, so a question can be sorted and answered by the right specialist. Every run is recorded as a step-by-step timeline you can open and read, and conversations are browsable per client. Connect tools through the Model Context Protocol, keep long-term memory in PostgreSQL, and store API keys as secrets that models only ever see as placeholders. Voice runs on the server with wake word detection and speech models, and clients cover a voice web app, Telegram, Discord, Slack, webhooks, and cron jobs. One password-protected console manages every agent, flow, and client. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Retinue
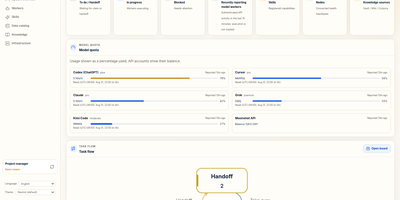
Retinue shows who is doing what across a fleet of AI agents, on a shared board where every task is a card with exactly one holder, a written acceptance check, and a receipt chain that cannot be rewritten. Operators publish cards, agents claim them through MCP or a token-scoped HTTP API, report progress, and hand off, and an agent that is not the holder gets a refusal when it tries to write. The Home dashboard counts what is waiting, running, and blocked, charts task flow and dispatch, and shows quota gauges for Claude, Codex, Cursor, Grok, and Kimi subscriptions. A collaboration workspace draws delegation graphs, device and model timelines, module contributions, and message conversations for any selected task. Operations pages report token usage by worker, and a data health page flags stale reports and duplicate identities. Read-only importers pull session data from Claude Code and Codex, and optional Lark, Feishu, and Telegram bridges turn chat messages into intents. The interface switches between English and Simplified Chinese. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LangGraph GUI
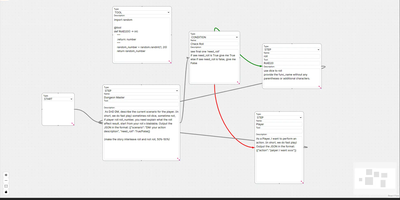
Building LangGraph agents in code means imagining the graph; LangGraph GUI turns that graph into something you draw, wire, and run from the browser instead. You place a start node, add step nodes, and drag edges between ports to define the flow, with cycles created by simply connecting nodes back toward each other. Condition nodes split execution into green true paths and red false paths, info nodes append context to stage output, and subgraph nodes run a whole named graph inside another one. Tool steps call real Python functions that you define in tool nodes with the familiar decorator style, so file saving, lookups, and custom logic sit inside the visual flow. Graphs save to JSON on your computer, load back for editing, and upload to the server as workflow files ready to execute. You configure which LLM to use and its API key in the panel, run against local models through Ollama or hosted APIs, then download every file the run produced in the workspace. Files upload to the server workspace as working environment, and a cache clean clears it between runs. Example graphs for role-playing loops, lottery branch switches, and tool-using flows show patterns you can copy and refine with your own prompts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PharosRAG
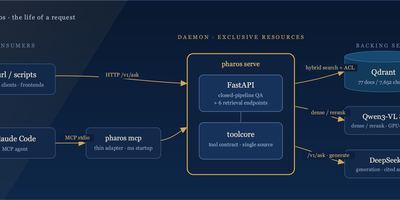
Your team's documents sit in folders nobody can search, and the answer to a simple question hides on page 40 of a PDF someone saved last year. Pharos ingests PDFs, scans, Word documents, presentations, and spreadsheets into a local knowledge base, then answers questions against that library with citations traced back to the exact page. Hybrid retrieval finds the passages that matter, and every answer carries its evidence so readers can verify the claim in the source. Access control decides visibility per person: an API key resolves to an identity with a tenant and group memberships, retrieval filters hard to only the documents that identity may see, and a document with no permissions attached stays invisible to everyone. Two doors lead into the same library. The HTTP API runs a closed question-answering pipeline that retrieves, grounds, and answers in one call, and coding agents connect through MCP to decide for themselves when to retrieve, how to rewrite a query, and when a question needs multiple hops. A resident daemon keeps the search index and models warm, so every session shares one backend instead of reloading heavy resources. The deployment scales from one machine to replicated application tiers behind a load balancer. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.