Categories
Developer Tools Privacy AI Agents AI Infrastructure Self-Hosted AI LLM Serving Model ManagementStars
Forks
Watchers
Developer links
ODS
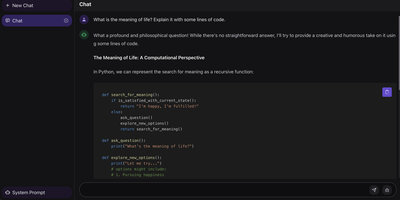
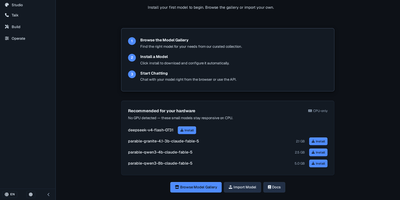
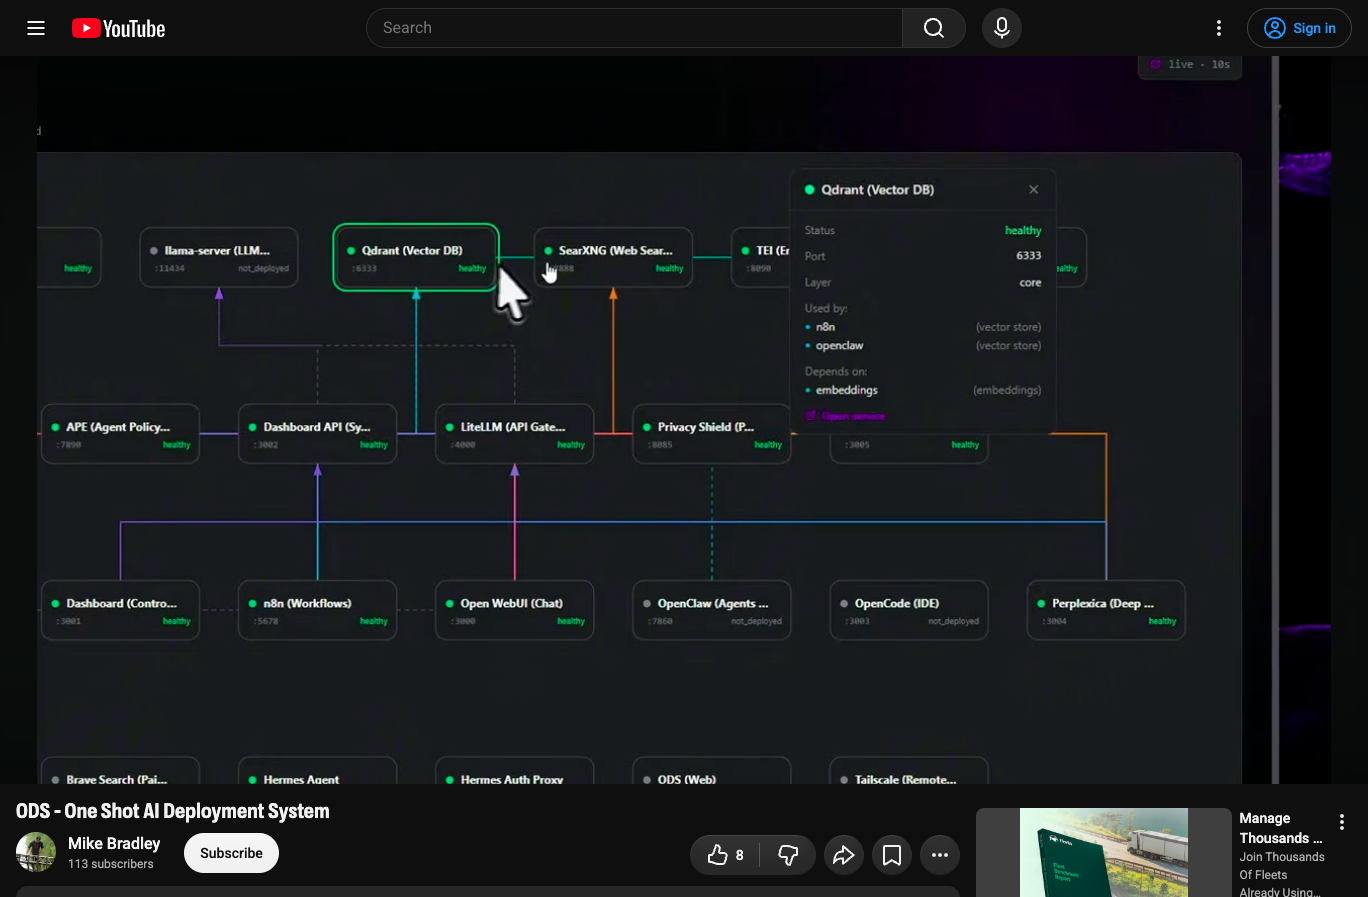
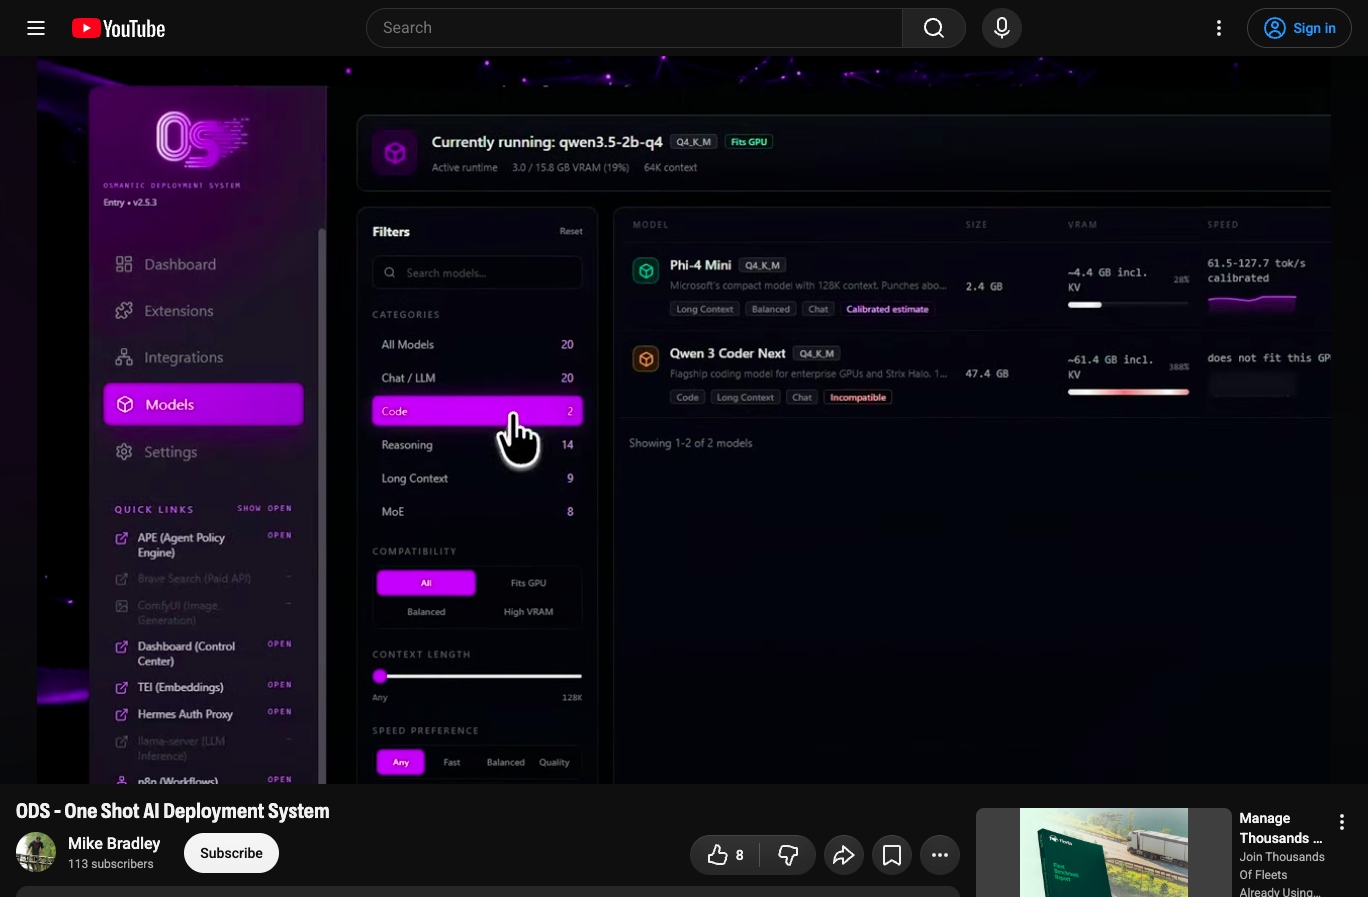
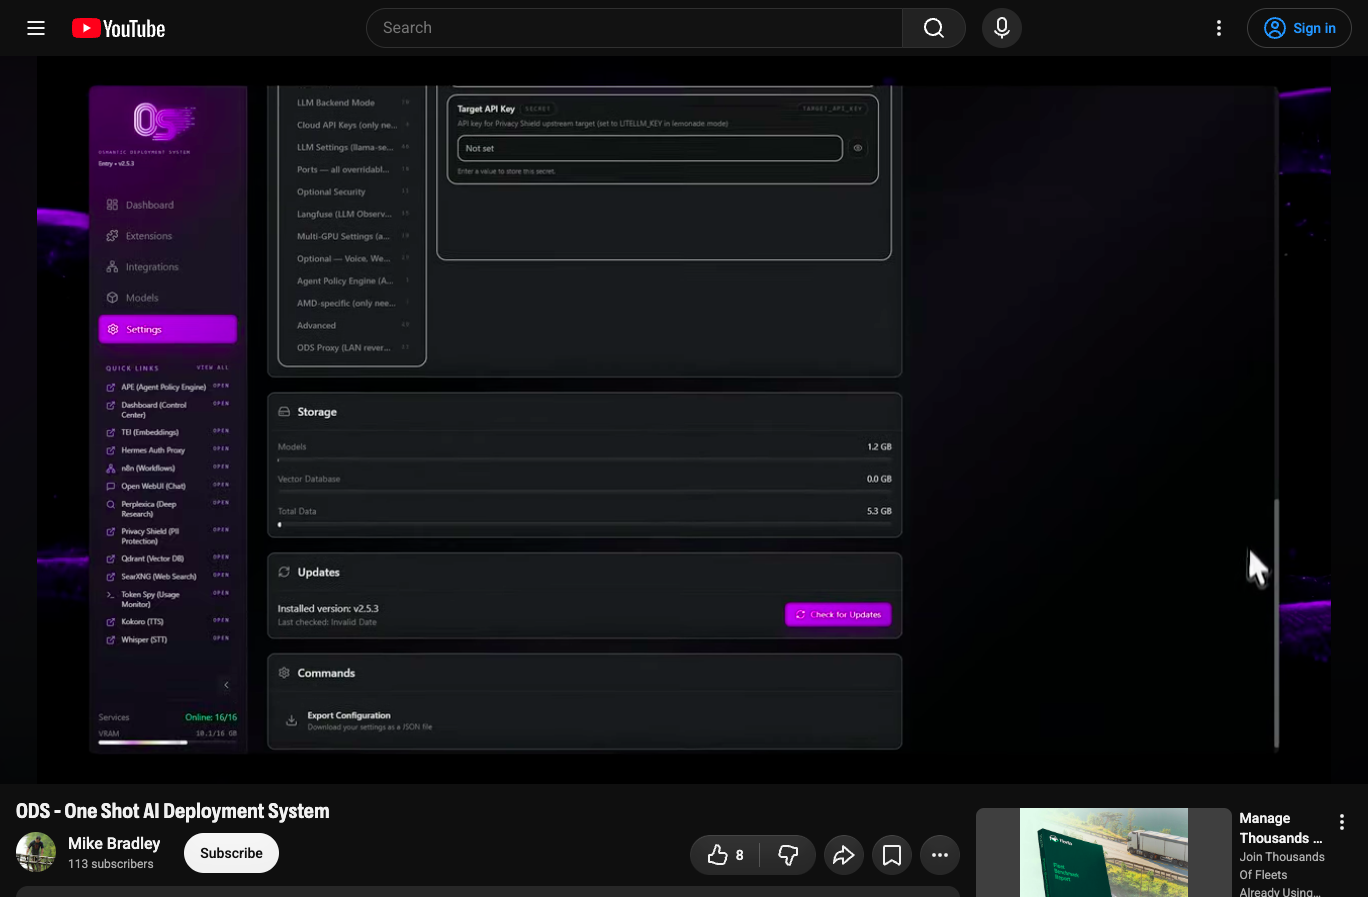
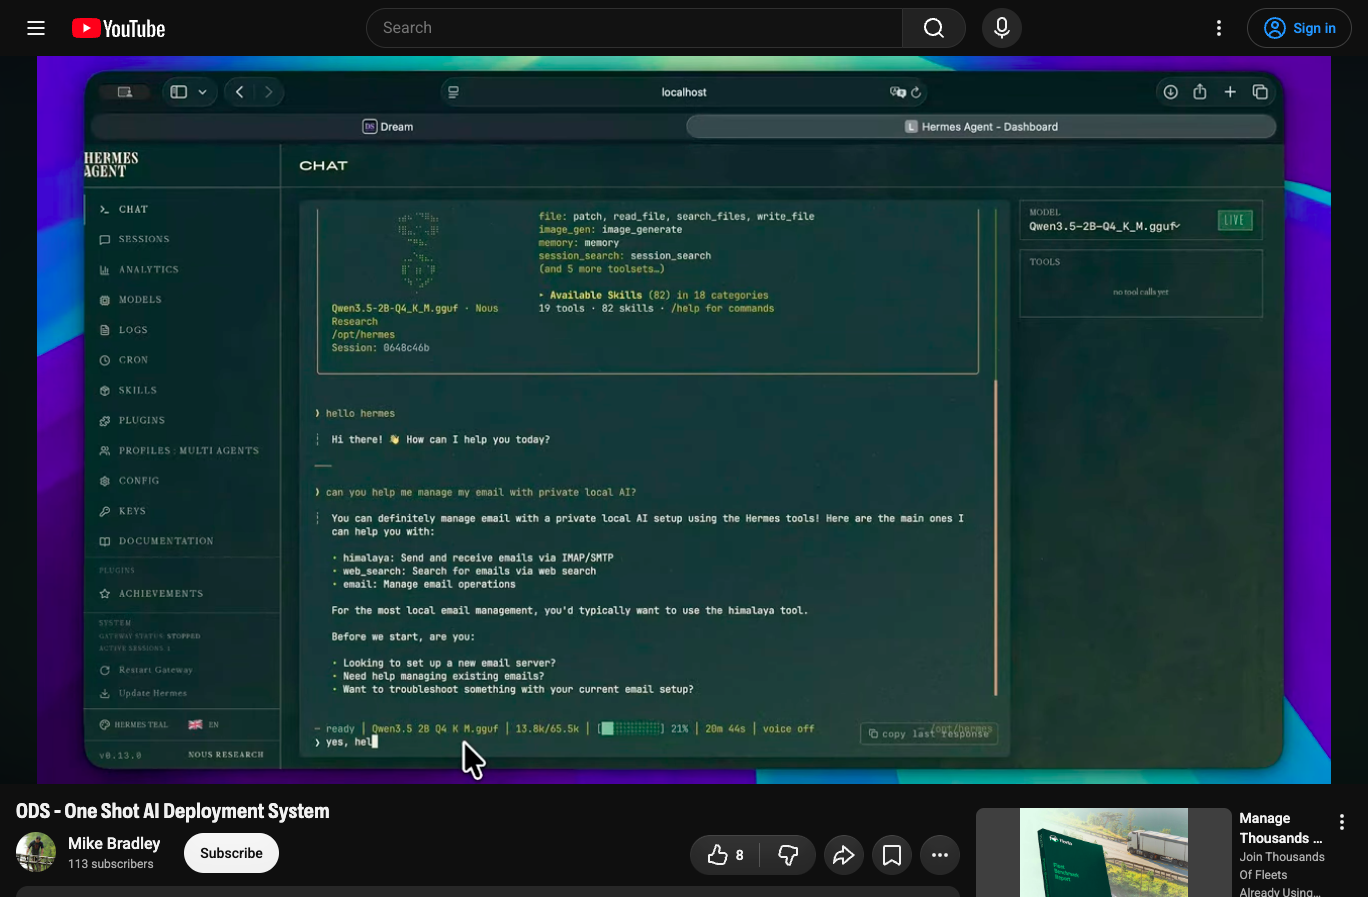
ODS turns a GPU machine or server you already own into a complete private AI stack with a single install command, replacing a shelf of separate tools with one system that serves models, chat, agents, automation, and search from your own hardware. The installer reads your GPU, VRAM, memory, and disk, then downloads a GGUF model matched to that hardware tier, and a compact bootstrap model starts answering within minutes while the full model finishes downloading. From the web dashboard you watch every service's health, ports, and resource use, restart what misbehaves, and check storage and updates without touching a terminal. You chat with local models in Open WebUI, hand background work to the Hermes and Portal agents, and build automations in n8n that connect the stack to more than 400 other apps. Documents you add become searchable knowledge through Qdrant vector storage, so answers cite your files instead of the model's memory. SearXNG and Perplexica answer web questions without trackers or accounts, Whisper transcribes speech, Kokoro reads text aloud, and ComfyUI generates images, all on the same box. Every bundled service is an extension you can enable, disable, or replace, and a Privacy Shield scrubs personal data before anything reaches an optional cloud model through the LiteLLM gateway. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- One Command, Full Stack
- One curl command installs inference, chat, agents, workflows, search, and voice services with generated credentials, hardware checks, and Docker Compose orchestration handled automatically for you.
- Hardware-Matched Model Selection
- The installer reads GPU and VRAM, then downloads a GGUF model sized for the machine, from a compact 2B bootstrap to 35B-class models on 48GB cards.
- Everything Managed From One Dashboard
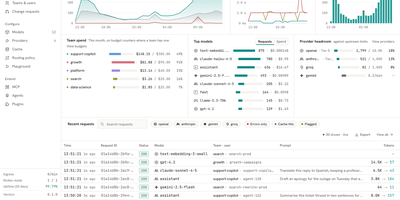
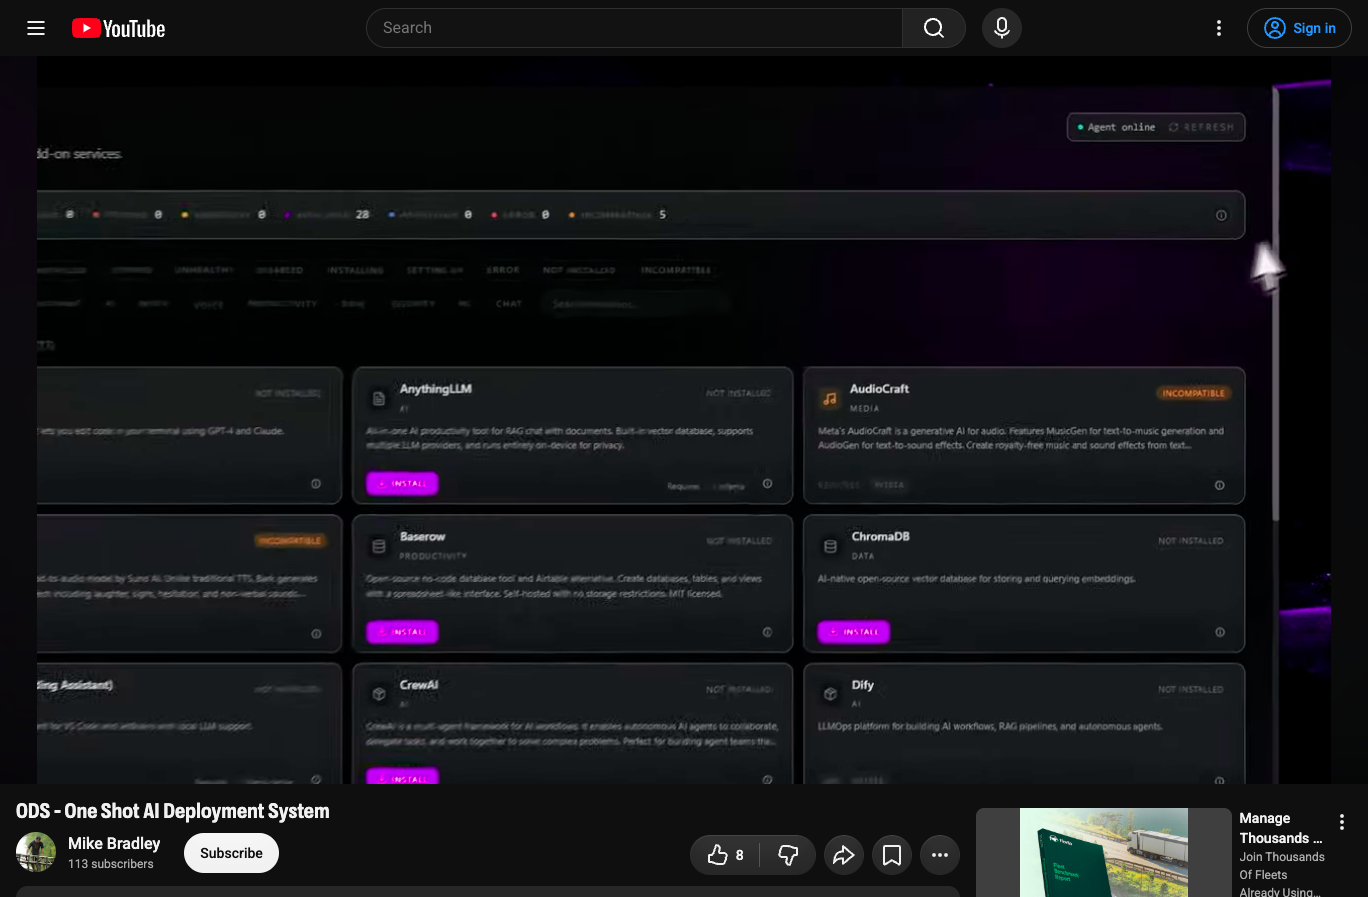
- A single web dashboard shows service health, ports, model status, storage, and updates, and every bundled service can be enabled, disabled, or inspected as an extension.
- Private By Default, Cloud Optional
- Inference runs locally with no telemetry, and optional cloud or hybrid mode routes through a LiteLLM gateway to OpenAI, Anthropic, or Together only when you enable it.
Features
- Automatic Hardware Tiering
- ODS detects GPU, VRAM, RAM, and disk, then picks a catalog GGUF model that fits, starting a small bootstrap model while the full download finishes.
- Full Local AI Stack
- The Compose stack bundles llama.cpp inference, Open WebUI chat, LiteLLM gateway, TEI embeddings, Whisper speech-to-text, Kokoro text-to-speech, and Qdrant vector storage.
- Agents And Workflow Automation
- Hermes Agent, the Portal agent, OpenCode, and n8n connect local models to tools and 400+ integrations, with the Agent Policy Engine bounding what agents may do.
- Private Search And RAG
- SearXNG and Perplexica answer questions from the web without trackers, while Qdrant-backed retrieval grounds chat answers in your own documents and embeddings.
- Privacy And Operations Tooling
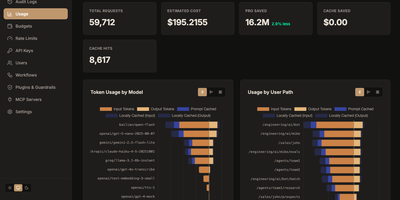
- Privacy Shield scrubs personal data before prompts leave the machine, Token Spy tracks usage, and optional Langfuse adds tracing for every model route.
- Extension-Based Service Management
- Every service is an installable extension with health checks and generated credentials, so you run only what you need and add pieces like ComfyUI later.