Stars
Forks
Watchers
Developer links
LlamaForge
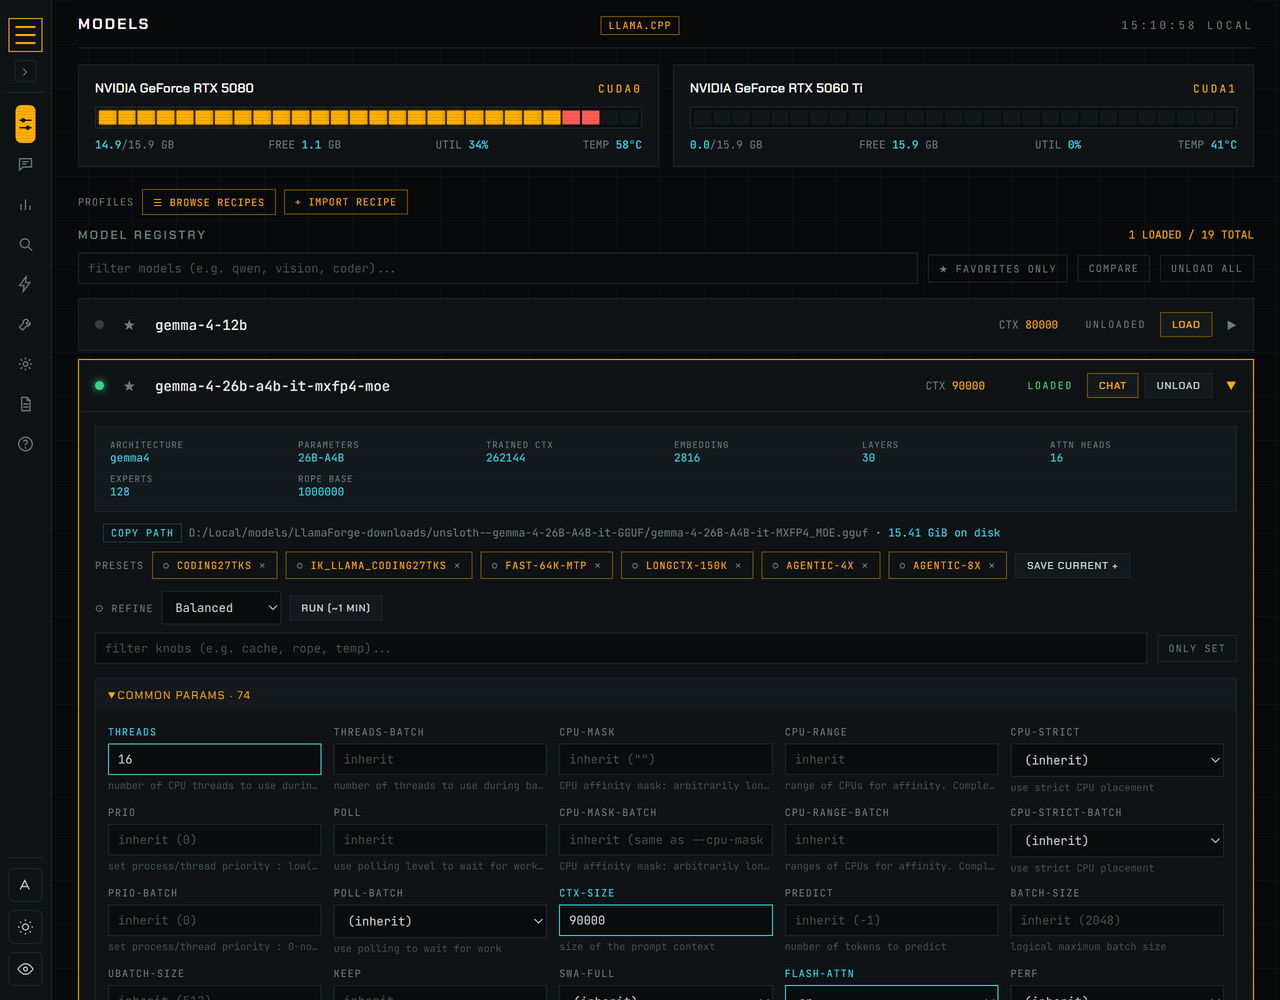
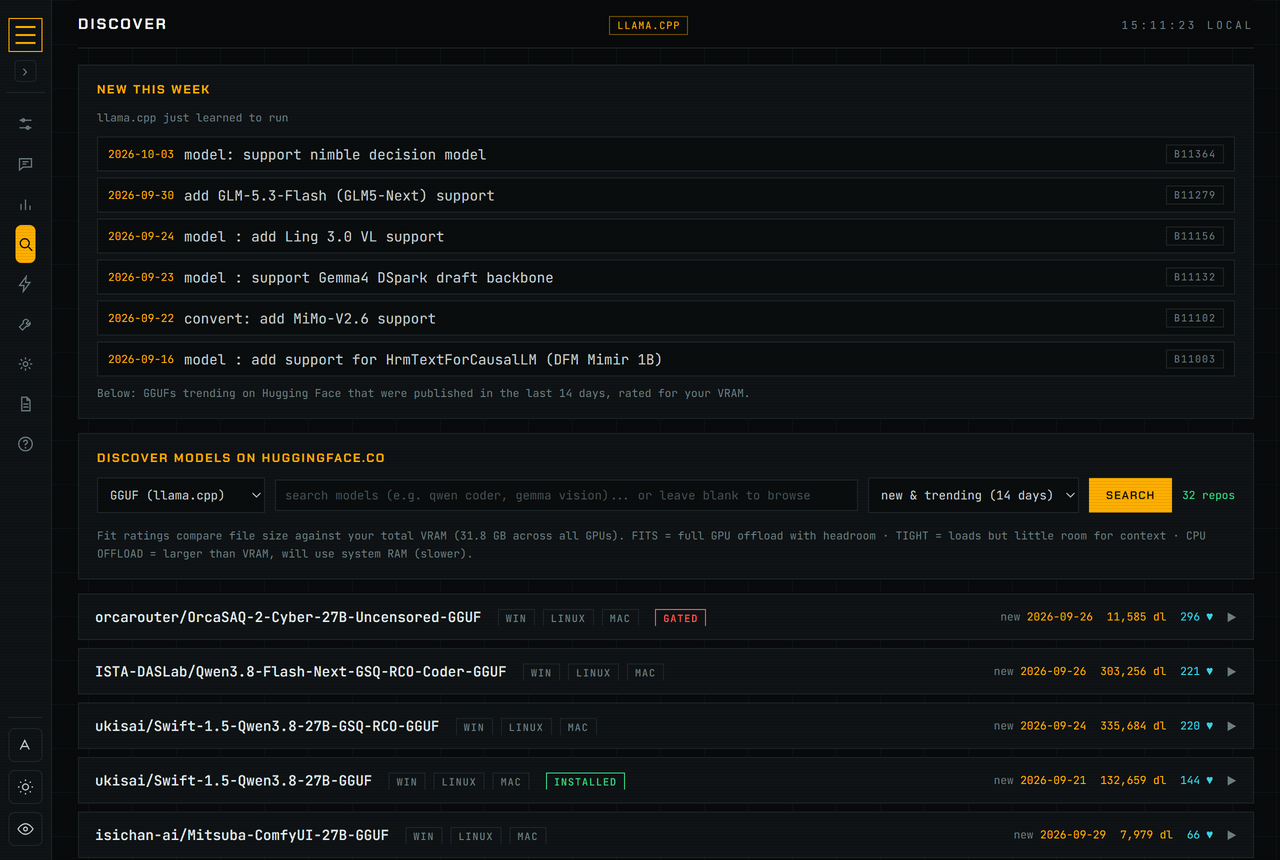
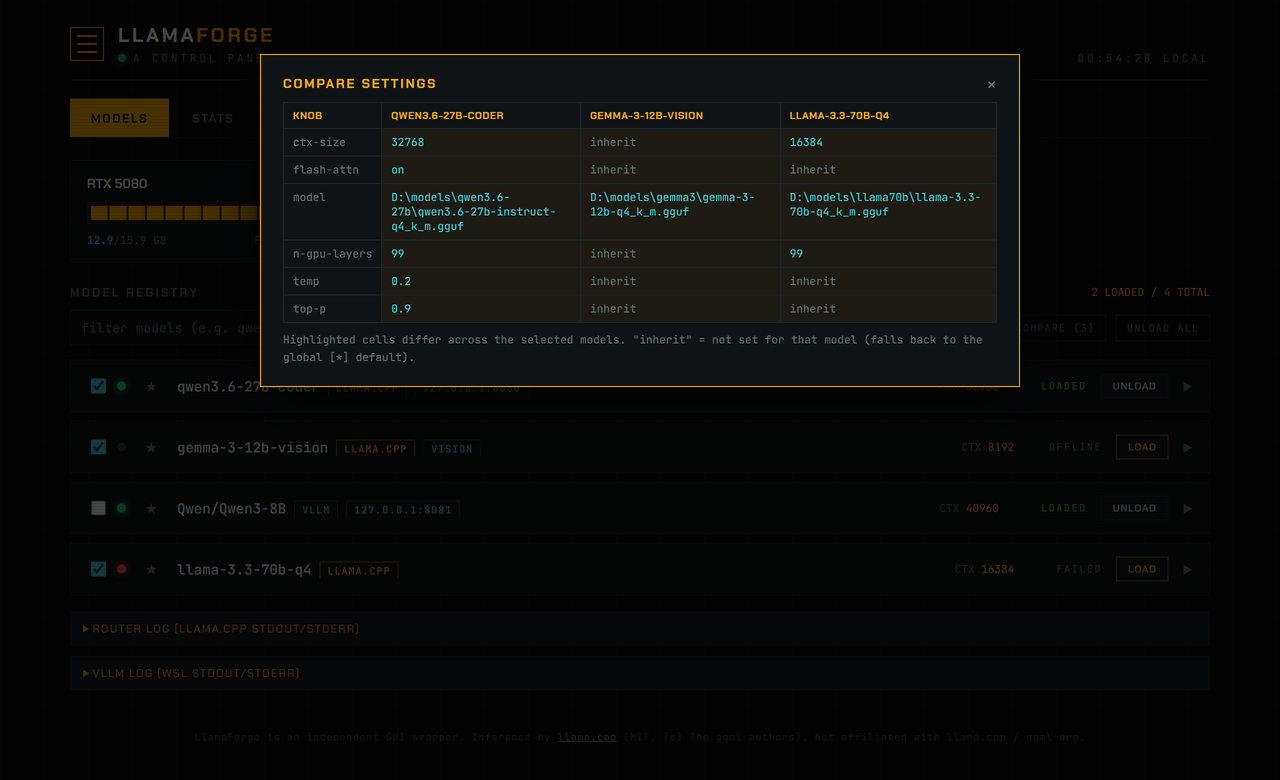
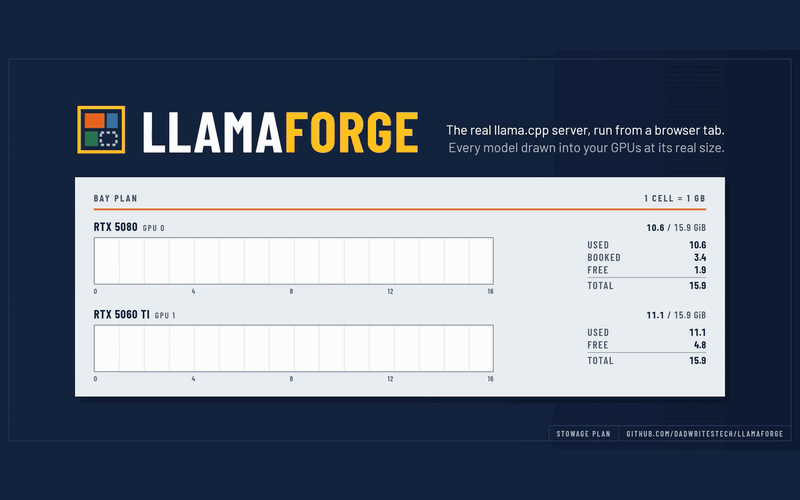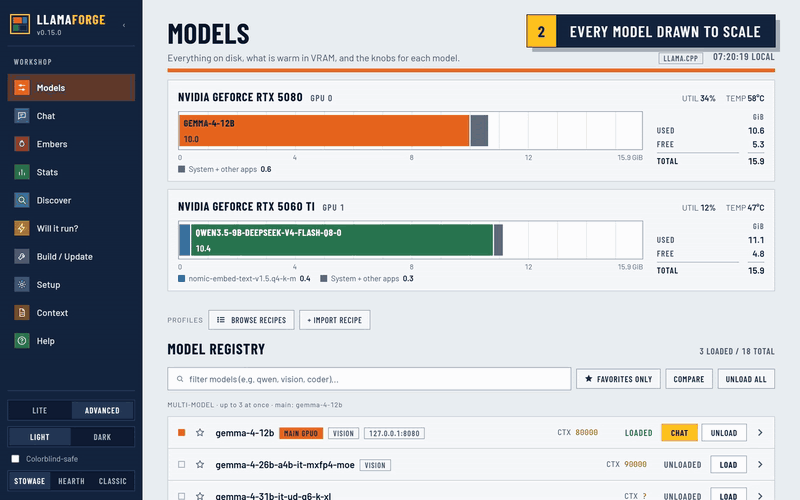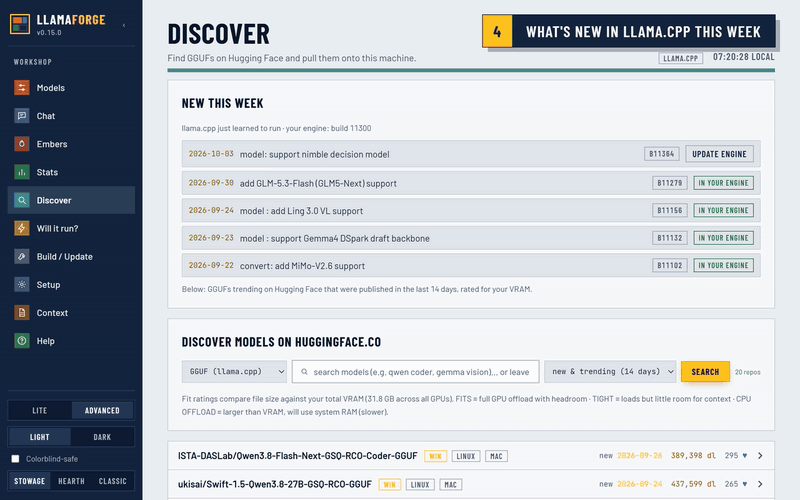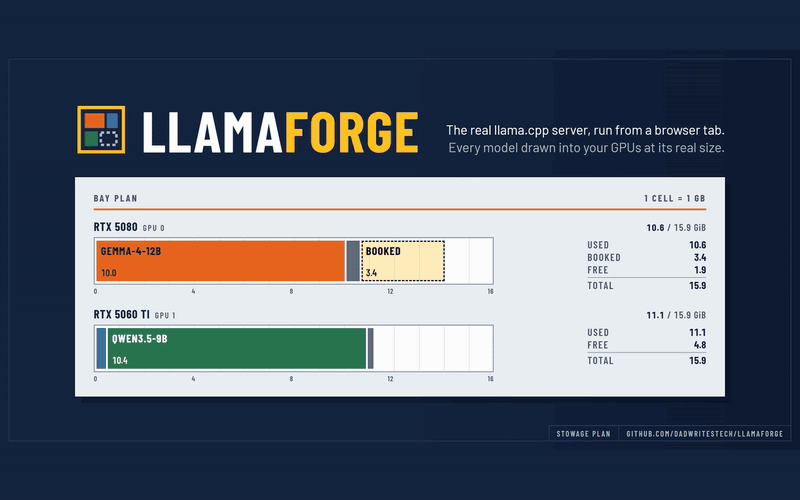
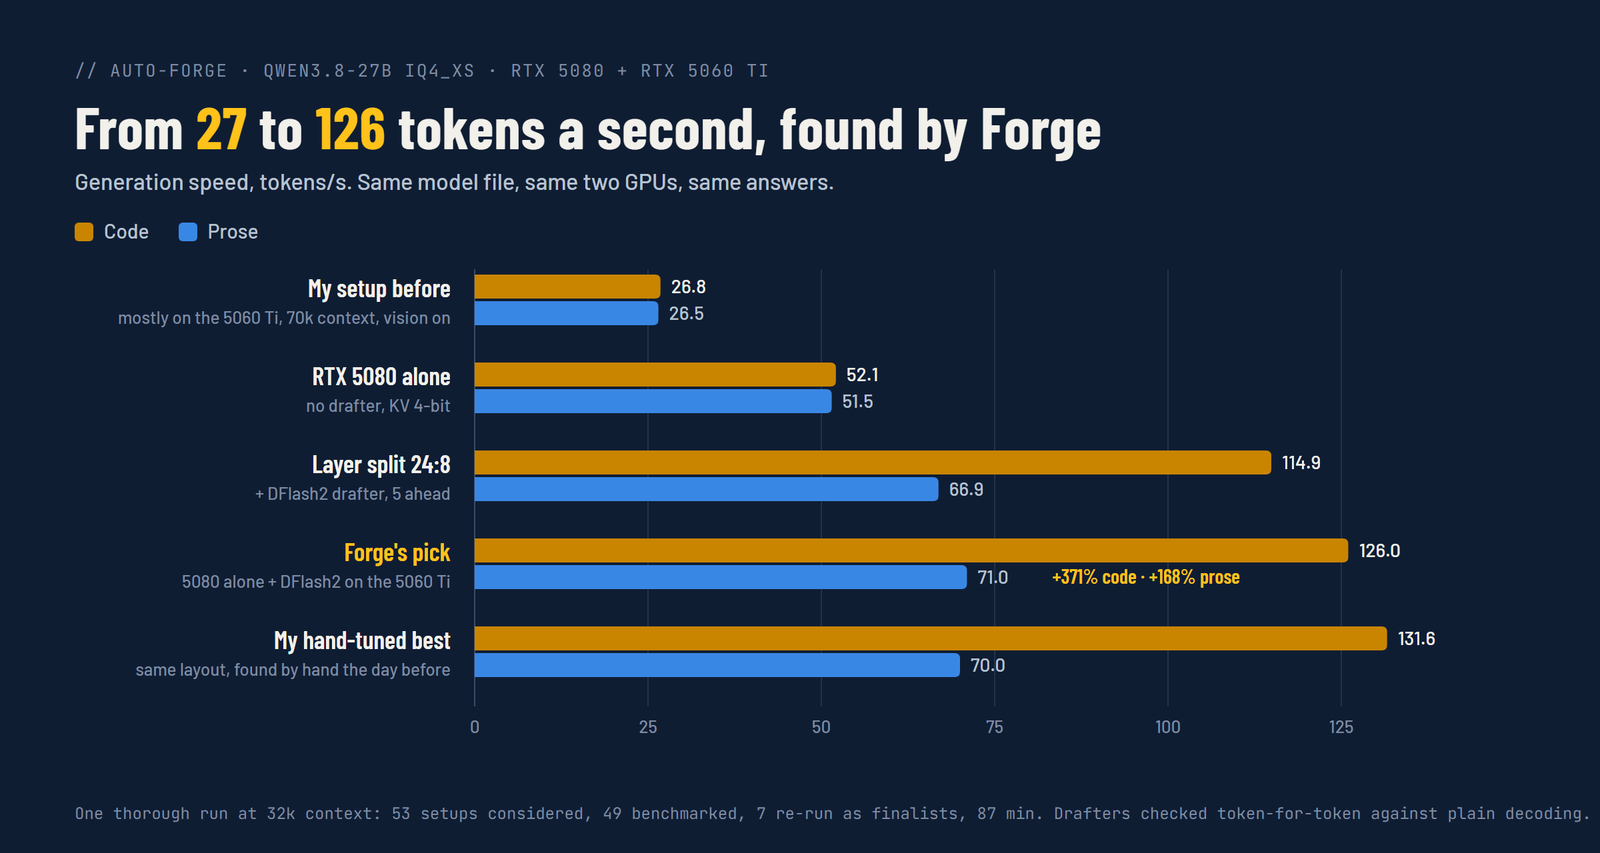
Running local models usually means choosing between a polished app that hides the engine and a terminal full of flags you half remember. LlamaForge refuses the trade: it installs and drives the official llama.cpp release itself, then puts a browser panel over all of it, every one of the 200-plus llama-server flags your build supports, grouped, searchable and editable per model. Before you load anything, each model is drawn into your GPUs at its real footprint, so the out-of-memory surprise happens on screen instead of in a crashed server; before you download anything, every quant on Hugging Face gets a fit rating for your VRAM, FITS, TIGHT or CPU OFFLOAD. Auto-Forge then measures placements, KV cache types and speculative drafters on your own hardware and keeps the fastest configuration, checking that a drafter still produces identical tokens before applying it with one click, and undoing it with one click. Keep several models loaded at once and a planner places each on the GPUs that fit it; when a game launches, Game Mode unloads your models and brings them back when you quit. Chat in llama.cpp's own interface, join from your phone by QR code, duel two models blind in the Arena under an Elo board, and let Embers, small local agents, keep a wiki and write scheduled briefs counting only facts they can quote verbatim. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- See The Fit Before Loading
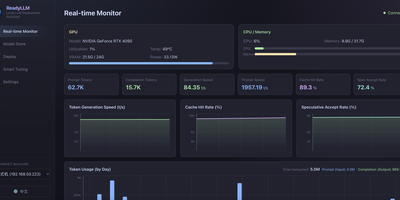
- Every model is drawn into your GPUs at its measured real size, with live VRAM, utilization and temperature per GPU, so you know it fits before loading.
- Measured, Not Guessed, Performance
- Auto-Forge benchmarks placements, KV cache types and drafters on your GPUs in a sandbox, verifies identical tokens, and applies the winner with one-click undo.
- The Real Engine, One Click Away
- LlamaForge runs official upstream llama.cpp builds, any version or your own fork, so new model architectures are one Update click away; it even runs the GGUF files Ollama already downloaded, in place, nothing copied.
- Every Flag, Per Model
- Expand any model to edit all 200-plus llama-server flags beside a GGUF metadata card, with presets and launch profiles pinning model, settings and build.
Features
- Multi-Model GPU Placement
- Keep a main model and workers loaded at once; a planner places each on fitting GPUs using measured footprints, and models can pin to their own build.
- Blind Arena With Elo
- Two models answer one prompt with names hidden; you vote, and an Elo board ranks them on your prompts and hardware, exportable as markdown.
- Embers Watch Agents
- Local agents watch a topic, keep a wiki and write scheduled briefs; items count only with verbatim source quotes, and nothing leaves the machine by default.
- Discover With Fit Ratings
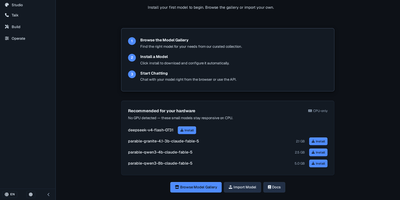
- Hugging Face search opens on architectures merged this week, checked against your build; every quant is rated FITS, TIGHT or CPU OFFLOAD before download.
- Chat, Phone And Voice
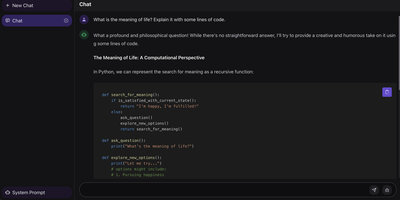
- Chat in llama.cpp's own UI, scan a QR code to chat from your phone over Wi-Fi or Tailscale, and synthesize speech with Qwen3-TTS or Pocket TTS.
- Elastic VRAM And Game Mode
- When another app needs the GPU, a loaded model shifts layers to CPU, keeps its conversation, then moves back; Game Mode unloads at launch, restores after.