Stars
Forks
Watchers
Developer links
Paddler
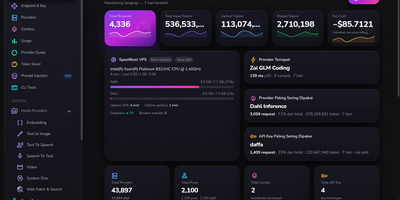
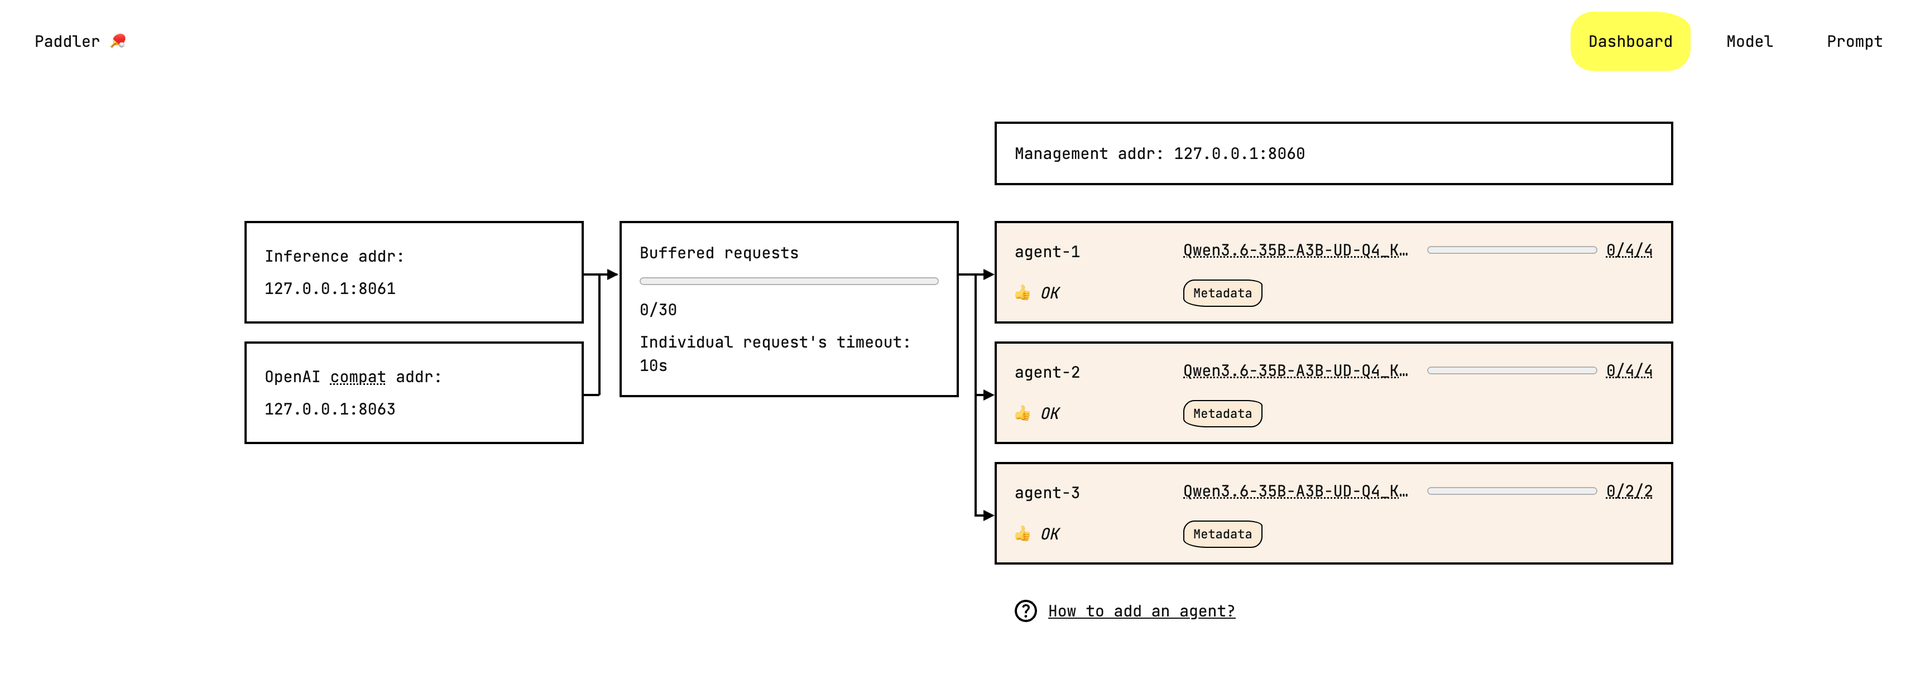
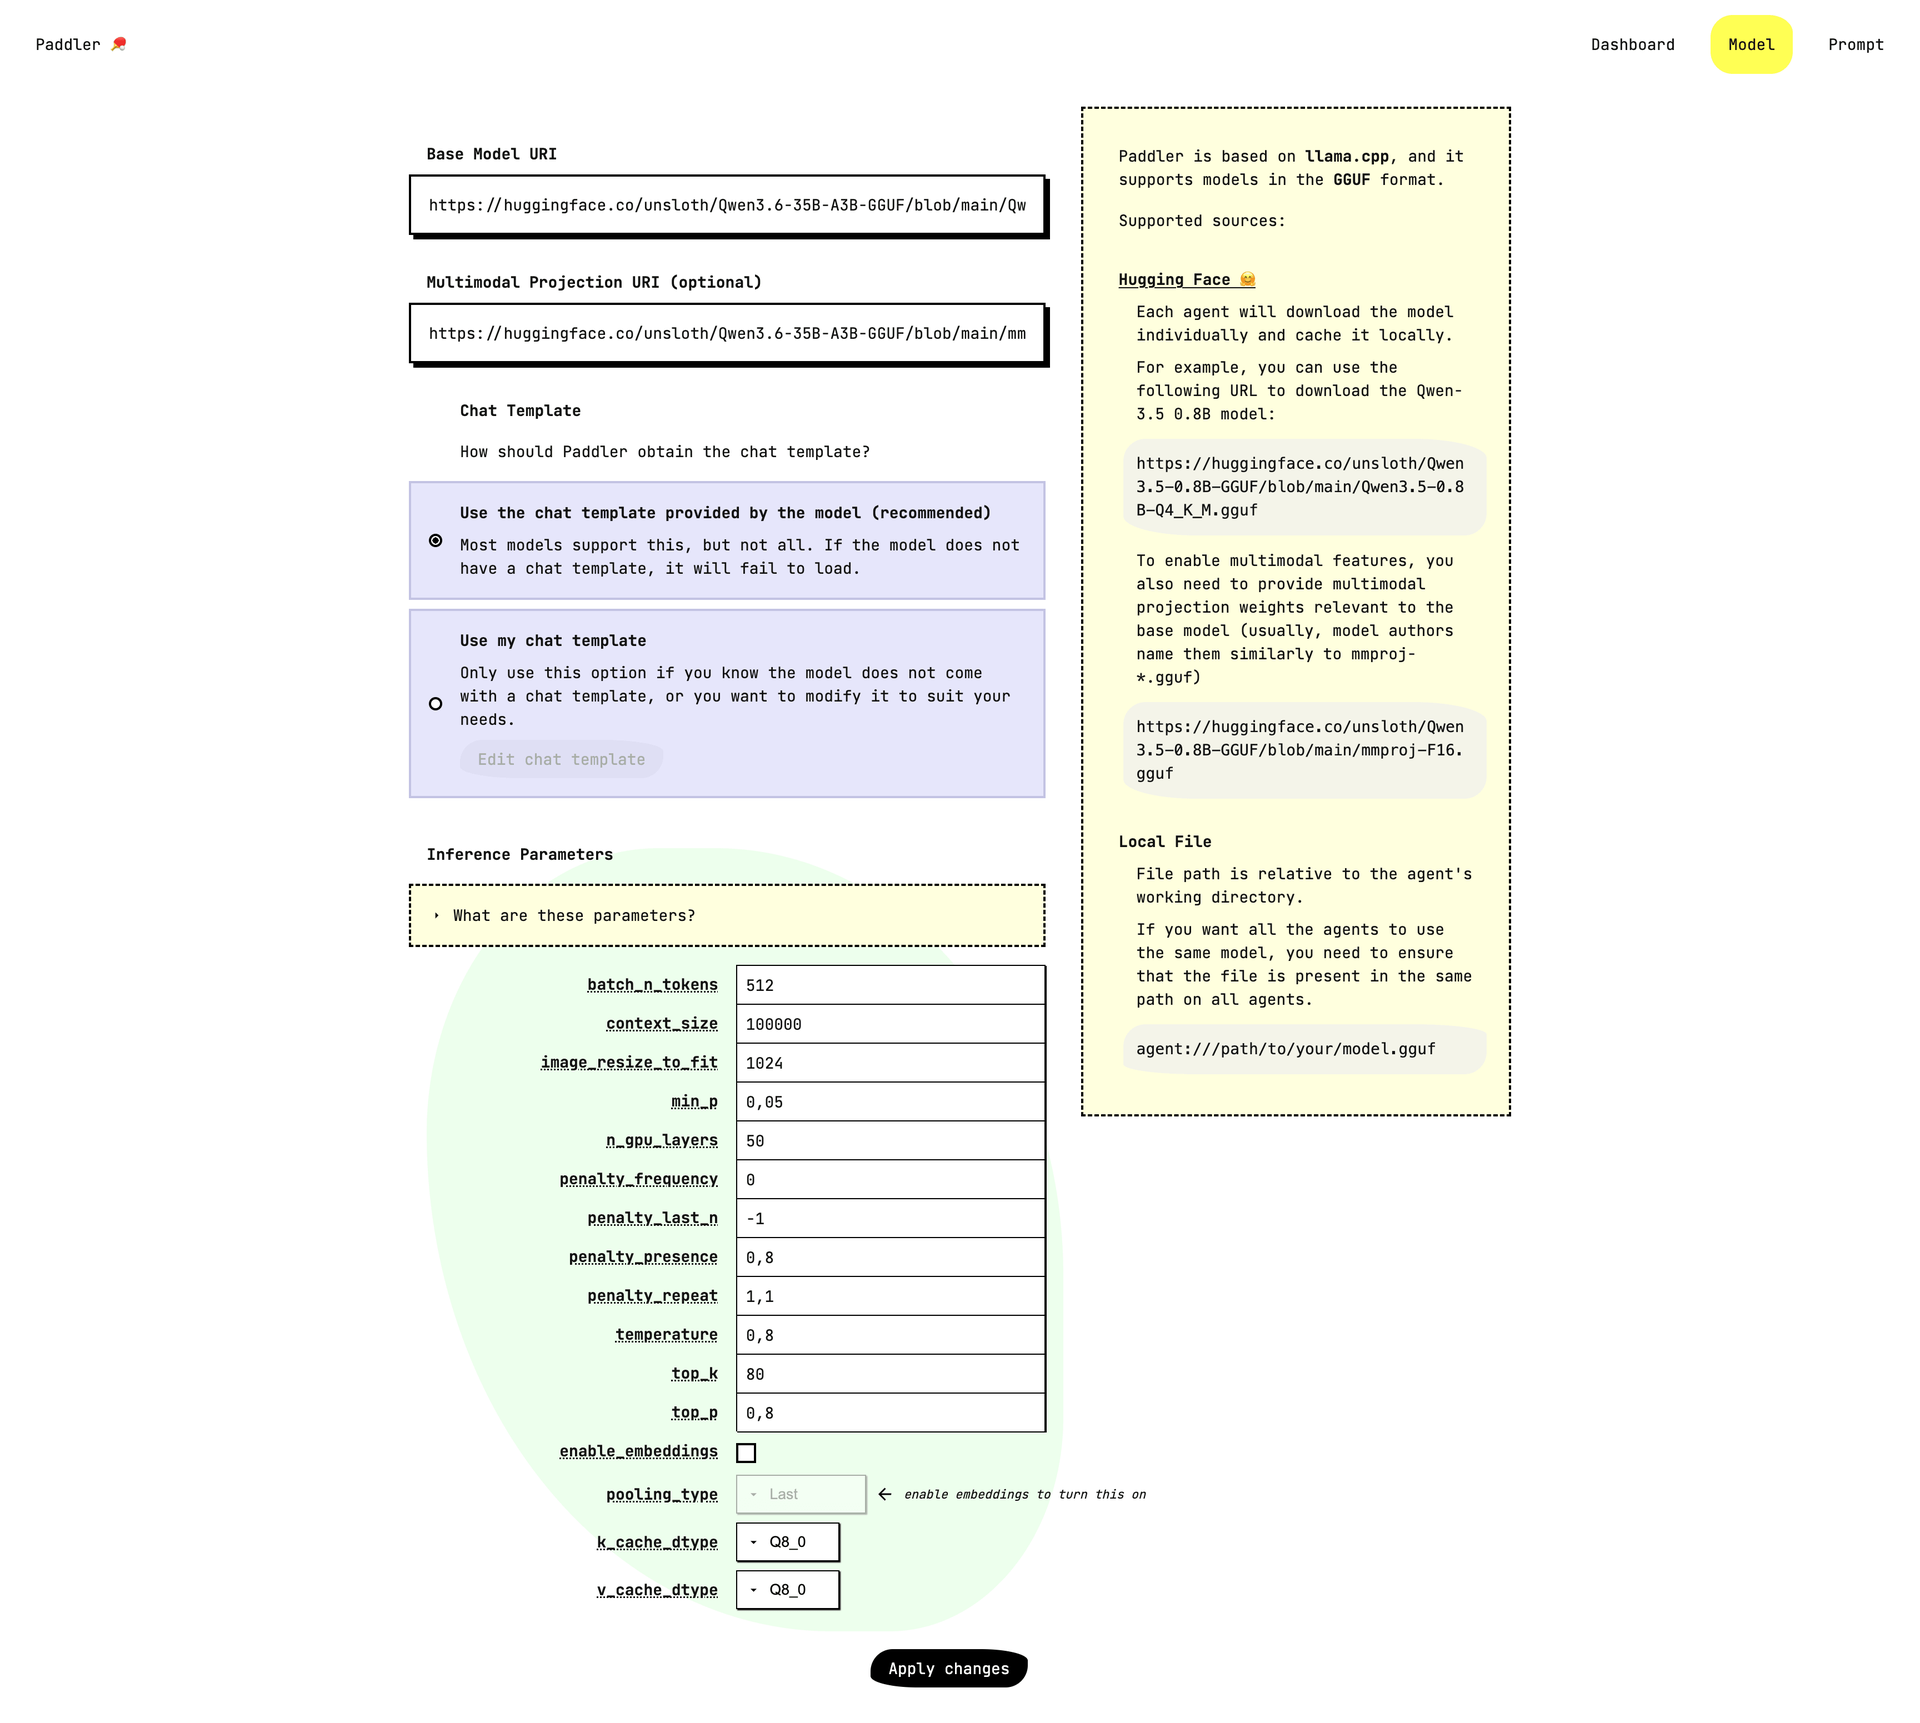
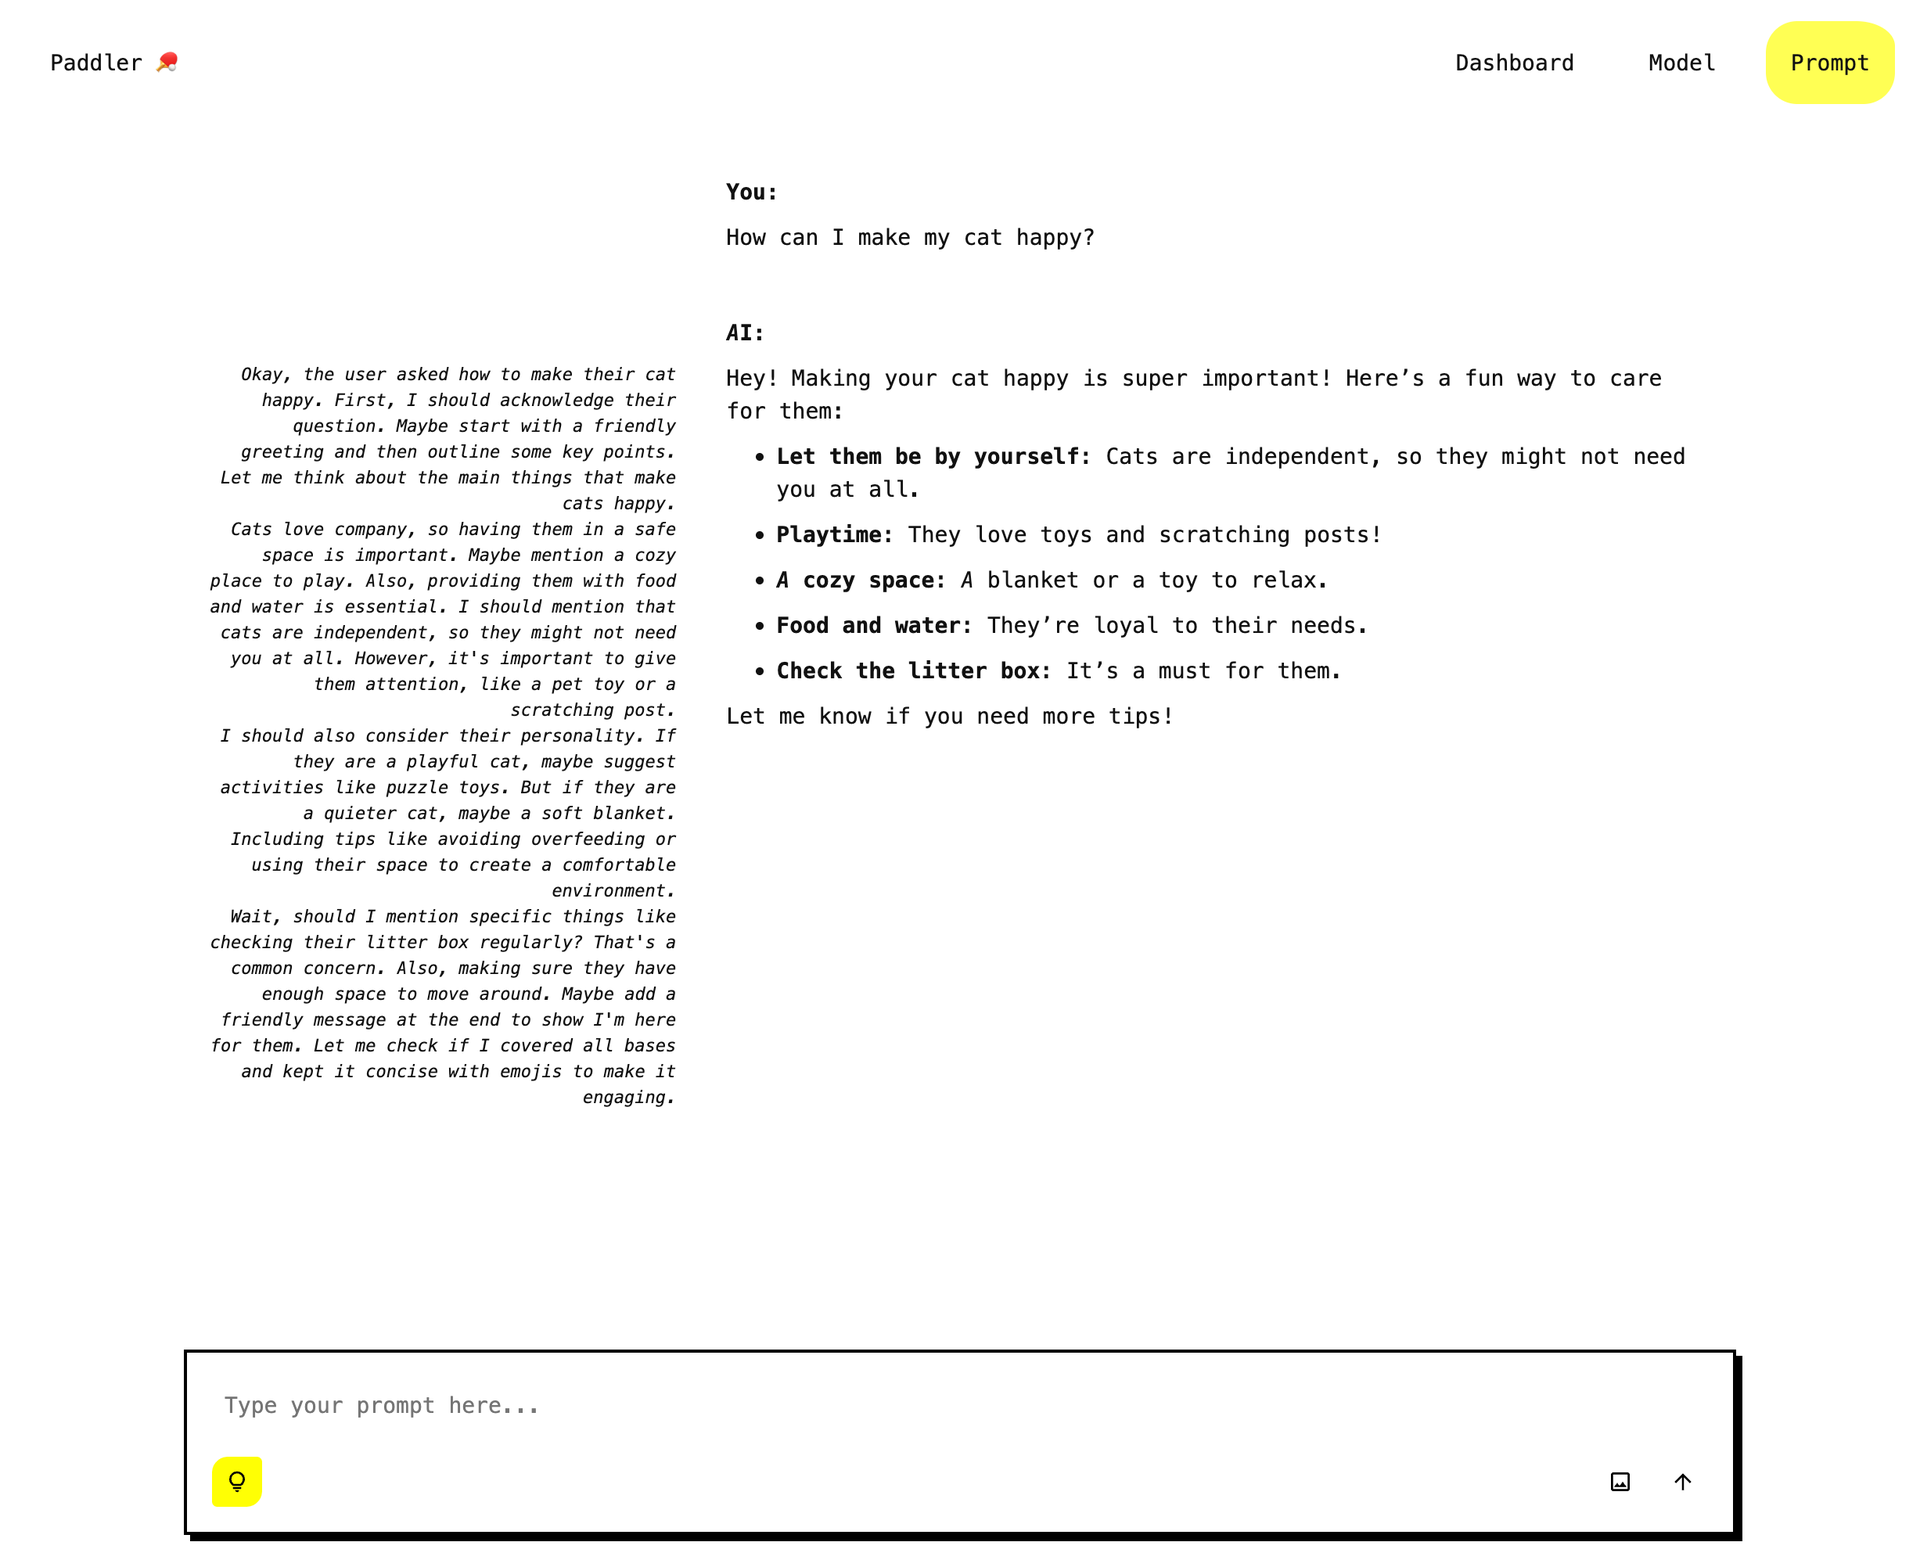
One binary. A fleet of machines. One calm endpoint for inference. Paddler balances large language model traffic across whatever hardware you already own, instead of renting tokens by the million. The balancer exposes an inference service, a management service, and a web admin panel from a single self-contained program. Agents on separate machines generate tokens and embeddings through slots, each carrying its own context and KV cache. Inference runs on the built-in llama.cpp engine, CPU or GPU. Need a different model? Swap it dynamically, no rebuild, no redeploy. Capacity follows demand: agents join the fleet when traffic grows and leave when it fades, and request buffering holds early work in a queue so scaling up from zero hosts drops nothing. Operators watch fleet health through observability metrics, configure models, chat templates, and inference parameters in the admin panel, and test prompts graphically before users ever see a change. A desktop edition drafts office workstations into service beside the rack servers. For medical, financial, or otherwise sensitive prompts, everything stays inside your own network, and predictable hardware replaces per-token pricing exposure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
Benefits
- LLM-Aware Load Balancing
- Balancing understands llama.cpp slots, context, and KV cache instead of treating inference like generic HTTP traffic, so requests land where they will actually run well.
- Scales From Zero Hosts
- Request buffering holds incoming work until agents appear, letting autoscaled fleets start from zero machines and grow into traffic without dropping early requests.
- One Binary Deployment
- Balancer, inference, management, and admin panel ship in a single self-contained file, removing the moving parts that make clustered inference platforms painful to run.
- Predictable Private Inference
- Prompts and documents stay inside your own network on hardware you already budget for, replacing per-token pricing exposure for sensitive workloads.
Features
- Built-In llama.cpp Engine
- Inference runs through an integrated llama.cpp engine on CPU and GPU, with a custom slot implementation keeping per-slot context and KV cache.
- Dynamic Agent Fleet
- Agents register and leave dynamically and distribute requests to slots, integrating with autoscaling tools for elastic capacity.
- Dynamic Model Swapping
- The model the fleet serves can be changed at runtime, along with chat templates and inference parameters, from the management tooling.
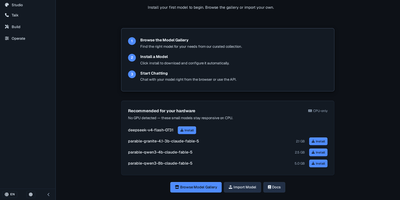
- Web Admin Panel
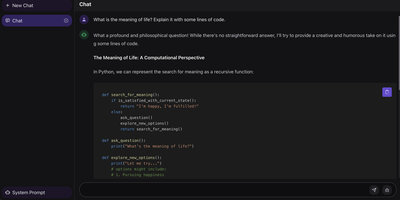
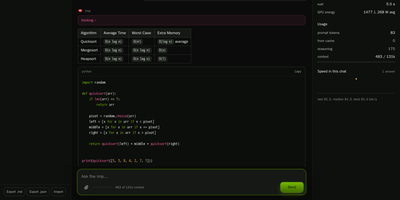
- The panel monitors the fleet, edits model configuration, and offers a graphical prompt tester for validating inference behavior.
- Observability Metrics
- Fleet metrics expose agent and slot health to operators, supporting monitoring of production self-hosted inference.