Categories
Developer Tools AI Agents Analytics Tracing Agent Evaluation AI Observability LLM MonitoringStars
Forks
Watchers
Developer links
PandaProbe
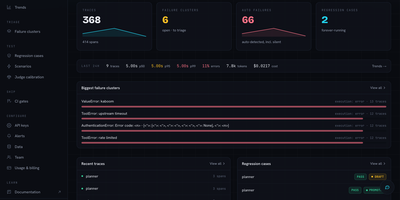
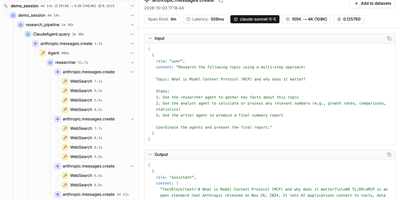
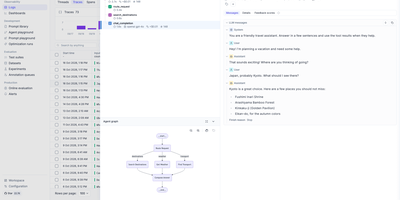
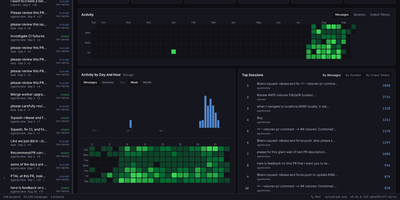
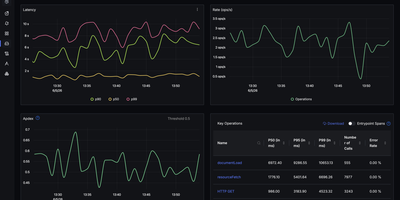
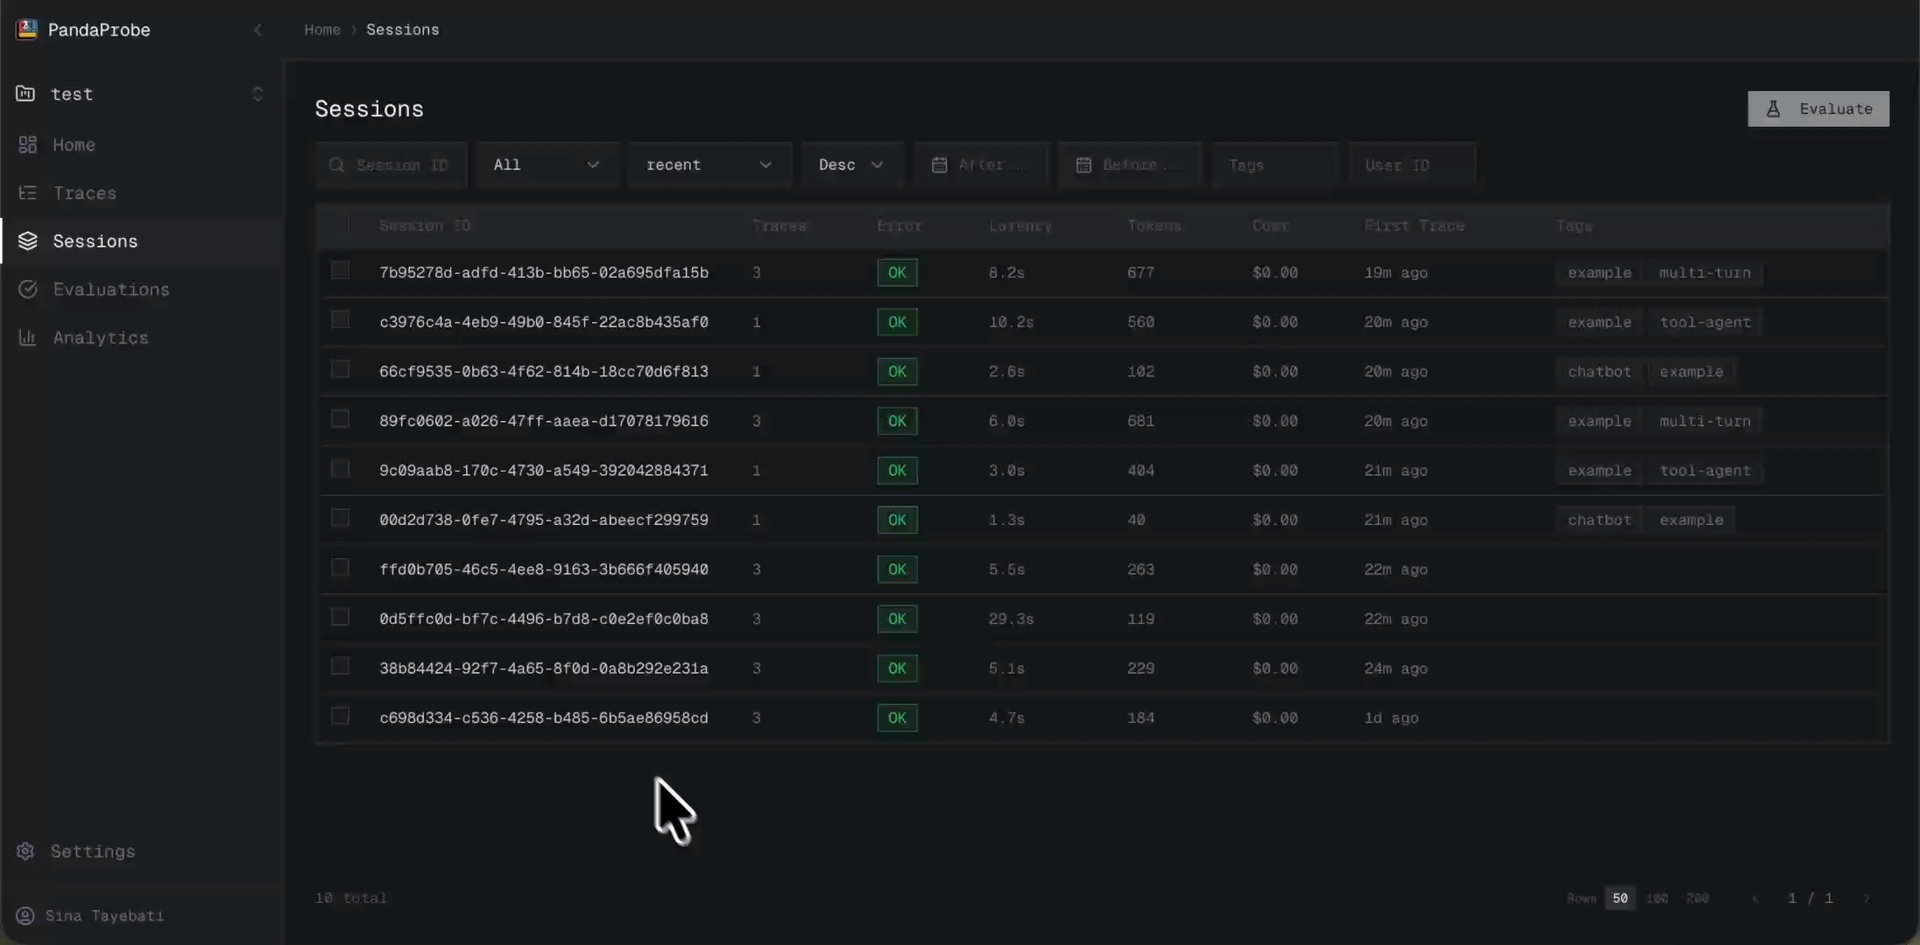
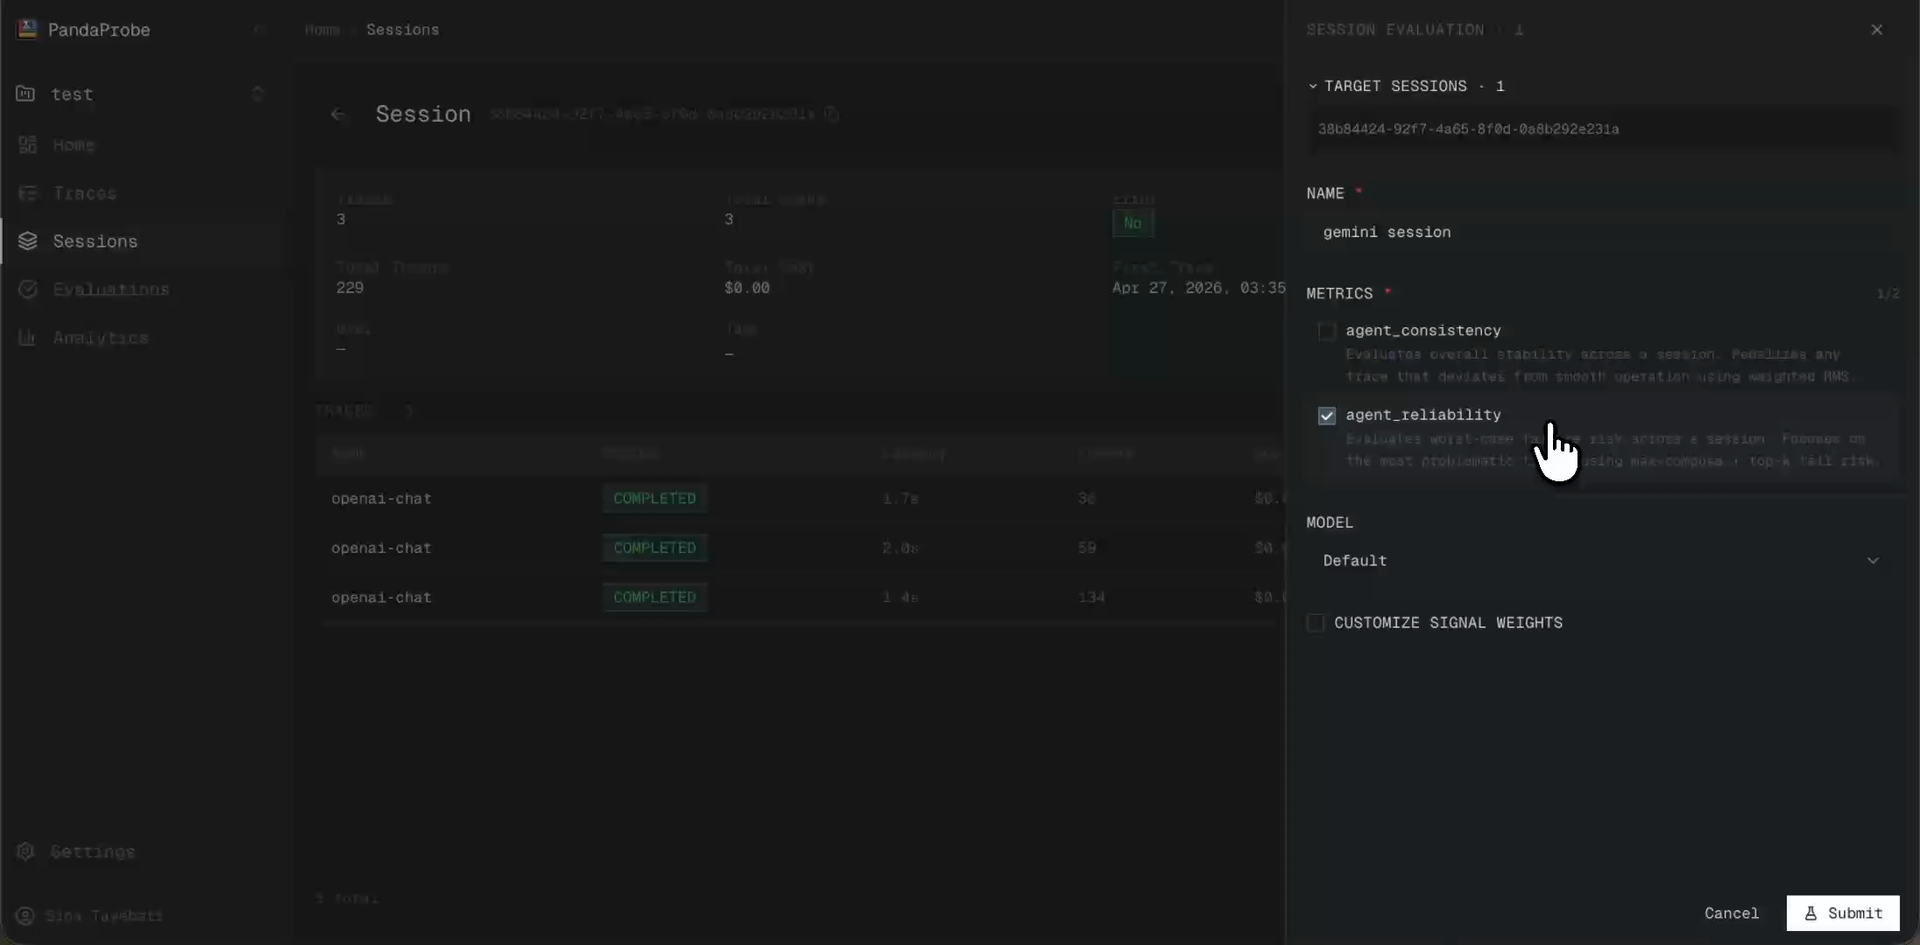
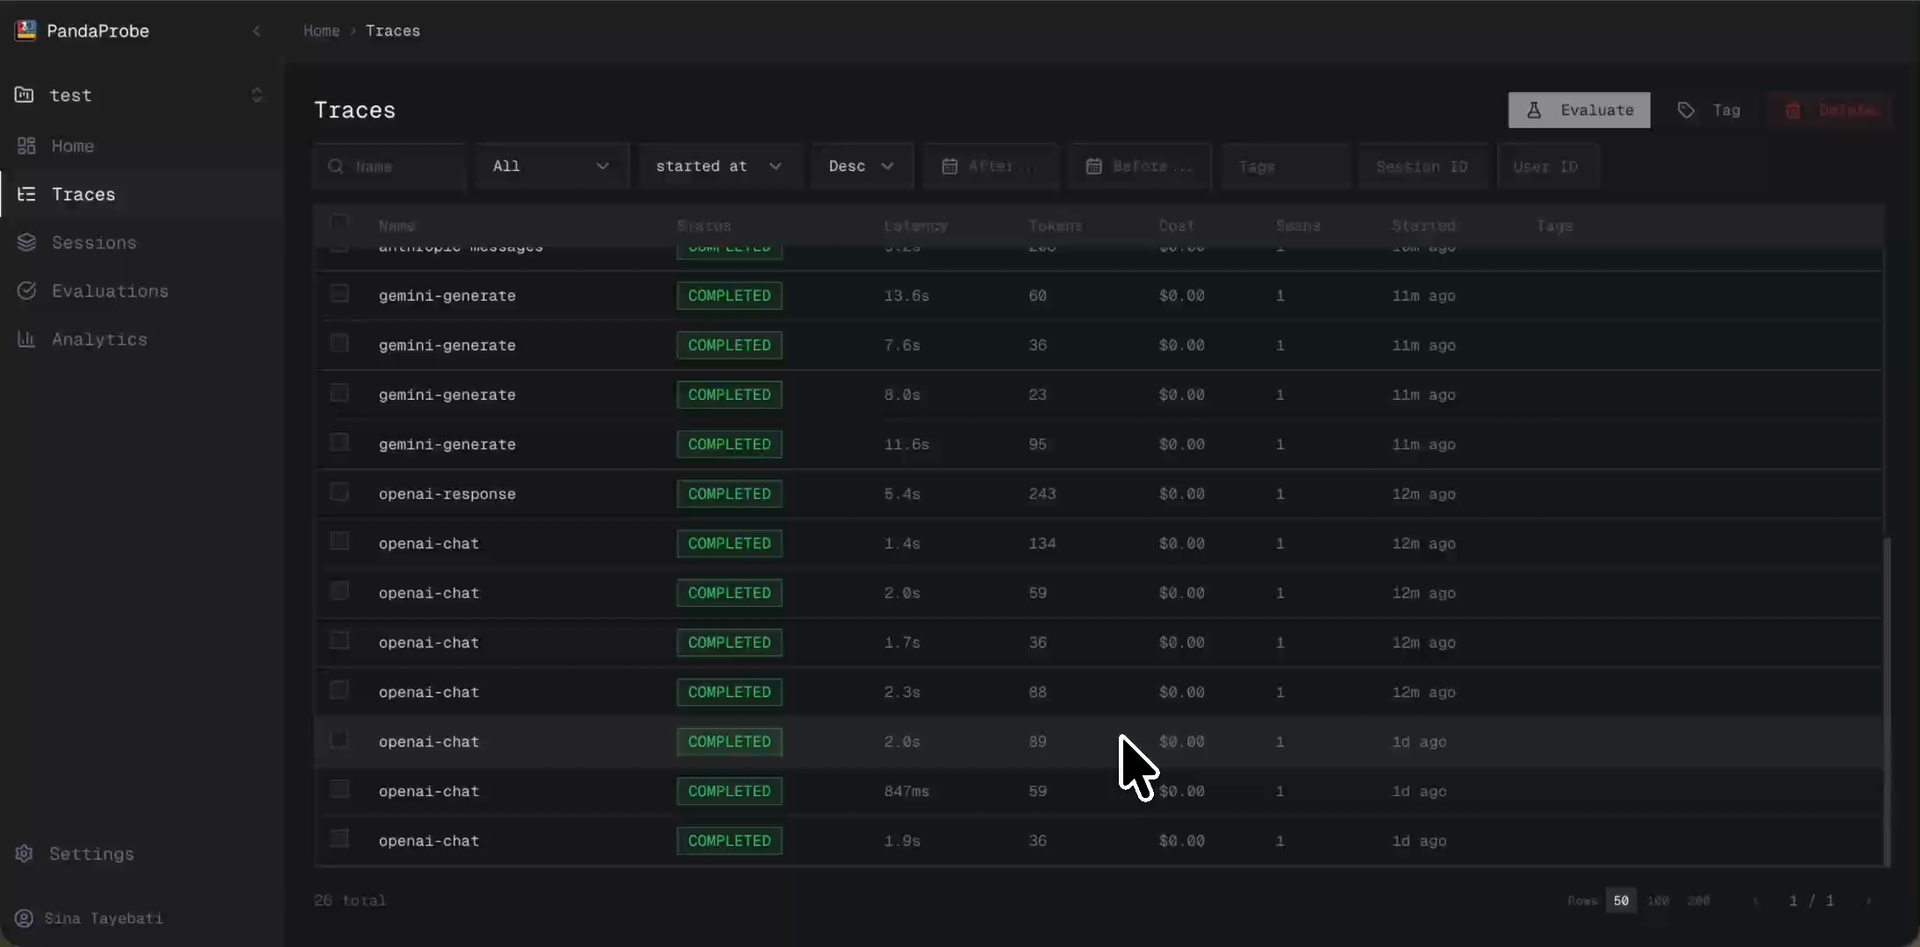
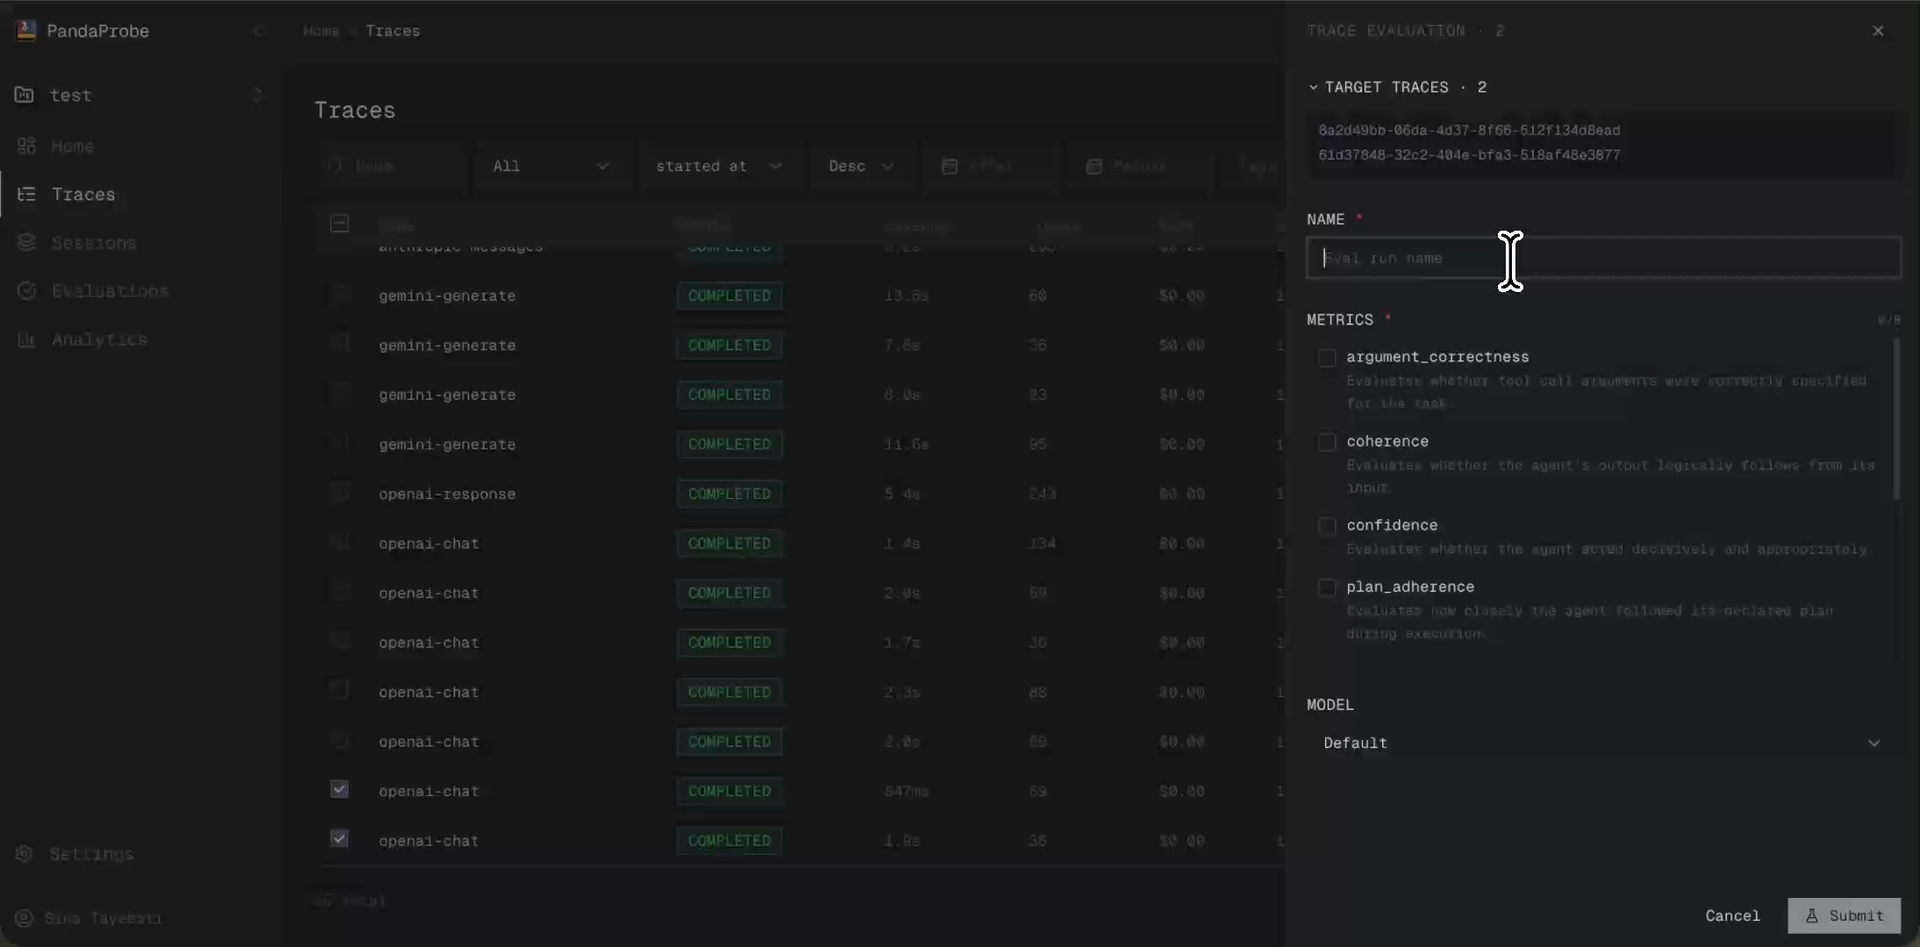
A looping agent burns money quietly until someone can see where it drifted, and PandaProbe is an observability and evaluation platform for AI agents that makes that drift visible step by step. Capture complete executions as sessions, traces, and spans spanning model calls, tool calls, multi-agent handoffs, and custom logic, then follow a looping or failing run back to the decision where it drifted. Score traces and sessions with agent-specific metrics, run asynchronous and sampled evaluations so judge models do not cost more than inference, and use lightweight trajectory signals to catch stalls, bad tool use, and regressions over time. Bring agents built with LangGraph, CrewAI, the Claude Agent SDK, the OpenAI Agents SDK, and other integrations, with MCP tool calls captured automatically where supported. Organize work by user, organization, and project, send data through an SDK or HTTP API with project keys, and query filtered, paginated traces when you need the raw record. Keep sensitive workflows local when that matters: prompts, traces, and evaluation results stay inside the deployment you run, instead of leaving for a hosted console. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- See Full Agent Trajectories
- Sessions, traces, and spans preserve the whole execution path across models, tools, agents, and custom code, so a late failure can be traced back to the earlier decision that caused it.
- Evaluate Without Overspending Judges
- Asynchronous and sampled evaluations, composable metrics, and structural trajectory signals measure quality continuously while avoiding the cost of running an expensive judge model on every single production trace.
- Keep Sensitive Workflows Local
- Self-hosting keeps prompts, traces, client data, and evaluation results inside your own deployment, which suits confidential agent workflows that should never leave for a third-party observability service.
- Works With Your Agent Stack
- Integrations for LangGraph, CrewAI, the Claude Agent SDK, and the OpenAI Agents SDK, plus SDK and HTTP ingestion, let existing agents report traces without a rewrite of their core logic.
Features
- Session Trace Span Capture
- Full agent executions are stored as structured sessions containing traces and spans for model calls, tool calls, agent steps, and custom logic, queryable later with filters and pagination.
- Trace And Session Evaluations
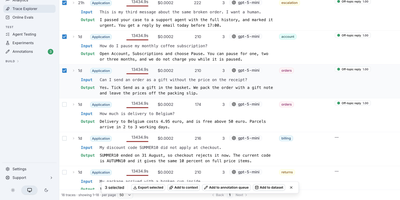
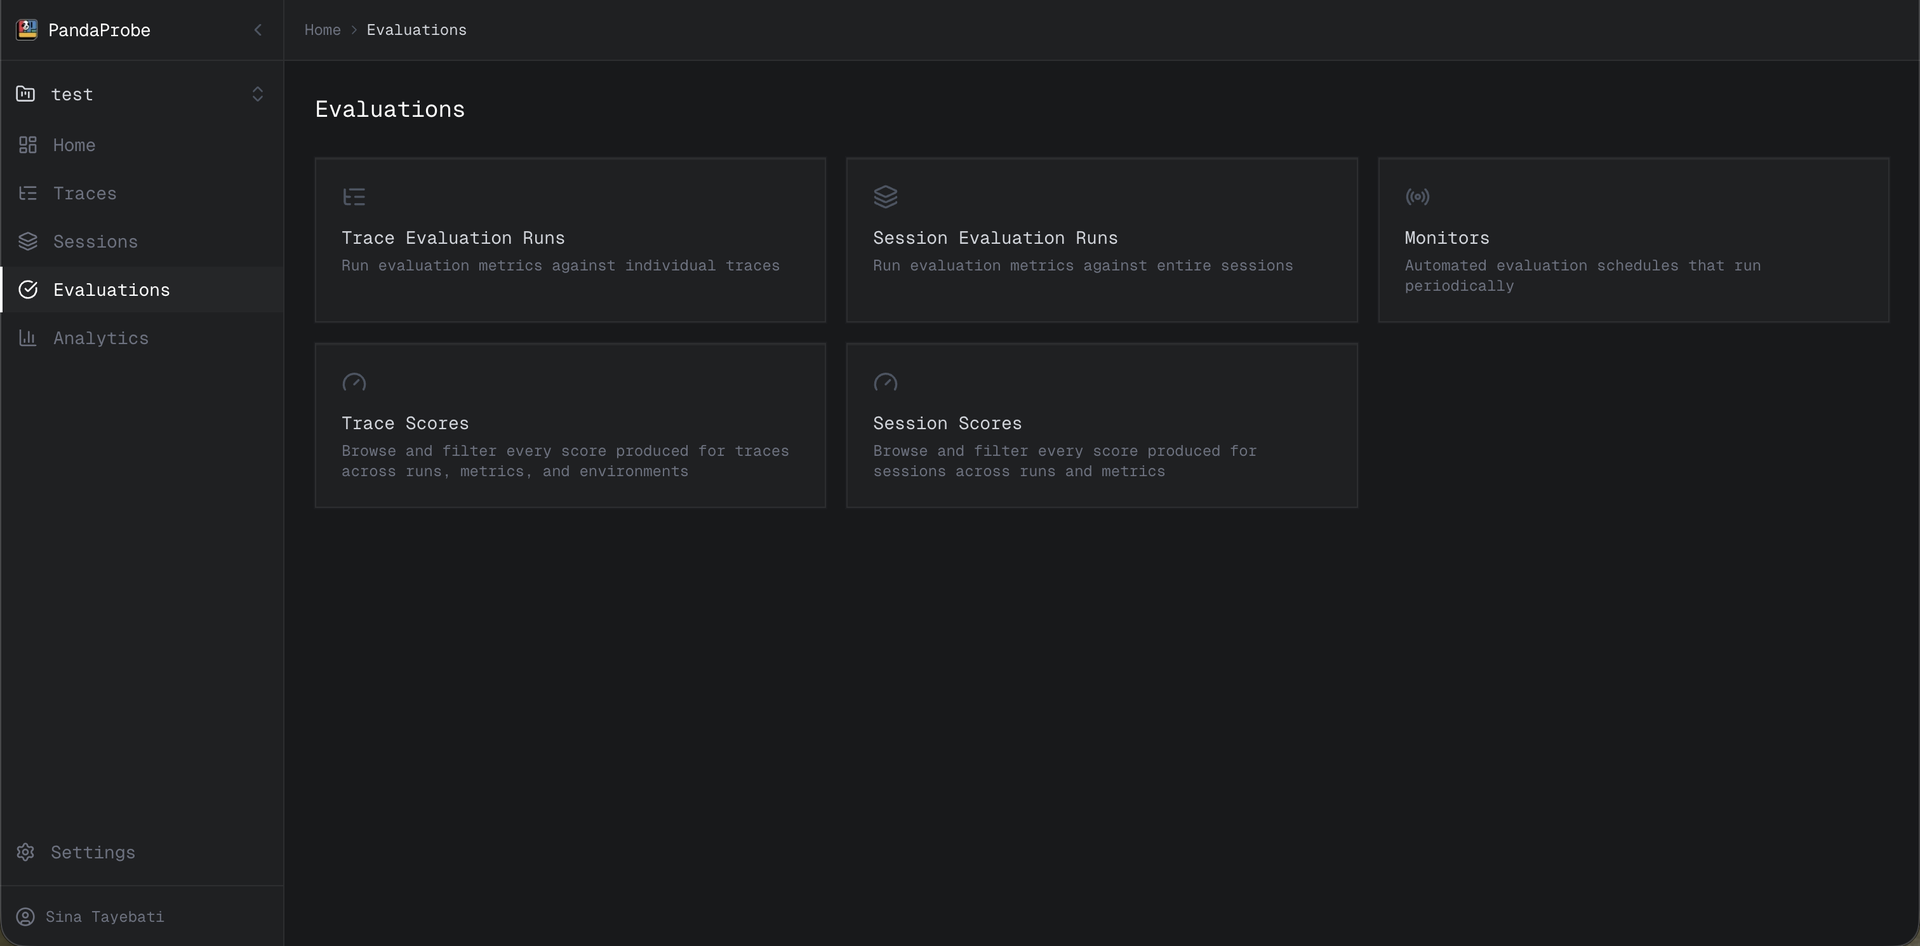
- Agent-specific metrics score individual traces and whole sessions, with LLM-as-a-judge evaluations persisted alongside the execution record so quality can be compared across runs and releases.
- Async Sampled Evaluation Jobs
- Evaluation requests are enqueued and processed by background workers, supporting sampled and asynchronous scoring that controls judge cost while still detecting drift, looping, and stalled progress.
- Framework Integrations Built In
- LangGraph, CrewAI, Claude Agent SDK, and OpenAI Agents SDK integrations report executions directly, and supported integrations capture MCP tool calls automatically as part of the trace.
- Organizations Projects API Keys
- Users, organizations, and projects scope access, management calls use authenticated identity tokens, and data-plane ingestion uses API keys with project names to route traces to the right workspace.