Categories
Developer Tools Analytics Machine Learning AI Tools LLM Evaluation Benchmarking Model ComparisonDeveloper links
LMRing
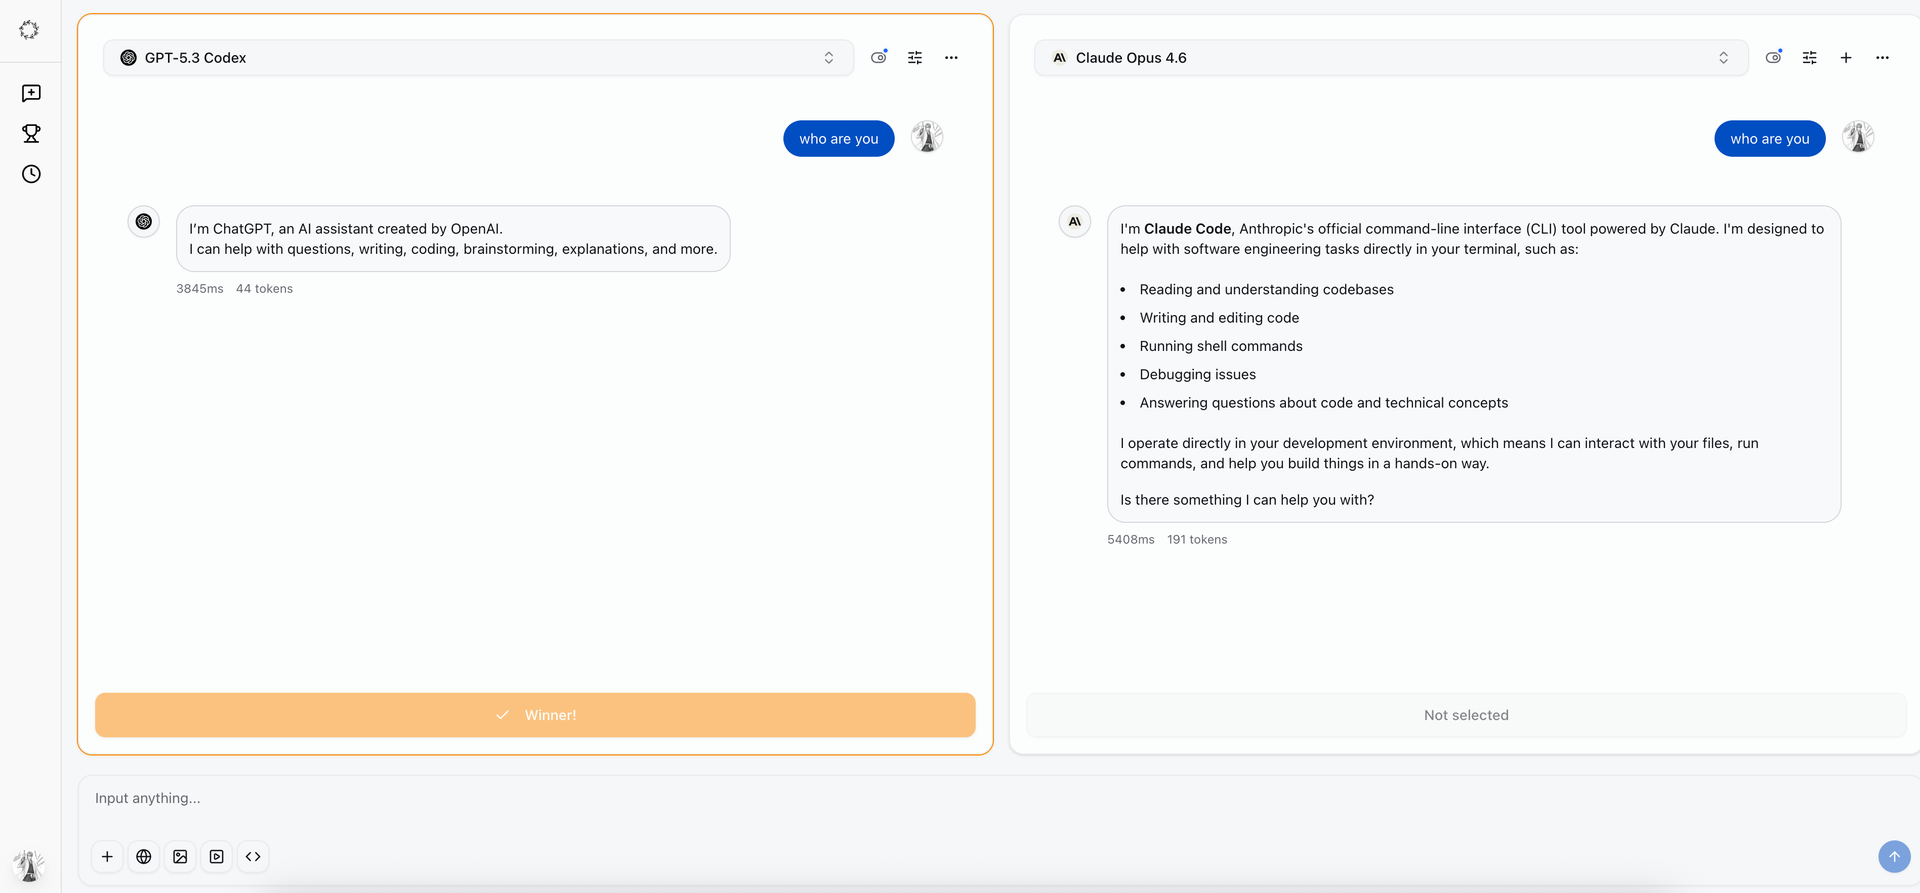
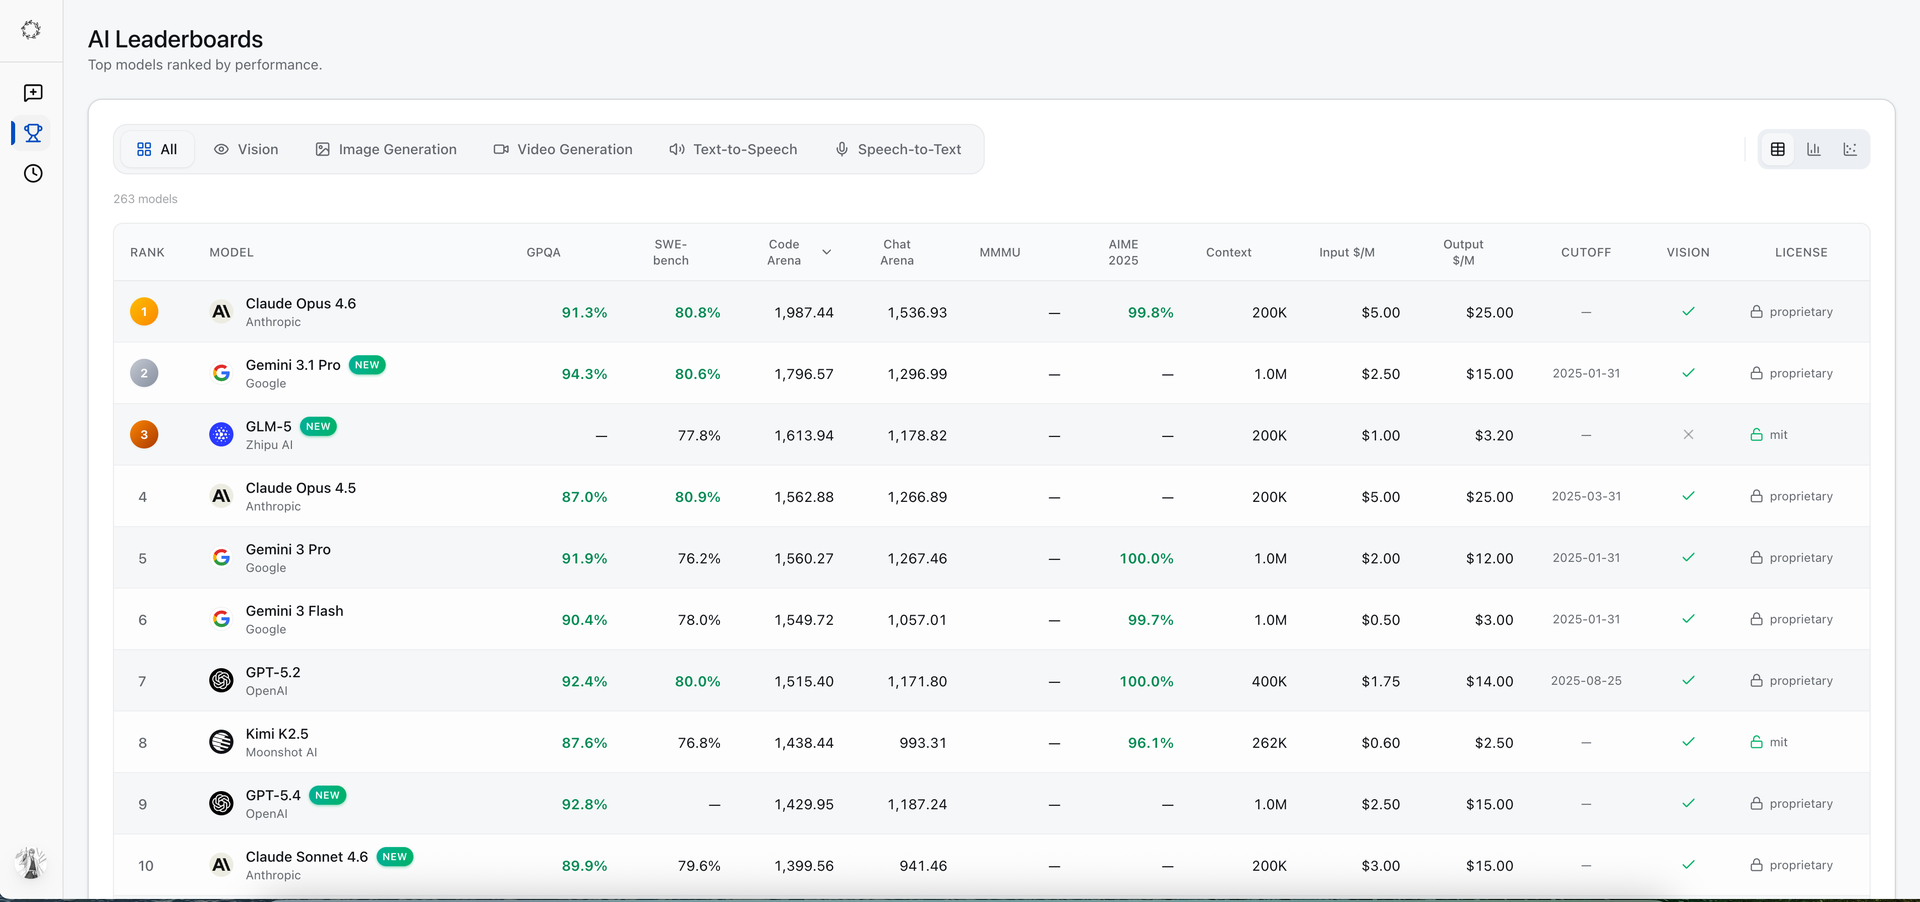
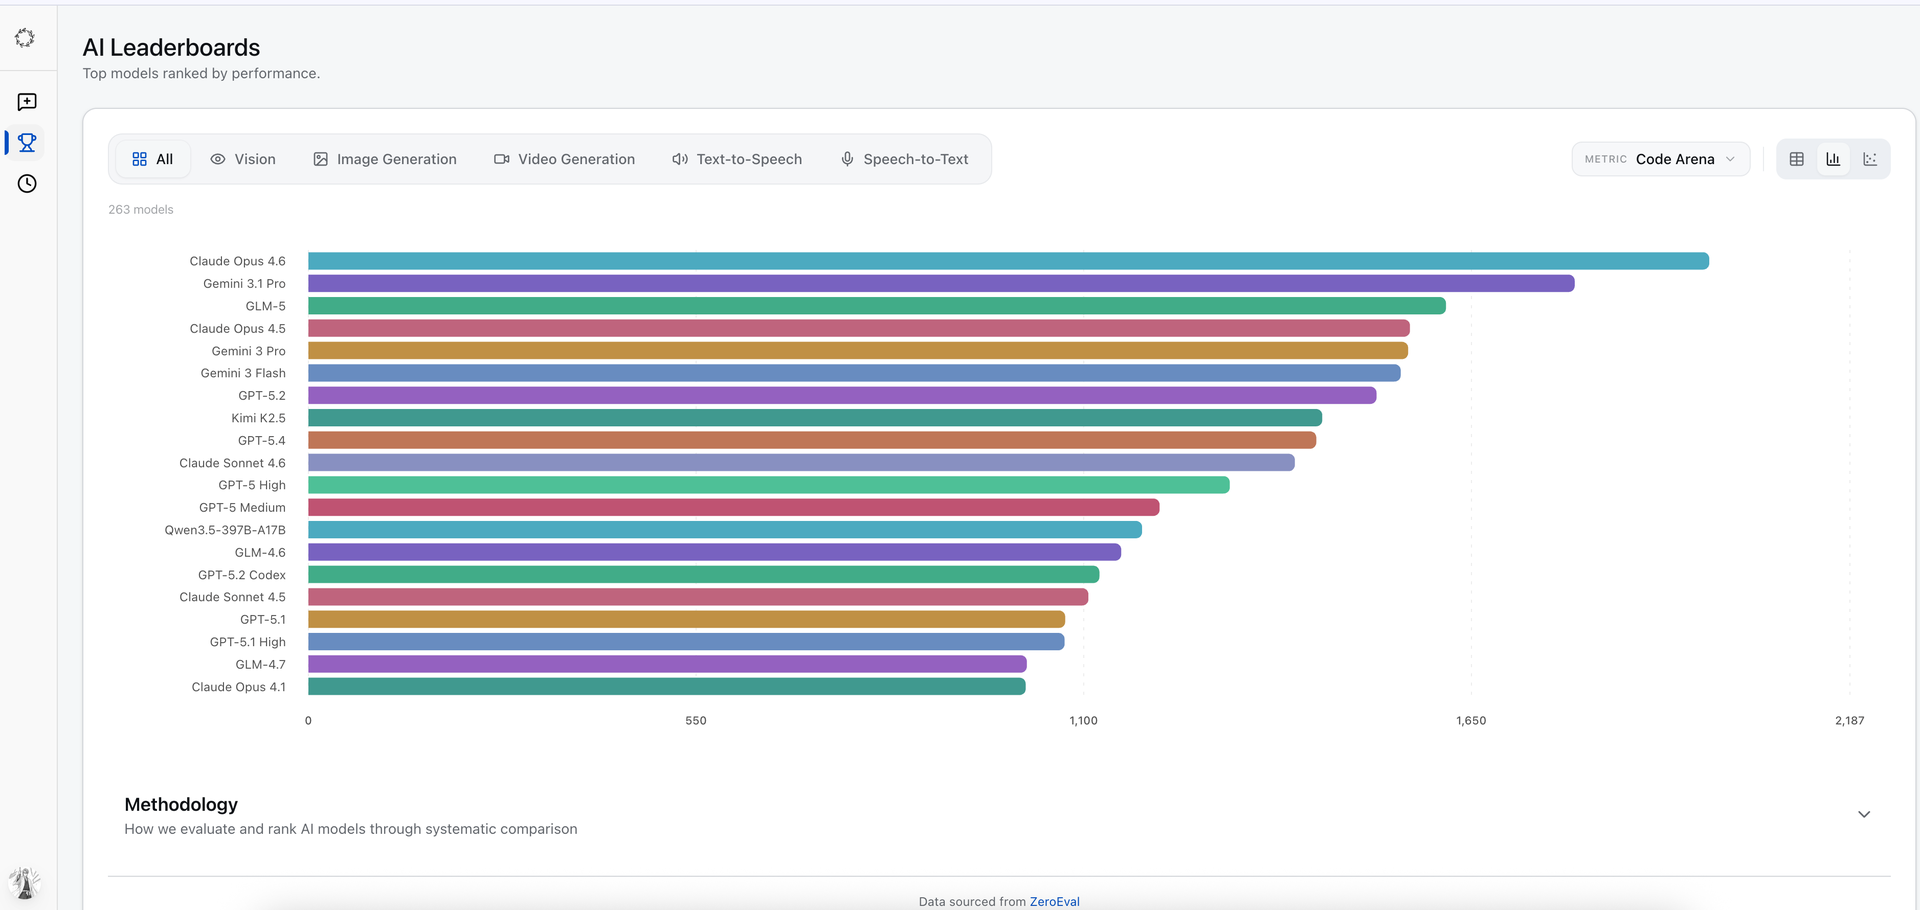
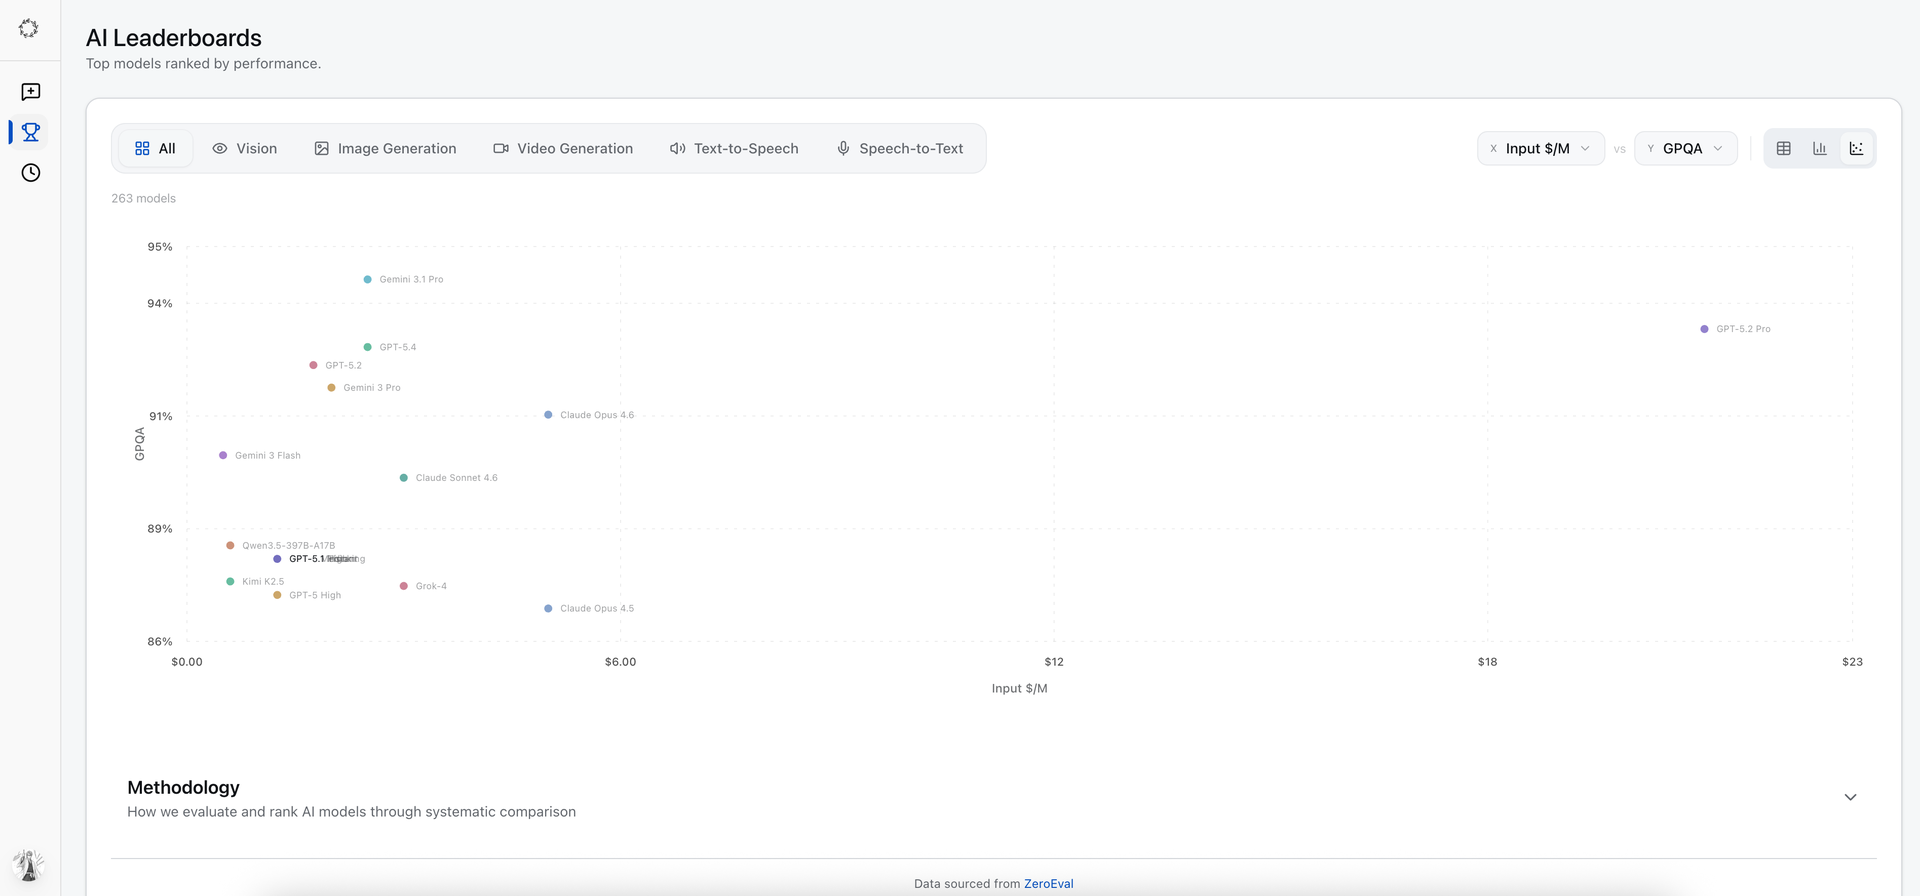
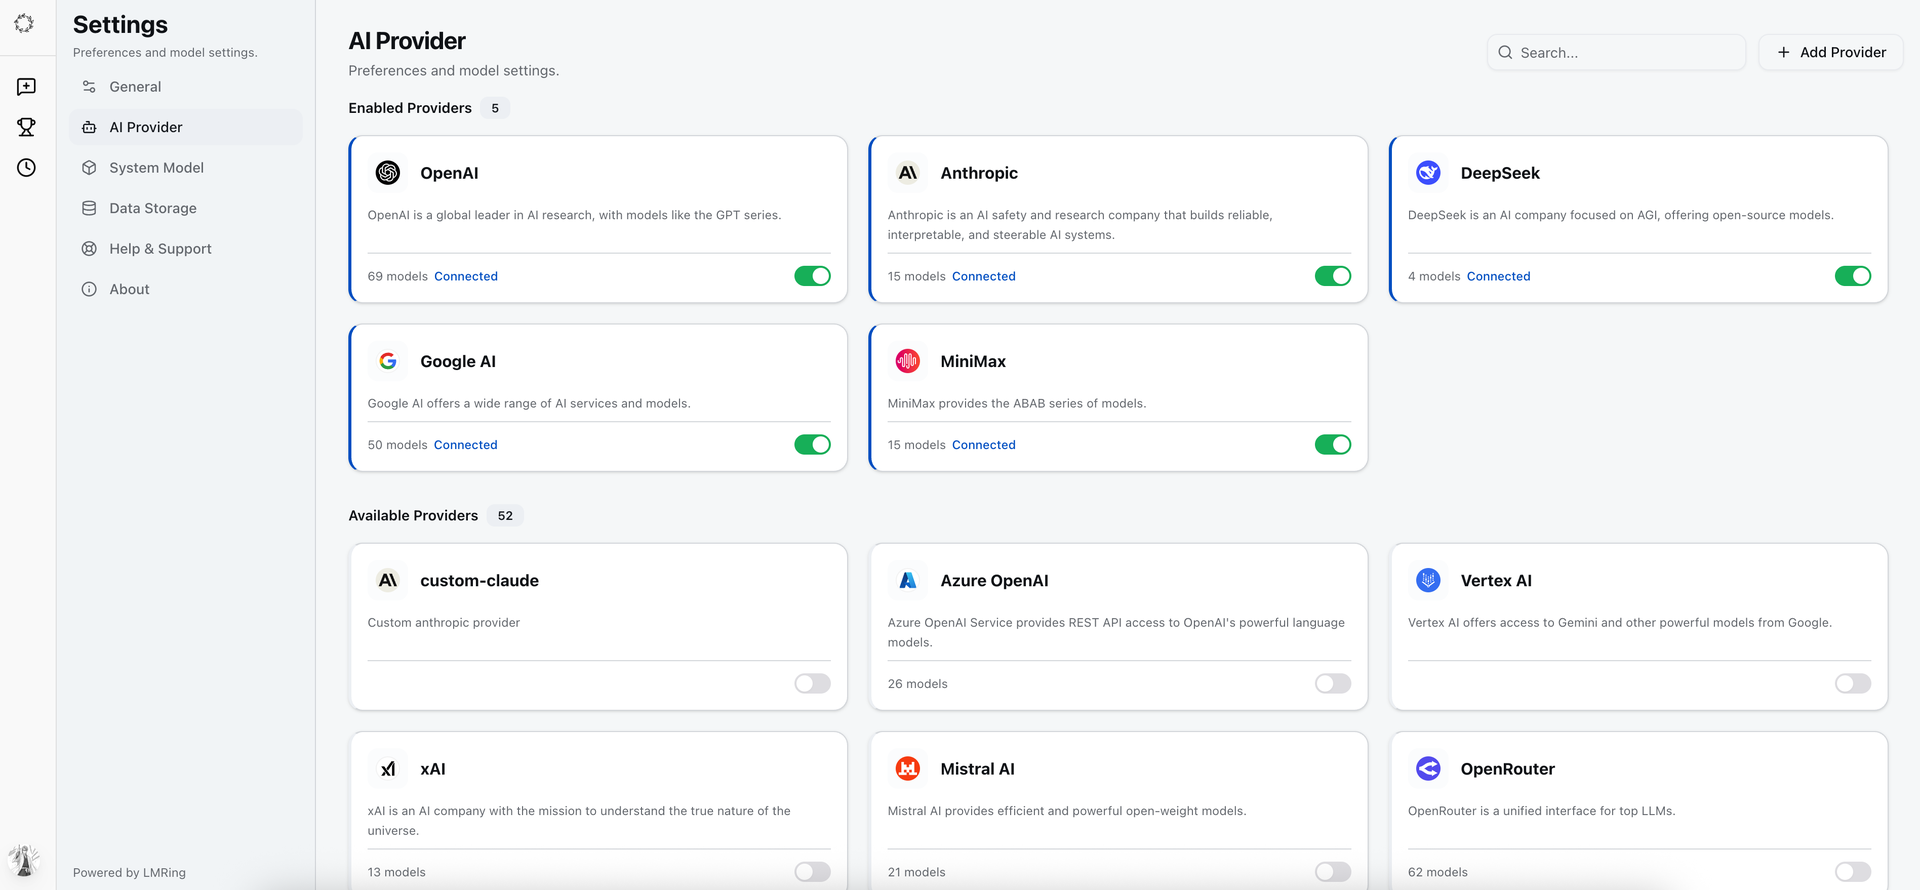
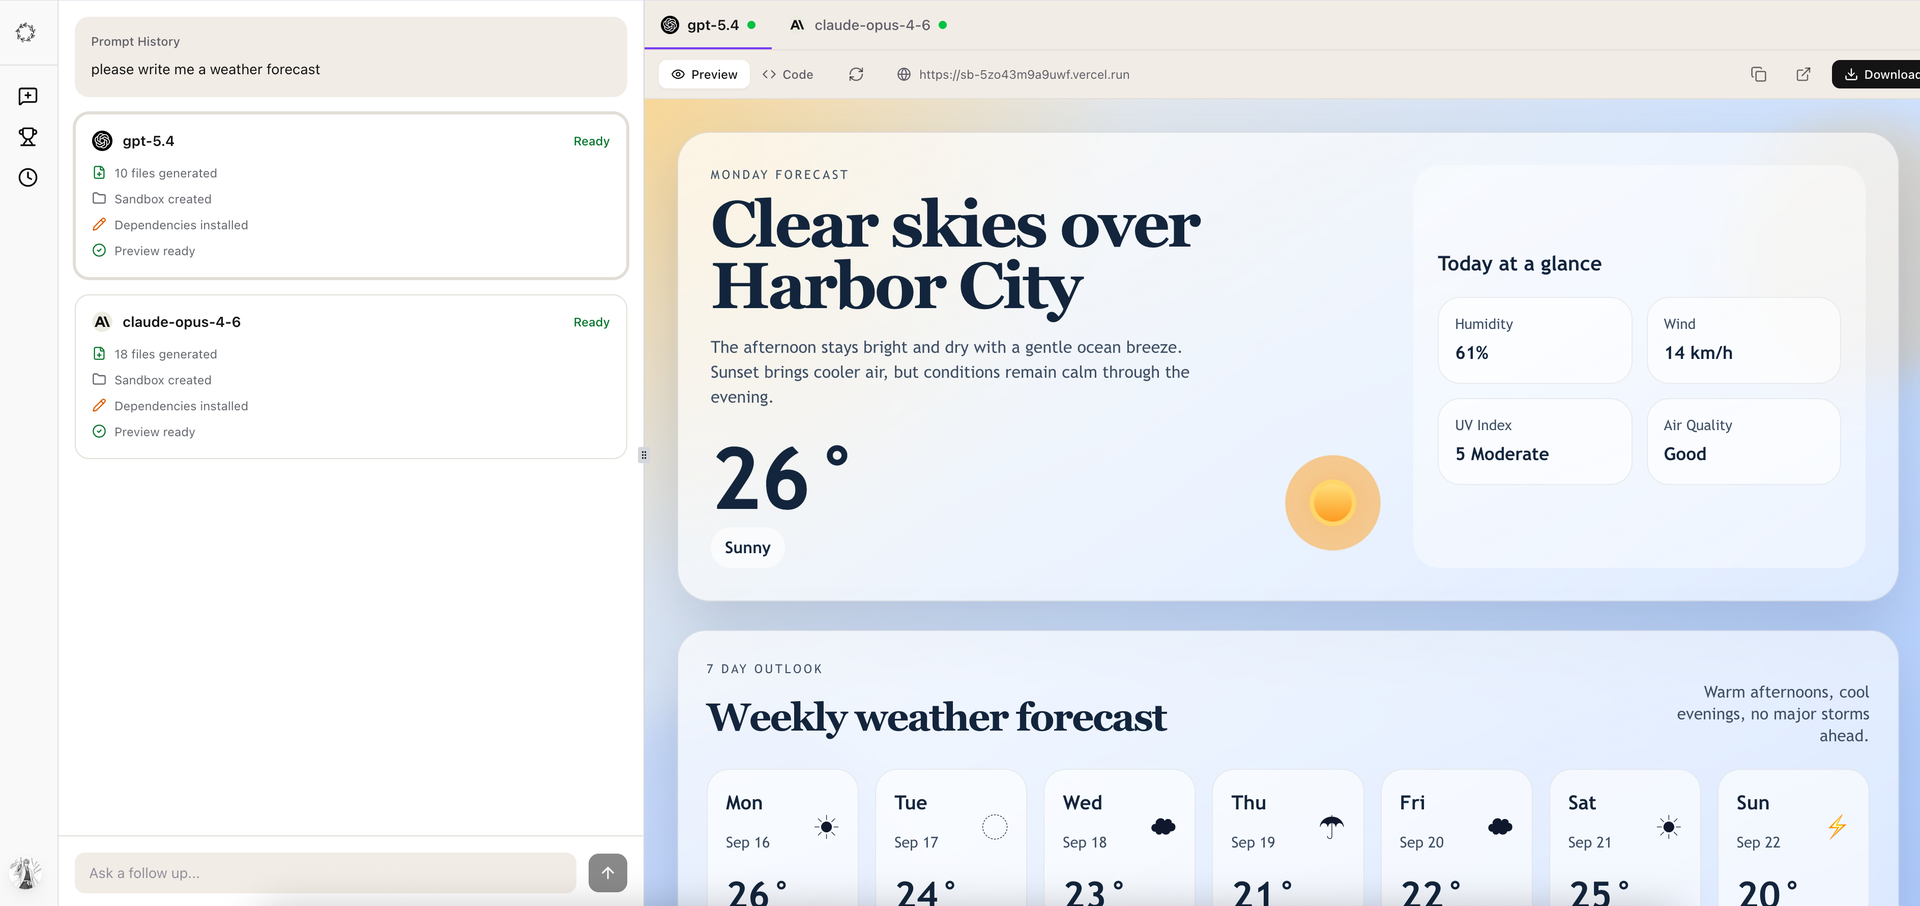
Stop guessing which model writes better and watch them compete on your own prompts: LMRing runs two to five language models side by side on the same input, streams every answer in real time, and lets you vote for the winner. Each comparison feeds a leaderboard you can read as a ranked table, a bar chart, or a scatter plot, so patterns in cost, speed, and quality stop hiding inside individual chats. The arena goes beyond text, with dedicated modes for comparing generated images, generated video across providers such as Sora and Veo, and live-rendered web development output where model code runs in front of you. More than fifty providers connect through their APIs, including OpenAI, Anthropic, Google, DeepSeek, Mistral, Groq, OpenRouter, and any OpenAI-compatible endpoint you point it at. Your comparison history is saved, shareable, and revisitable, which turns one-off impressions into an evaluation record your team can argue from. Sign-in flexes to your setup with GitHub, Google, or Linux.do OAuth, or email one-time codes, and the interface speaks English, French, and Chinese. Because the arena is yours, the prompts, votes, and provider keys stay on infrastructure you control instead of feeding someone else's public ranking. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- Judge Models on Your Prompts
- Two to five models answer the same prompt simultaneously with real-time streaming, so model selection is based on your actual workloads instead of published benchmarks that may not match them.
- Votes Become a Leaderboard
- Every vote feeds ranked tables, bar charts, and scatter plots, giving your team a shared, evidence-based view of which models earn their keep across many comparisons over time.
- More Than Text Answers
- Dedicated comparison modes cover image generation, video generation across providers like Sora and Veo, and web development output rendered live, extending evaluation to the modalities teams actually ship.
- Your Evaluation Data Stays Yours
- Self-hosting keeps prompts, votes, conversation history, and encrypted provider API keys on your own PostgreSQL database, rather than contributing your evaluation workload to a public third-party arena.
Features
- Simultaneous Model Arena
- Arena mode streams answers from two to five models at once through the Vercel AI SDK, with text, image, and video inputs for vision-capable and multimodal models.
- Leaderboard Visualizations
- Rankings render as tables, bar charts, and scatter plots built from crowdsourced votes, making quality, cost, and speed trade-offs visible across more than fifty connected providers.
- Fifty-Plus Provider Connections
- OpenAI, Anthropic, Google, Azure, Amazon Bedrock, DeepSeek, Mistral, Groq, OpenRouter, xAI, Together AI, Fireworks, and Perplexity connect, plus any OpenAI-compatible endpoint with encrypted key storage.
- Flexible Sign-In Options
- Better-Auth powers GitHub, Google, and Linux.do OAuth together with email one-time codes through Resend, and provider API keys are encrypted at rest in PostgreSQL via Drizzle ORM.
- Saved Comparison History
- Conversations are stored, shared, and revisited later, and the interface is localized in English, French, and Chinese for teams evaluating models across regions and languages.