Categories
Self-Hosted Developer Tools AI Agents Privacy Observability AI Gateway LLM Proxy Model RoutingStars
Forks
Watchers
Developer links
magpie
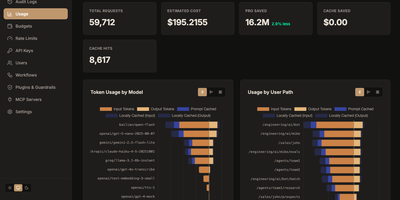
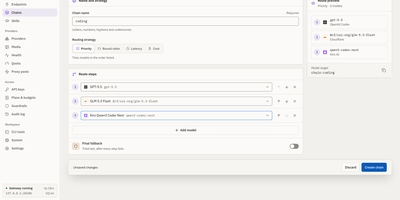
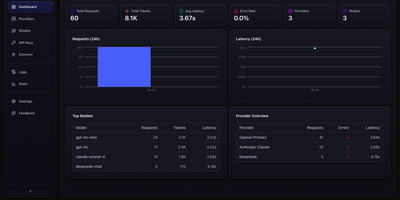
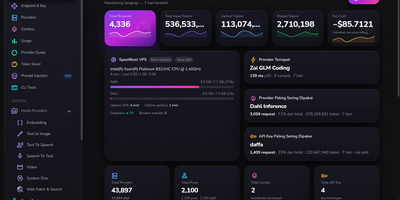
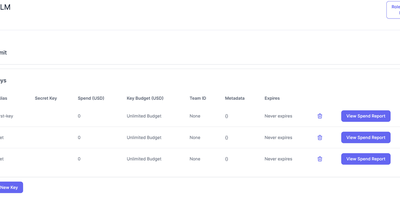
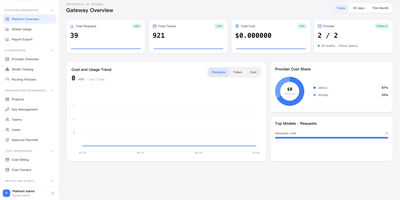
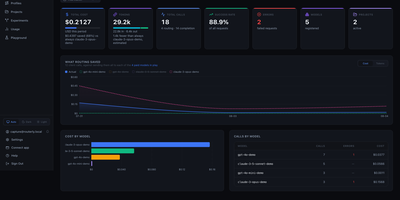
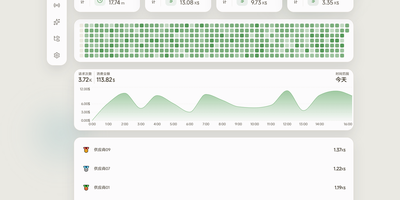
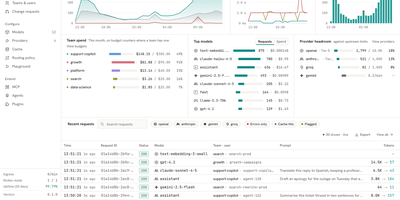
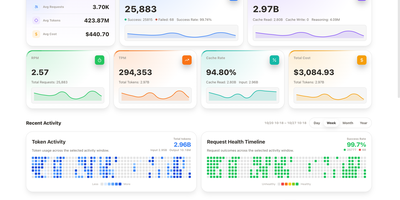
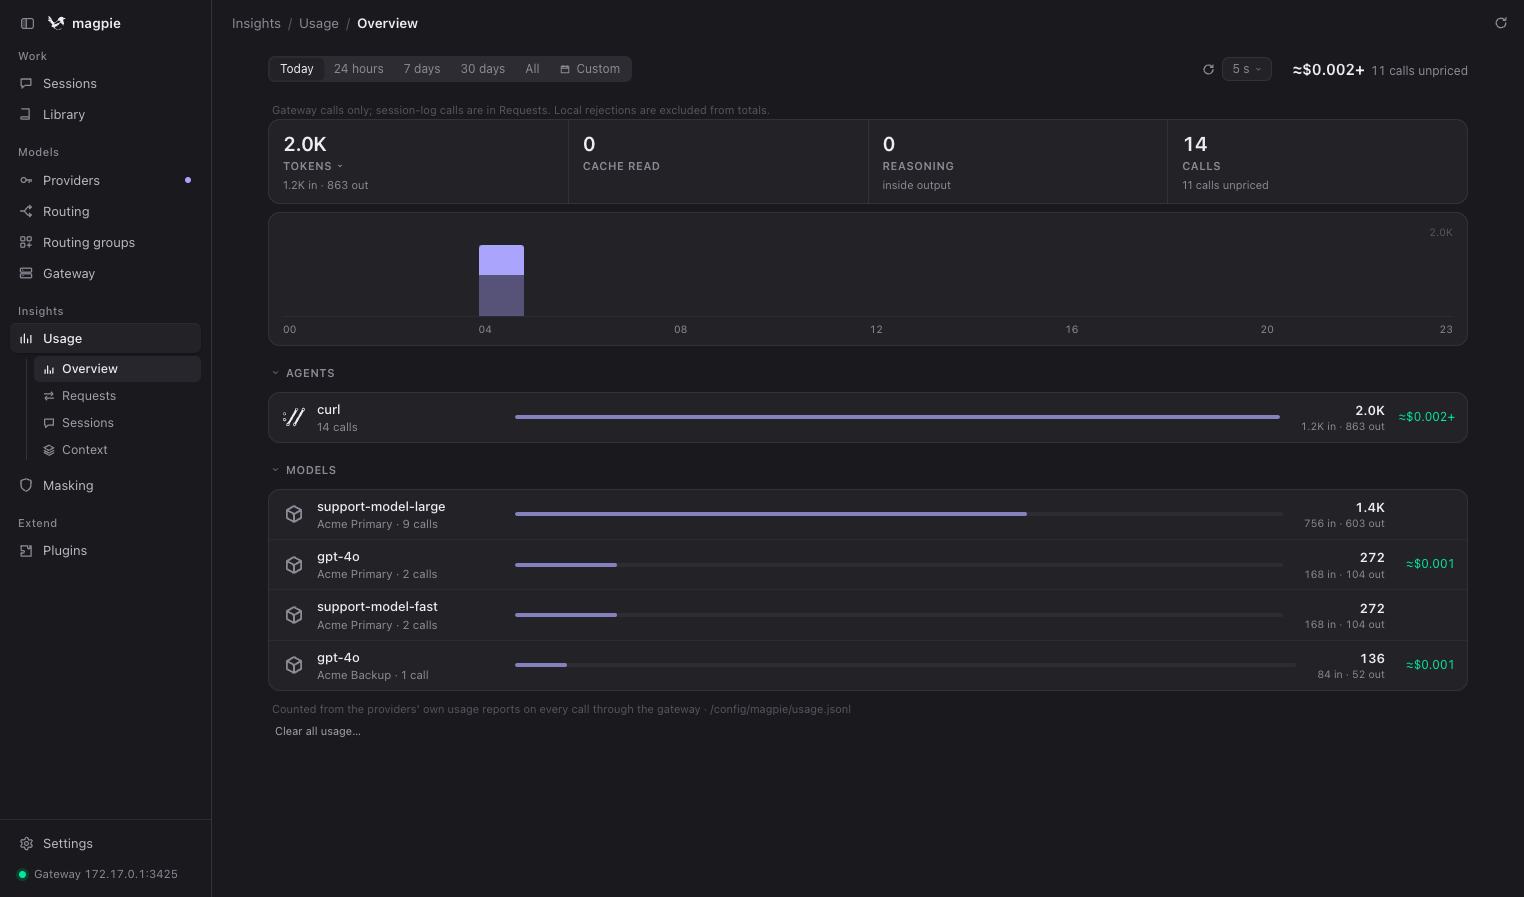
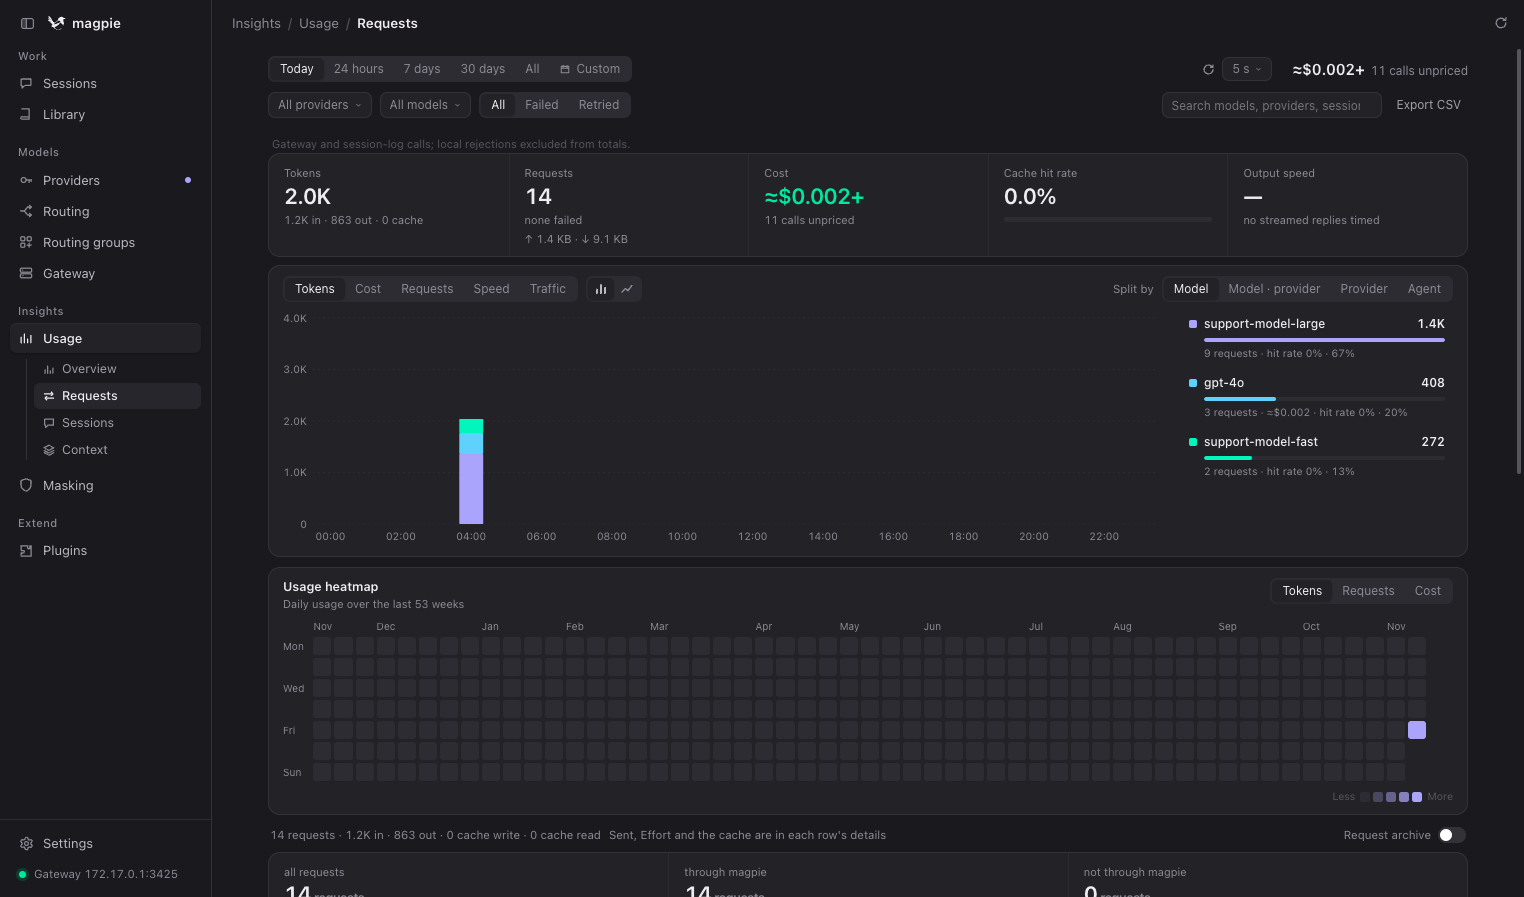
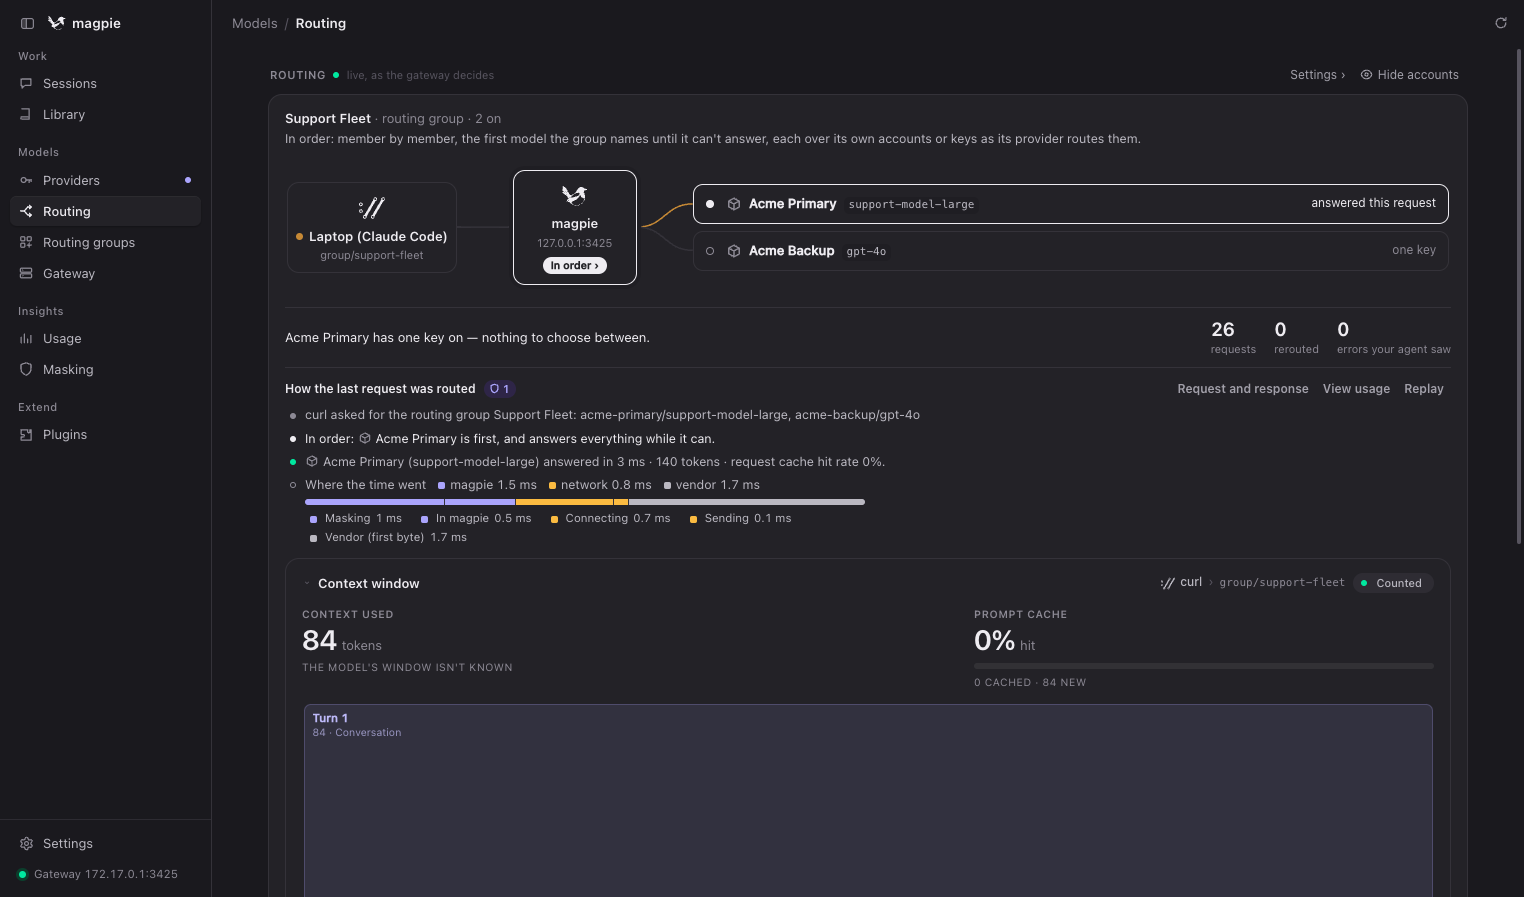
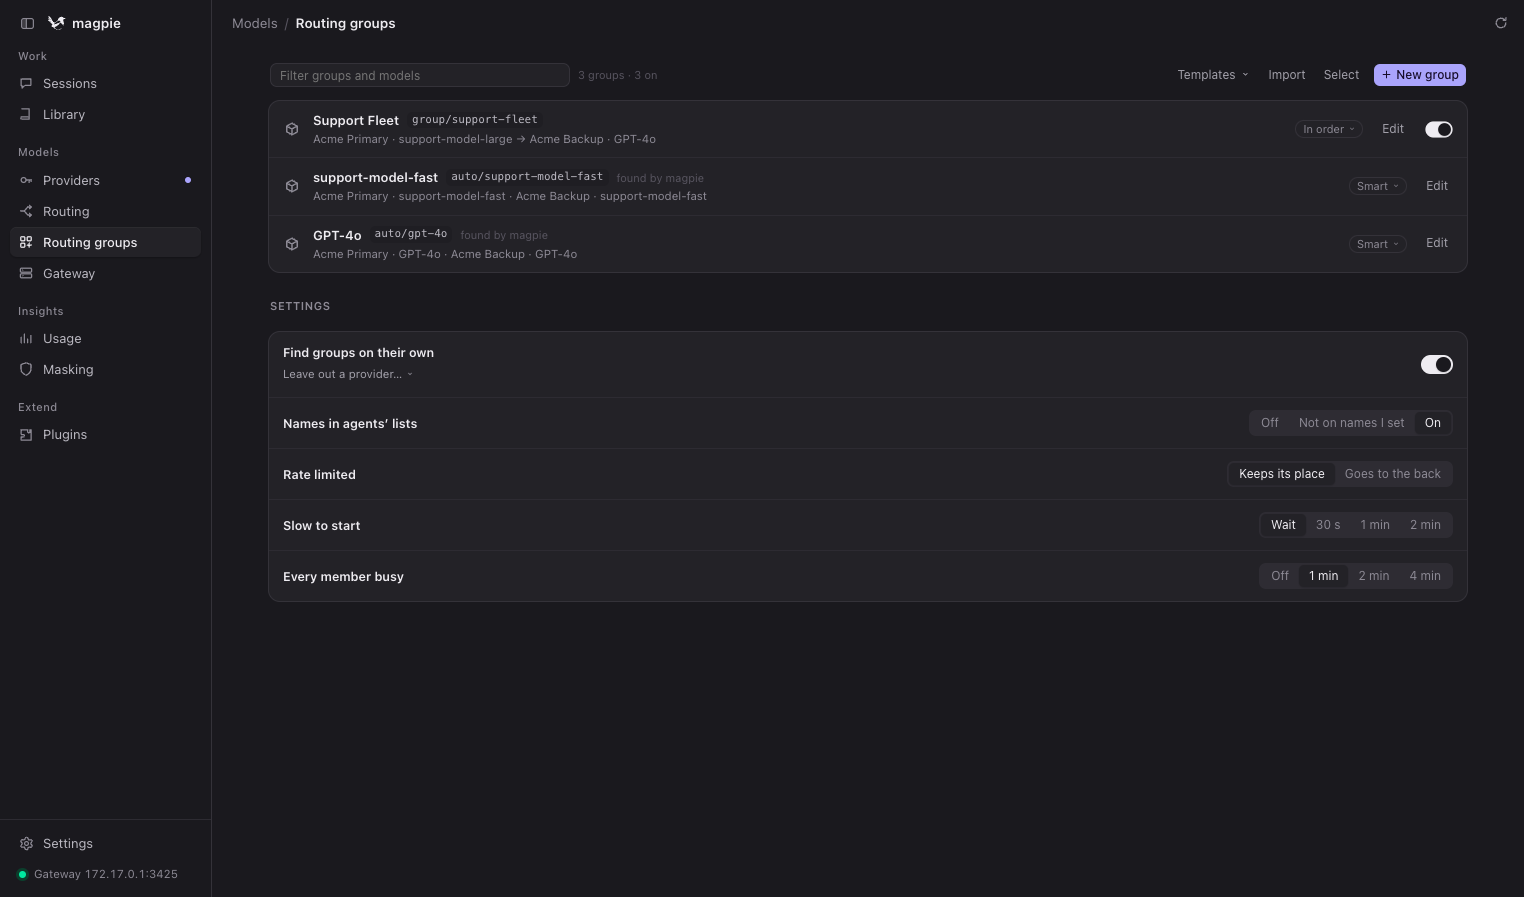
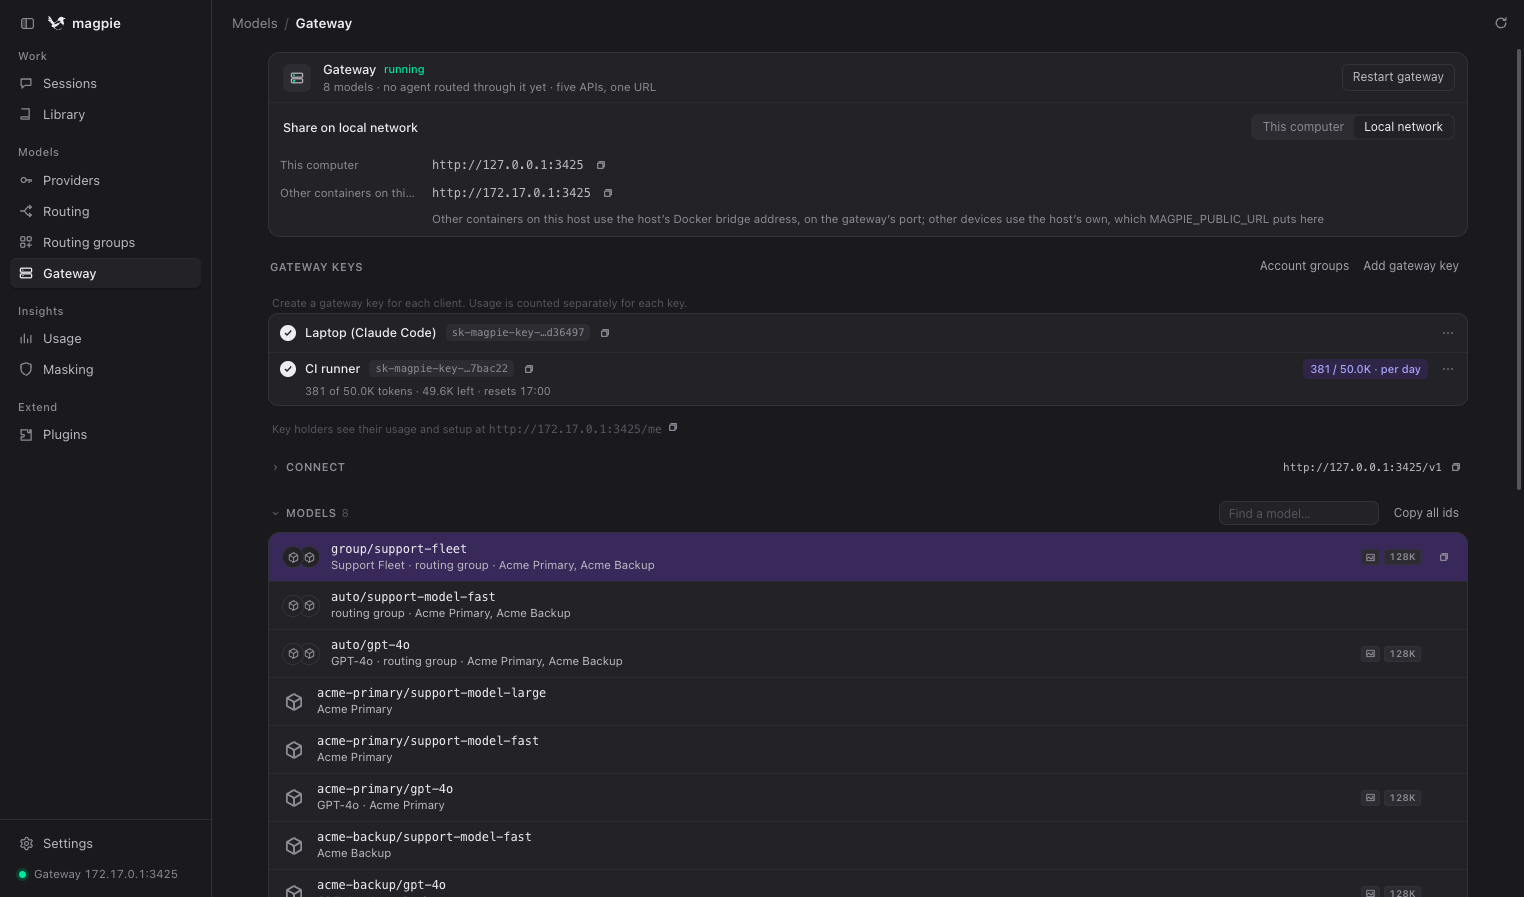
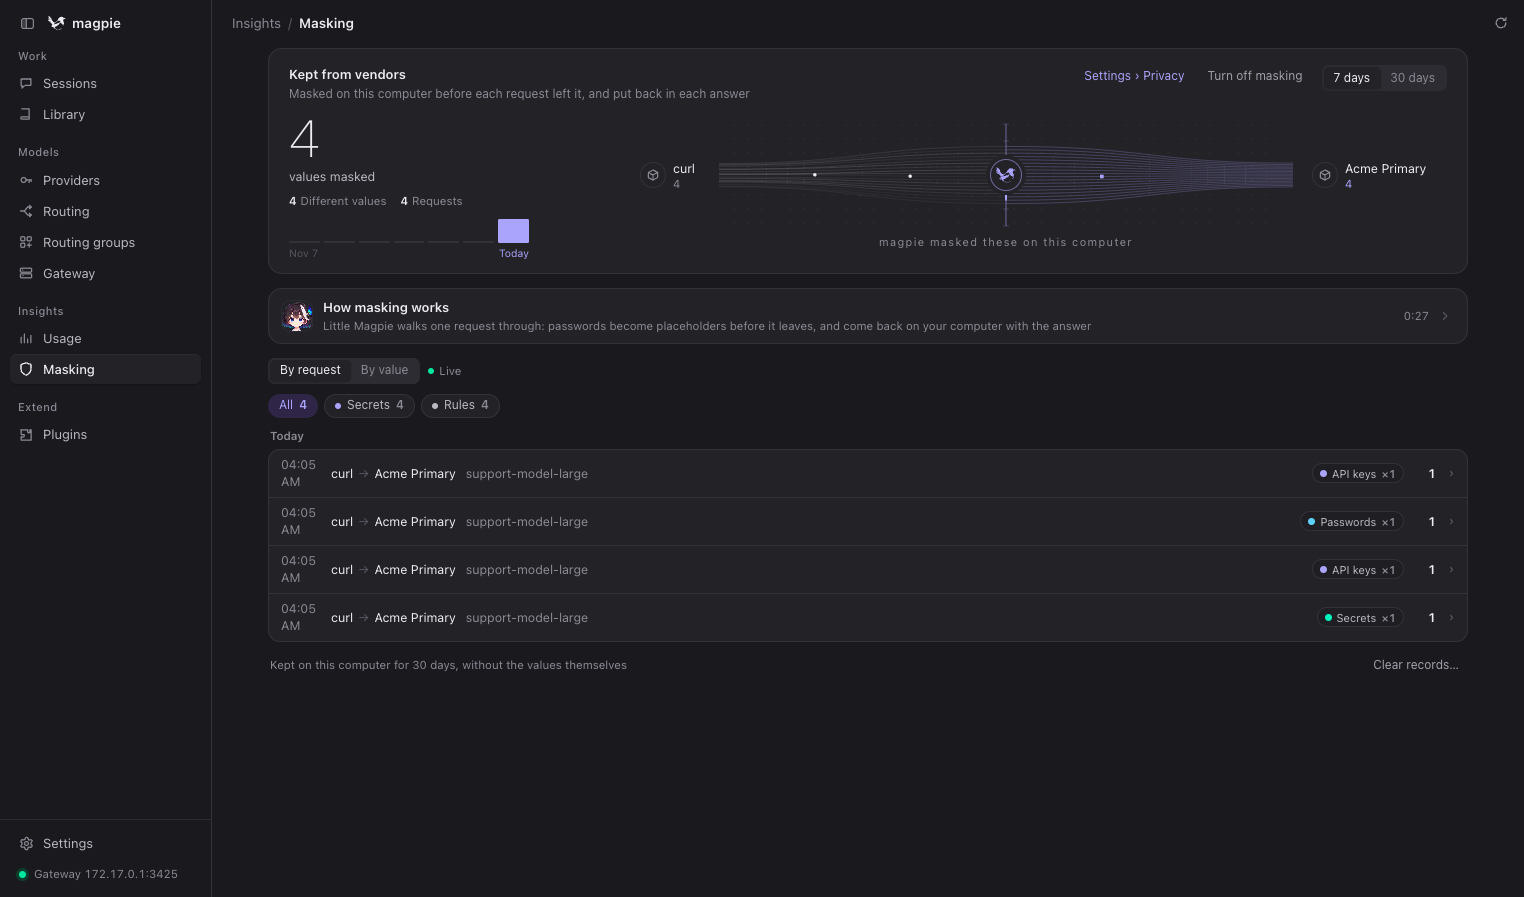
Point every coding agent and chat client at one self-hosted gateway, then choose which model answers from a single browser console. Add providers by preset or custom OpenAI-compatible URL, or sign in with the subscriptions you already pay for. Routing groups bundle several models into one name and move to the next member when a quota runs out, so the calling agent never sees the error. Create a gateway key per client, cap each with daily token or cost budgets, restrict its models, and watch usage counted separately. The Usage pages chart tokens, cost, request counts, cache hit rate, and a yearly heatmap, split by model, provider, or agent, with CSV export. A Routing view replays how each request was routed, with timing for masking, connecting, and the vendor. Masking swaps passwords, API keys, and tokens for placeholders before a prompt leaves your server and restores them in the answer. The browser page is protected by a key you set at launch. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- One Gateway For Every Agent
- Serve one OpenAI-compatible address to coding agents and scripts on other machines, then change which model each one uses from the console without touching their configs.
- Quota Runs Out, Work Continues
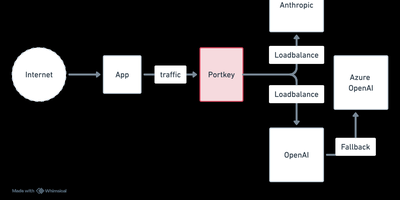
- Routing groups try members in order, rotate between them, or favor the fastest, and move on when a provider is rate limited, so long agent sessions keep running.
- Spend And Access Under Control
- Every client gets its own gateway key with token or cost limits and a model allowlist, and usage is counted per key, so one noisy script cannot drain the budget.
- Secrets Stay On Your Server
- Turn on masking and keys, passwords, and tokens in prompts become placeholders before leaving your server, then return in the reply, with a log of what was masked.
Features
- Provider And Account Manager
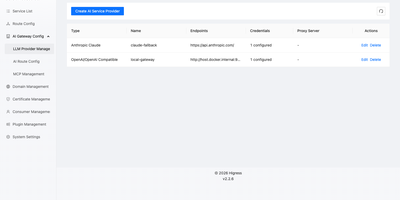
- Add preset vendors, custom OpenAI, Anthropic, or Gemini compatible endpoints, and multiple keys per provider, then pick which models each provider exposes.
- Routing Groups
- Combine models into one named group with in-order, smart, rotate, usage, or fastest routing, plus rate limit and busy handling settings.
- Per-Client Gateway Keys
- Issue named keys for laptops and CI runners, set daily token budgets, and share the gateway on the local network with each key's usage shown.
- Usage And Request Analytics
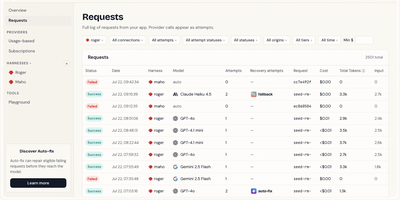
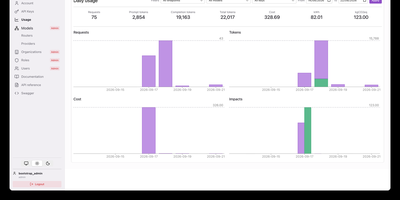
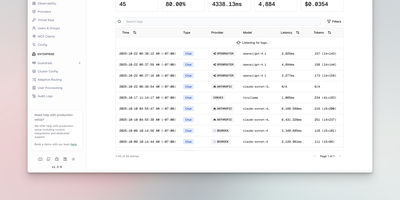
- Chart tokens, cost, requests, and cache hit rate by model, provider, or agent, search request history, and export every call as CSV.
- Request Routing Inspector
- Open any request to see which provider answered, if it was rerouted, the context window used, and where the milliseconds went.
- Prompt Masking Log
- Review which requests had secrets masked, grouped by type, like API keys and passwords, with counts per client and provider.