Stars
Forks
Watchers
Developer links
Respan Gateway
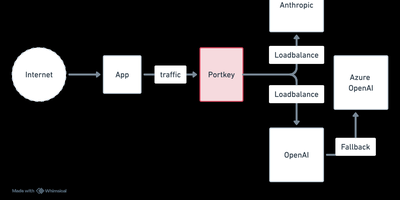
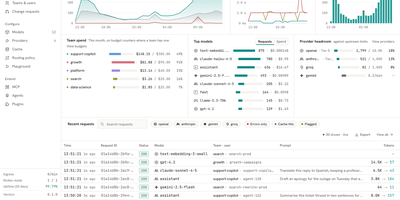
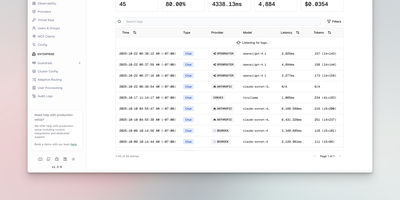
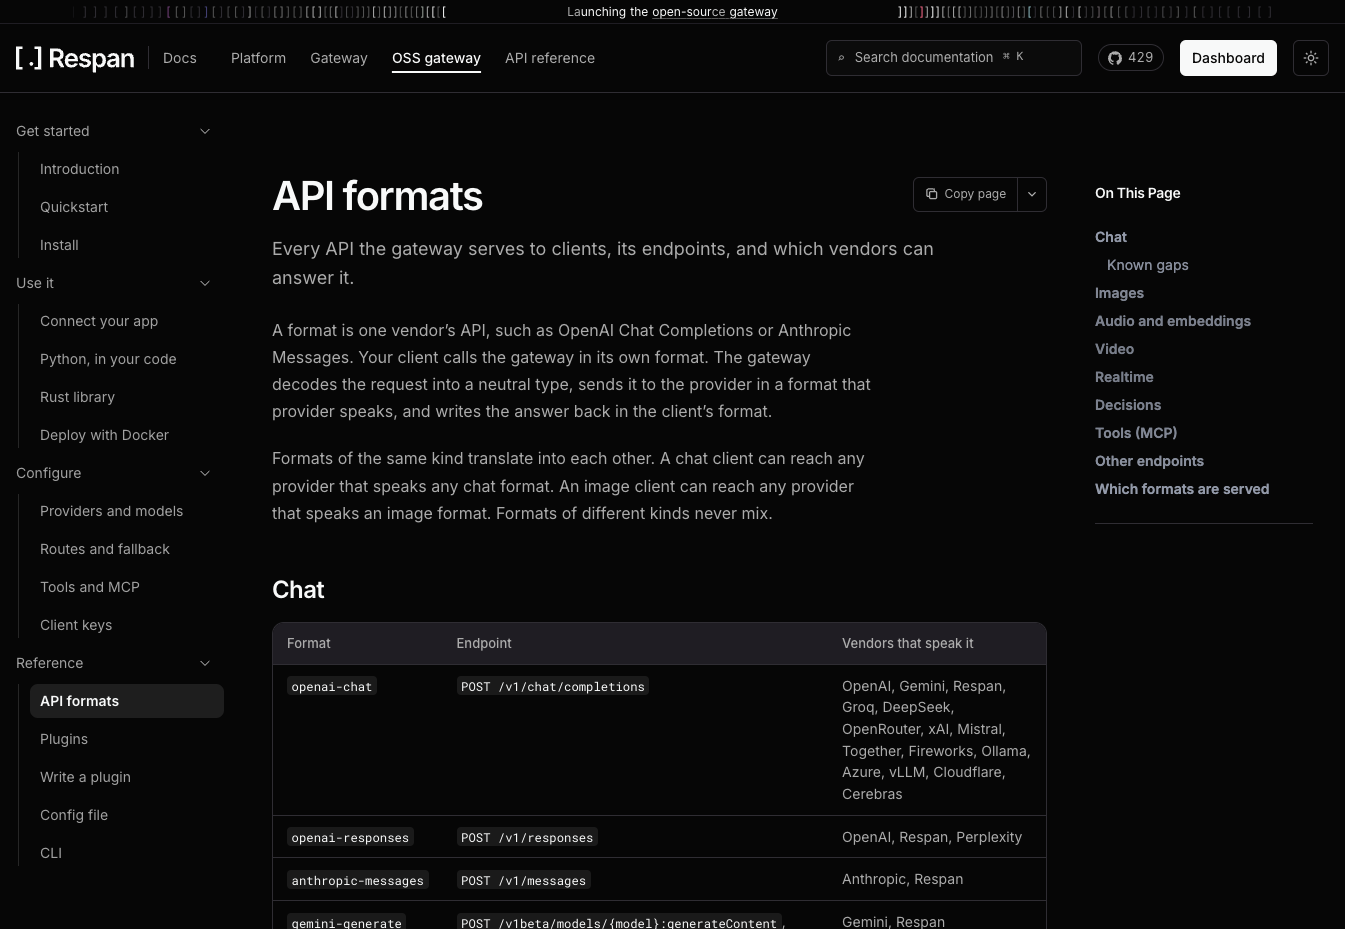
Respan Gateway is a single-binary LLM gateway that lets the SDK you already use call any AI model from any provider, translating between OpenAI, Anthropic, and Gemini API formats on the way through. Point an OpenAI, Anthropic, or Gemini client at it and you reach chat models on sixteen providers, plus any OpenAI-compatible endpoint of your own, with streaming, tools, images, and reasoning translated. Traffic control works the way operators think: name a route, send it to the cheapest or fastest provider, retry on failure, fall back to a second vendor, or hedge a slow call by racing another provider. Models that never had tools get them anyway, because MCP servers and built-in search, browsing, code, document, and memory tools run inside ordinary chat requests behind the gateway. Realtime voice crosses vendors too, with an OpenAI Realtime client able to talk to Gemini Live, alongside images, speech, transcription, embeddings, and video through one endpoint. A live request log in the web UI shows the client key, model, provider, status, tokens, cost, and latency of every call, so runaway agents and surprise bills are visible immediately. Everything is a plugin on one public Rust API, from routing and pricing to tracing, with examples for guardrails, PII masking, and billing. One TOML file configures keys, providers, routes, and tools, validates before it starts, and reloads on signal. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- Any SDK, Any Model
- OpenAI Chat, OpenAI Responses, Anthropic Messages, and Gemini clients all call models across sixteen providers, with streaming, tools, images, and reasoning translated between API formats automatically.
- Fallbacks That Race Providers
- Named routes can pick the cheapest or fastest provider, retry failures, fall back to a backup vendor, and hedge slow calls by racing a second provider in parallel.
- Tools For Every Model
- MCP servers and built-in web search, browsing, code sandbox, document, and memory tools run inside chat requests, so models without native tool support can still use them.
- Every Call Logged Live
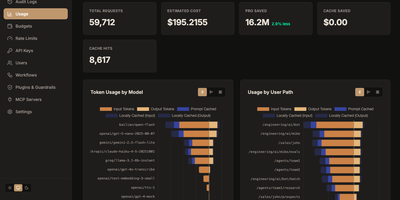
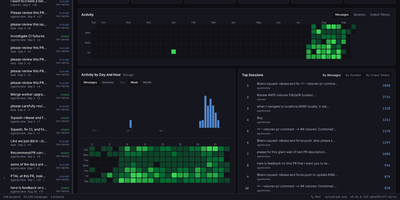
- The web UI request log records client key, model, provider, status, tokens, cost, and latency for each call, making agent traffic and spending visible as it happens.
Features
- Format Translation Engine
- Requests decode into a neutral type and re-encode in the provider's format, so OpenAI, Anthropic, and Gemini chat, image, audio, embedding, and video APIs interoperate.
- Routing And Hedging
- Routes match model names and globs, then pick, fall back, retry with backoff, or hedge after a delay, with per-route conditions on what a provider must support.
- MCP Tool Loop
- Configured MCP servers and tool vendors are served at /mcp and can run inside chat requests, letting any model search, browse, execute code, and use memory.
- Live Request Log
- An always-on log keeps the last thousand finished requests in memory for the web UI and admin API, each with tokens, cost, latency, and provider details.
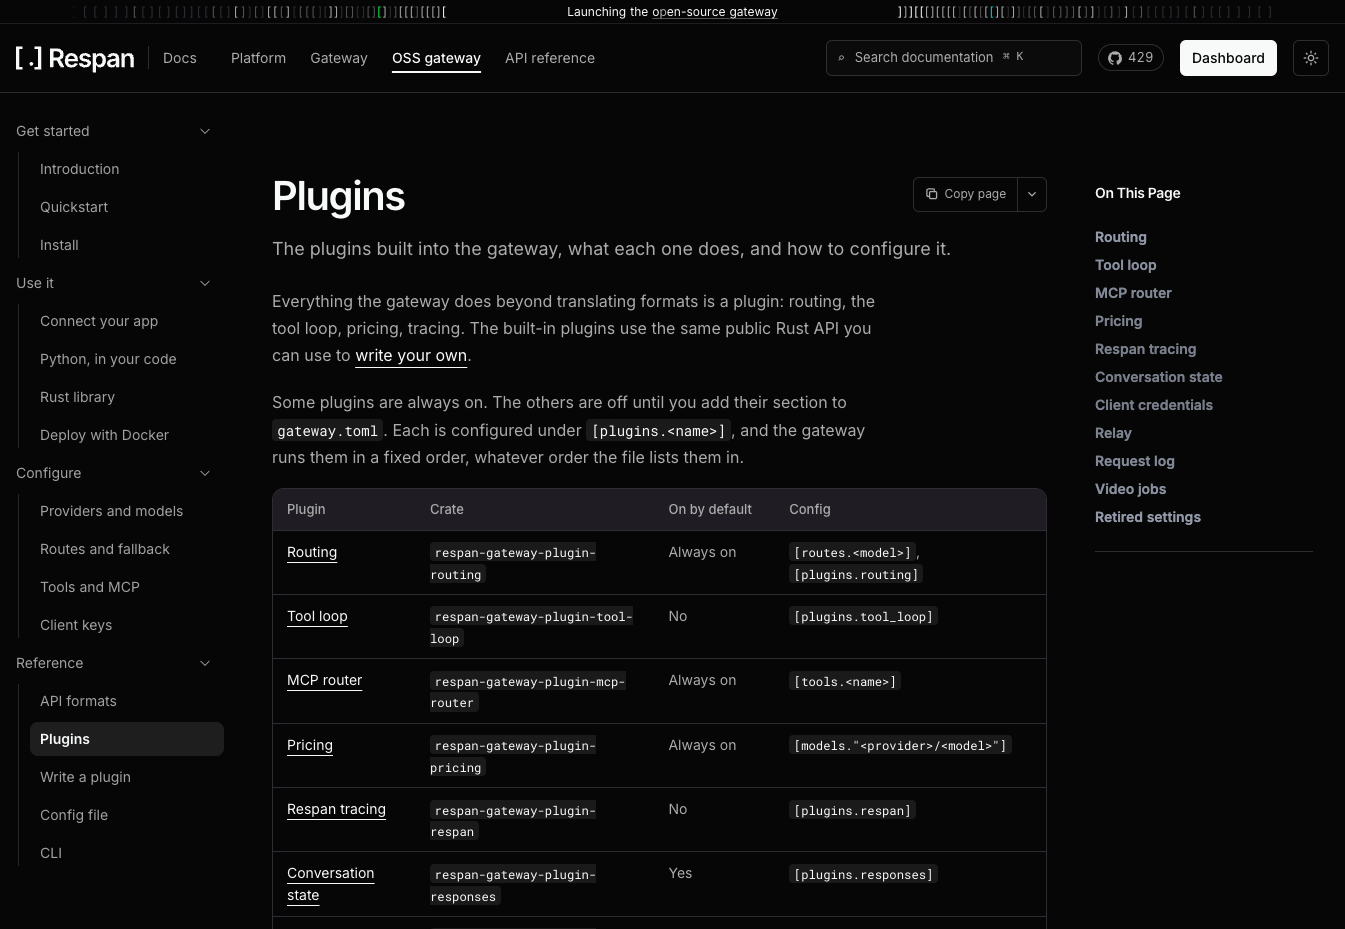
- Plugin Extension API
- A four-hook Rust Plugin trait powers routing, pricing, tracing, and your own guardrails, PII masking, or billing plugins, compiled into a gateway binary you build.