Stars
Forks
Watchers
Developer links
SmarterRouter
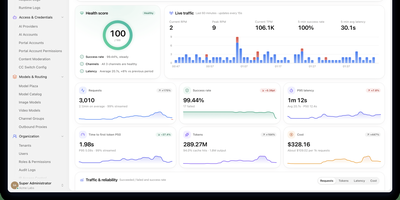
SmarterRouter stops you from playing model roulette with your local AI setup, choosing the right model for every prompt so you never have to. Point your applications at one familiar endpoint and send the request; the router studies the prompt, weighs category and complexity against benchmark results gathered on your actual hardware, and hands the job to the model most likely to answer well. It discovers the models your backend already serves, profiles each one with standard tests the first time it meets them, and keeps learning from the feedback your usage generates. When the first choice fails, a backup model takes over without your application noticing. Repeated questions come straight back from cache instead of burning another generation. Your graphics memory is watched continuously across one card or several, and models are unloaded before an ambitious request runs the machine dry. Cloud providers can join the same routing pool when a question deserves them, while everything local stays local and free. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- No More Model Roulette
- Every prompt is analysed and routed to the model profiled best for that kind of task on your hardware, ending manual model picking per request.
- Benchmarks On Your Machine
- Models are profiled with standard prompts on the hardware that will run them, so routing decisions reflect your real speeds rather than published claims.
- Failures Handle Themselves
- When a chosen model errors or stalls, requests retry against backup models automatically, keeping applications working through individual model trouble.
- Memory Watched Continuously
- Graphics memory across all detected cards is monitored and models unload before limits are hit, preventing the crashes that kill long local sessions.
Features
- Automatic Model Discovery
- Available models are found from your backend automatically and can be added or removed live, without restarting the router to pick up changes.
- Performance Profiling
- Each model is tested with standardised prompts, and the aggregated results drive which model receives coding, reasoning, or chat requests.
- Response Caching
- Identical prompts return cached answers instantly, with cache statistics available per model so you can see what the cache is saving.
- VRAM-Aware Loading
- Memory on NVIDIA, AMD, Intel, and Apple Silicon hardware is tracked, and models load and unload against a budget you control.
- Local And Cloud Together
- Local backends and external providers share one routing pool, addressable by prefix when a request should go somewhere specific.