Categories
Knowledge Base Self-Hosted AI RAG Local LLM Semantic Search Ollama Document Chat Private AIStars
Forks
Watchers
Developer links
LocalGPT
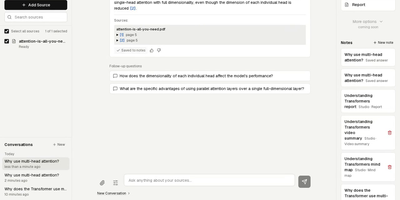
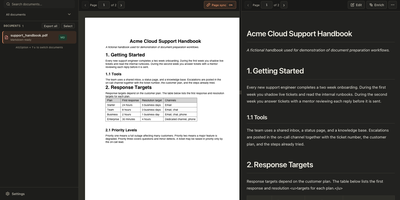
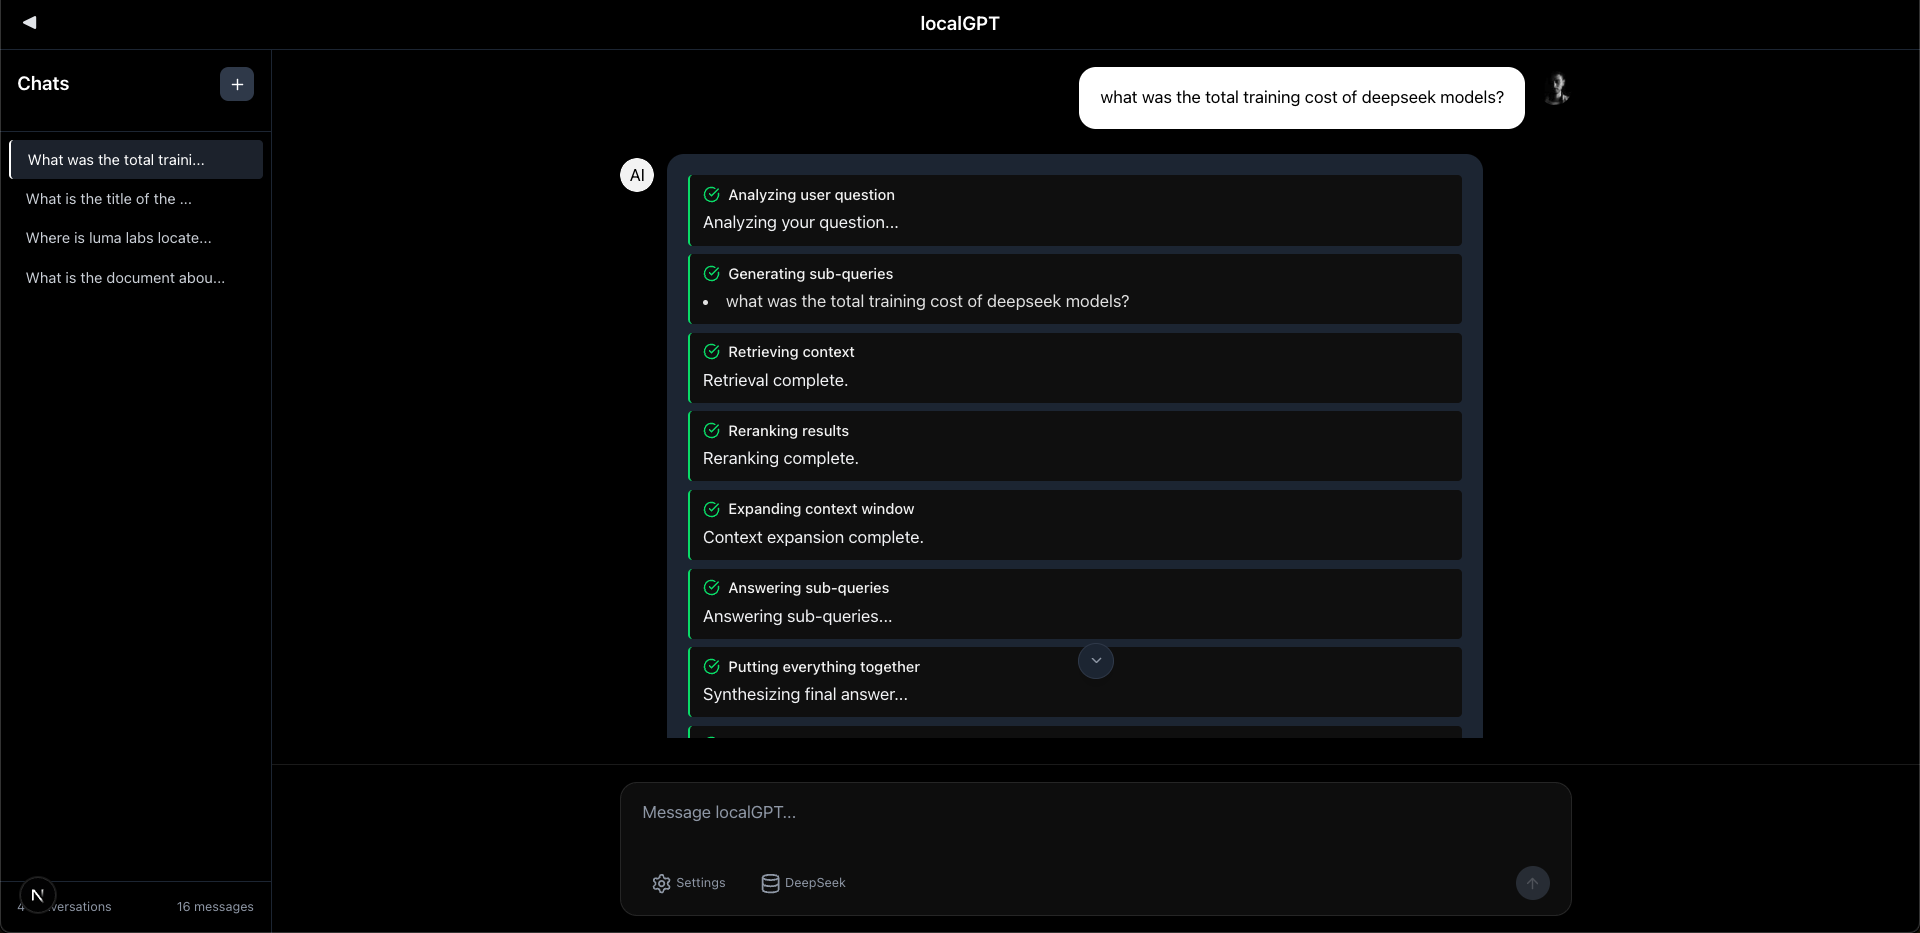
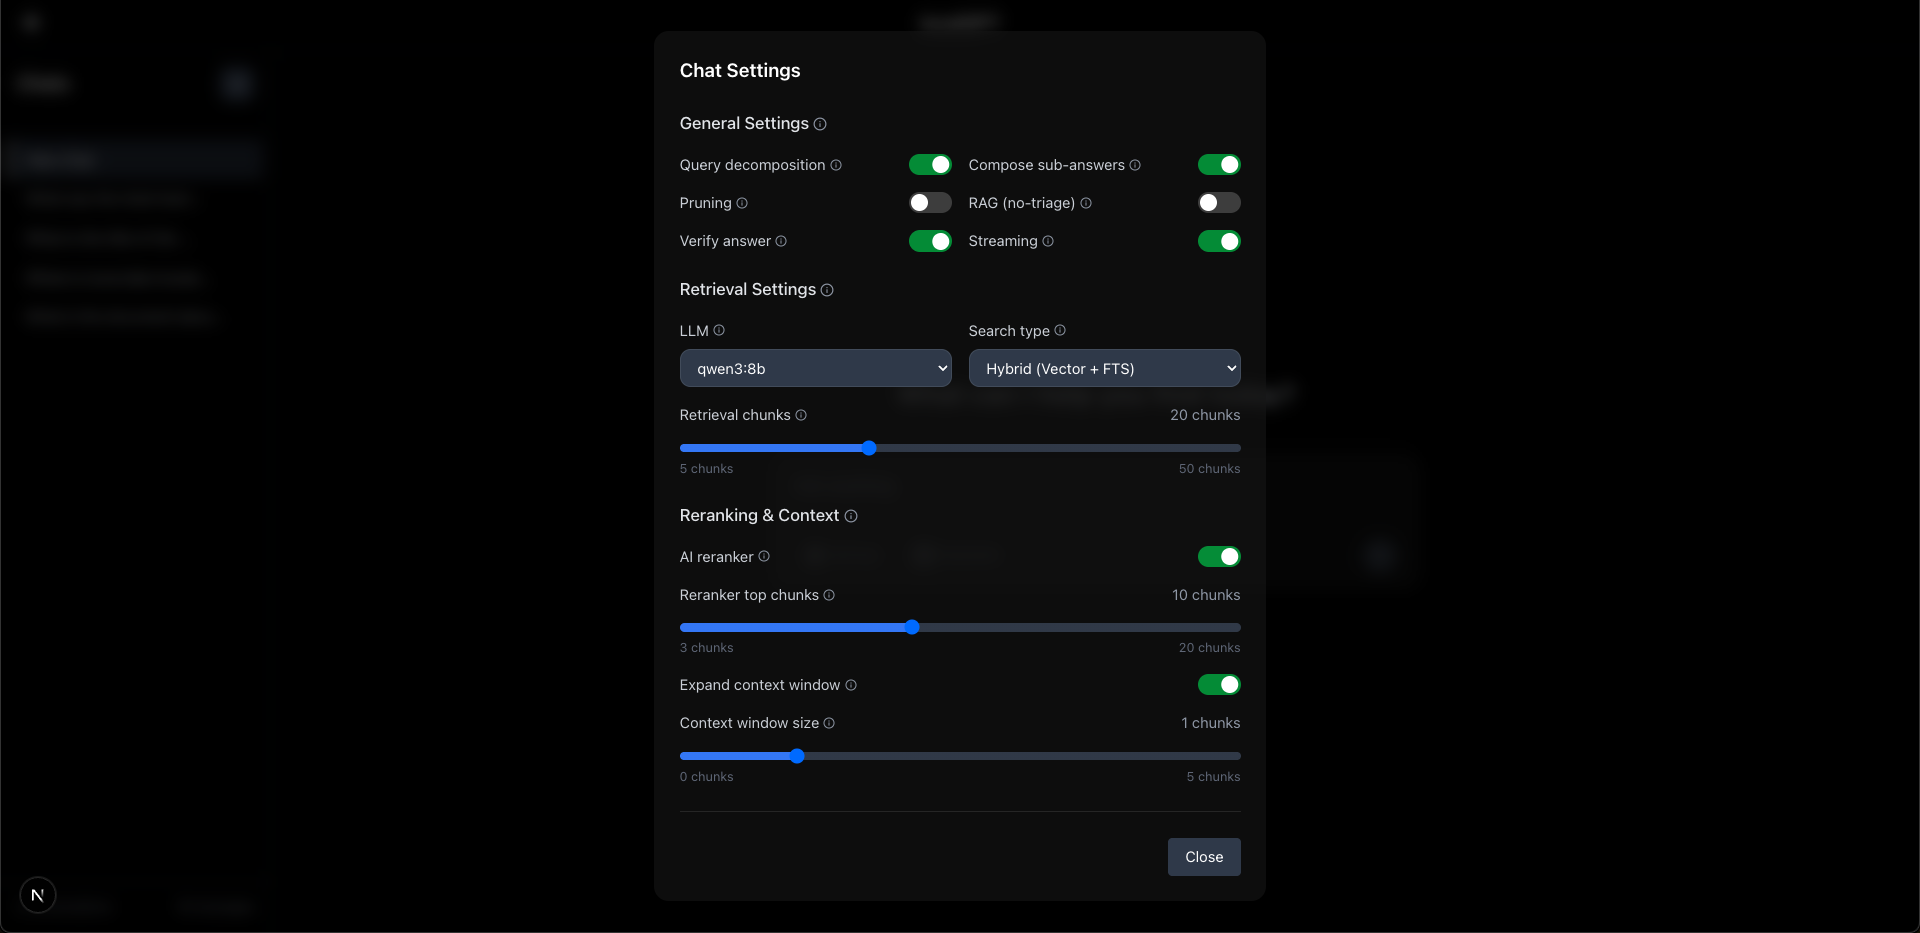
If a document is too sensitive for a hosted chatbot, LocalGPT lets you question it in plain English on your own server, with every answer citing the passages it used. Drop PDF, DOCX, HTML, Markdown, or plain-text files into a named index and scanned PDFs are read through OCR. Vector and full-text results are fused by rank, then a cross-encoder reranker keeps the best passages. A router decides per question between searching your documents and answering directly. Complex questions split into sub-questions that are searched separately, pooled, and answered in one pass. Progress cards stream the retrieval, reranking, and synthesis stages into the chat as they run. An optional verification pass appends a confidence percentage to the answer. A session-scoped semantic cache answers repeated questions faster. Per-chat settings toggle decomposition, pruning, verification, search type, model, and retrieval depth. Swap the answer model per session or per message, and choose the embedding model when you build an index. From a terminal, one command indexes a folder and another asks a question, and a REST API exposes every action the interface can take. A start script runs everything in Docker against Ollama on the host or in a container. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Documents Never Leave Your Server
- Indexing, retrieval, and answering all run on infrastructure you control, with local models served by Ollama, so contracts, research, and internal files are never uploaded to a hosted chatbot.
- Better Answers Than Plain Search
- Hybrid vector and full-text retrieval, rank fusion, and a cross-encoder reranker surface the right passages, so answers stay grounded in your files and point back to their sources.
- Watch Every Retrieval Step Live
- Streaming progress cards show question analysis, sub-queries, retrieval, reranking, and synthesis as they happen, so you can see where an answer came from and why it took time.
- Tune Quality Without Touching Code
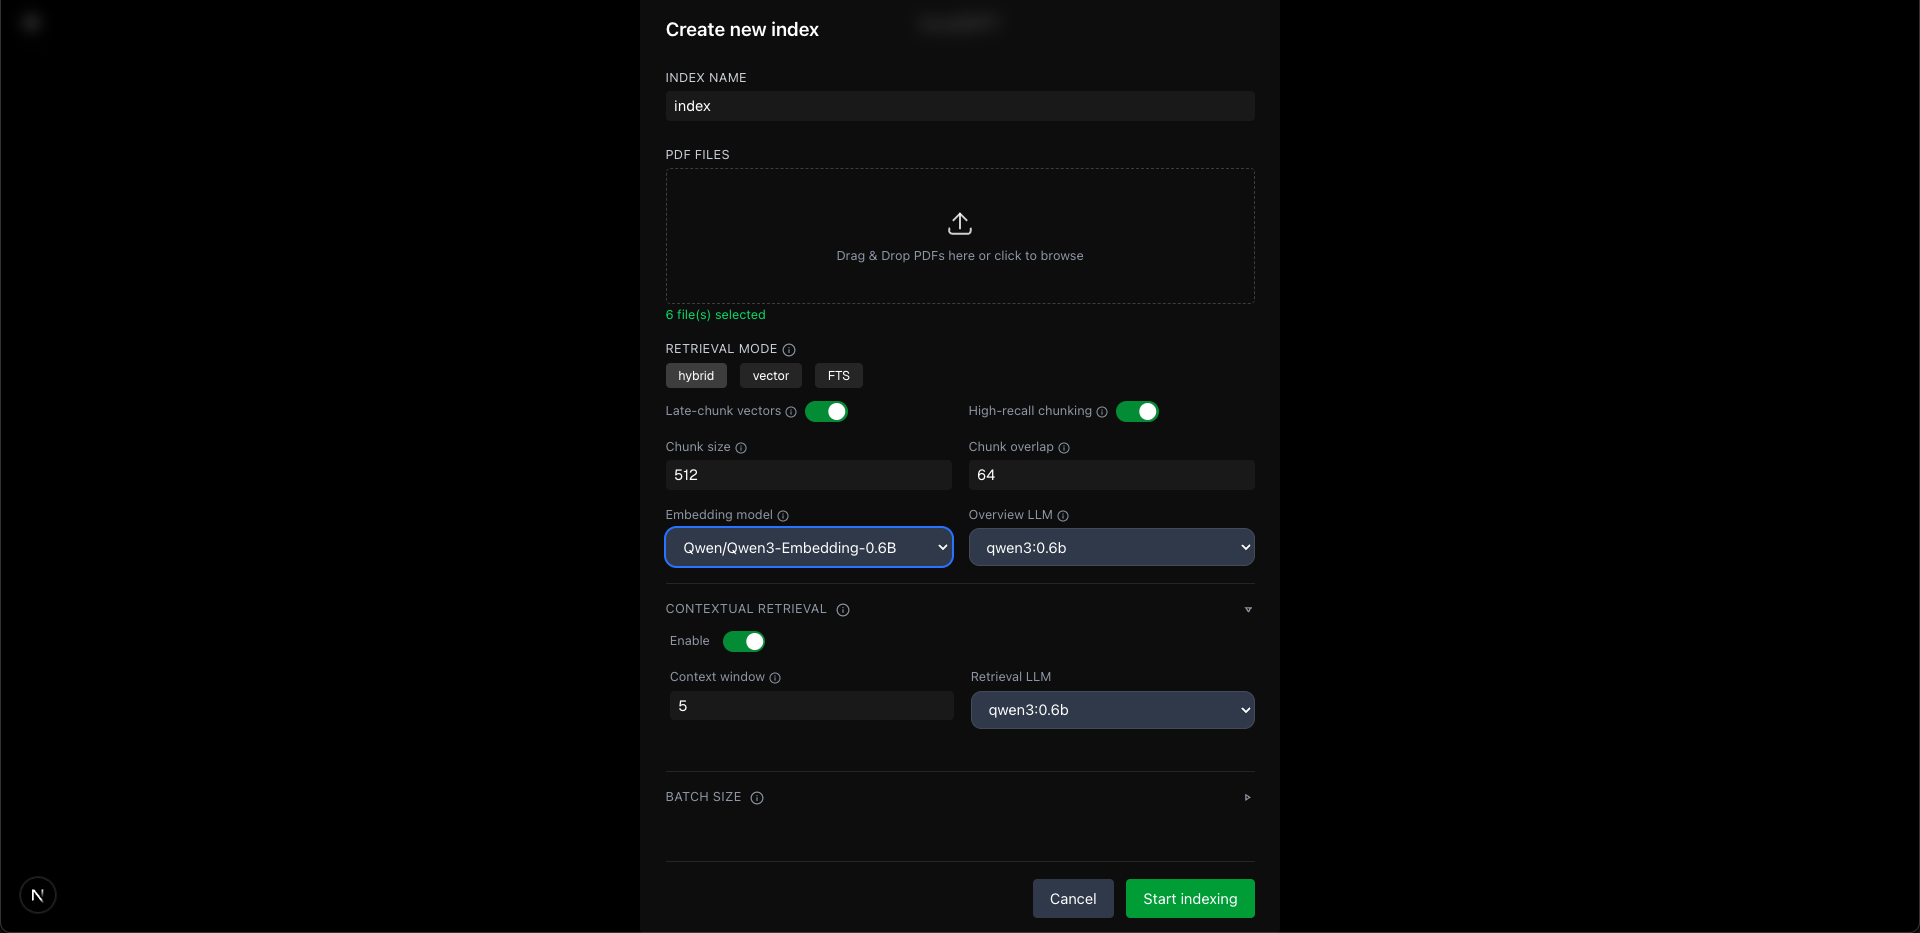
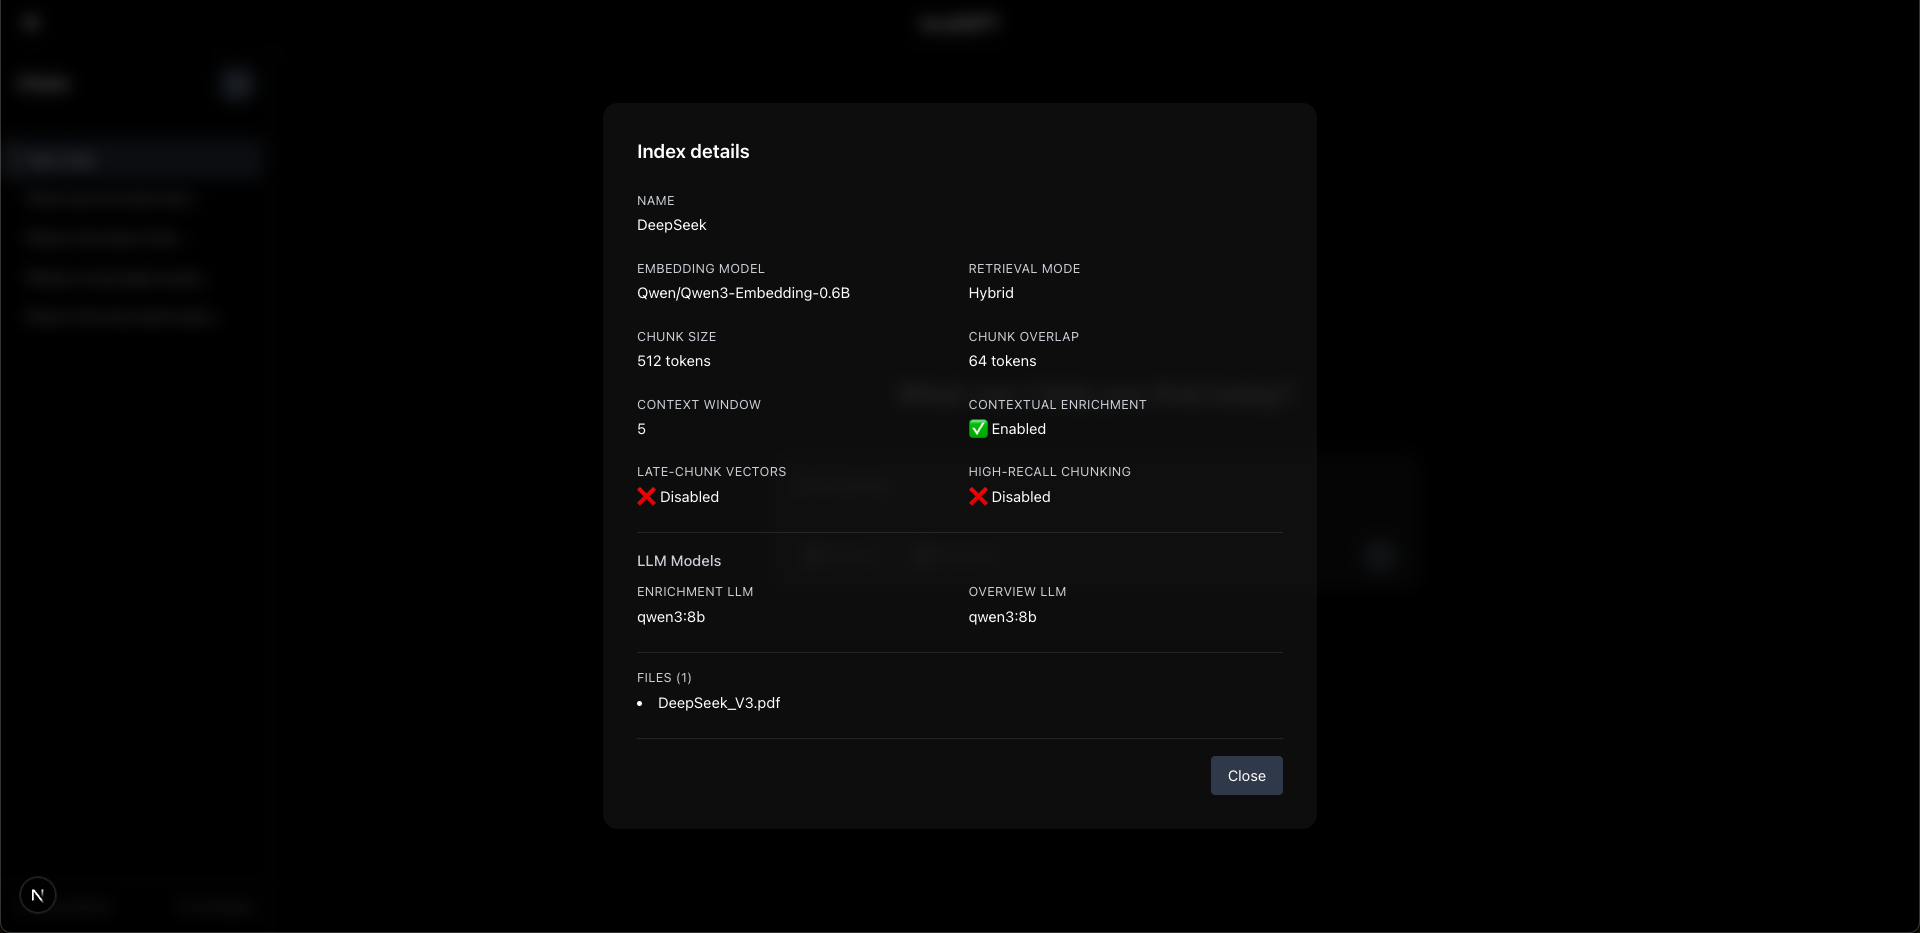
- Per-chat toggles and sliders adjust decomposition, pruning, verification, reranking, and retrieval depth, while the index form picks chunk size, embedding model, and enrichment before you build.
Features
- Hybrid Search With Reranking
- Fuses dense vector and full-text results with reciprocal rank fusion, then a cross-encoder reranker keeps only the passages that best match each question.
- Smart Query Routing
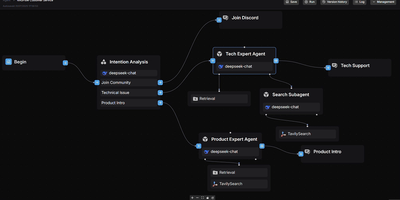
- Chooses per question between retrieval over your documents and a direct model answer, and splits complex questions into sub-questions before pooling and reranking the evidence.
- Multi-Format Document Ingestion
- Reads PDF, DOCX, HTML, Markdown, and text files, runs OCR on scanned PDFs, and adds chunk-level context with a small language model during indexing.
- Cited Answers and Verification
- Responses include the source chunks they were grounded in, with an optional verification pass that appends a confidence percentage to the answer.
- Index and Session Management
- Create named indexes from uploaded files, inspect their settings, and keep separate chat sessions per topic, each with its own model and retrieval options.
- REST API and Streaming
- A backend gateway and a RAG API expose every interface action over HTTP, with Server-Sent Events streaming each pipeline stage as it runs.