Categories
Self-Hosted Observability LLM Gateway Load Balancer Cost Tracking Claude Code AI Developer Tools API ProxyStars
Forks
Watchers
Developer links
LLMIO
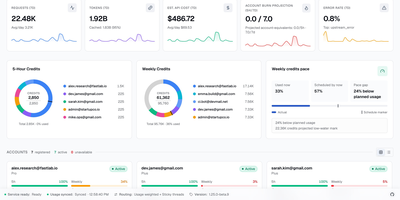
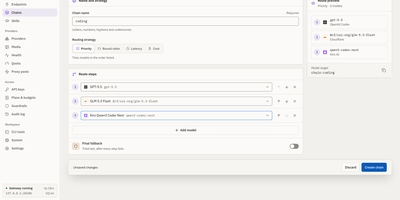
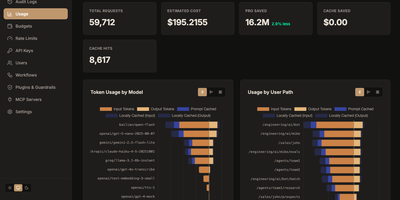
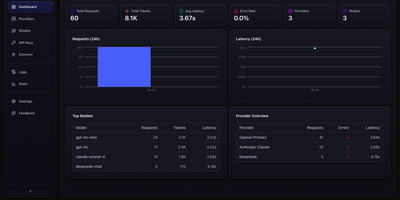
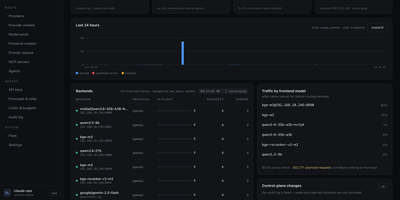
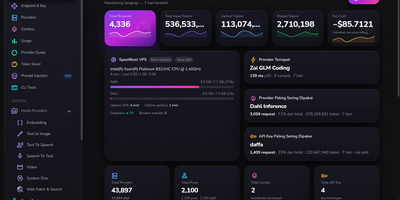
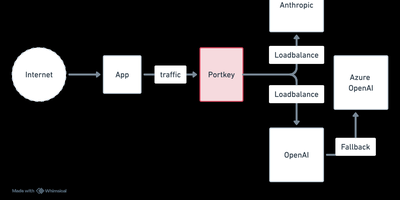
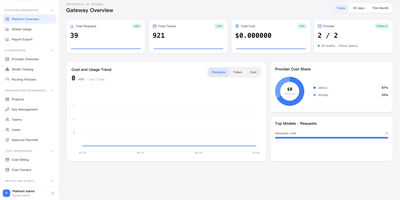
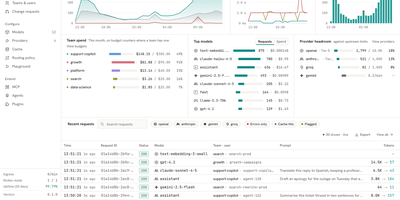
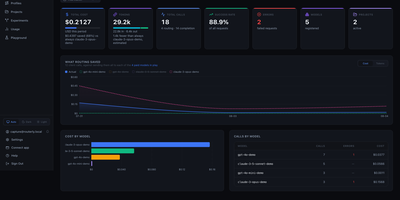
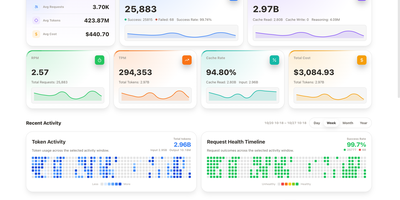
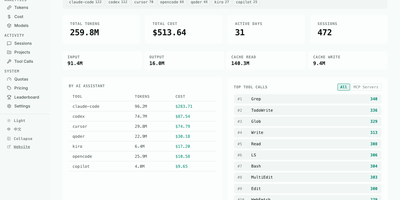
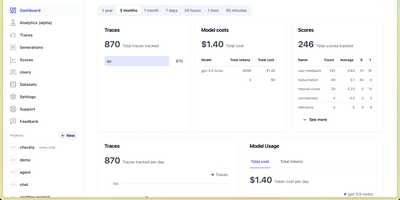
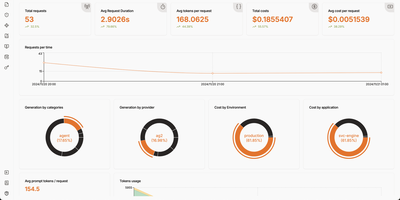
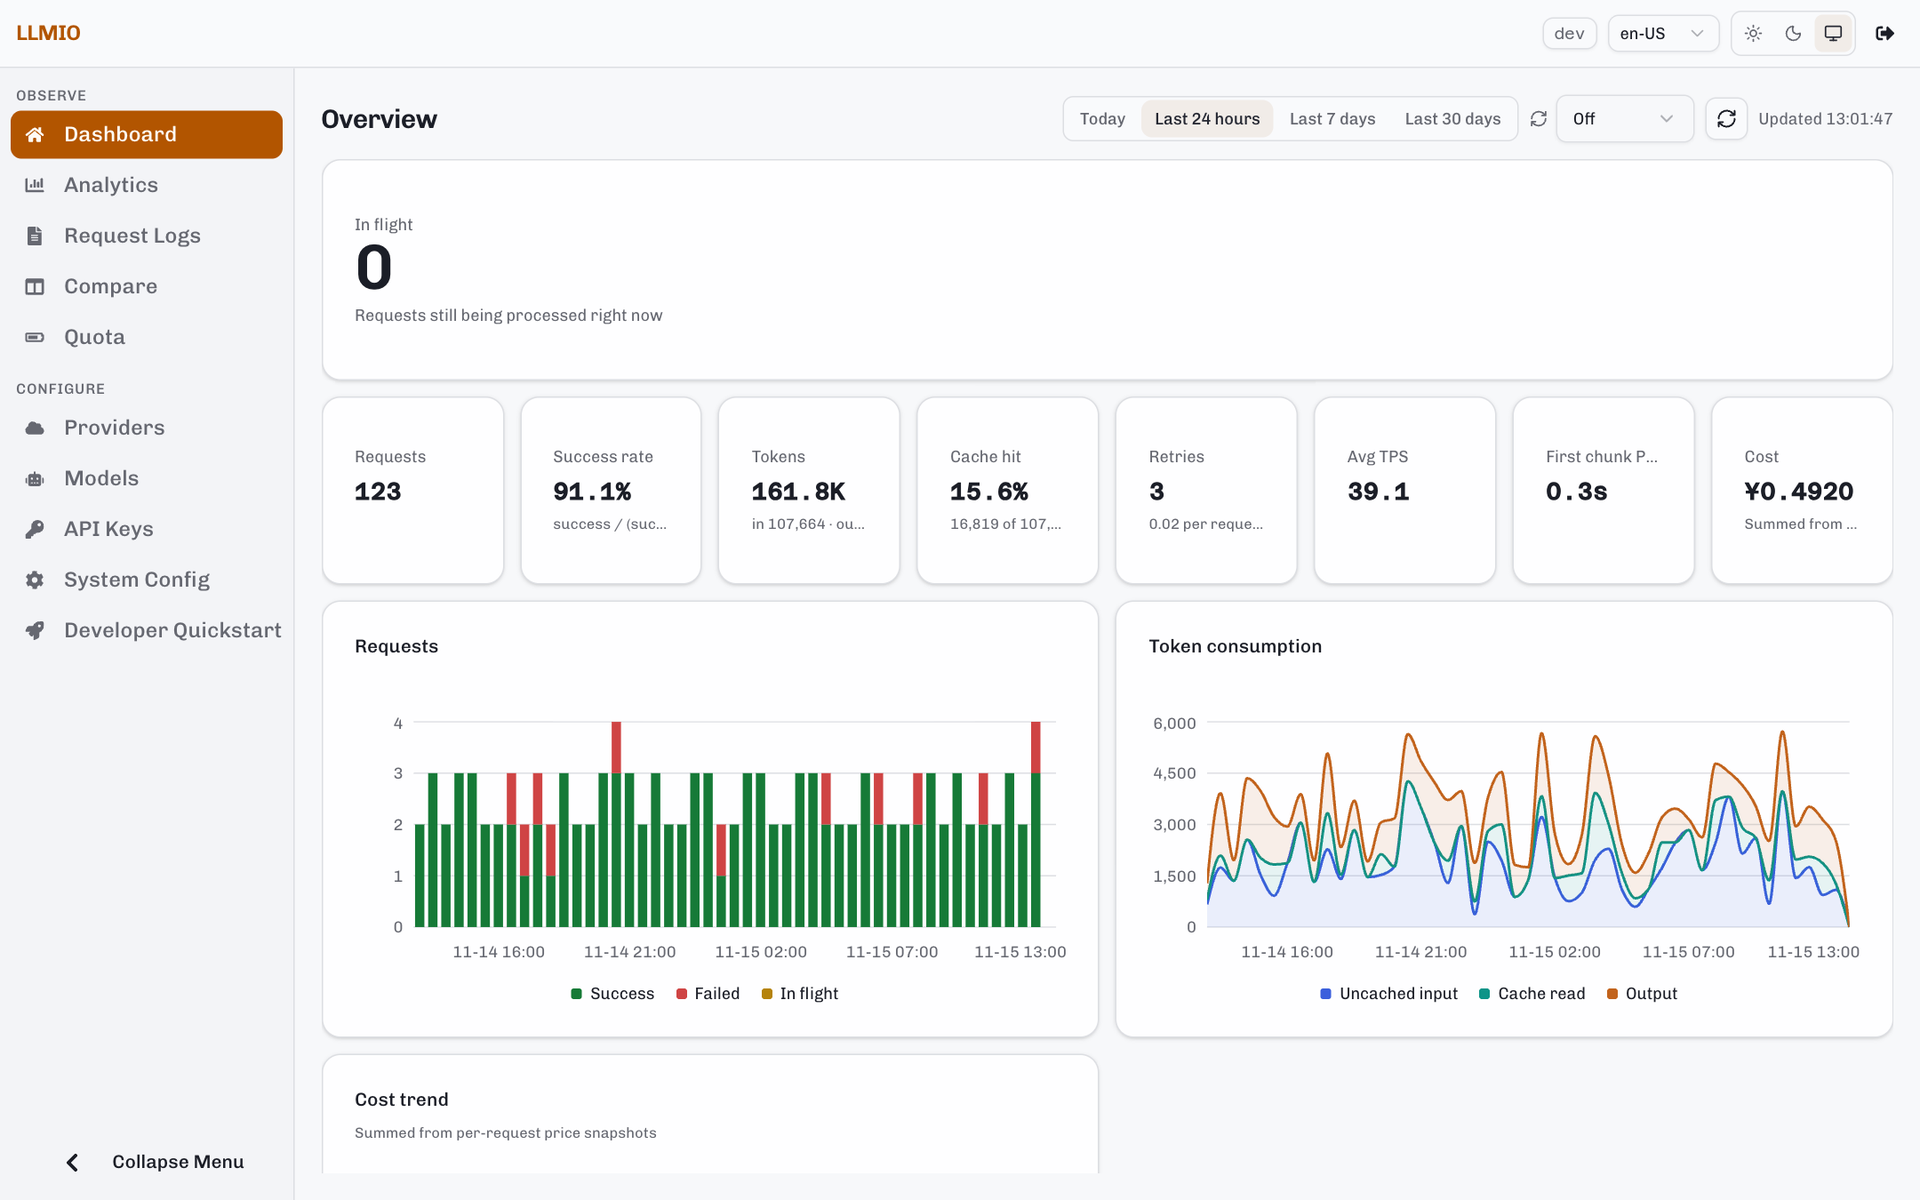
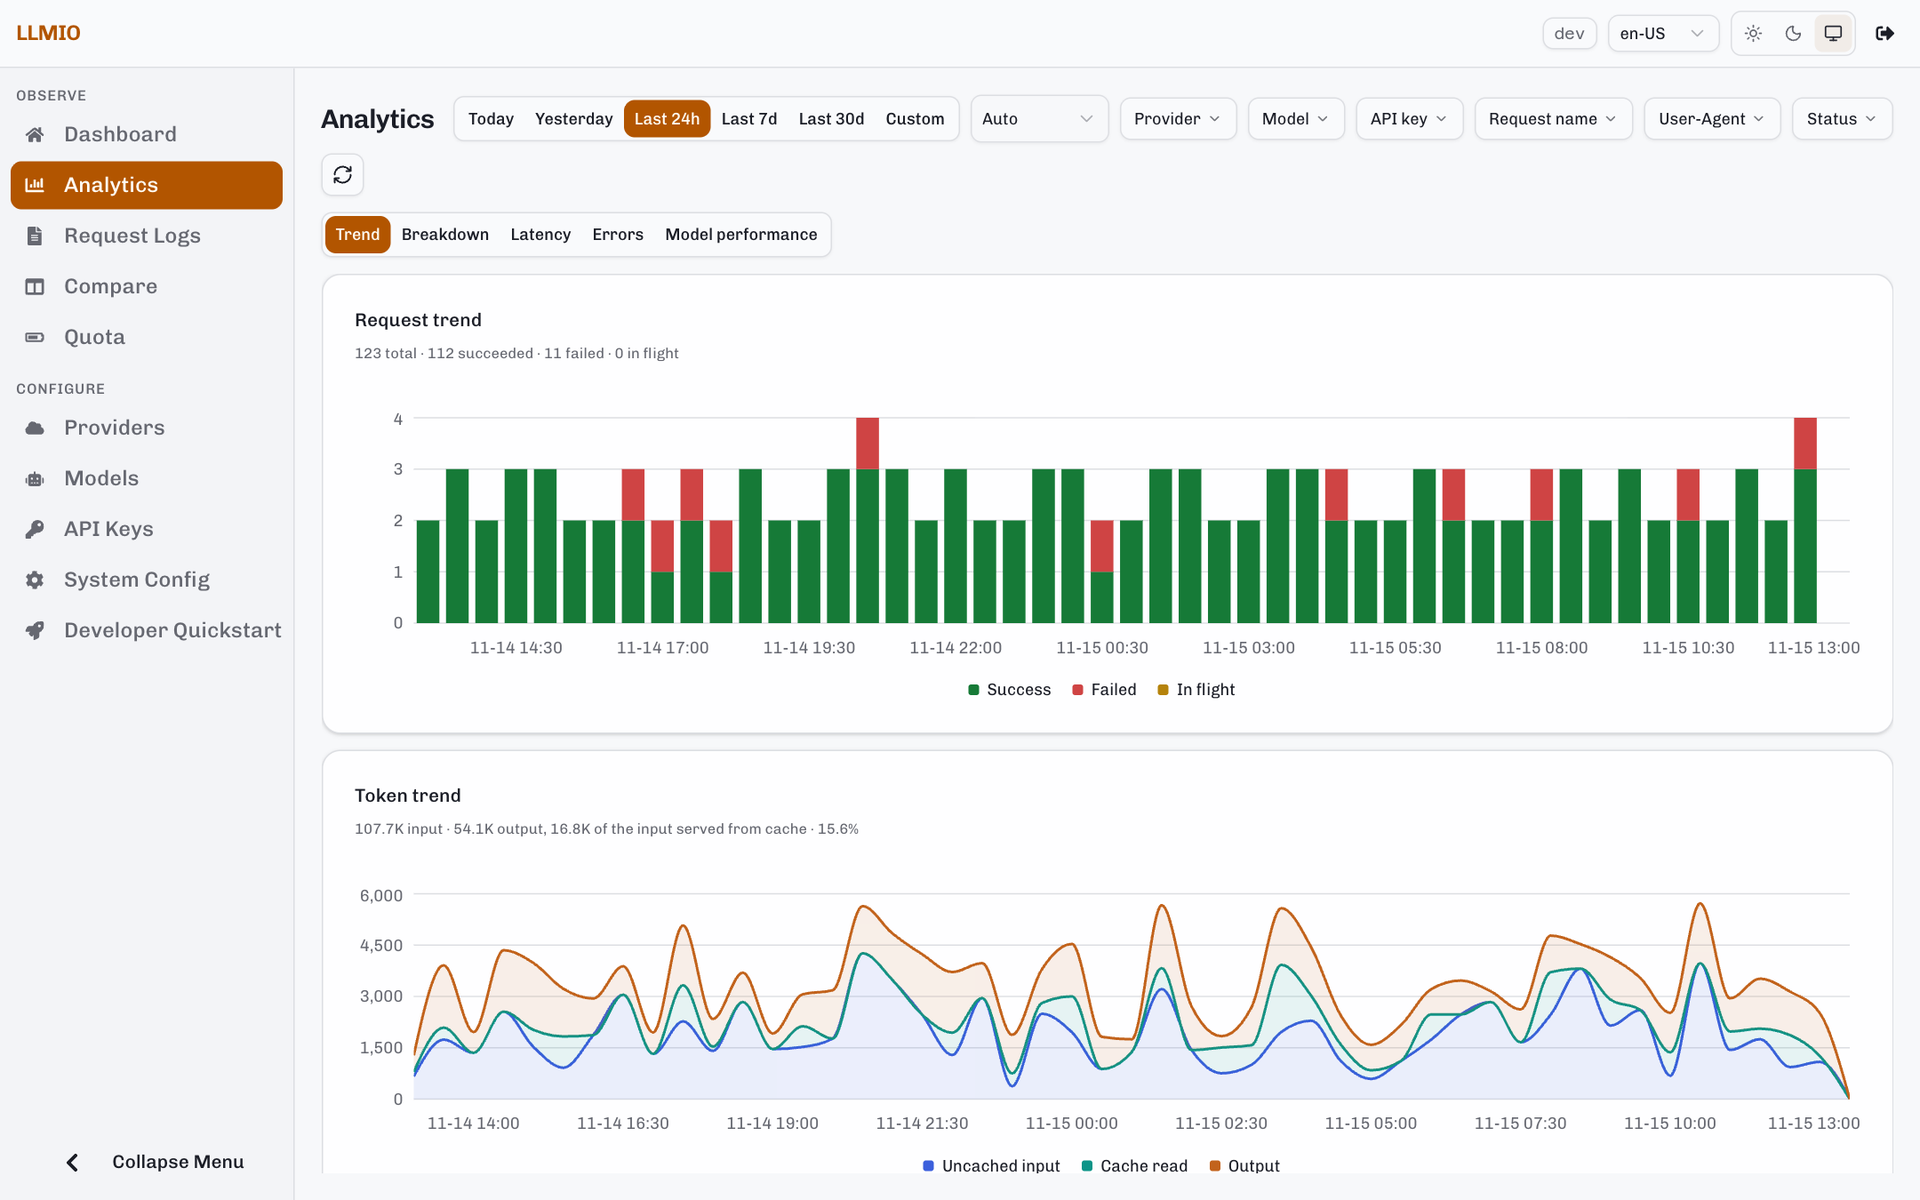
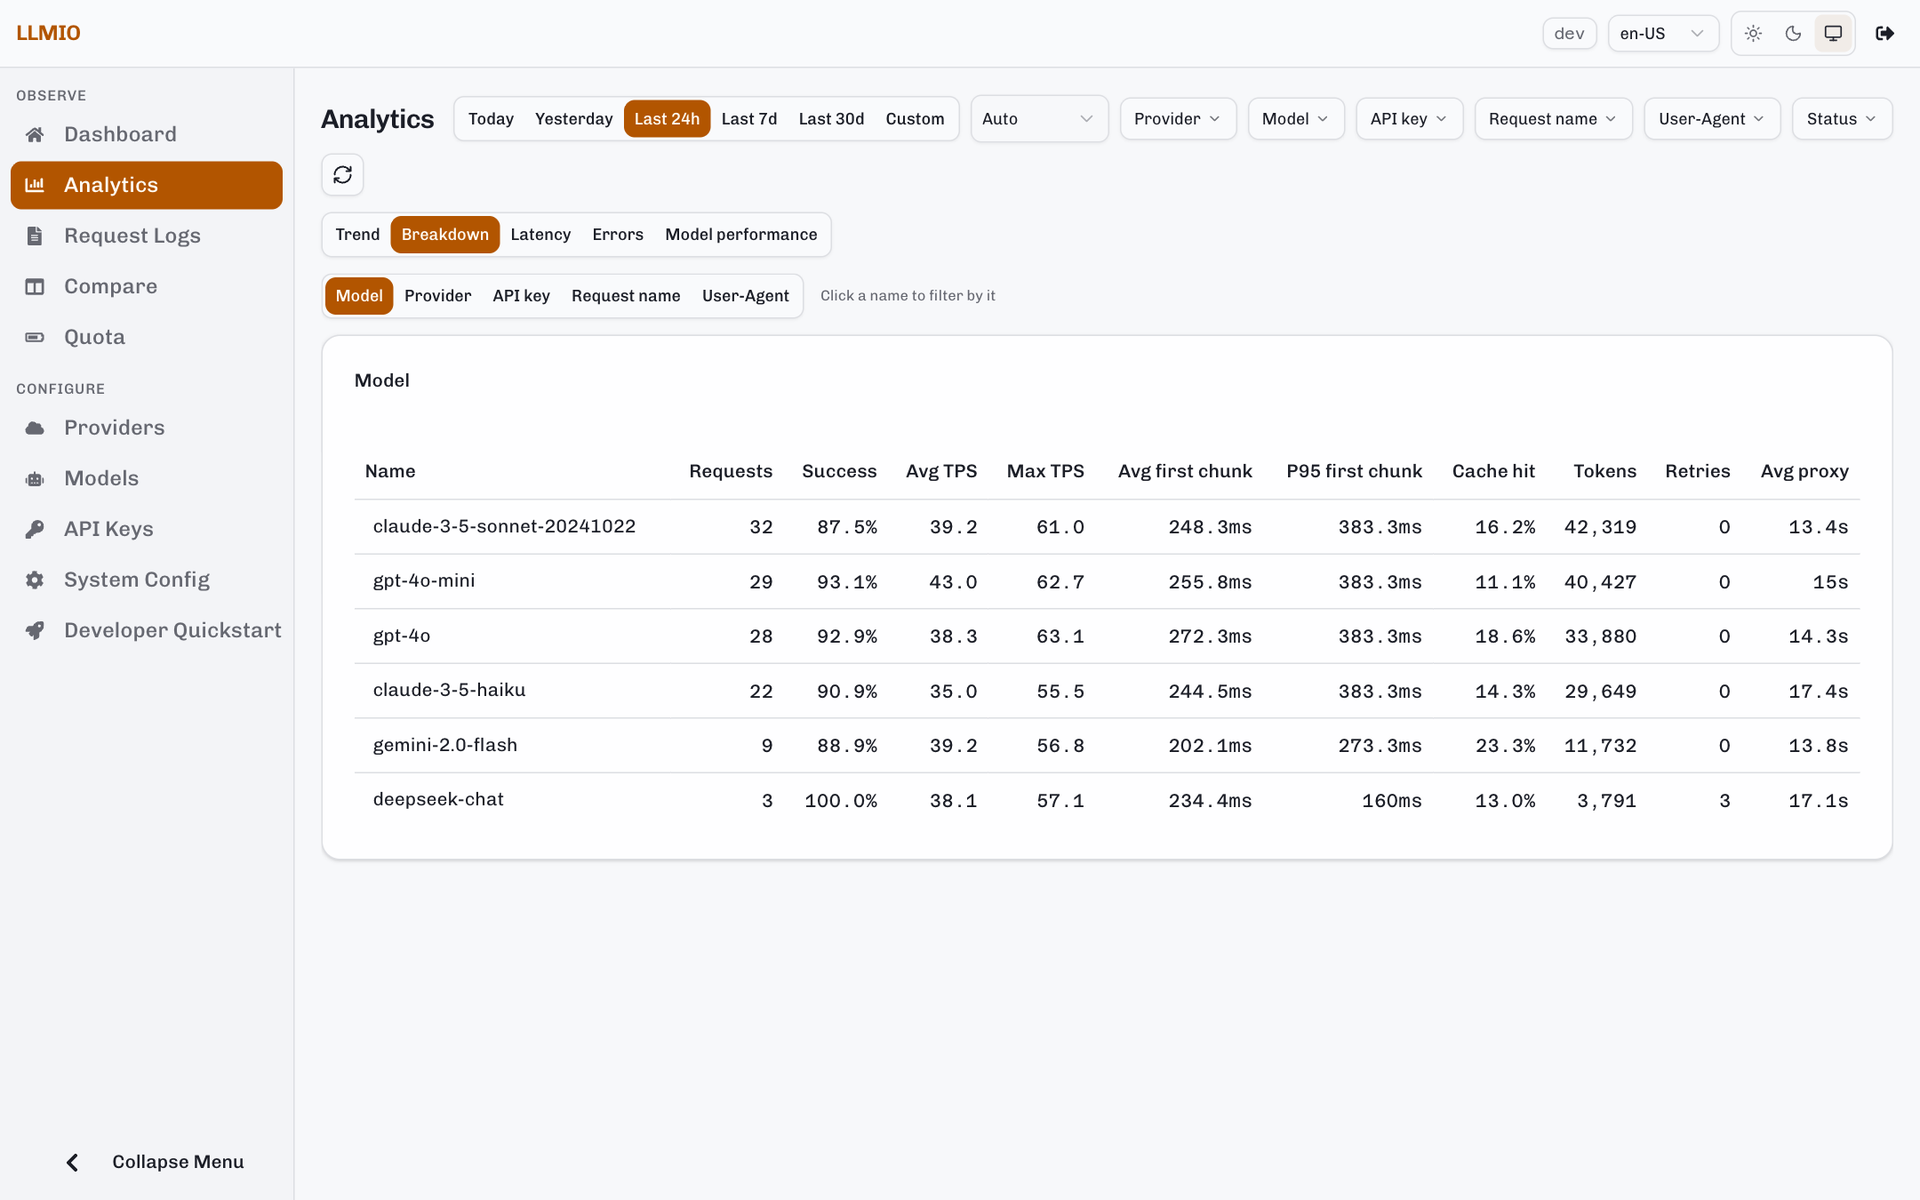
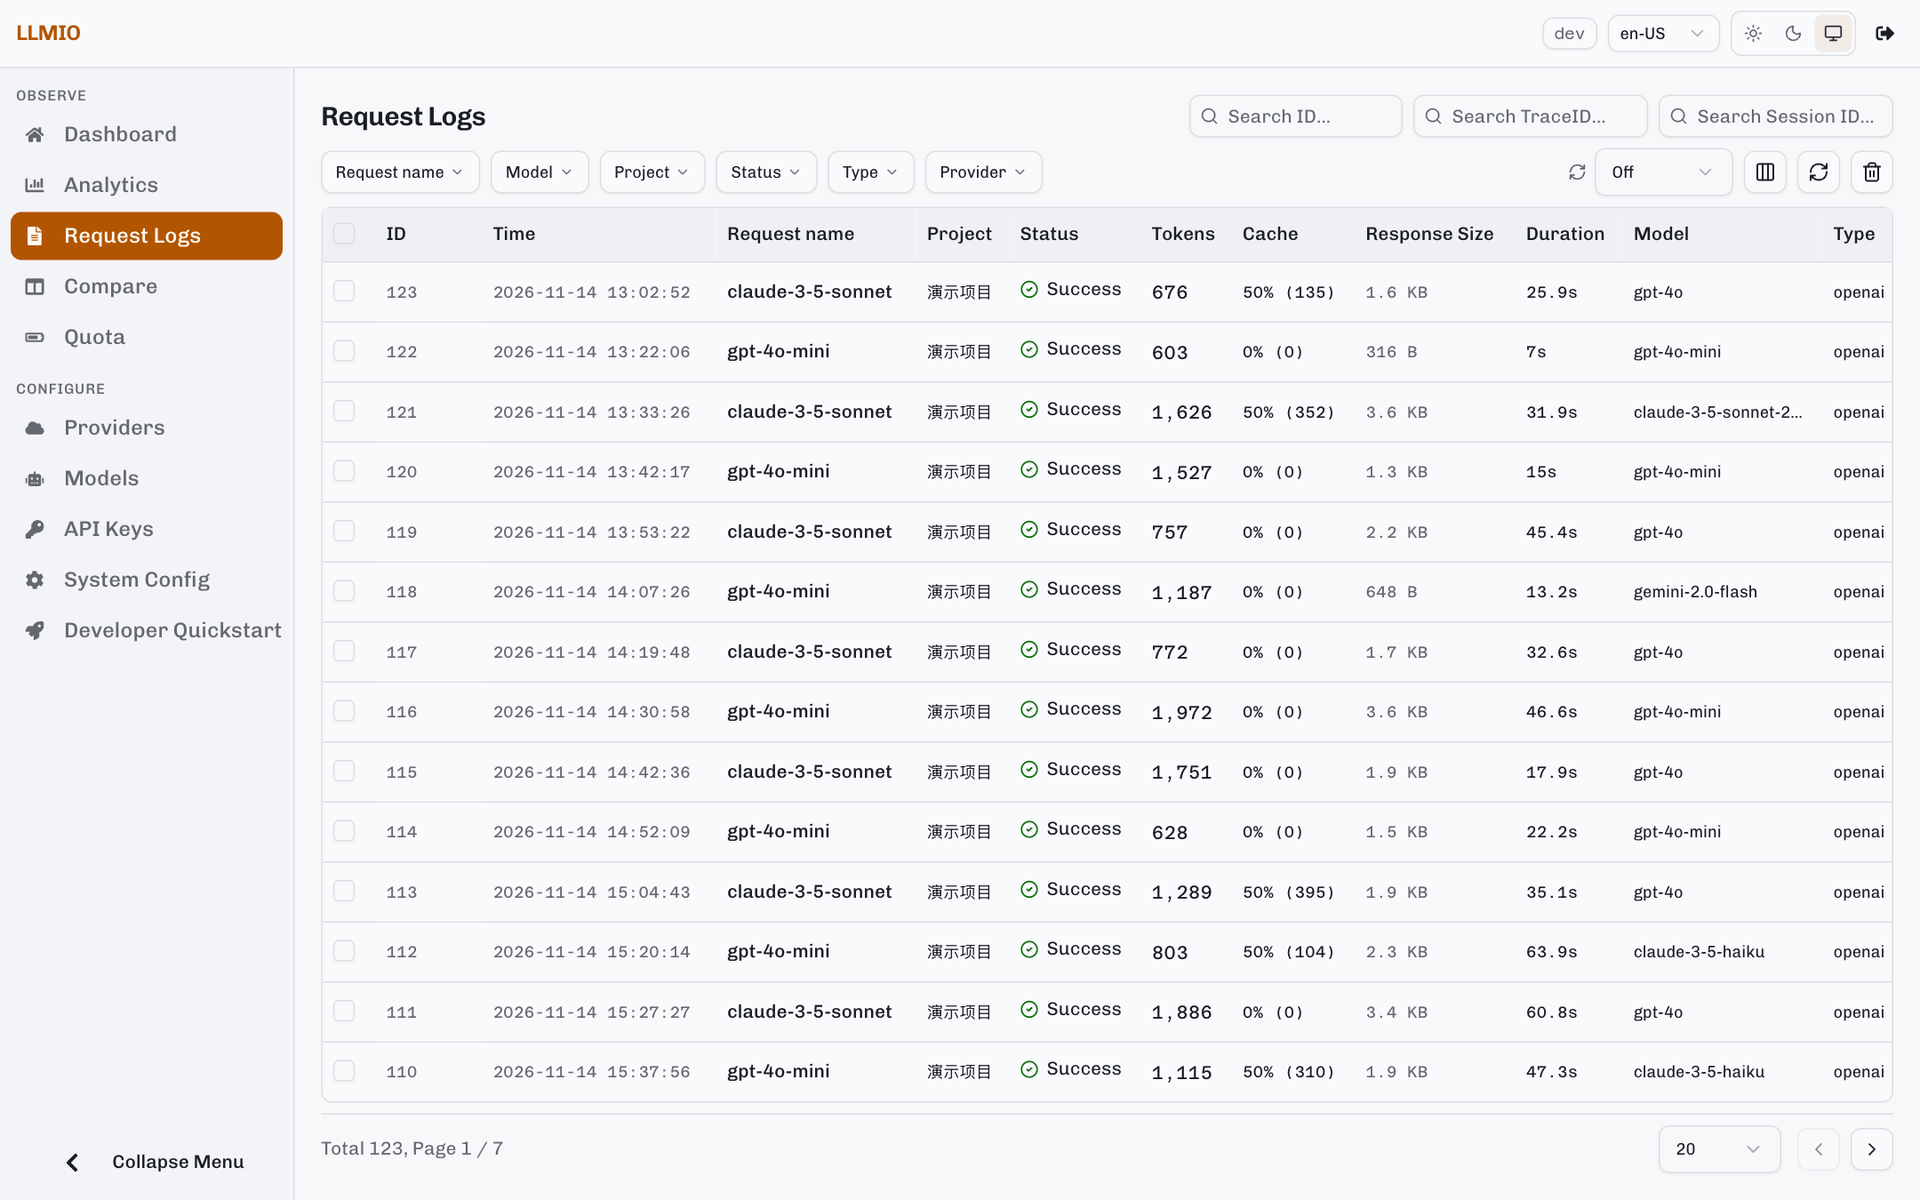
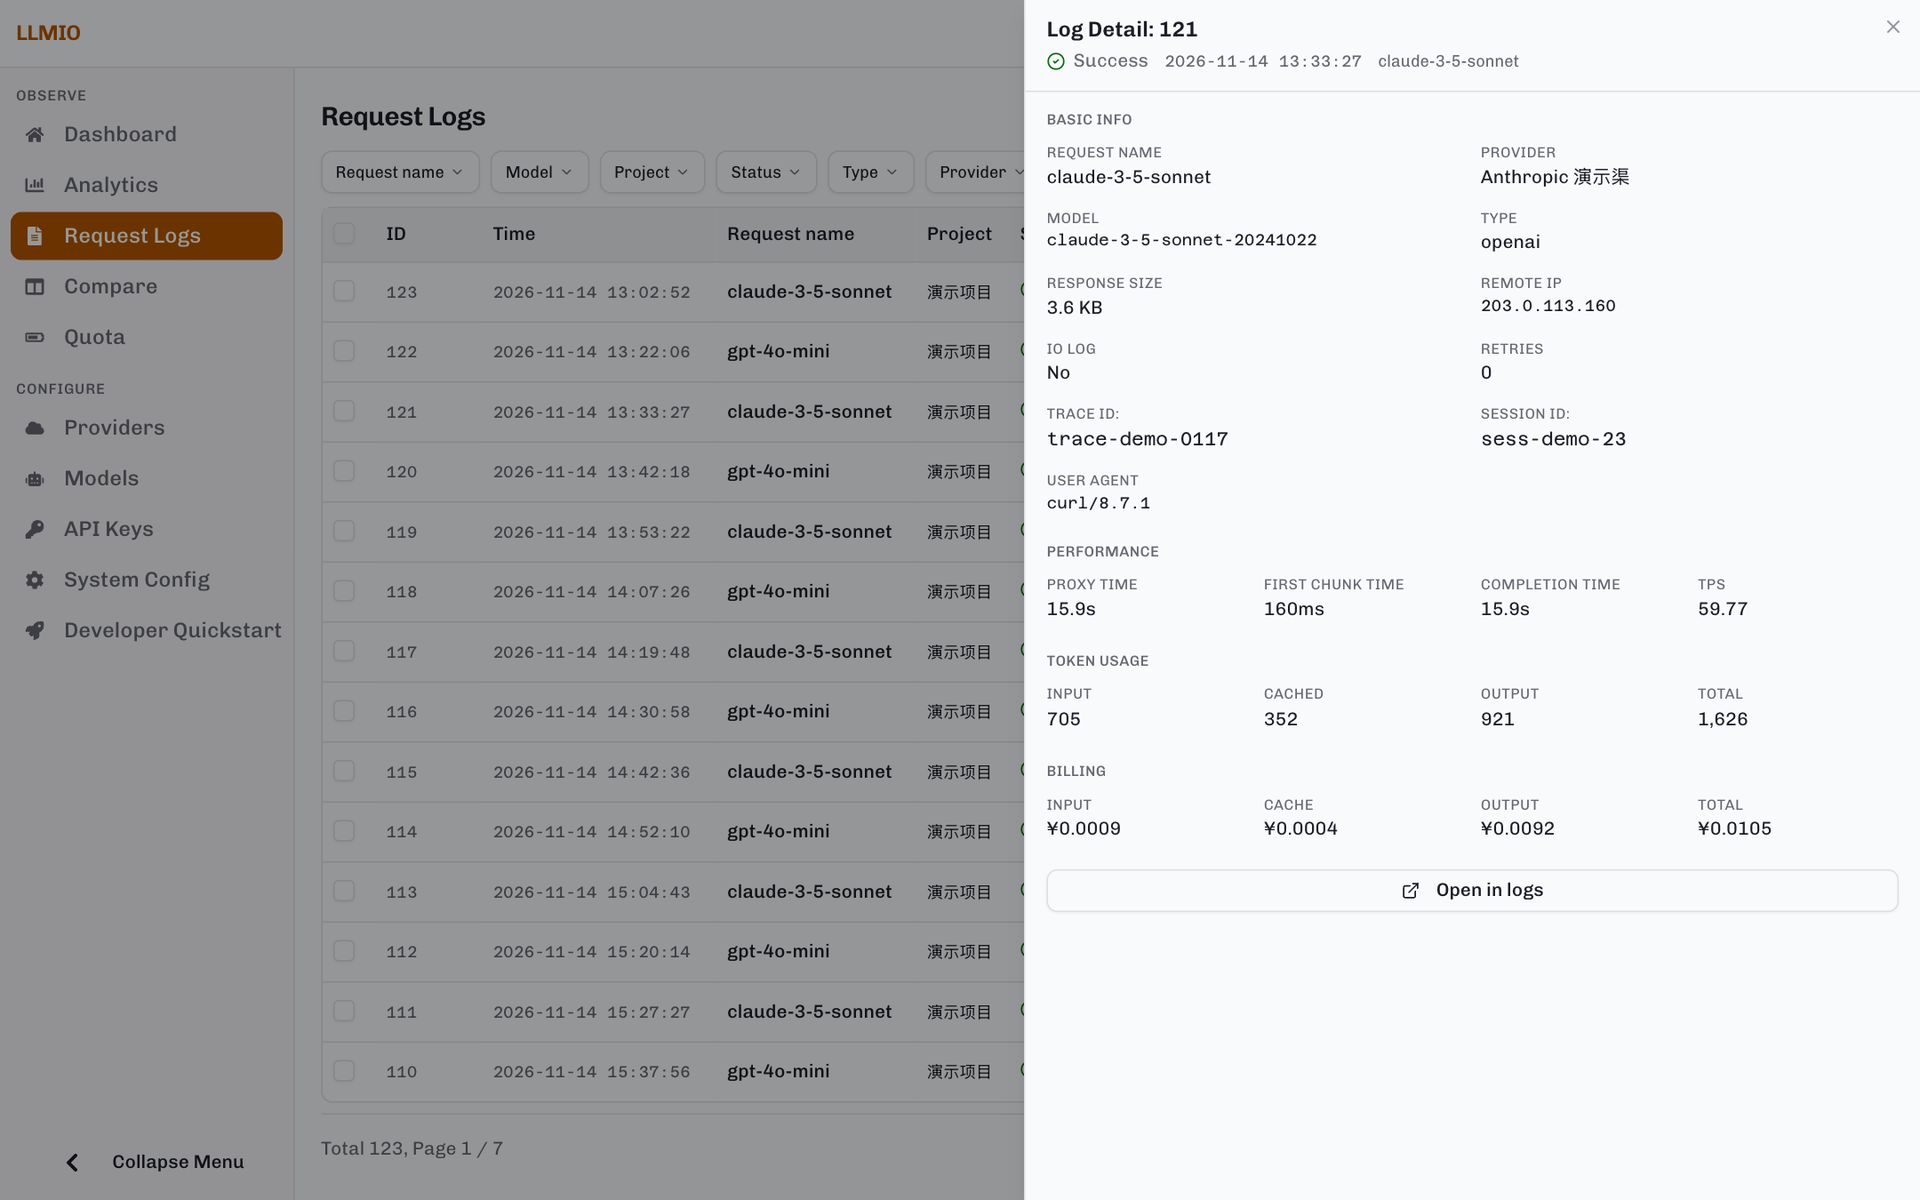
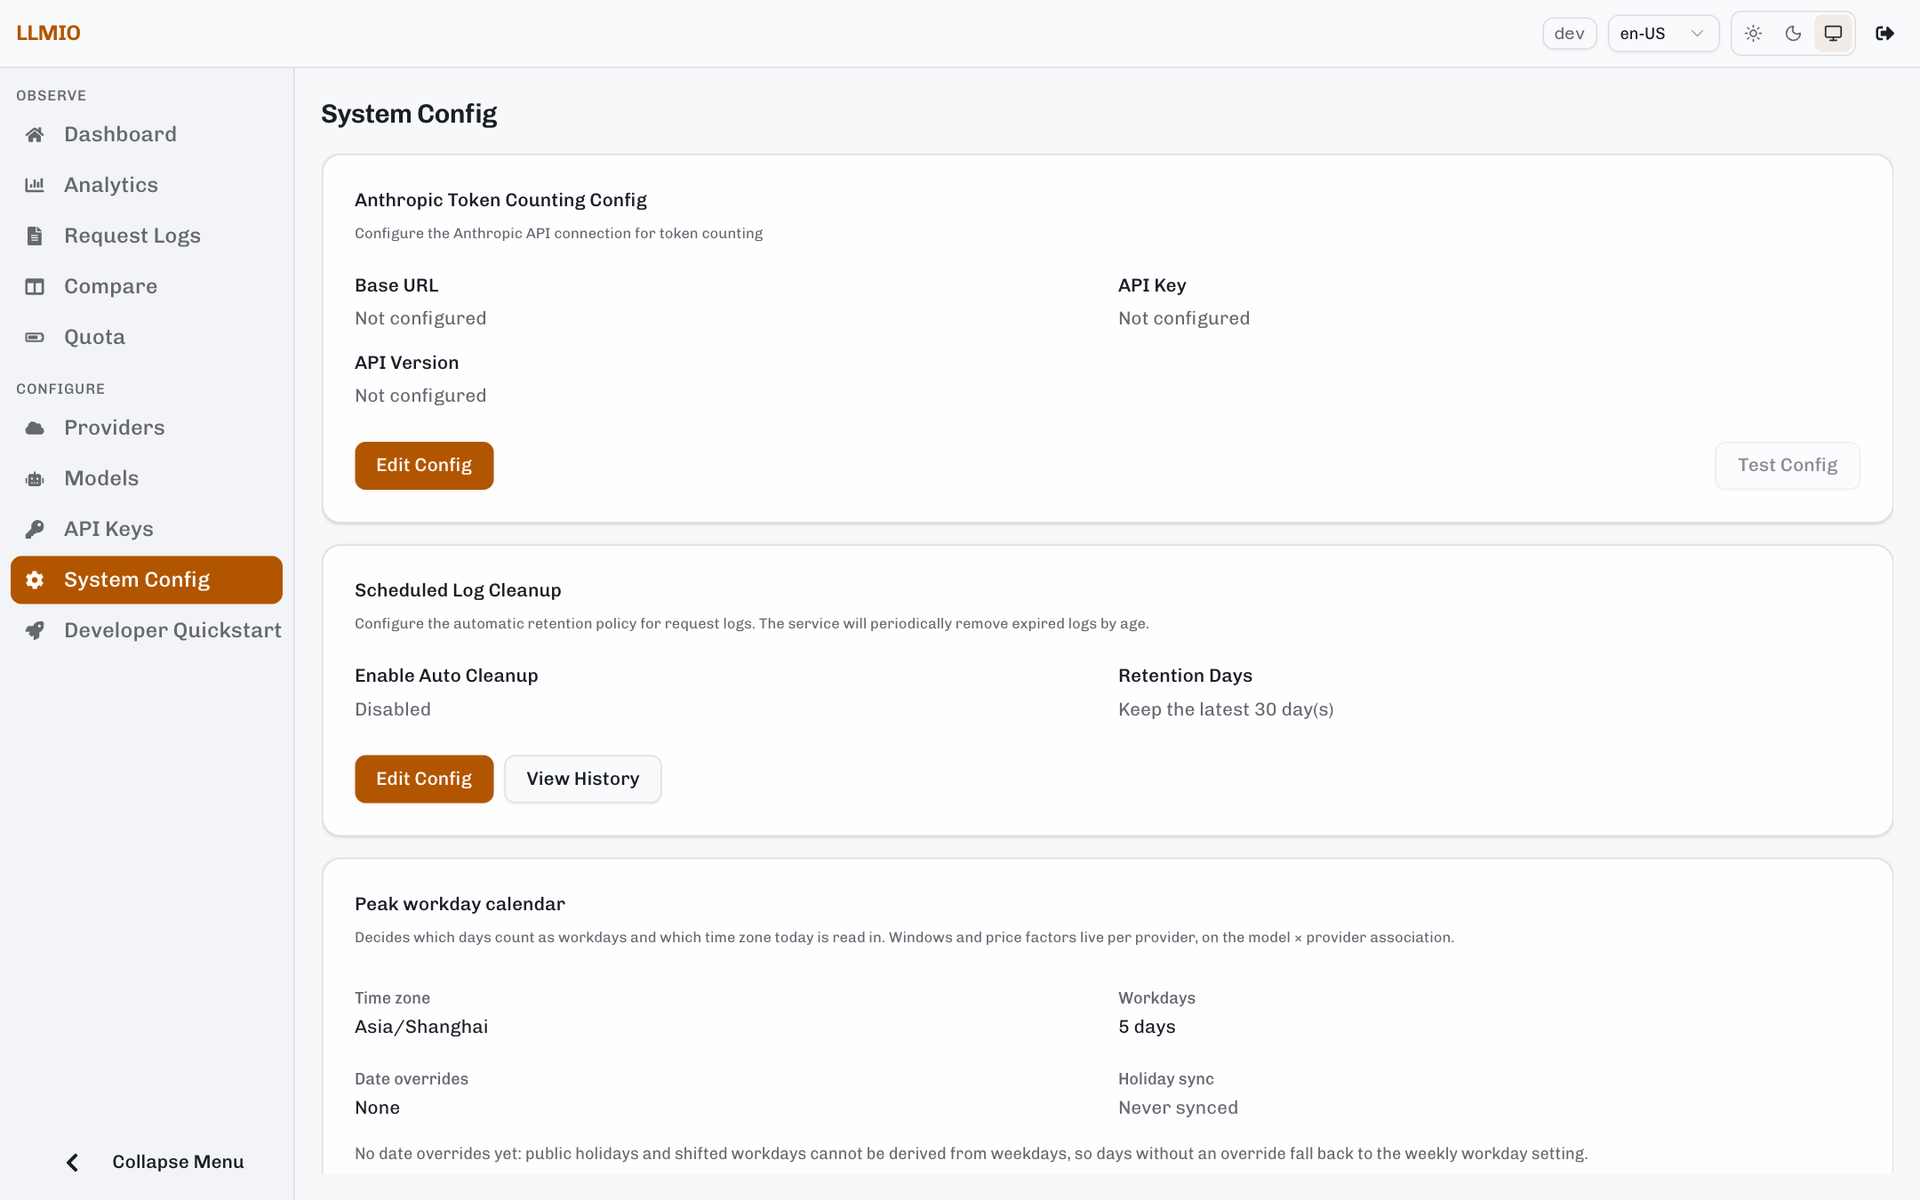
Every provider has its own API, quota, and price list, and LLMIO puts them all behind one door. Clients speak OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, or Gemini, and a protocol bridge translates between OpenAI and Anthropic formats, including streaming events, when the upstream differs. Each model name maps to several providers with weights, a lottery or rotor load strategy, retry limits, and timeouts, and routing can follow tool calling, structured output, and image support. A per-model circuit breaker and rate-limit fallback keep one failing upstream from taking the rest down. The dashboard shows live requests, success rate, tokens, cache hits, retries, tokens per second, and cost, and analytics add trend, breakdown, latency, error, and model performance views with provider, key, and status filters. The request log records trace and session IDs with full request and response inspection, and a compare page lines up to six requests to show how a prompt cache builds. Access keys carry expiry dates, model allow-lists, and optional body logging. Quota sources, time-of-day pricing, and scheduled log cleanup round out the console. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- One Door For Every Provider
- Claude Code, Codex, Gemini CLI, Open WebUI, and other clients all call one address, and the gateway forwards each request to whichever provider is chosen.
- Failures Stay Contained
- Weighted retries, rate-limit fallback, and a circuit breaker per model move traffic to healthy upstreams, so one provider outage does not interrupt the people using your gateway.
- Costs And Latency Visible
- Every call stores tokens, cache reads, first-chunk time, tokens per second, and calculated cost, so slow models and expensive routes show up in charts instead of surprise invoices.
- Separate Keys Per Client
- Give each tool or teammate its own access key with expiry, model allow-list, and optional request recording, then filter logs and analytics by that key.
Features
- Weighted Model Routing
- Attach several providers to each model with weights, retries, and timeouts, and pick a lottery or rotor strategy, with optional routing by tool-calling or vision capability.
- Protocol Bridge
- Translate requests, responses, and streaming events between OpenAI and Anthropic formats automatically, and see which fields were recorded or rejected in the log detail view.
- Usage Analytics
- Explore trend, breakdown, latency distribution, error groups, and model performance tables for custom time ranges, filtered by provider, key, model, user agent, and status.
- Request Log Inspector
- Search requests by ID, trace, or session, open a side panel with timing, tokens, and billing, and compare several logs to understand prompt caching.
- Quota And Pricing
- Track upstream balances from built-in adapters, HTTP endpoints, or scripts, and apply time-of-day price multipliers with a workday calendar for accurate cost reports.