Categories
Developer Tools Observability AI Gateway API Management LLM Infrastructure Model Routing Cost AnalyticsStars
Forks
Watchers
Developer links
LLM Gateway
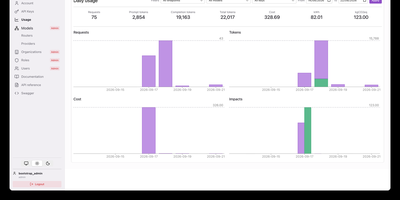
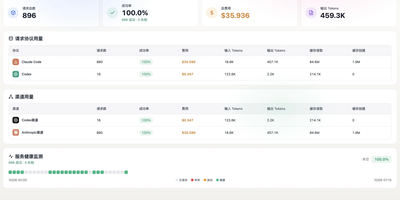
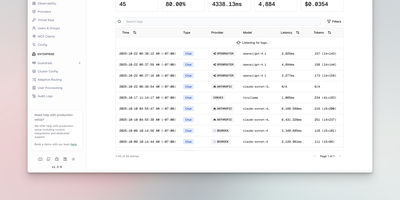
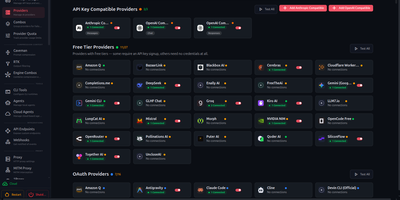
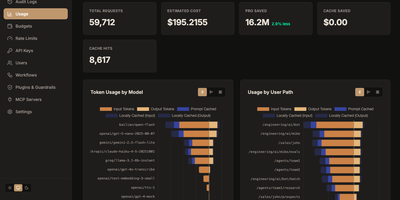
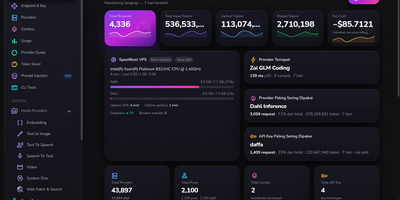
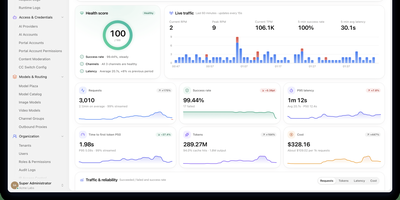
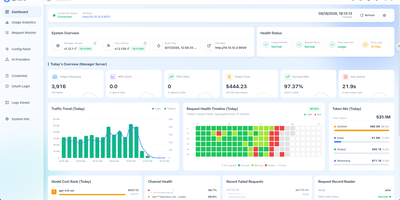
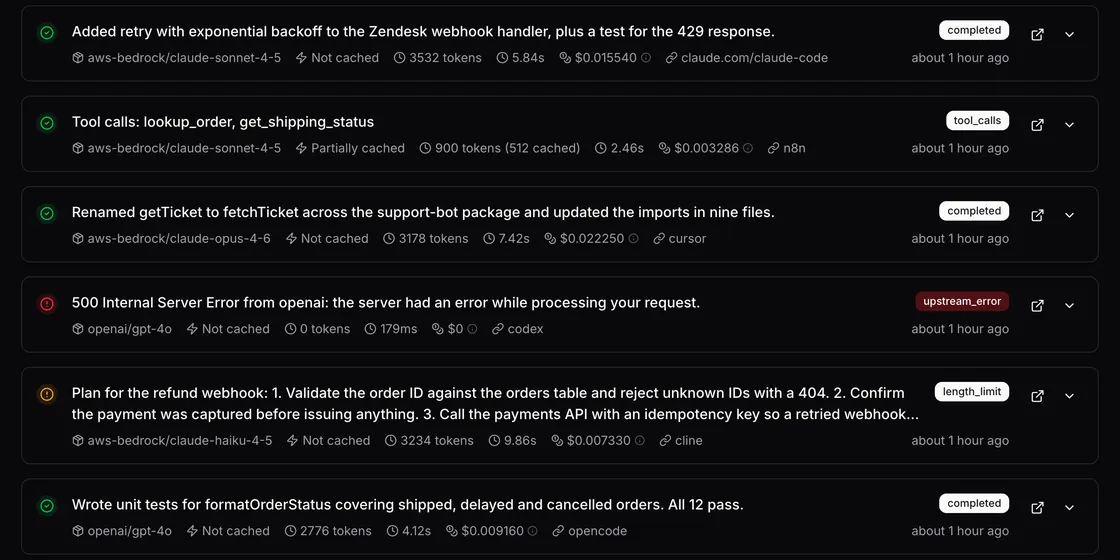
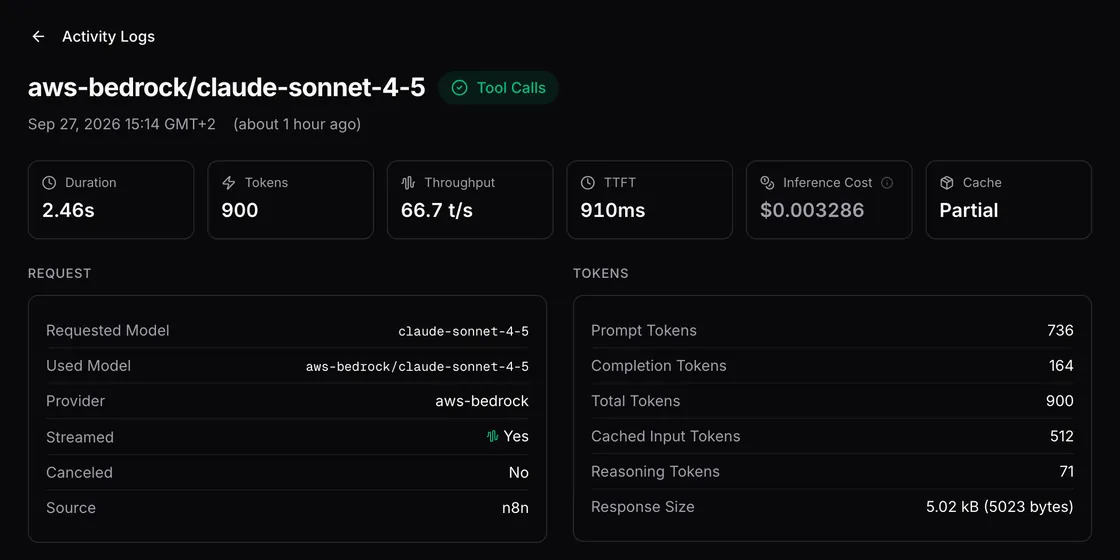
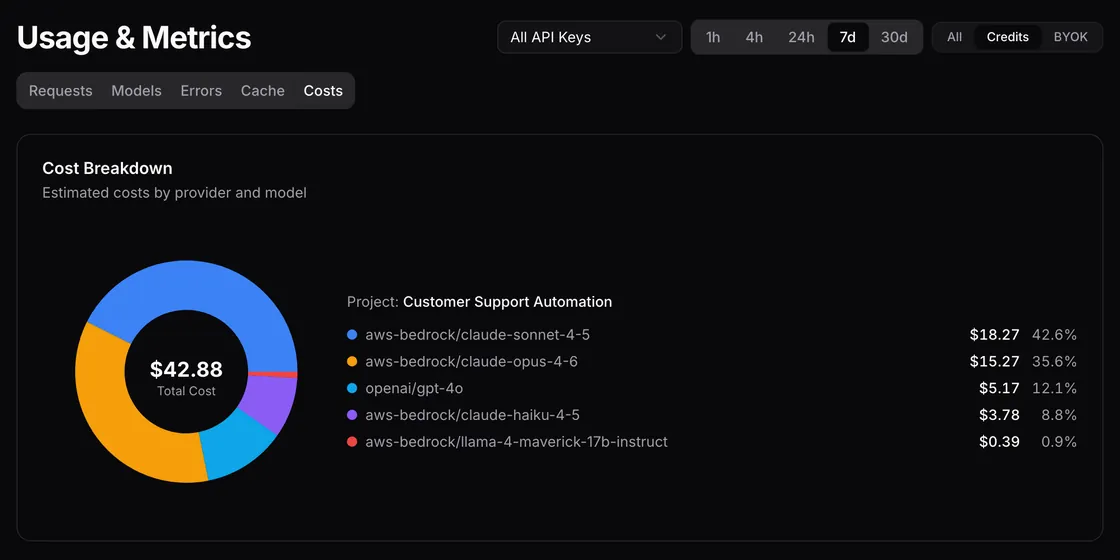
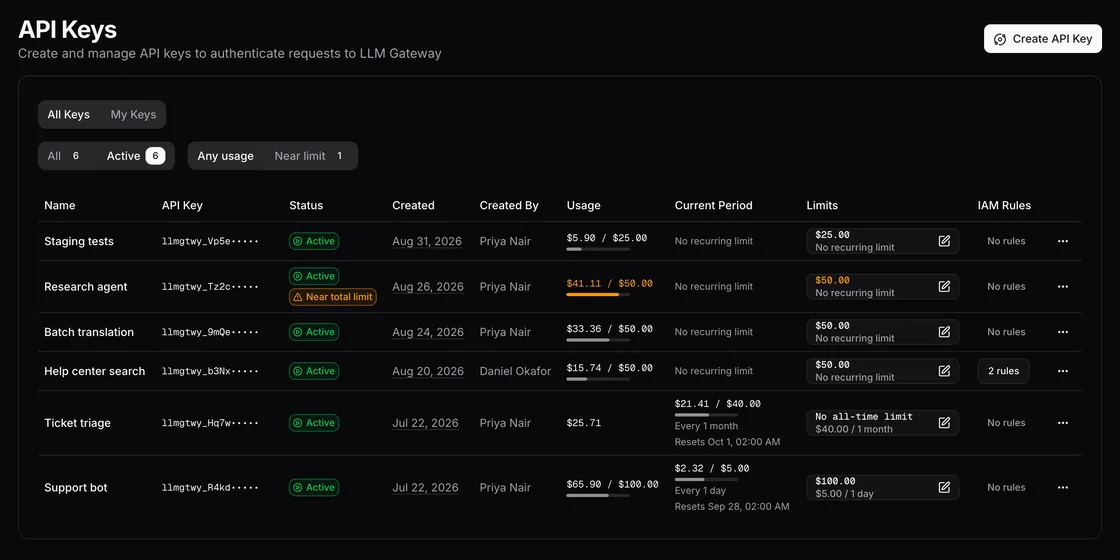
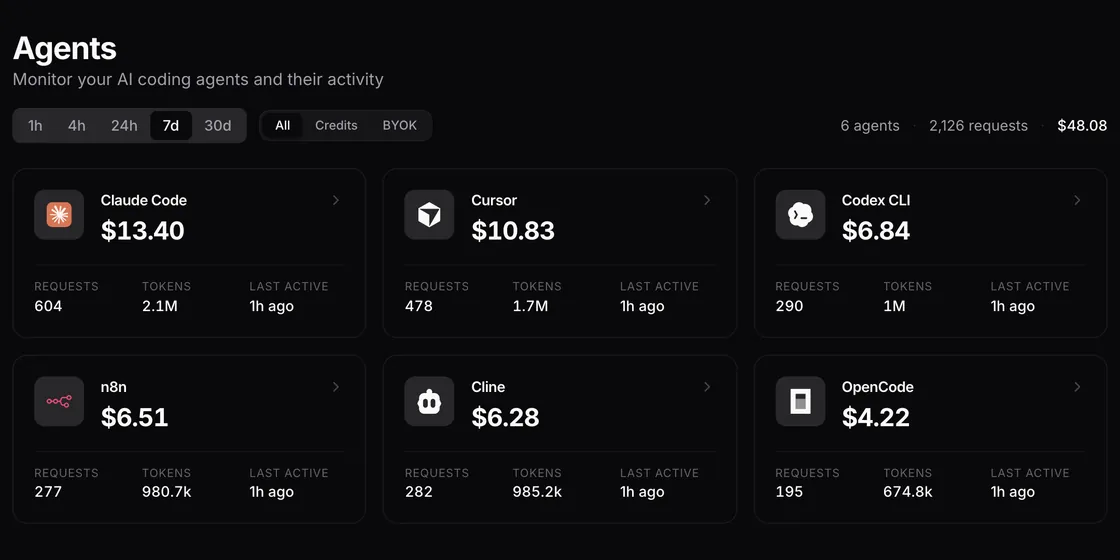
One OpenAI-compatible API fronts more than 250 models across 40 providers in LLM Gateway, with routing, cost analytics, and key management in a single dashboard. Existing OpenAI SDK code keeps working: change the base URL and model name to reach OpenAI, Anthropic, Google, xAI, DeepSeek, Groq, and dozens more. Every request lands in an activity log with its model, cache status, token counts, duration, and cost, and opening a request shows time to first token, throughput, and cached token usage. Spend splits by model, provider, project, and API key over 7 or 30 days, so the expensive endpoint stops hiding inside one monthly invoice. Scoped API keys carry spend caps and recurring limits, and requests stop automatically at the cap. Provider errors, timeouts, and rate limits trigger a retry on another provider for the same model before the caller hears about it. Coding agents and automation tools get their own usage views with requests, tokens, and spend per tool. Self-hosting runs the unified Docker image or a Kubernetes Helm chart on your own network. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
- One API, Every Provider
- Reach more than 250 models from over 40 providers through a single OpenAI-compatible endpoint, changing only the base URL and model name in your existing SDK code.
- Per-Request Cost Visibility
- Every request is logged with model, tokens, duration, cache status, and cost, and spend breaks down by provider, model, project, and API key.
- Spend Caps On Keys
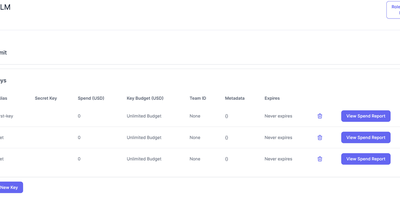
- Scoped API keys carry spend caps and recurring limits, and the gateway stops requests automatically when a cap is reached, before an invoice can surprise you.
- Automatic Provider Failover
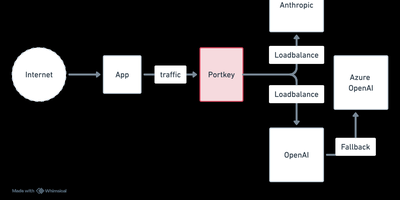
- When a provider errors, times out, or rate limits a request, the gateway retries on another provider for the same model before responding to your application.
Features
- OpenAI-Compatible Endpoints
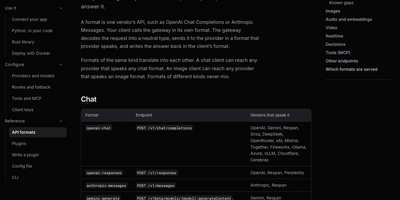
- Chat completions, responses, image generation, and image edits are exposed under one gateway, so existing OpenAI SDK code works unchanged.
- Activity And Request Logs
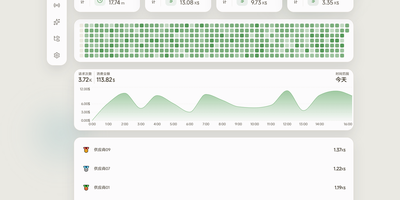
- The activity view lists each request with its model, cache status, tokens, duration, cost, and source tool, and each request opens into a full detail page.
- Per-Model Cost Breakdowns
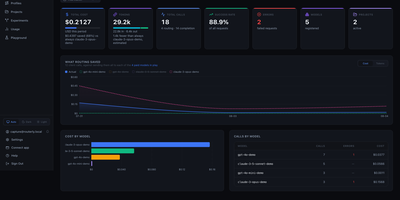
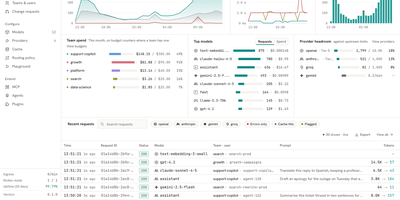
- Donut charts and tables split spend by model and provider per project over 7 or 30 days, showing average cost per thousand tokens.
- Scoped Keys And Caps
- Create keys per application with masked display, creator tracking, spend against each cap, recurring limits, and rules that stop traffic at the limit.
- Provider Failover Retries
- Failed, timed-out, or rate-limited requests retry up to twice on another provider for the requested model, and pinned requests stay with their provider.