Stars
Forks
Watchers
Developer links
Google Browser Scraper
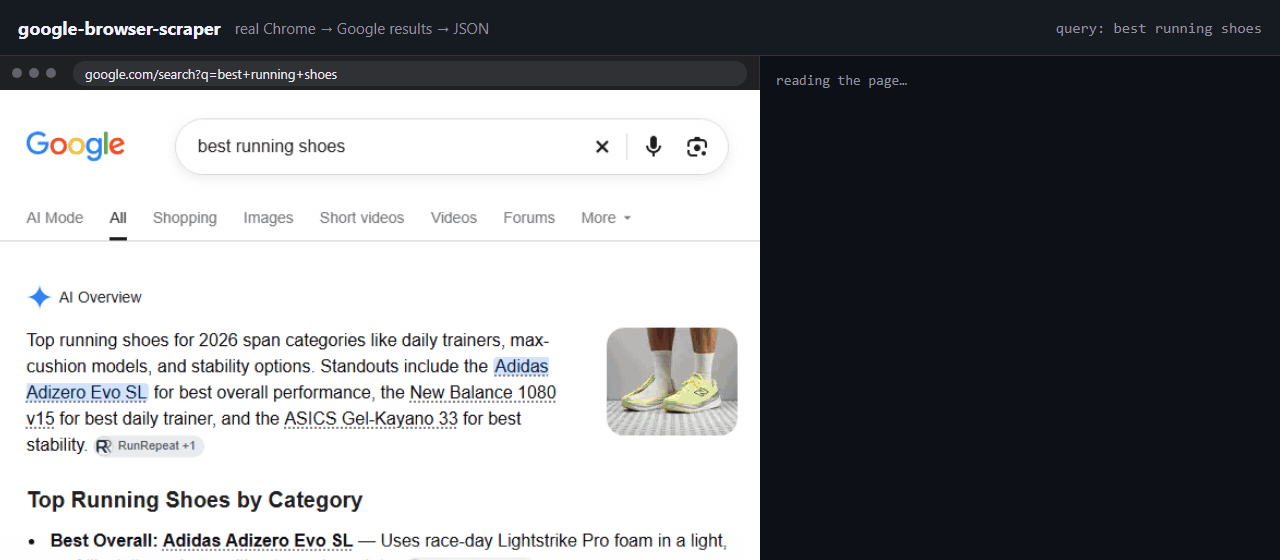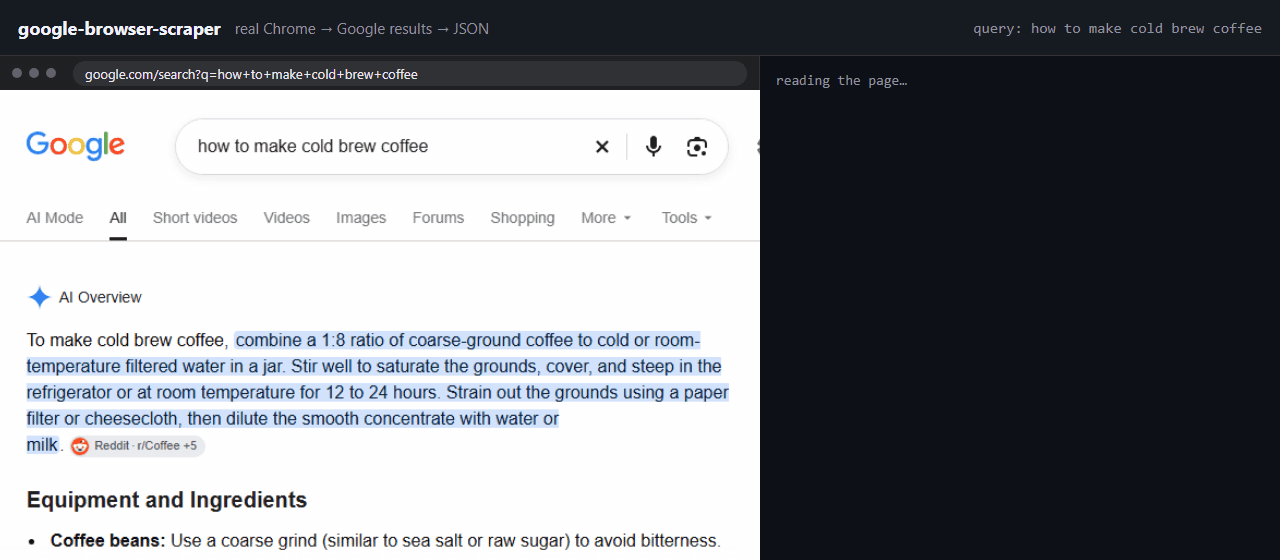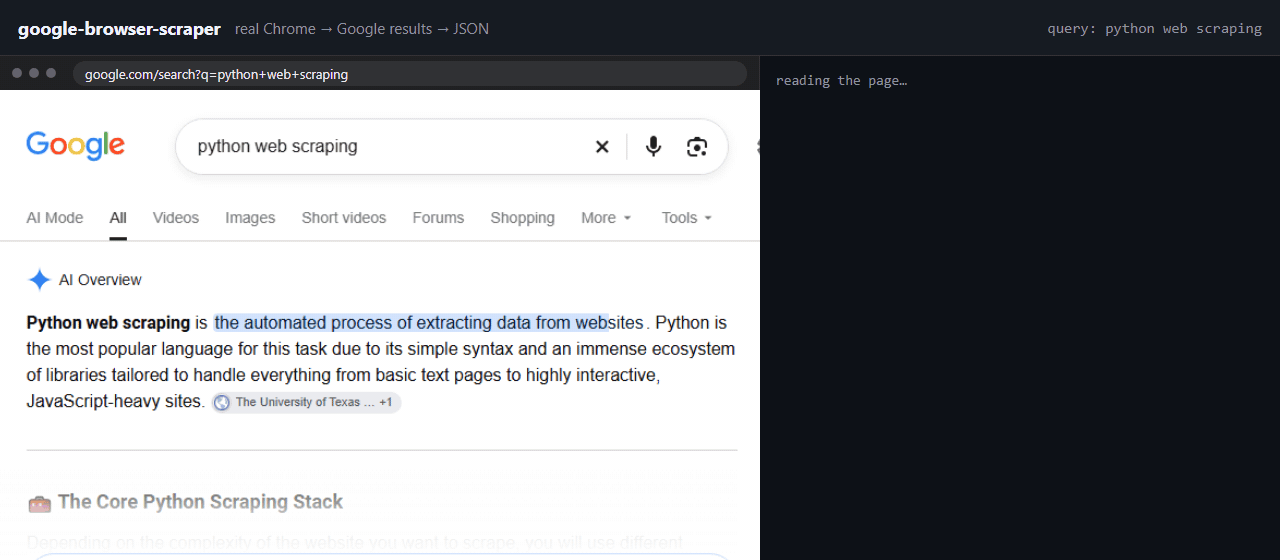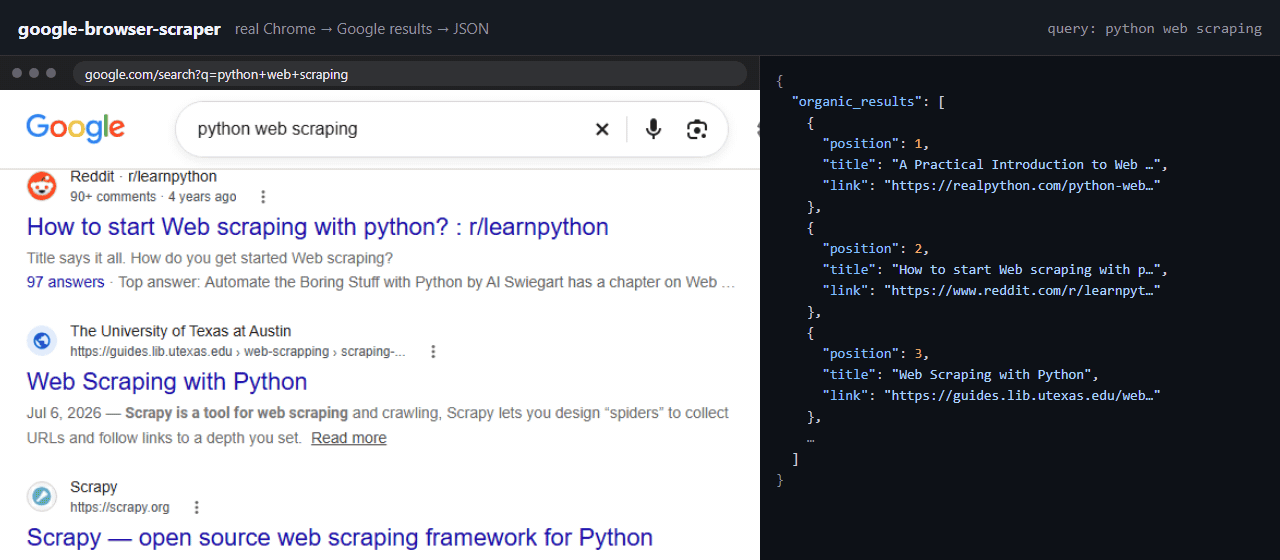
Google Browser Scraper is a self-hosted SERP API that gets Google results from a real Chrome browser and your own residential proxy, because plain HTTP scraping is refused and a fresh browser on a fresh IP is refused almost as fast. It warms a sticky proxy session with ordinary browsing first, lets the browser pass Google's checks, and then switches to a hybrid mode that fetches results pages directly over HTTPS with the browser's own cookies, at about 0.4 MB and 1.4 seconds per search on a warm IP. Every page comes back as SERP-style JSON with organic results, ads, related questions, related searches, pagination, the AI Overview, and local results. If a proxy IP starts serving poisoned pages for some other query, the scraper catches it within a few pages, drops that IP, and asks the query again on a fresh one. Captchas and blocks are reported as captchas and blocks, never disguised as an empty result set, so your pipeline knows when to retry or rotate. Run it as a CLI for keyword files, import it as a Python library, serve it as a local HTTP API, or expose the MCP server so AI agents get live Google search. Every run ends with a traffic and cost summary per thousand pages, and any sticky residential proxy works, with NodeMaven sessions handled for you. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Real Chrome Passes Checks
- Real Chrome via Patchright is warmed up before every new identity, so Google's checks pass instead of refusing a fresh browser on a fresh proxy IP within pages.
- Hybrid Mode Saves Traffic
- Results pages travel over HTTPS between Google's checks at about 0.4 MB and 1.4 seconds per search on a warm proxy IP, a fraction of full browser traffic.
- Poisoned Results Caught Early
- Pages of results for some other query are caught automatically: the proxy IP serving them is dropped within a few pages and the query is asked again fresh.
- Failures Reported Honestly Always
- Captchas and blocks come back labeled as such in the page verdict, never disguised as no results, so pipelines can retry, rotate or stop instead of trusting empty data.
Features
- SERP Style JSON
- One JSON object per results page with organic_results, ads, related_questions, related_searches, pagination, ai_overview and local_results, ready for pipelines that expect a SERP API shape.
- MCP Search Server
- An MCP server gives AI agents live Google search, including the AI Overview and map places, so LLM apps read current results instead of stale training data.
- Any Sticky Proxy
- Bring any residential proxy with sticky sessions by putting the session placeholder in the username, with built in NodeMaven support handling the session id for you.
- Traffic Cost Summaries
- Every run ends with a summary of pages served and traffic used, with cost per 1000 pages, and a demo sub user can cap a run's total traffic.
- CLI API Docker
- Run it as a CLI, import it as a Python library, serve it as a local HTTP API or MCP server, or pull the published Docker image from GHCR.