Categories
Data Engineering ETL Data Integration Data Pipelines Stream Processing Synchronization Change Data CaptureStars
Forks
Watchers
Developer links
Apache SeaTunnel
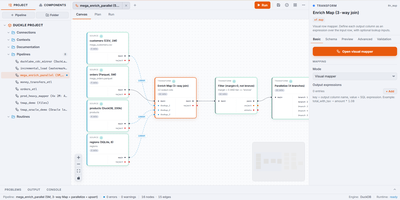
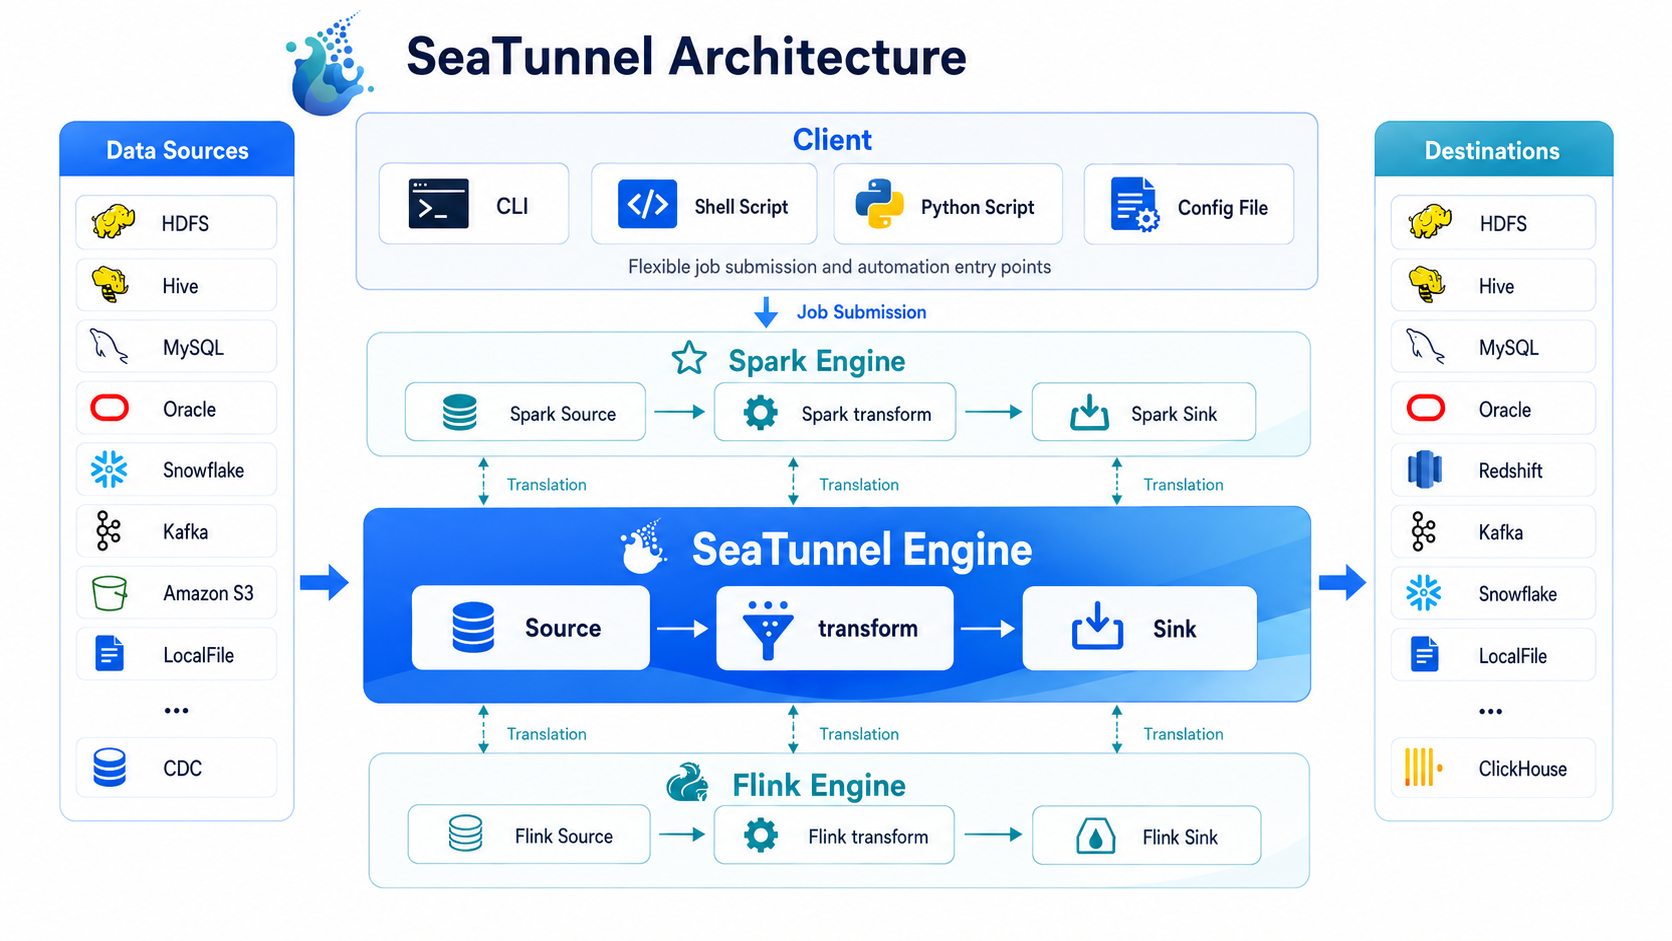
Apache SeaTunnel is a distributed integration platform that runs batch, streaming, and change-data-capture pipelines between databases, message queues, data lakes, lakehouses, and SaaS applications without hand-rolled scripts. Pipelines are declared once in a configuration file and executed on your choice of the native Zeta engine, Apache Flink, or Apache Spark, so the same job definition travels across engines without connector rewrites. Real-time CDC captures row changes from major databases with a snapshot-first handoff that never locks the source, while checkpoint-backed recovery restarts jobs from the last completed checkpoint with exactly-once semantics. When an upstream table gains a column, schema evolution propagates the change downstream automatically instead of pausing the pipeline for manual surgery. Roughly two hundred connectors cover relational databases, Kafka, object storage, search indexes, vector stores, and business apps, and the multi-table routing keeps every record on the right destination path. Engineers can dry-run configurations against sampled data before a full launch, isolate failures per table, and route bad records to dead-letter queues. Release 3.0.0 adds AI-assisted configuration generation from natural language, Python sources and transforms, and document parsing with text chunking for RAG preparation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- One Pipeline, Three Engines
- Define a synchronization job once and execute it on the native Zeta engine, Apache Flink, or Apache Spark. The same configuration and connectors travel across engines, so infrastructure choices never force pipeline rewrites.
- CDC Without Source Locking
- Capture database changes in real time with a snapshot-first approach that hands off to binlog streaming without locking tables. Low-latency replication keeps replicas, lakes, and search indexes continuously current.
- Exactly-Once Recovery Guarantees
- Checkpoint-backed fault tolerance restarts interrupted jobs from the last completed checkpoint with consistent records across failures and retries. Table-level fault isolation and dead-letter queues keep one bad stream from sinking the rest.
- Two Hundred Connectors
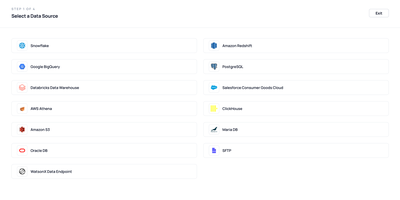
- Move data between relational databases, message queues, object storage, data lakes, vector stores, and SaaS applications through a broad connector catalogue. Multi-table sync and routing handle whole-database replication in a single job.
Features
- Change Data Capture
- Stream row-level changes from MySQL, PostgreSQL, SQL Server, DB2, Vitess, and more with seamless batch-to-stream handoff. Startup modes let you begin from a snapshot, a timestamp, or the latest position.
- Automatic Schema Evolution
- Detect upstream DDL changes such as added columns and propagate them to downstream tables in real time. Pipelines keep flowing through schema changes instead of stopping for manual migration work.
- Zeta Execution Engine
- Run pipelines on SeaTunnel's own distributed engine with worker resource APIs, live job metrics, and dynamic log-level control. Local-sample dry-run validates configurations against real data before full execution.
- Multi-Table Synchronization
- Replicate entire databases table by table in one job, routing each record to its matching destination writer. Parallel split readers divide large batch loads across workers for throughput.
- AI Data Preparation
- Parse PDFs, attach RAG-oriented metadata, and chunk text for downstream embedding and retrieval pipelines. New Python sources and transforms let teams customize extraction in a familiar language.