Categories
Vector Search Data Engineering Real-Time Analytics Big Data Stream Processing Embedded Analytics SQL Analytics OLAP DatabaseStars
Forks
Watchers
Developer links
Apache Pinot
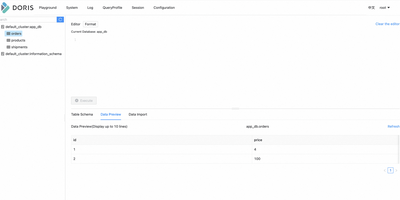
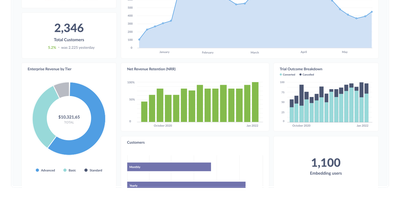
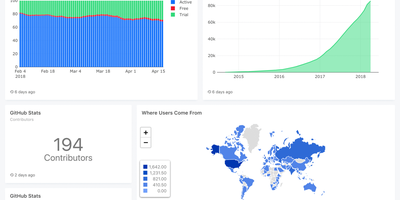
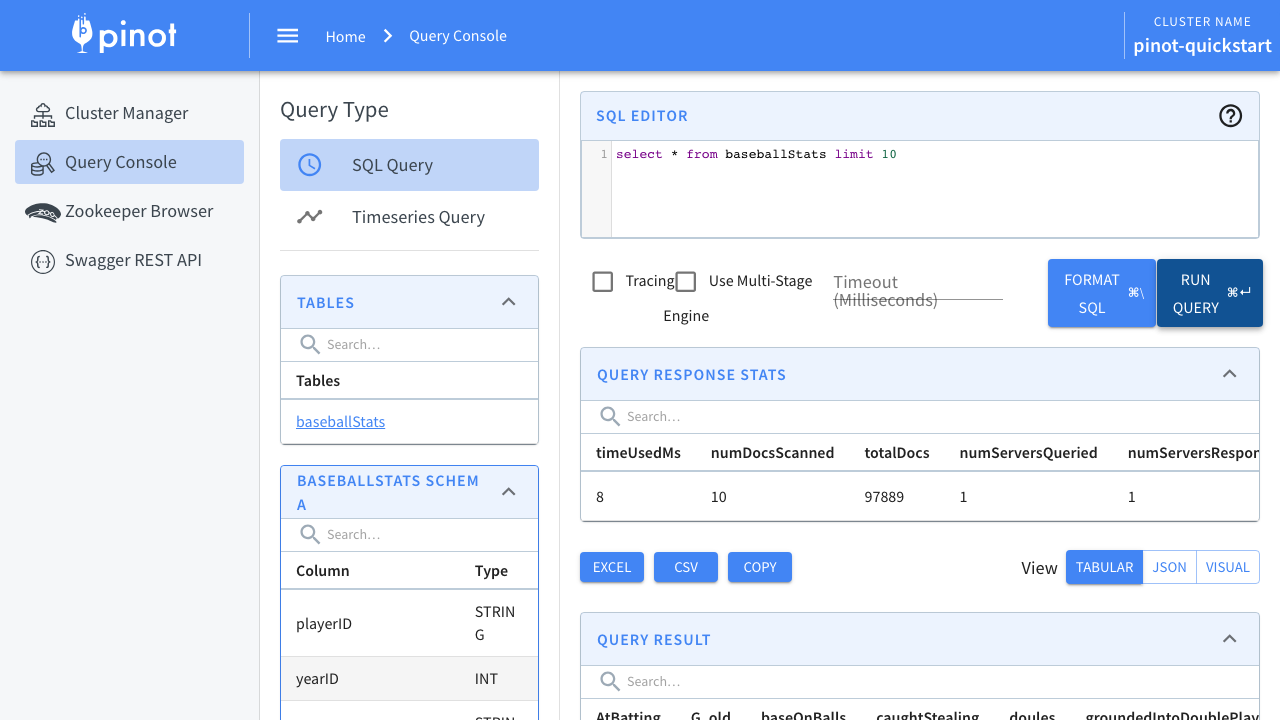
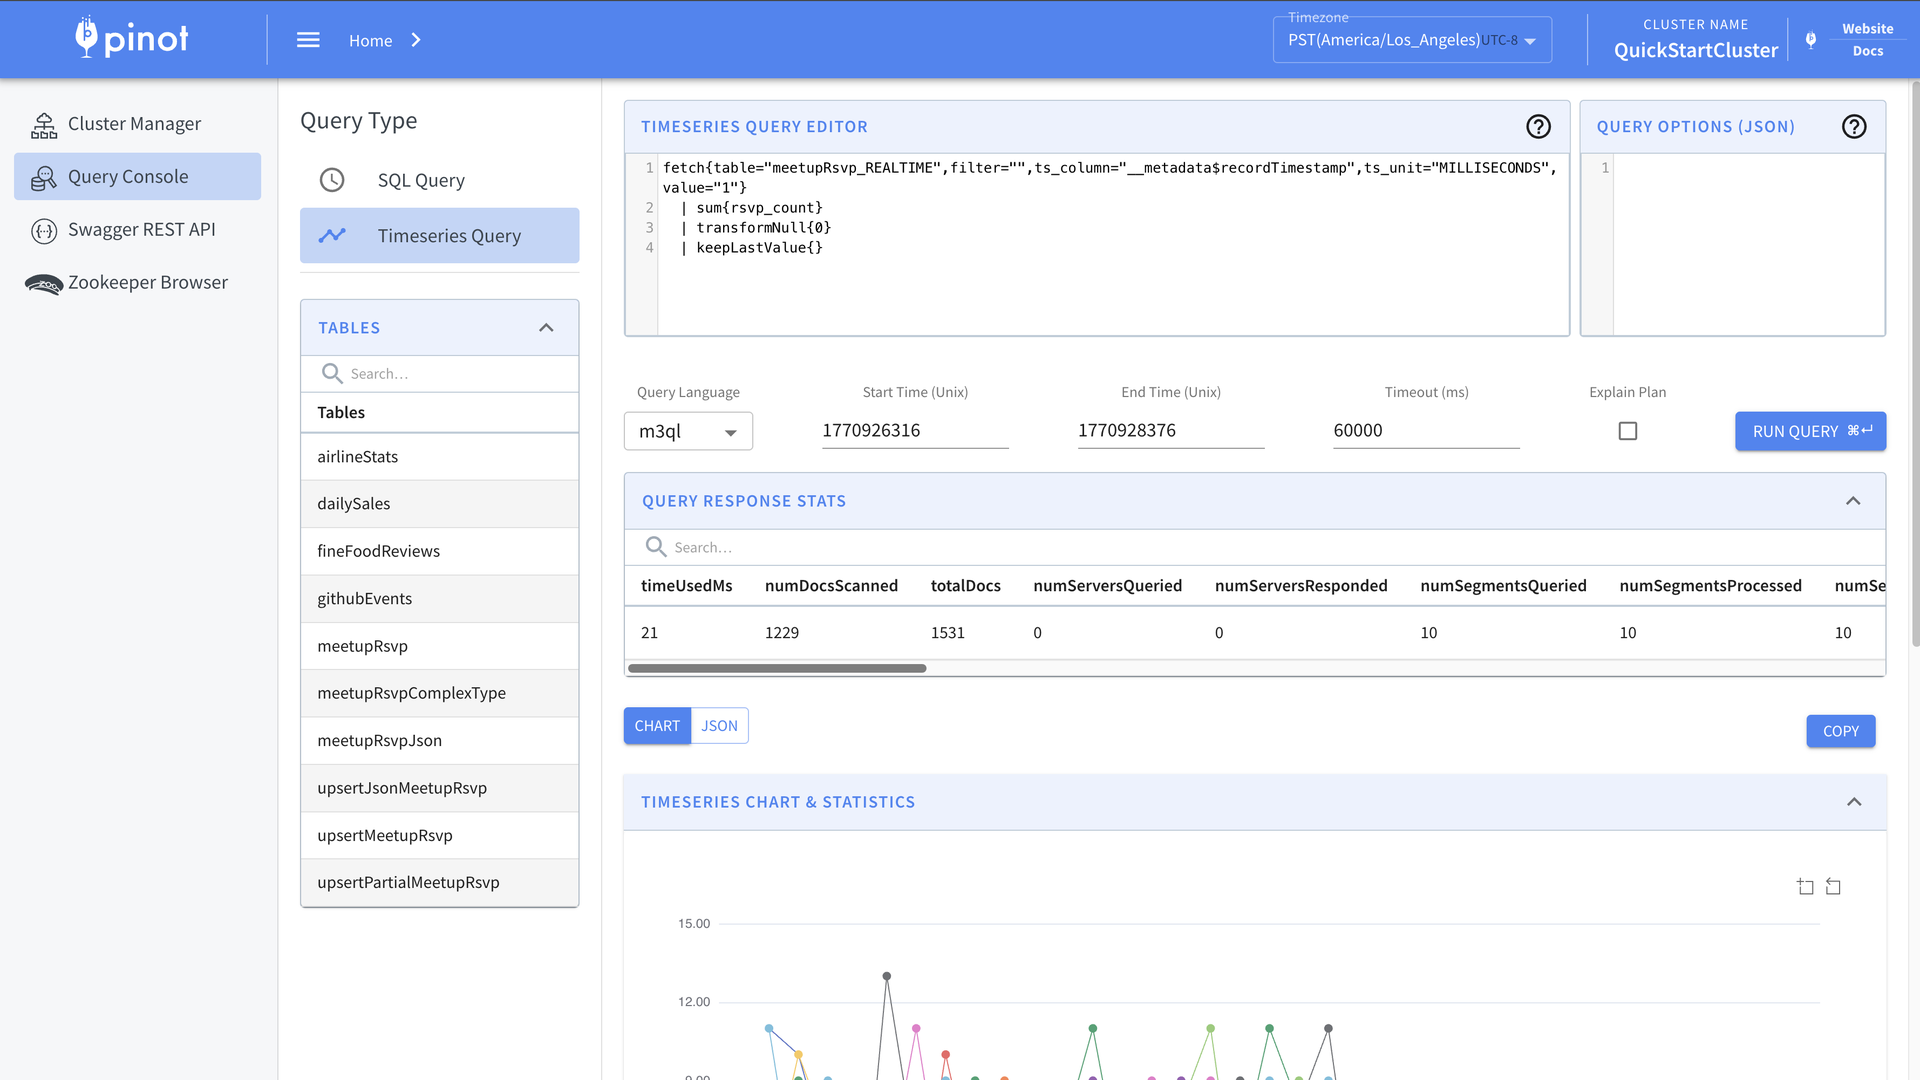
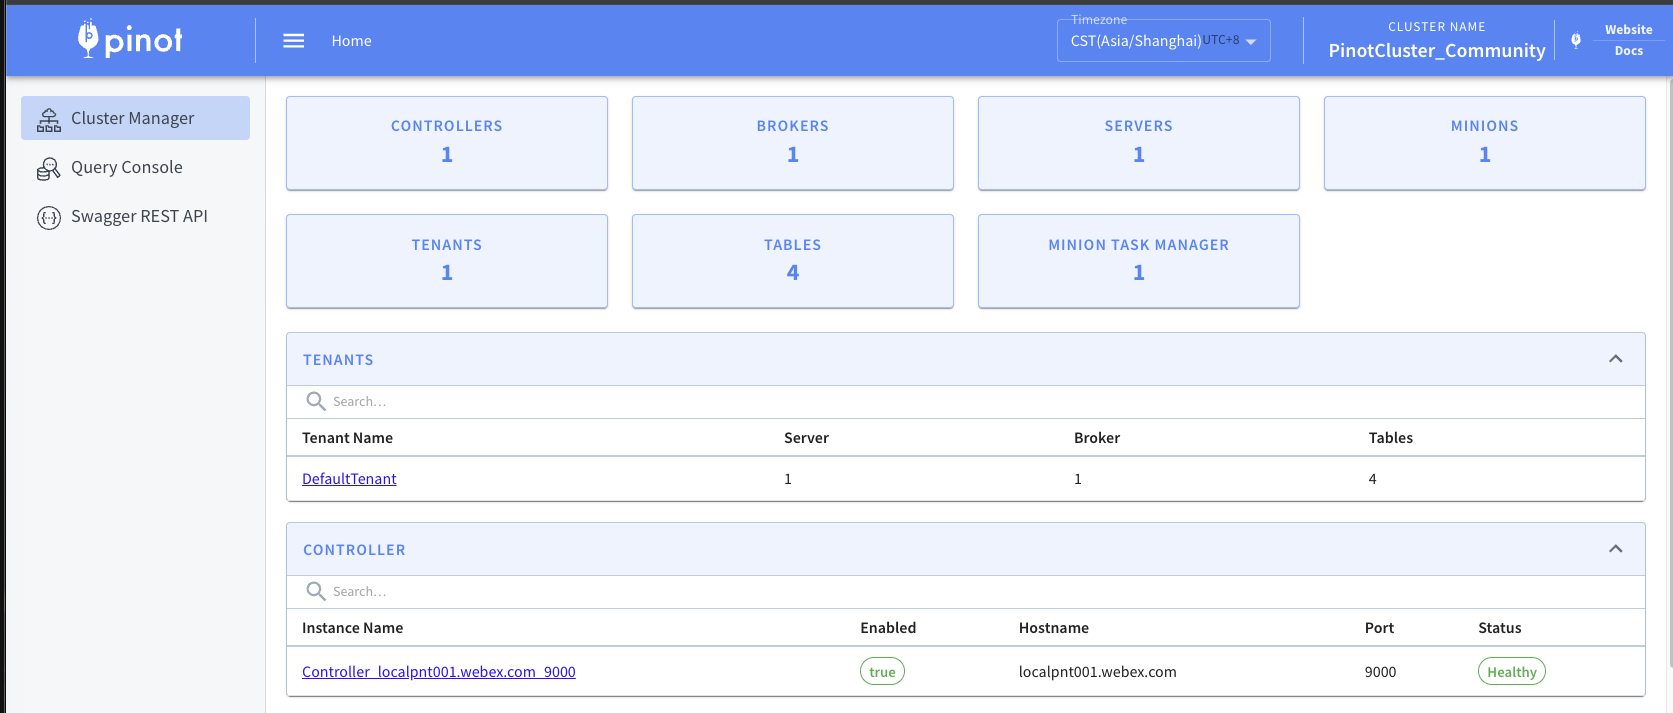
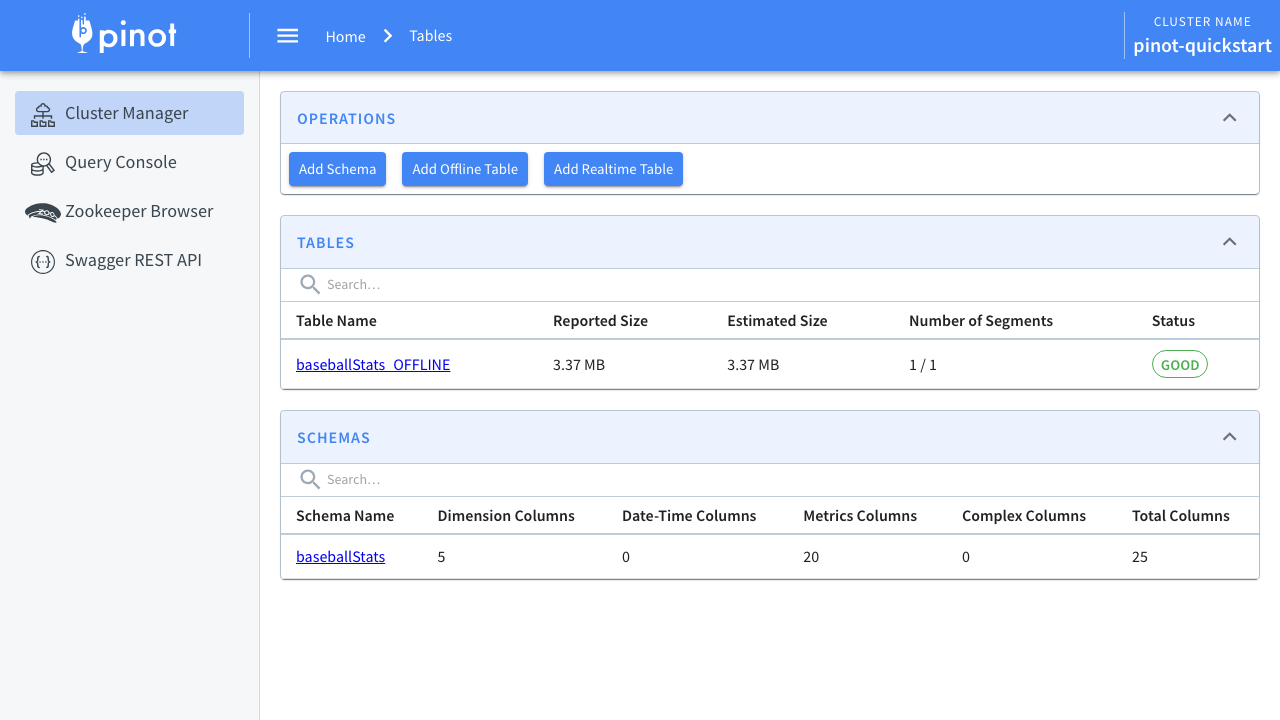
Teams that ship live dashboards, metrics APIs, or AI agents can query events from seconds ago in milliseconds with Apache Pinot, an open-source real-time analytics database. Streams from Kafka, Pulsar, or Kinesis and batch files from Hadoop, Spark, or S3 feed the same hybrid table, and upserts keep only the latest version of each record. Standard SQL runs in a built-in query console or through a REST API, and the multi-stage engine adds joins between large fact tables and dimension tables. Inverted, range, text, JSON, geospatial, Bloom filter, StarTree, and timestamp indexes keep filters and aggregations fast, while vector indexes support nearest-neighbor search over embeddings. Multitenancy isolates teams and customers, tiered storage separates hot and cold data, and optional minions merge and roll up segments in the background. The web Data Explorer lists tenants, tables, segments, and consuming partitions, lets you pause or resume real-time ingestion, and links to a Swagger page covering every controller endpoint. Typical uses include embedded customer analytics, leaderboards and usage meters, fraud and pricing signals, and fresh context for retrieval by AI agents. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- Millisecond Queries for Many Users
- Filters and aggregations over very large tables return in milliseconds, so product pages and customer dashboards can show live numbers to many users at once without precomputed reports.
- Fresh Data Without Nightly Jobs
- Events from Kafka, Pulsar, or Kinesis become queryable almost immediately, and batch loads from S3, Spark, or Hadoop join the same table, so results do not have to wait for an overnight pipeline.
- Self-Hosted With No Query Fees
- The Apache-2.0 licensed software carries no per-query, per-seat, or per-node charges, so costs track the VPS you choose and your analytics data stays inside your own infrastructure.
- One Backend for Agents and Dashboards
- Vector indexes and plain SQL let AI agents and retrieval pipelines pull fresh context from the same tables that power your dashboards, instead of from stale exported copies.
Features
- Streaming and Batch Ingestion
- Consume Kafka, Pulsar, and Kinesis streams, load batch files from Hadoop, Spark, or S3, and combine both sources in one hybrid table.
- SQL With Multi-Stage Joins
- Query with standard SQL in the built-in console or REST API, and join fact and dimension tables with the multi-stage engine, including lookup and colocated join strategies.
- Rich Index Types
- Add inverted, range, text, JSON, geospatial, Bloom filter, StarTree, timestamp, and vector indexes per column to speed up filters, aggregations, and similarity search.
- Upserts and Background Tasks
- Keep the latest version of each record with full or partial upserts, while optional minions merge, roll up, and optimize segments away from the query path.
- Multitenancy and Tiered Storage
- Isolate teams or customers in tenants, split data into hot and cold storage tiers, and restrict access with basic authentication.
- Built-In Data Explorer
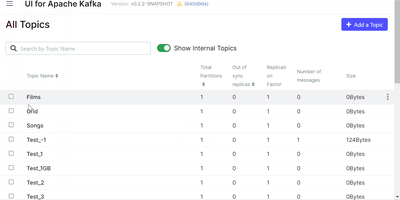
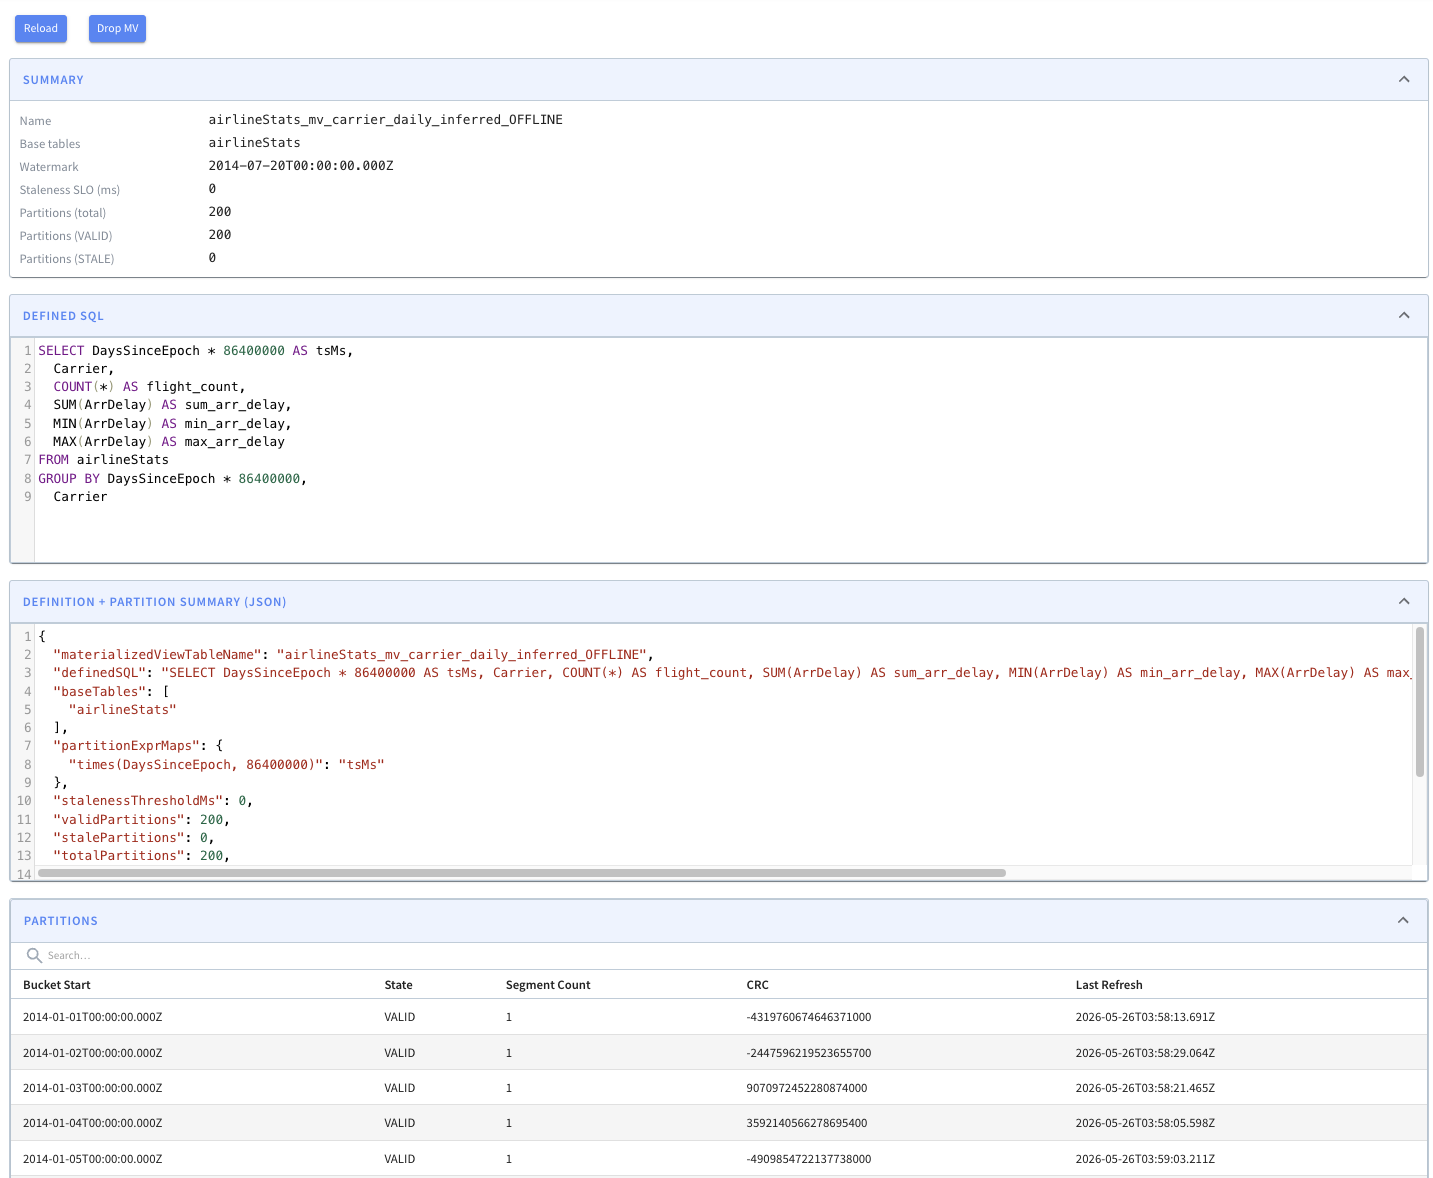
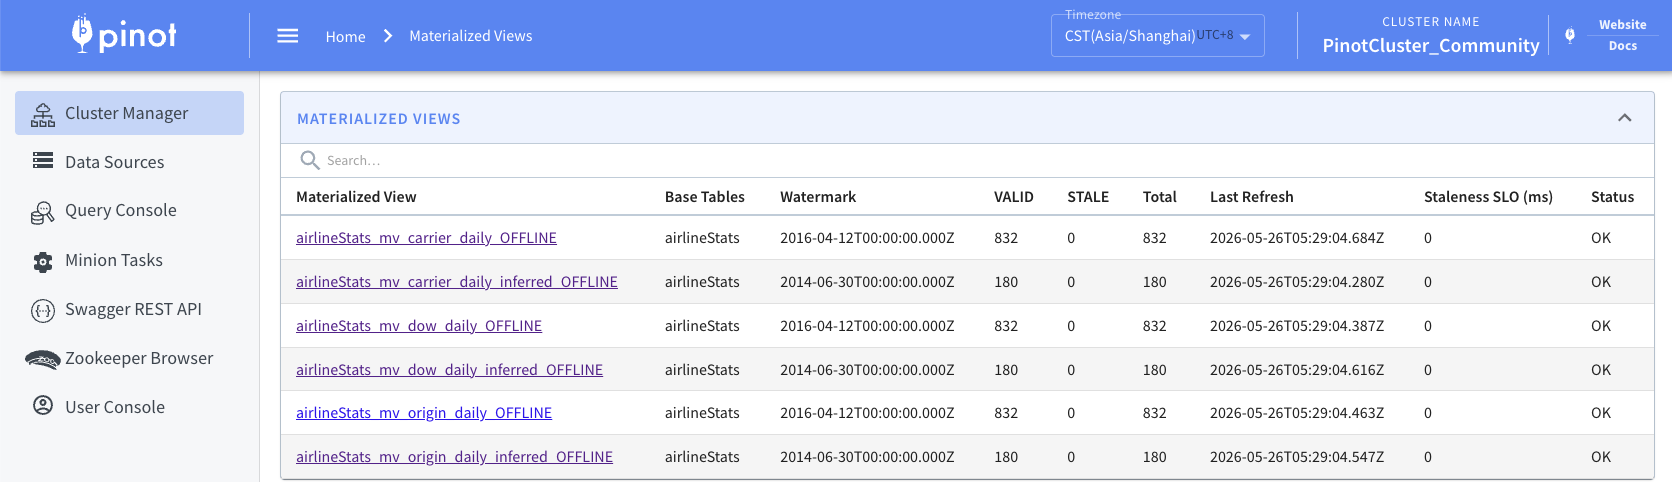
- Browse tenants, tables, segments, and minion tasks, run SQL, pause real-time ingestion, and try controller endpoints in Swagger, all from the web interface on port 9000.