Stars
Forks
Watchers
Developer links
MatrixOne
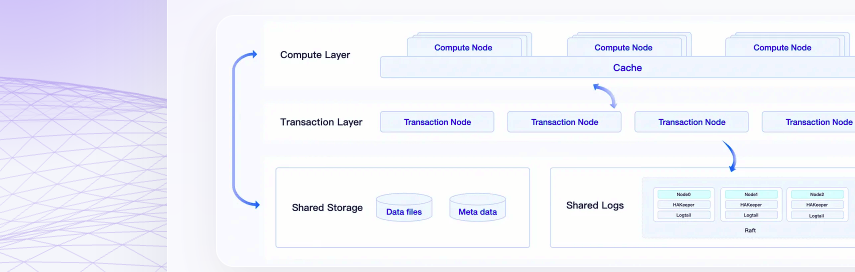
Transactions, analytics, full-text search, and vector retrieval stop needing four separate systems: MatrixOne folds them into one hyper-converged database engine that speaks the MySQL 8.0 wire protocol, so existing drivers, JDBC applications, Navicat, and BI tools connect unchanged. A single TAE storage engine serves OLTP and OLAP together, with compute and storage separated so query nodes scale independently of the data they scan. Vector columns carry IVF and HNSW indexes with L2, cosine, and inner-product distance, powering RAG and semantic search at billions scale beside your relational tables instead of in a sidecar database. Full-text indexing joins the same query, so hybrid searches combine keyword relevance and embedding similarity in one statement. Git-style version control for data lets teams clone, branch, and roll back datasets the way they already treat code, which makes experiments and audits reproducible. Streaming ingestion through Kafka connectors keeps analytical tables current, and the 4.2 line sharpens window-query performance, composite-index planning, and physical backup and restore that preserves table history. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- One Engine For Every Workload
- Run transactions, analytical queries, full-text search, and vector retrieval in a single database instead of stitching together four systems. Data stays in one place, in one copy, under one security model.
- MySQL Compatibility Throughout
- Connect with the MySQL 8.0 protocol, syntax, JDBC drivers, and familiar tools like Navicat and MySQL Workbench. BI platforms treat MatrixOne as MySQL, so dashboards migrate without rewiring data sources.
- Vector Search Built In
- Store embeddings in vector columns with IVF and HNSW indexes supporting L2, cosine, and inner-product operations. RAG applications query vectors and relational filters together in one SQL statement.
- Data Versioned Like Code
- Clone, branch, and roll back datasets with Git-style version control over your tables. Experiments, audits, and what-if analysis run against snapshots without copying production data by hand.
Features
- HTAP Single Engine
- The TAE storage engine serves transactional and analytical workloads together with compute-storage separation. Query capacity scales independently, so reporting never competes with checkout traffic for the same nodes.
- Hybrid Search Queries
- Combine full-text relevance with vector similarity and relational predicates in a single query. Semantic product search and RAG retrieval stop needing a separate search cluster.
- Streaming Ingestion
- Feed analytical tables continuously through Kafka connectors with dedicated stream syntax. Dashboards and models read current data instead of last night's batch export.
- Physical Backup and Restore
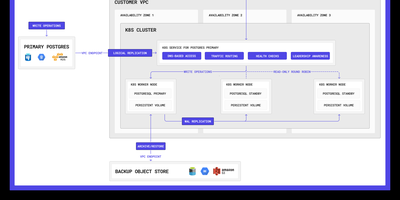
- Back up and restore the database with table-ID history and index objects preserved across the operation, hardened in the 4.2 line. Recovery brings back structure and history, not just rows.
- Python UDFs and SDKs
- Extend SQL with custom Python functions and drive vector indexes through a SQLAlchemy-based Python SDK. Application teams stay in familiar languages while the engine handles execution.