Categories
AI Agents Content Curation AI News Aggregation Digest Publishing Self-Hosted RSS News MonitoringStars
Forks
Watchers
Developer links
AIHOT
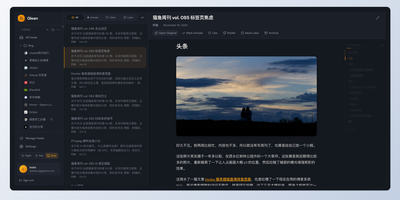
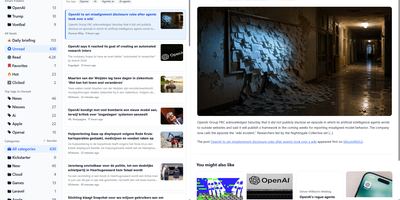
AIHOT is a self-hosted engine for running your own AI news site: it watches the sources you choose, scores every story twice, and publishes only the coverage worth reading. Point it at RSS feeds, web list pages, JSON APIs, X accounts, WeChat public accounts, or content pushed in by scripts, polled on schedules you control. After deduplication and pre-screening, every story faces two independent scoring passes under the same rubric, so one generous run cannot wave a weak story through. Coverage of the same story clusters into one event across the last two weeks, so forty outlets on one launch read as a single developing story. Hotness is measured per event: each source counts once per 48 hours and its weight halves daily, so repeat posting cannot inflate the ranking. Digests compile on schedule: a daily edition at 08:00, a weekly review on Mondays, and a monthly rollup on the first, assembled by rules without model calls. Readers browse topic pages by company, research direction, and content form, search titles, summaries, and full text, and keep local favorites with export and import. From the admin backend you can test sources, correct scores by hand, calibrate selection against labeled samples, and swap the model behind each pipeline step. Output flows through RSS, a public API, MCP, agent Markdown, and llms.txt, so humans and AI agents can subscribe. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.


Benefits
- Run Your Own News Station
- Swap in your industry sources and curation criteria to run a news site for law, finance, HR, or any beat. The framework ships with 18 demo sources so the site works out of the box.
- Twice-Scored, De-Duped Stories
- Every item passes deduplication, pre-screening, and two independent scoring runs under one rubric before selection. Tiered sources apply different thresholds, and you can label samples to calibrate selection with SelectBench.
- Events, Not Echo Chambers
- Reports about the same story cluster into a single event using vector similarity and text overlap, with model judgment separating follow-ups. Hotness counts independent sources, so loud repetition never outranks real breadth.
- Digests That Write Themselves
- Daily editions compile at 08:00 by rule with no model calls, weekly reviews land on Mondays, and monthly rollups follow on the first. Readers subscribe through RSS, a public API, MCP, or llms.txt.
Features
- Six Source Types
- Collect from RSS feeds, web list pages, JSON APIs, X accounts, WeChat public accounts, and script-pushed content, with three source tiers setting selection thresholds and polling frequency.
- Dual Scoring Pipeline
- Deduplication and pre-screening feed two independent scoring passes under one rubric, producing Chinese titles, answer-first summaries, recommendation reasons, and full translations of foreign articles.
- Event Clustering Engine
- Coverage merges into events using vector similarity over titles and summaries from the last two weeks, text-overlap fallback, and model judgment, with an optional separate review model.
- Per-Event Hotness Ranking
- Each event's heat counts every independent source once per 48 hours and decays by half every 24 hours, with X discussion included, so rankings reflect breadth of attention.
- Scheduled Digest Editions
- Daily reports compile at 08:00 by rule without model calls, weekly editions on Mondays and monthly rollups on the first add model-written overviews, with edition times configurable in site settings.
- Admin And Agent Outputs
- The admin backend manages sources with test fetch, diagnostics with manual score correction, and run records, while RSS, a public API, MCP, Markdown, and llms.txt serve agents.