Stars
Forks
Watchers
Developer links
LightRAG
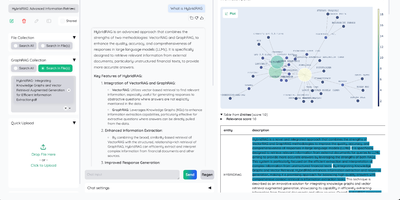
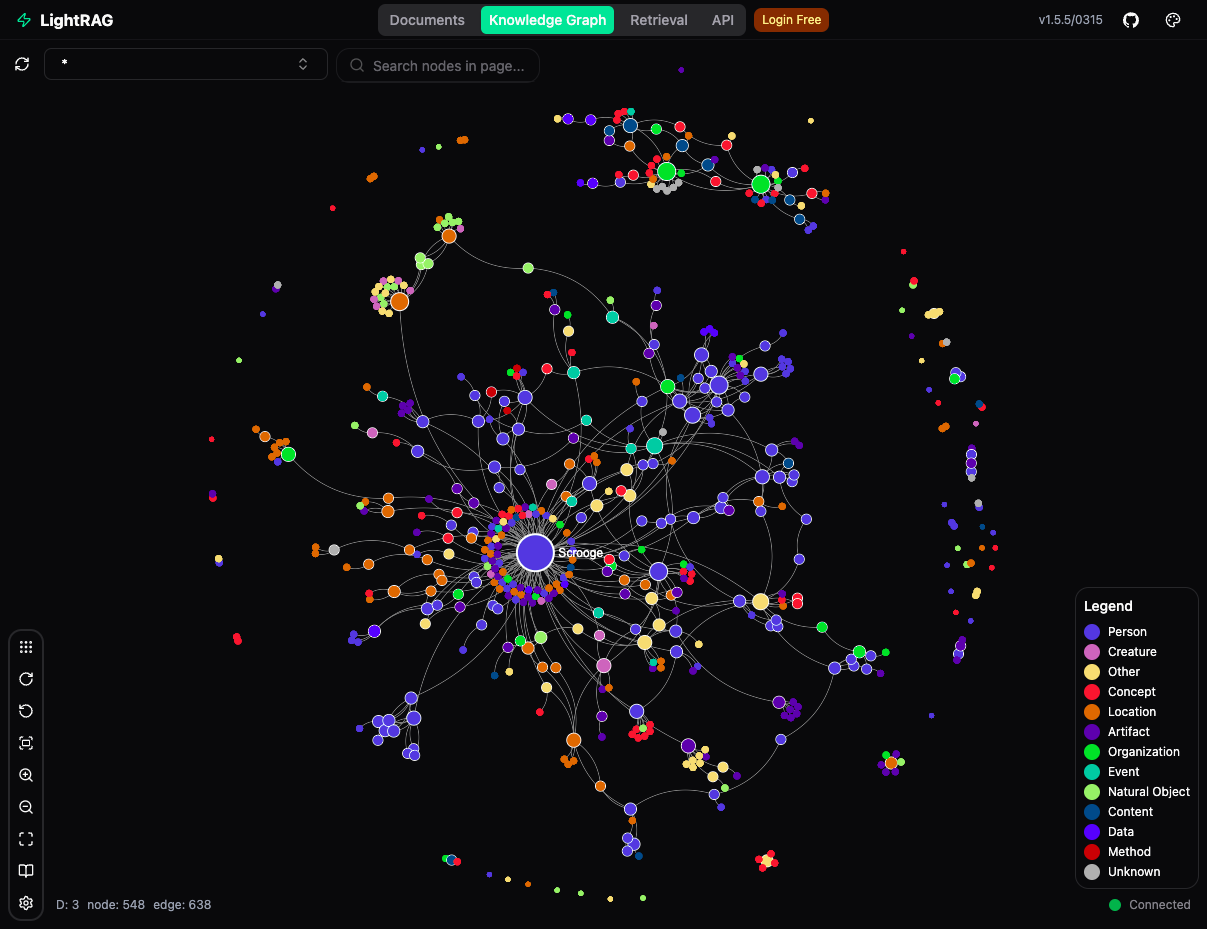
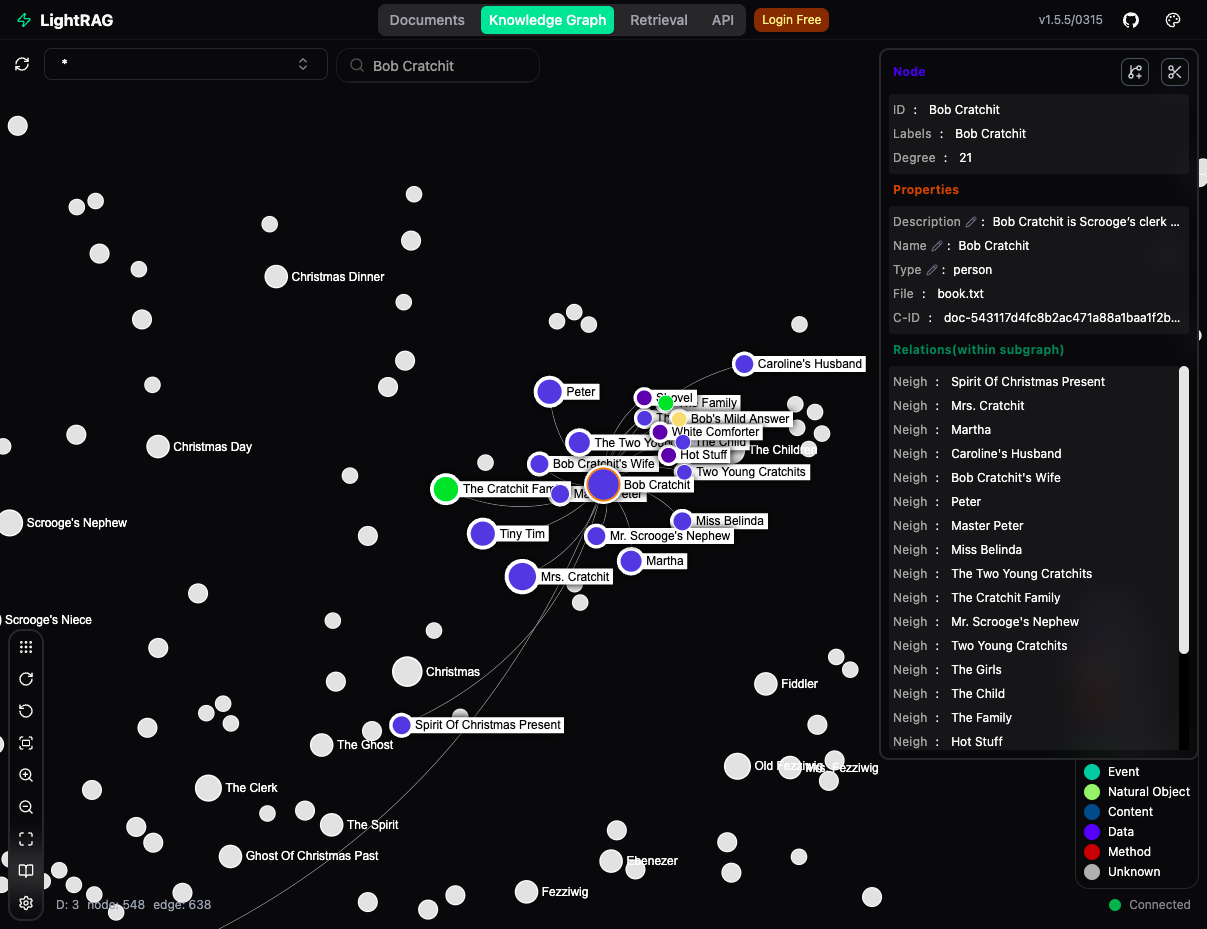
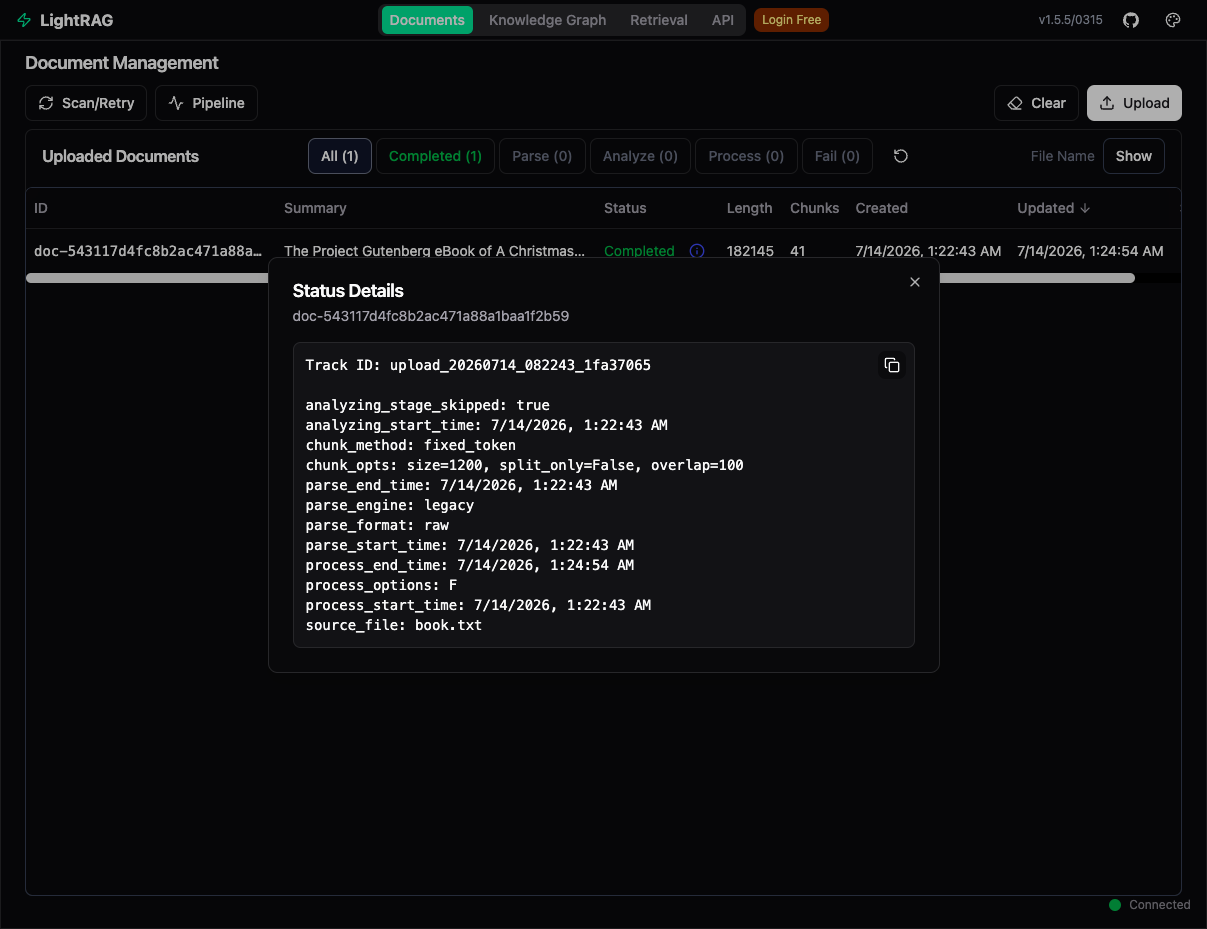
Plain chunk retrieval hands an LLM disconnected excerpts; LightRAG builds a knowledge graph from your documents so answers can join facts spread across many files. Ask about one named person, product, or clause and local mode pulls its details. Ask for themes across the whole library and global mode follows the links between entities. Hybrid blends the two, naive falls back to plain chunk search, and mix combines all three. Mix is the default. Upload text, Markdown, PDF, Word, PowerPoint, and Excel files; MinerU, Docling, or the native parser can extract images, tables, and formulas. The admin console manages documents, explores the graph visually, and debugs queries, while a query-only workspace page gives everyday colleagues a clean chat screen that works on phones. A REST API covers indexing and queries, and an Ollama-compatible endpoint lets chat front ends such as Open WebUI use the knowledge base as a model. New files merge into the existing graph without a full reindex, and deleting a document rebuilds only the entities and relationships it touched from cached results. Separate model roles let an inexpensive model extract entities while a stronger one writes answers. An API key or accounts protect the server, and named workspaces keep several knowledge bases apart. Pair it with local Ollama models and no document text leaves the server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Answers That Connect Many Documents
- Entities and relationships extracted from every file form a graph, so a global query can join facts spread across documents that plain chunk retrieval would return as disconnected excerpts.
- Update Without Reindexing Everything
- New files merge into the existing graph, and deleting a document rebuilds only the entities and relationships it touched, using cached extraction results instead of reprocessing the whole library.
- Right Model For Each Job
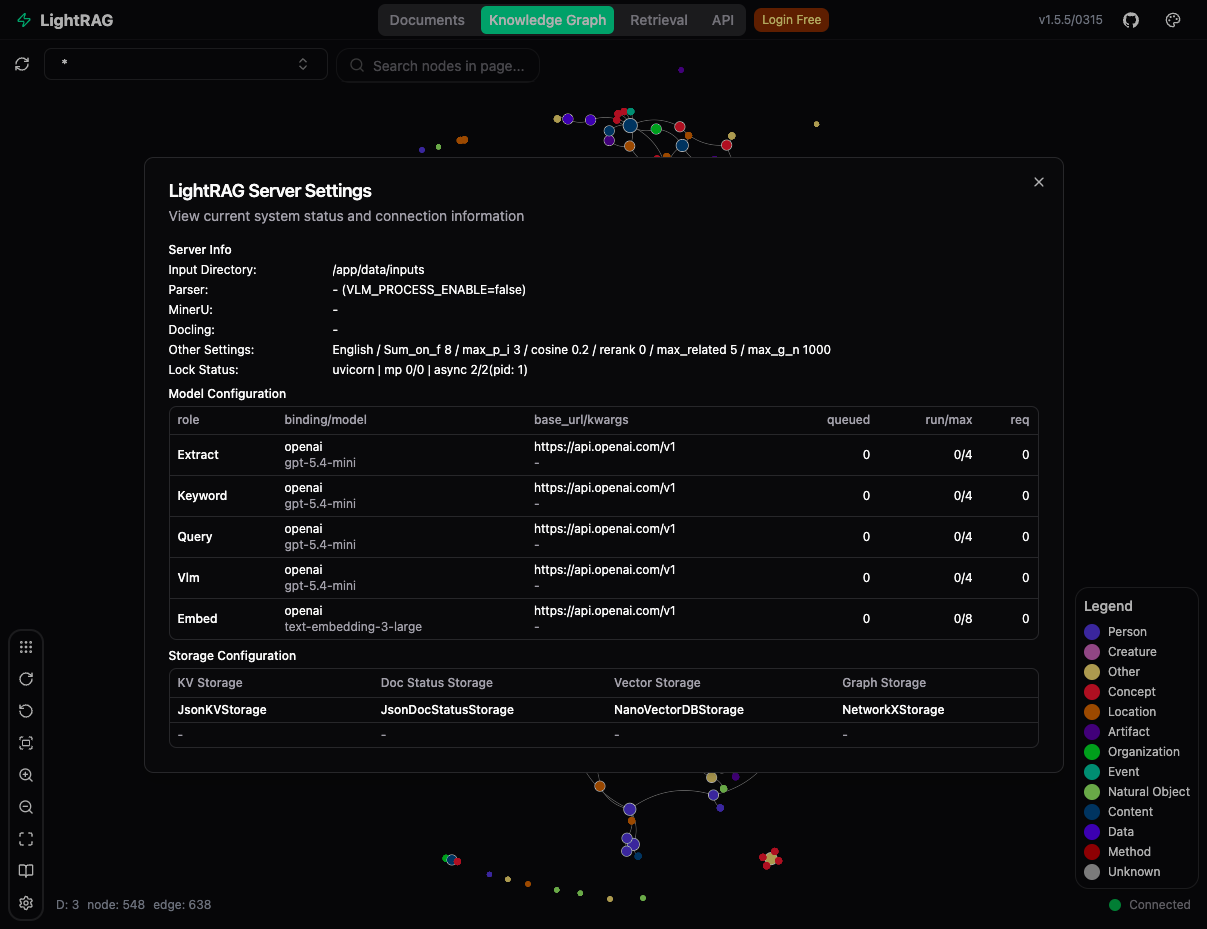
- Role-specific settings let a fast, inexpensive model handle entity extraction while a stronger one writes answers, and each role can use OpenAI-compatible, Ollama, Gemini, Azure OpenAI, or Bedrock endpoints.
- Knowledge Stays On Your Server
- Documents, graph, and vectors live in storage you control. Pair LightRAG with local Ollama models for both LLM and embeddings and no document text leaves the server.
Features
- Six Query Modes
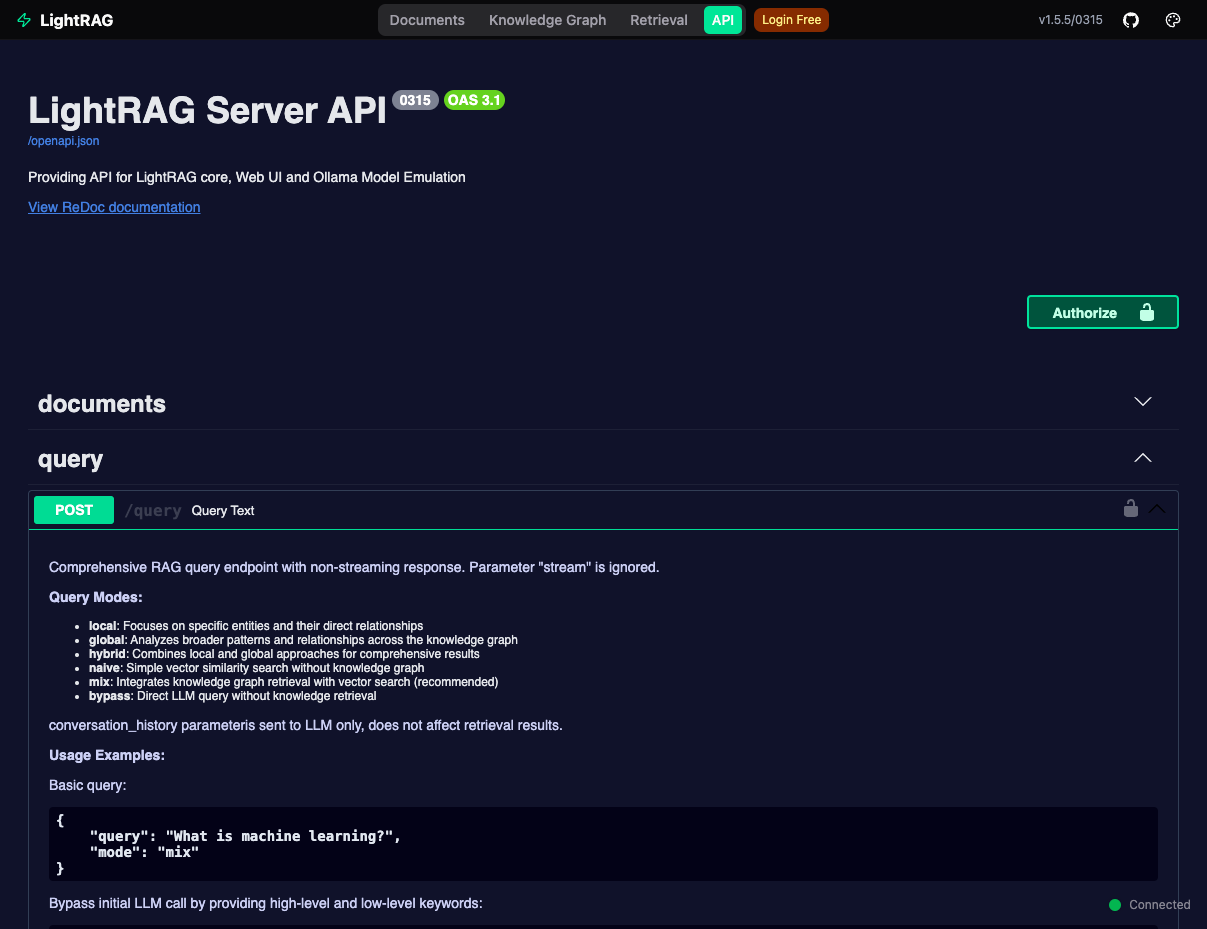
- Local, global, hybrid, naive, and mix modes retrieve from entities, relationships, or text chunks, and bypass skips retrieval; mix is the default, with an optional reranker for better ordering.
- Admin Console And Query Page
- The /webui console manages documents, explores the knowledge graph, and debugs queries, while /workspace is a mobile-friendly, query-only chat page for everyday users.
- Flexible Document Parsing
- Reads TXT, Markdown, PDF, Word, PowerPoint, and Excel files; MinerU, Docling, and a native parser extract images, tables, and formulas, with four chunking strategies available.
- REST And Ollama APIs
- A REST API handles indexing and queries, while an Ollama-compatible endpoint lets Open WebUI chat with the knowledge base as a model named lightrag:latest.
- Pluggable Storage Backends
- Local files by default; PostgreSQL can host all four stores, with MongoDB or OpenSearch as single-backend options, Milvus or Qdrant for vectors, and Neo4j or Memgraph for graphs.
- Authentication And Workspaces
- An API key or bcrypt-hashed accounts with JWT sessions protect the server, and named workspaces isolate multiple knowledge bases that share one storage backend.