Stars
Forks
Watchers
Developer links
XianScan
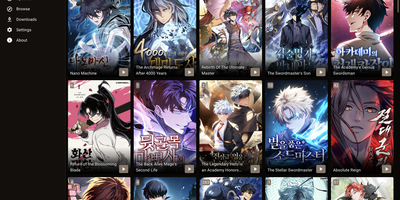
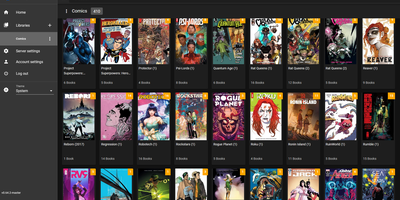
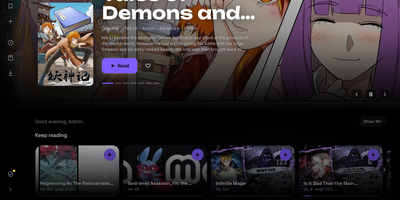
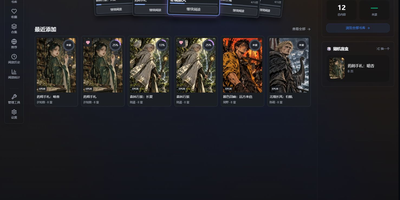
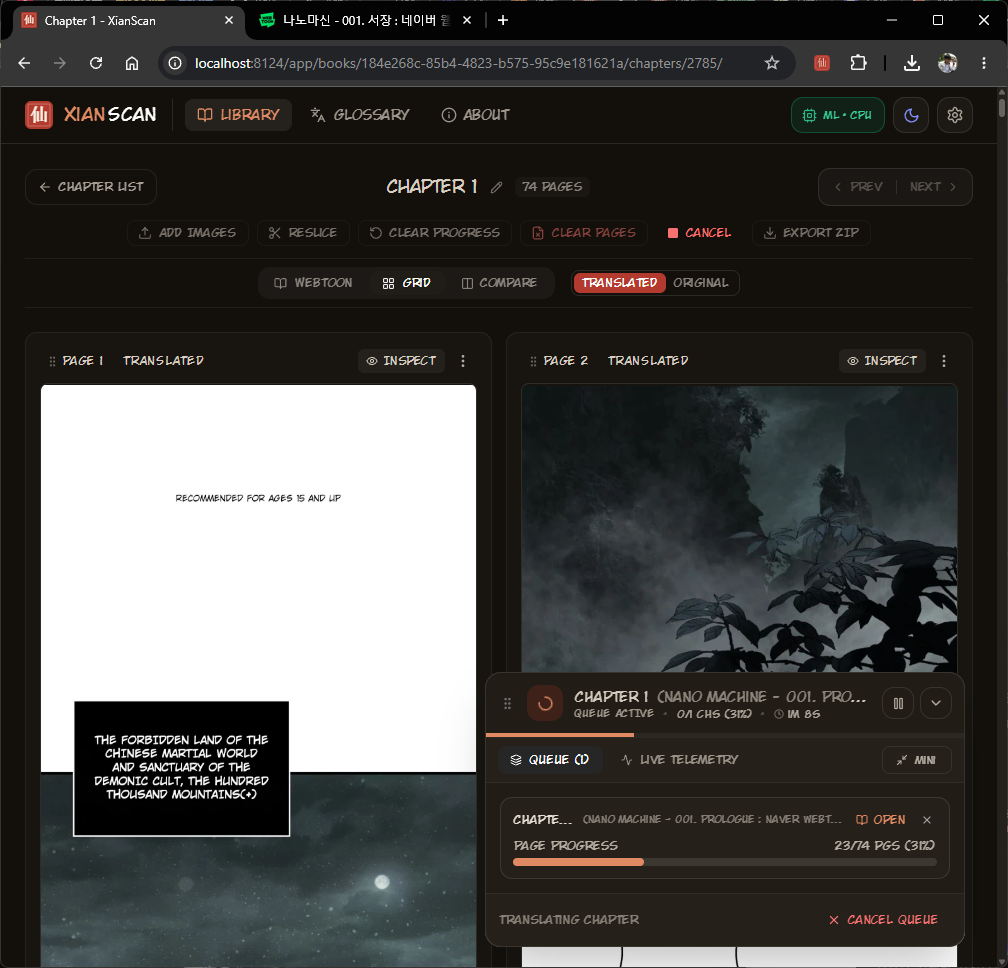
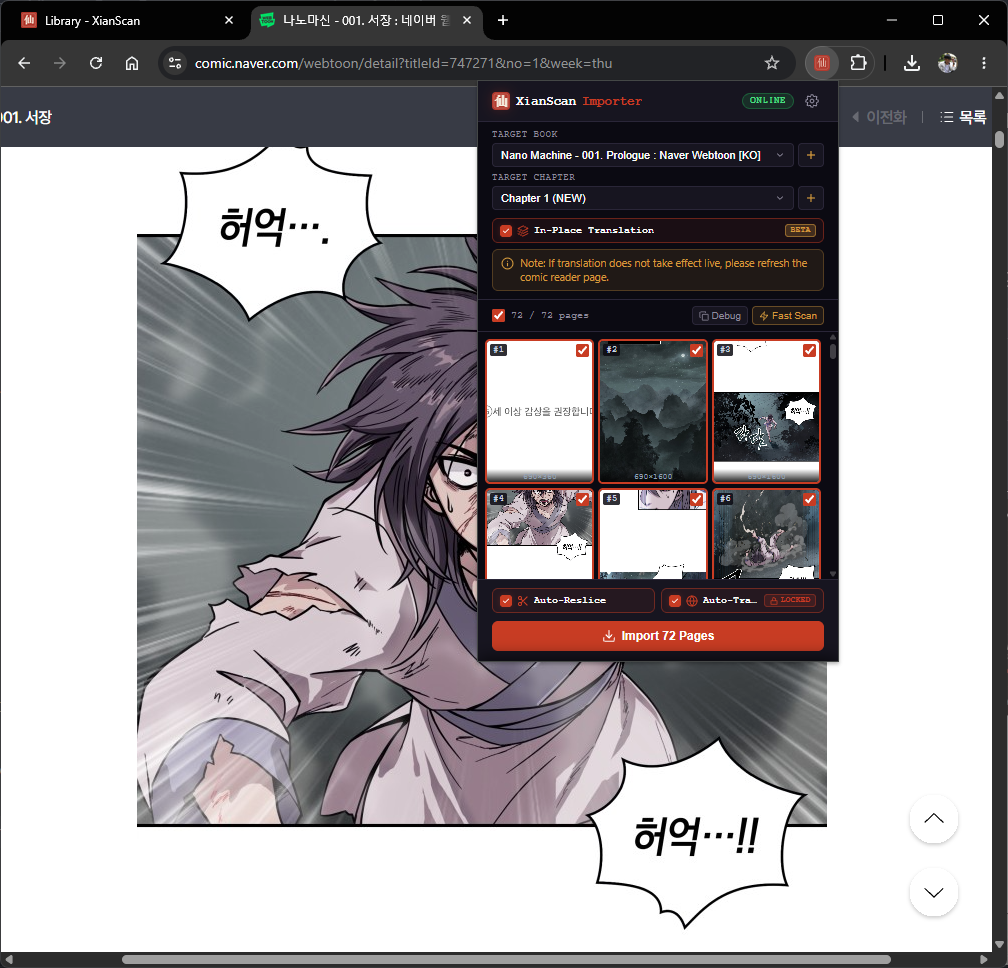
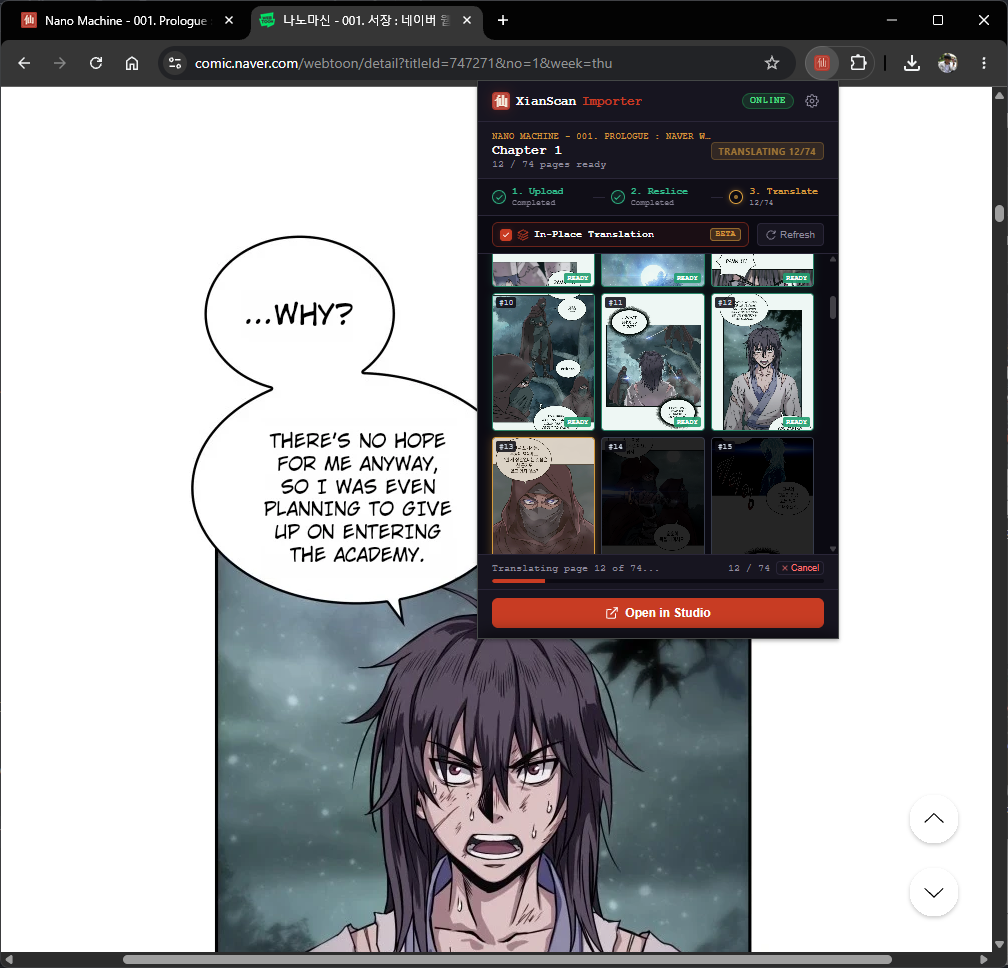
Reading a new manhwa chapter on release day usually means waiting for a scanlation group, or pasting panels into three tools yourself. XianScan collapses that whole relay into one server: point its browser extension at a chapter on a reader site and it captures every page, or drop raw pages into the studio and let the pipeline run. Speech bubbles, captions and sound effects are detected automatically, the text inside them is read by OCR supporting ten languages in vertical and horizontal layouts, and tall webtoon strips are resliced along natural panel gutters so no bubble is ever cut in half. Translation keeps a sliding memory of previous pages so speakers, pronouns and story topics stay consistent, while terminology glossaries lock character names and cultivation terms across an entire series. The original lettering is then removed by neural inpainting that rebuilds the artwork underneath, and the translation is typeset back into the bubbles with computed font sizes, line breaks and per-script fonts, including right-to-left scripts and accent fonts for attack names. Inspect OCR boxes and confidence scores, fix text before saving, then read in the web studio or stream chapters to the Mihon app on your phone. Local models through Ollama or LM Studio keep everything offline, or plug in Gemini, OpenAI, Groq or OpenRouter keys when you prefer the cloud. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Whole Pipeline, One Server
- Capture, bubble detection, OCR, translation, neural inpainting and typesetting run as one automated flow in a single self-contained binary with embedded ONNX models, replacing the screenshot, Photoshop and manual lettering relay entirely.
- Translations That Remember Context
- A sliding dialogue window over previous pages keeps speaker identity, pronouns and topic consistent across page turns, and Aho-Corasick glossaries enforce the same rendering of names and cultivation terms across chapters.
- CPU First, GPU When Available
- Multi-threaded SIMD inference with AVX2, AVX-512 and ARM NEON tuning runs on ordinary CPUs with no GPU required, and automatically uses DirectML, CoreML or CUDA acceleration when supported hardware is present.
- Read Anywhere On Your Network
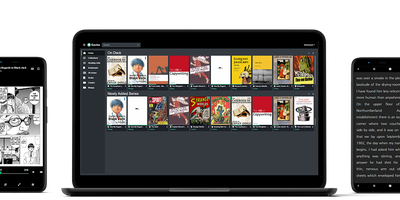
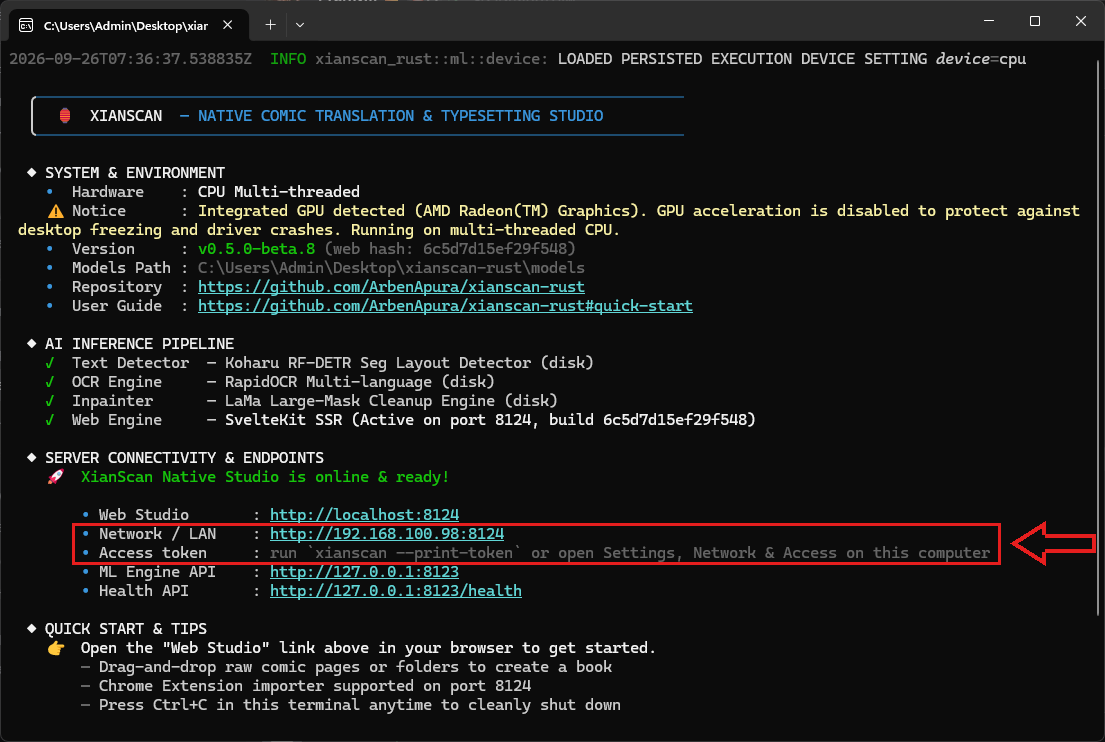
- Finished chapters stream to the Mihon and Tachiyomi extension on Android over local Wi-Fi, the web studio serves any browser on your network behind an access token, and a REST API exposes the engine.
Features
- One-Click Browser Importer
- The Chrome, Firefox and Edge extension captures full chapters from reader sites, handling lazy-loaded images and filtering ad containers, with in-place translation overlaying results on the page.
- Bubble And Text Detection
- The Koharu RF-DETR Seg 2XL model finds dialogue bubbles, captions, sound effects and panels; the OCR line detector reads each line across ten languages and both orientations.
- Neural Artwork Inpainting
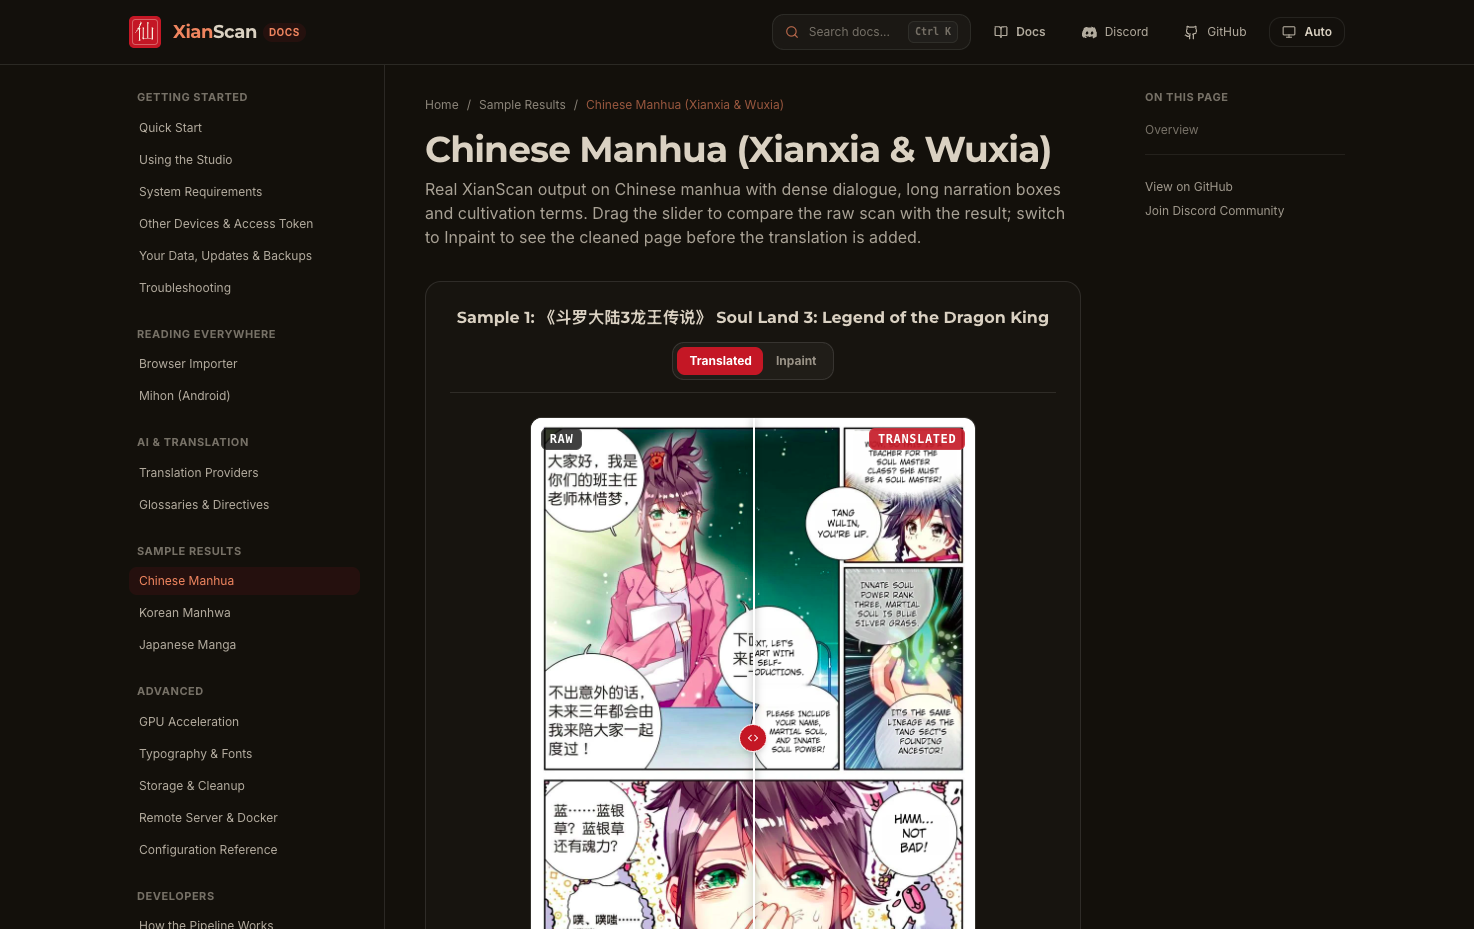
- The LaMa large-mask cleanup engine removes original lettering and reconstructs the underlying artwork, gradients and textures, with configurable edge padding so cleaned pages look untouched rather than smeared.
- Automatic Typesetting Studio
- Font sizing, line breaks, outline strokes and bubble tilt are computed per bubble, with per-script fonts for CJK, Hindi, Thai and Arabic, plus accent fonts for skills.
- Webtoon Gutter Reslicing
- Tall vertical strips are recombined and split along natural panel gutters before processing, and pages can be viewed in webtoon, grid or raw-versus-translated compare modes in the studio.
- Local Or Cloud Translation
- Connect Ollama or LM Studio running Qwen, Llama or Gemma for offline translation, or use Gemini, OpenAI, Groq and OpenRouter APIs; the ML engine runs on port 8123.