
Categories
Self-Hosted Productivity Artificial Intelligence Document Management OCR Bookmark Manager Personal Knowledge ManagementDeveloper links
Eclaire
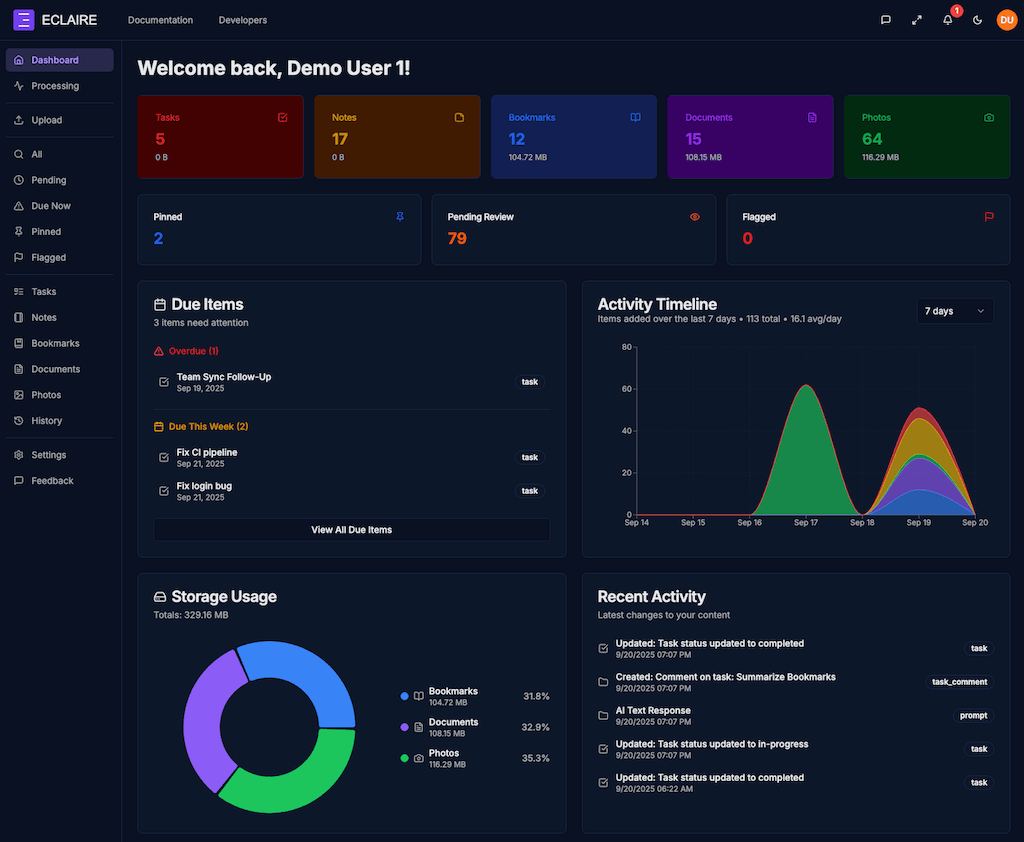
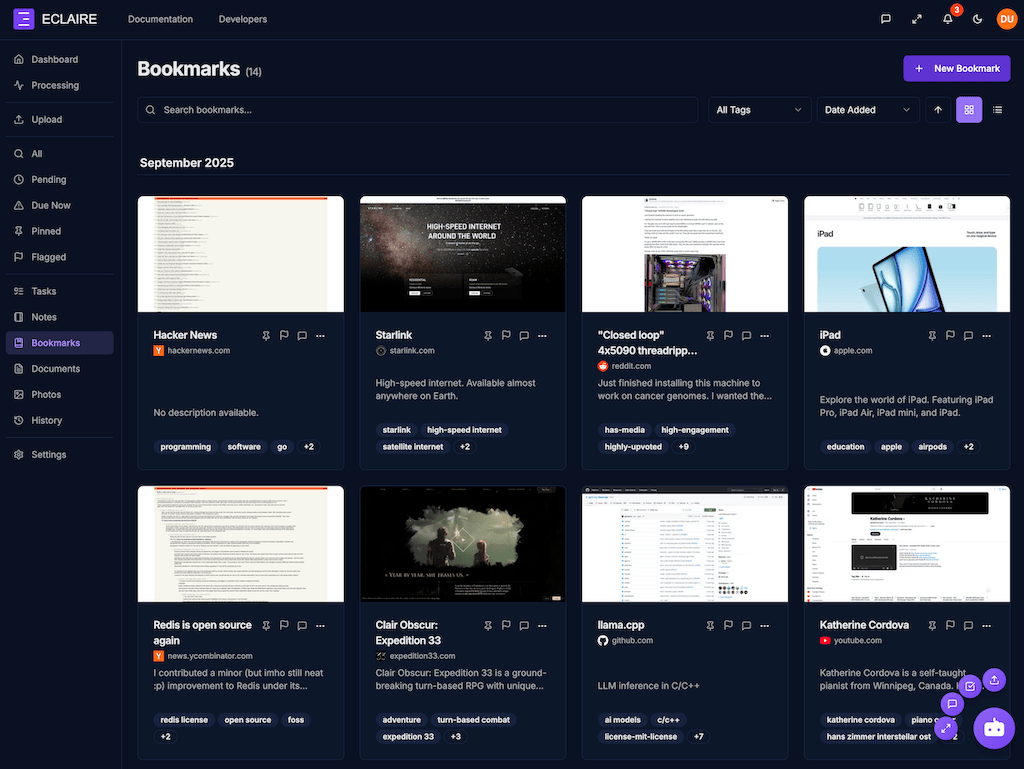
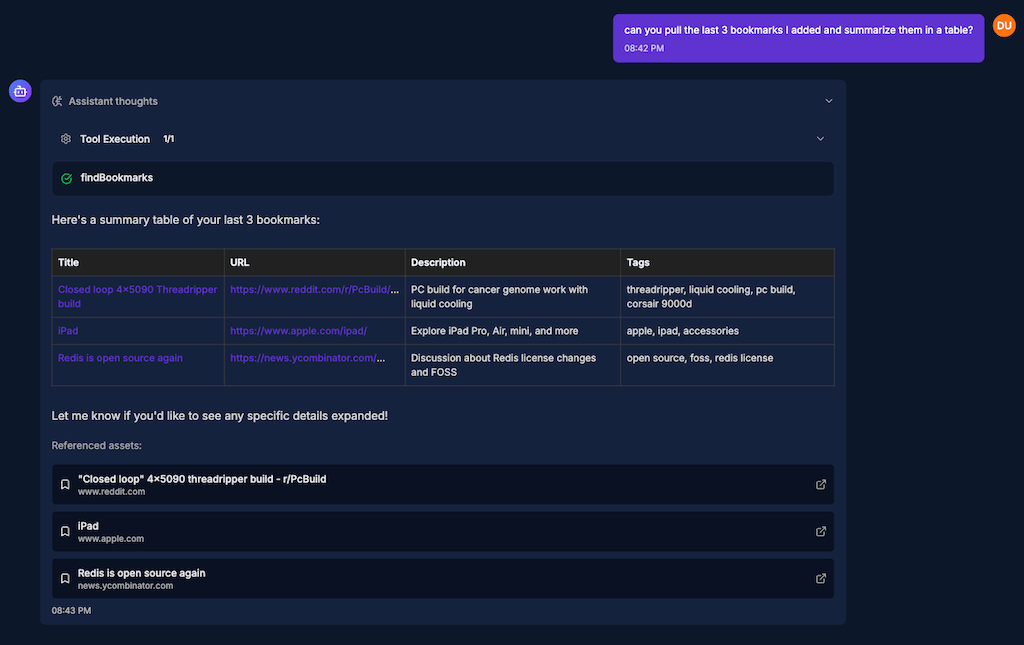
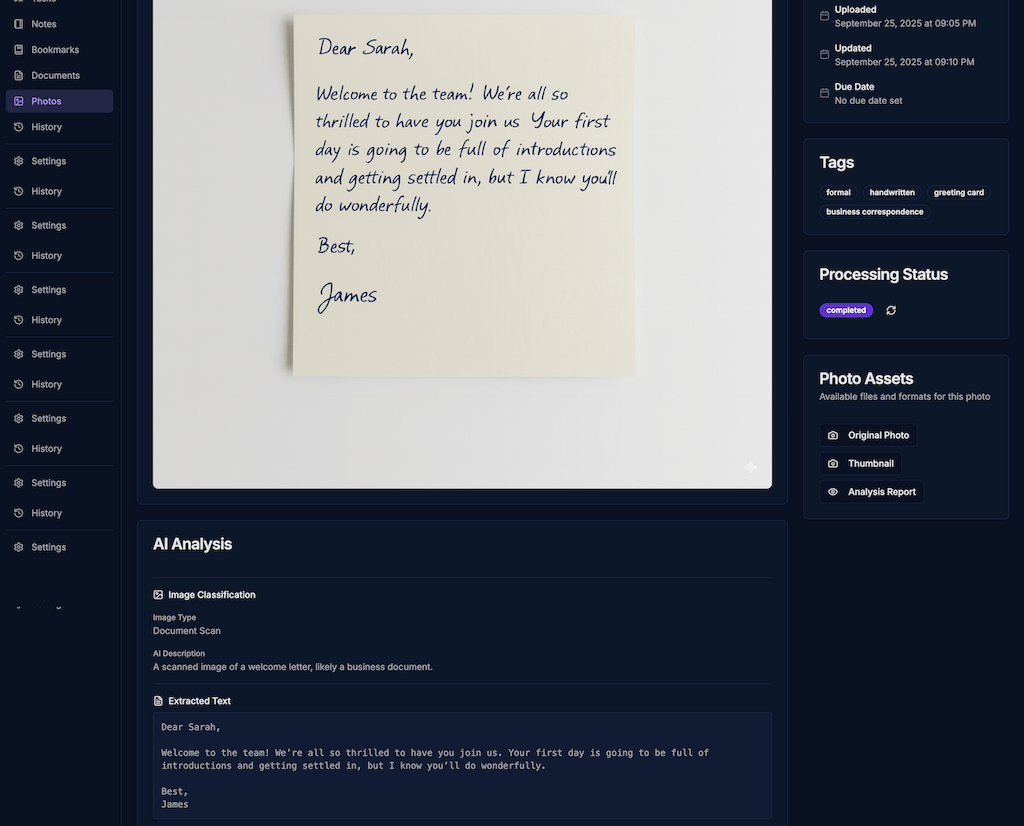
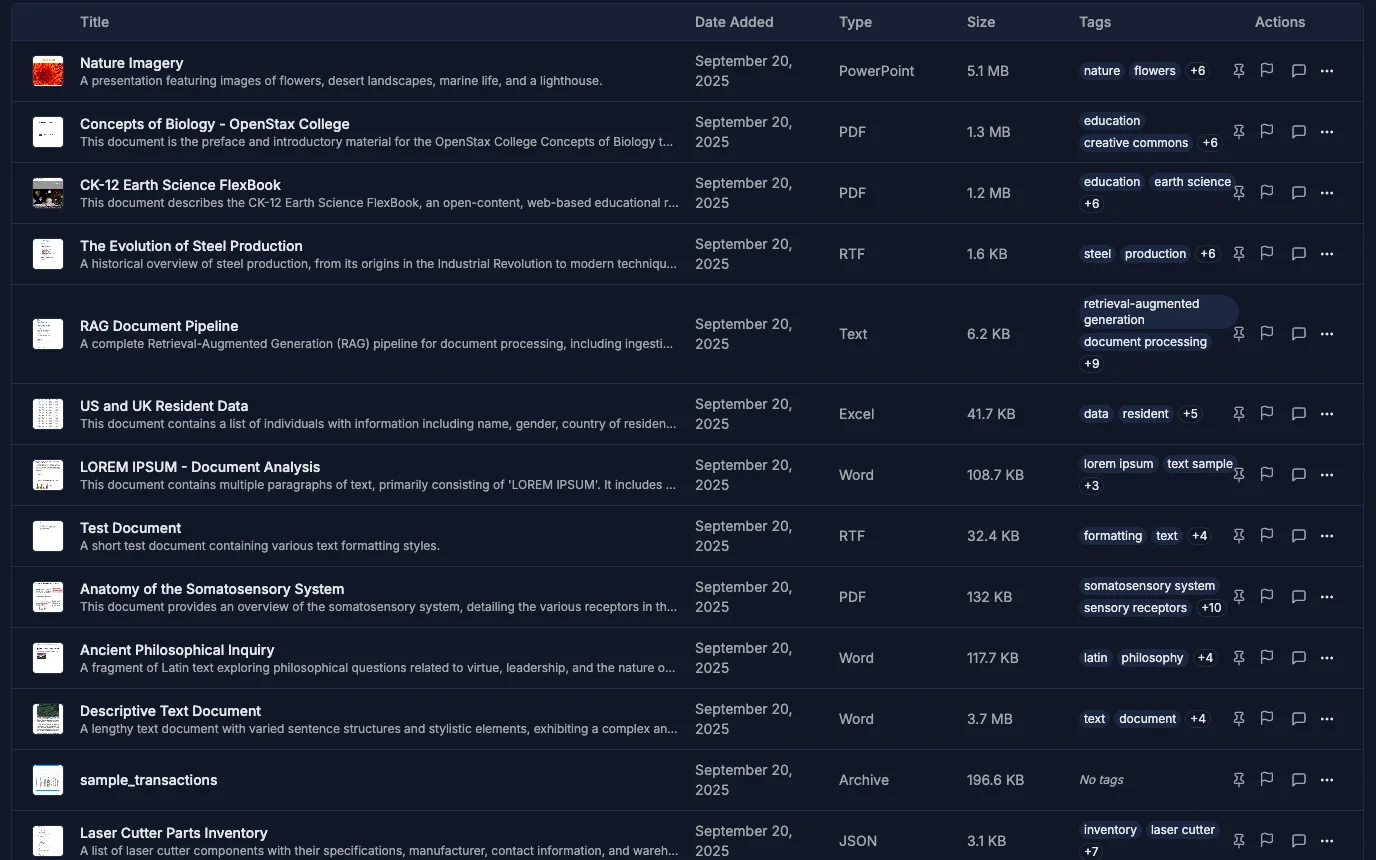
Built to consolidate fragmented digital life into a private personal cloud, Eclaire centralizes tasks, notes, documents, photos, and web bookmarks into a unified workspace powered by local artificial intelligence. Users can save web articles to generate clean Markdown copies and searchable PDF archives, automatically bypassing clutter and dead links. The integrated document ingestion engine extracts tabular data from spreadsheets, performs optical character recognition across uploaded receipts and handwritten images, and indexes multi-page PDF manuals for rapid full-text search. Conversational assistant panels allow operators to interrogate their accumulated library using natural language, asking for cross-document summaries, research timelines, or action items extracted from meeting transcripts. Background workers prioritize asynchronous indexing queues, categorizing image libraries with visual object tags and managing recurring task deadlines with automated Telegram alert notifications. External automation flows can interact directly with the unified storage layer via an OpenAI-compatible REST API, allowing mobile shortcuts and custom scripts to ingest bookmarks and dictate notes remotely. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Private Local Knowledge Ingestion
- Process confidential records, scans, and notes directly on your own infrastructure using local llama.cpp or MLX inference models without transmitting proprietary data to external cloud providers.
- Unified Multi Format Asset Hub
- Consolidate web bookmarks, office spreadsheets, presentations, PDFs, and high-resolution photos into a single searchable database backed by PostgreSQL or SQLite with automated format conversions.
- Automated OCR and Visual Tagging
- Extract text from photos and image receipts automatically using vision language models and Poppler utilities, generating searchable transcripts and topical metadata tags for every snapshot.
- OpenAI Compatible Developer API
- Trigger background extractions, query accumulated documents, and ingest remote links from Apple Shortcuts or custom automation scripts through standard REST endpoints and persistent API keys.
Features
- Web Archival and Reader
- Scrapes bookmarked web pages to produce sanitized readability text, downloadable PDF snapshots, and LLM-friendly Markdown versions using Playwright and background Node.js queues.
- Multi Modal Document Extraction
- Parses complex documents including DOCX, XLSX, PPTX, and PDF formats using Docling and LibreOffice integrations for structured table extraction and full-text search indexing.
- Conversational Research Assistant
- Interrogate accumulated assets using streaming chat interfaces built with React 19 and TanStack Router, providing citations and clickable link previews for referenced documents.
- Asynchronous Background Processing
- Dispatches CPU-heavy OCR, image conversion, and embedding generation tasks across dedicated background worker queues backed by database tables or Redis message brokers.
- Omni Channel Notification Relay
- Delivers task reminders, due date alerts, and conversational assistant responses directly to Telegram bots, allowing users to interact with personal data remotely.