Onyx
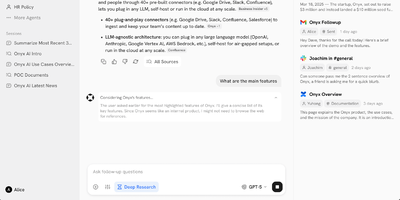
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
AnythingLLM
Chat with your own documents: AnythingLLM, from Mintplex Labs, wraps retrieval-augmented generation (RAG) in an open-source application anyone can run. You organize content into workspaces, each an isolated namespace with its own documents, vector embeddings, chat history, and settings, so one instance can hold several separate knowledge bases. Upload PDFs, DOCX, TXT, and other formats, or scrape web pages; the built-in collector parses and chunks them into a vector database (LanceDB by default, with Pinecone, Chroma, Qdrant, and others supported). Answers cite their source documents. It works with both cloud LLMs (OpenAI, Anthropic, Gemini) and local ones via Ollama or LM Studio, and the embedding model is separately configurable. Beyond RAG chat, it includes AI agents that can browse the web and run tools, an embeddable chat widget for your website, a developer API, and multi-user mode with admin, manager, and default roles plus per-workspace access control. Context assembly is smarter than naive RAG: pinned documents, attached files, vector search hits, and recent chat history are combined under a token budget so the model's context window is filled efficiently, and each workspace supports multiple independent conversation threads against the same knowledge base. Because the embedding model, vector store, and chat LLM are all independently swappable, you can move between providers without re-ingesting a single document. The stack is Node.js with a React frontend, MIT-licensed.
SurrealDB
With 32,800 GitHub stars, 180 contributors, and version 3.2 shipping in July 2026, SurrealDB eliminates the database zoo by unifying document, graph, relational, time-series, geospatial, and key-value data models into a single Rust binary queried through SurrealQL — an intuitive SQL-like language that handles graph traversals, record links, subqueries, and computed fields without switching between multiple database engines. Purpose-built for AI applications, it integrates vector indexing, full-text search, and hybrid retrieval that blends semantic similarity with graph and relational intelligence for context-aware RAG pipelines and recommendation engines. Real-time subscriptions and event-driven triggers push live data changes to connected clients without requiring external message brokers like Kafka. Multi-row, multi-table ACID transactions guarantee consistency while incrementally computed views deliver pre-calculated analytics without batch processing. Role-based access control with record-level permissions, JWT authentication, and multi-tenant isolation enables backend-as-a-service usage where client applications connect directly with fine-grained security. SDKs for JavaScript, Python, Go, Rust, .NET, and Java connect via WebSocket or HTTP APIs. Storage and compute separation allows deployment as an embedded library, a single-node server, or a highly-scalable distributed cluster with TiKV or FoundationDB backends. Deploy via Docker with persistent volumes on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Source-available licensed.
OpenSearch
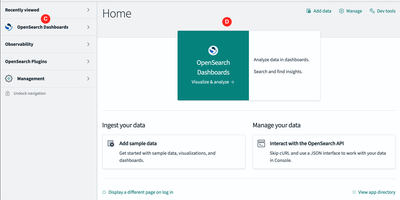
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
SearXNG
Up to 280 search services - Google, Bing, DuckDuckGo, Brave, Qwant, Startpage - aggregated without tracking or profiling: SearXNG is a privacy-respecting metasearch engine (AGPL-3.0, successor to Searx). Your instance queries the upstream engines on your behalf: your IP address, cookies, and search history never reach them, tracker parameters are stripped from result URLs, and an optional image proxy fetches thumbnails server-side so result pages leak nothing. It can even route outbound queries through Tor for full anonymity. Search is organized into categories - general, images, videos, news, maps, music, IT, science, files - with bang shortcuts for targeting specific engines, and every source can be enabled, disabled, or weighted per category in settings.yml. A plugin system adds calculators, hash tools, tracker removal, and unit conversions inline, and preferences (themes, safe search, languages, engine selection) persist in cookies rather than server-side accounts. The real argument for running your own instance rather than trusting a public one is control: you decide the logging policy (none), the engine mix, rate limiting, and who gets access - making it the default search backend for browsers, families, and teams that want Google-quality results without the profile.
Kotaemon
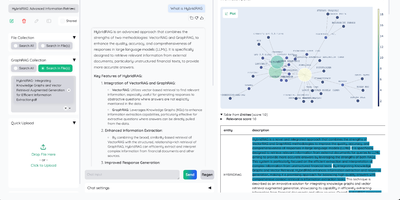
Kotaemon is a document QA platform that combines advanced RAG techniques with a clean Gradio-based web interface for chatting with your documents. Built by Cinnamon, the Python backend supports any LLM provider including OpenAI, Azure OpenAI, Cohere, Groq, and local models via Ollama and llama-cpp-python, with a model management panel for configuring LLM and embedding providers from the UI. The default hybrid RAG pipeline combines full-text keyword retrieval with vector similarity search and applies re-ranking to ensure optimal result quality, while multi-modal document parsing extracts content from tables and figures alongside text. Advanced citations link every answer to specific source passages with relevance scores, viewable directly in the built-in PDF viewer with highlighted text spans. GraphRAG indexing via NanoGraphRAG, LightRAG, or Microsoft GraphRAG builds knowledge graphs from document collections for relationship-aware retrieval. Agent-based reasoning supports question decomposition for multi-hop queries using ReAct and ReWOO strategies. Multi-user authentication organizes documents into private and public collections with sharing and collaboration features. The platform supports Docker deployment in lite, full, and Ollama-bundled variants, runs on port 7860, and stores application data in a persistent volume. MCP tool integration enables external system connections for extended retrieval capabilities. On RepoCloud, deploy Kotaemon on a dedicated VPS with Docker, root SSH access, and complete control over your document AI infrastructure, all under the Apache 2.0 license.
Valkey
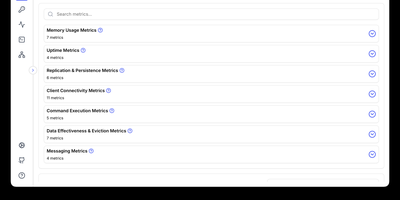
With 26,600 GitHub stars, 50 contributing companies including AWS, Google Cloud, Oracle, and Ericsson, and governance under the Linux Foundation ensuring the BSD 3-Clause license can never be revoked by a single entity, Valkey delivers a truly open-source Redis-compatible key-value datastore that reached 1.19 million requests per second in version 8.0 through redesigned asynchronous I/O threading across CPU cores while maintaining single-threaded data structure operations for predictability. Native data structures include strings, hashes, lists, sets, sorted sets, bitmaps, HyperLogLogs, streams, and geo-spatial indices with JSON support through modules. Valkey 9.0 shipped full-text search and aggregation via Valkey Search, enabling tag queries, numeric filtering, and text matching directly within the datastore without external search engines. Cluster mode provides horizontal scaling with automatic sharding, replication for high availability, and per-slot metrics for granular monitoring. Lua scripting enables complex atomic operations, while the module plugin system extends the server with custom commands and data types including probabilistic Bloom filters. Client libraries for Python, Java, Go, Node.js, and PHP maintain full Redis OSS protocol compatibility — existing Redis applications work without code changes. Deploy as a standalone daemon or in clustered mode with Docker, supporting persistent and ephemeral workloads on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
Hoarder
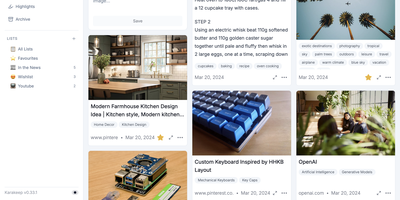
Hoarder (now Karakeep) is a bookmark manager that actually fights link rot: every page you save gets archived at capture time using Monolith, so the content survives even when the original URL dies. Beyond archival, an AI layer powered by OpenAI or local Ollama models auto-tags everything by analyzing page content. Prefer full privacy? Ollama keeps all inference on your server with zero external API calls. Full-text search through Meilisearch indexes the actual scraped content of every bookmark, not just titles and tags, so you find articles by what they say rather than labels you half-remember. Save links with automatic metadata extraction, plain text notes, uploaded images, and PDF documents, all organized into shareable lists with collaborative access. Browser extensions for Chrome and Firefox make saving a one-click operation from any page. Migrating is painless with importers for Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. LLM summarization condenses saved pages into brief overviews for quick scanning. The AI layer is entirely optional: Hoarder works perfectly as a manual bookmark manager, with intelligence adding convenience rather than imposing a requirement. SSO integration and responsive dark mode round out the package.
Redis
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Whoogle
Google's search results without Google's surveillance: Whoogle is a self-hosted proxy that strips the tracking and keeps the results. Your query goes from browser to your Whoogle instance, which fetches results from Google with a randomly generated User Agent and strips everything hostile before returning them: no ads or sponsored content, no third-party JavaScript or cookies, no AMP links, no URL tracking tags like utm_source, no referrer header - and Google sees your server's IP, never yours. Unlike metasearch engines that blend sources, Whoogle proxies Google exclusively, so result quality is exactly what you'd get logged out and incognito, minus the noise. A lightweight Flask app configured entirely through environment variables, it supports DuckDuckGo-style bang shortcuts, autocomplete suggestions, safe search, per-country and per-language filtering, site blocklists, and automatic rewriting of social links to privacy front-ends like Nitter and Invidious. Privacy hardening goes further: built-in Tor routing makes Google see an exit node instead of your server, HTTP/SOCKS proxy support covers other setups, and POST-based queries keep search terms out of logs. Light, dark, and fully custom CSS themes plus browser search-engine registration make it a drop-in default on desktop and mobile. Stateless, tiny, and trivial to run.
Farfalle
Live web search plus an LLM of your choice: Farfalle is an open-source, self-hosted answer engine in the Perplexity mold. Queries route through one of several search providers - self-hosted SearXNG for a fully independent stack, or Tavily, Serper, and Bing APIs - and the model composes a cited answer from the retrieved results. Model flexibility is the core design: run llama3, mistral, gemma, or phi3 locally through Ollama for zero per-query cost and full privacy, use cloud models like GPT-4o or Groq-hosted Llama 3 for speed, or route to any provider via LiteLLM. An Expert Search mode uses an agent that plans a multi-step search strategy and executes it for harder questions, and chat history keeps prior research sessions available. The stack is a Next.js and shadcn/ui frontend over a FastAPI backend with Redis rate limiting, shipped as a pre-built Docker image. A browser search-engine entry pointing at your instance makes it the default search from the address bar. Paired with SearXNG and Ollama, the whole pipeline runs with no external API at all.
Elasticsearch
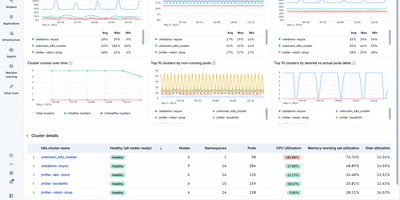
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
RAGFlow
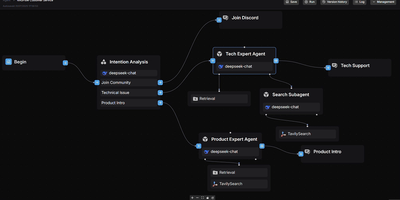
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
MongoDB
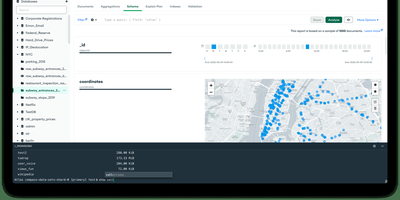
Used by over 46,800 companies including Forbes, Toyota, and Cisco, MongoDB stores data as flexible JSON-like BSON documents that eliminate rigid table schemas and support rapid application iteration. Its aggregation pipeline processes complex data transformations through composable stages including $match, $group, $lookup for joins, $unwind, and $project, operating directly within the database engine. Horizontal scaling is built in through automatic sharding, which distributes data across nodes using range-based, hashed, or zone-based shard keys, while replica sets provide automatic failover with configurable read preferences and write concerns. Multi-document ACID transactions span multiple collections and shards since version 4.0, enabling relational-style consistency guarantees within a document model. Starting with Community Edition 8.2, native full-text search and vector search are available directly in the database through $search and $vectorSearch aggregation stages, supporting RAG patterns, semantic retrieval, and hybrid search without external dependencies. Change streams provide real-time event-driven data access by tailing the oplog through the aggregation framework, enabling reactive architectures without polling. Time series collections offer optimized columnar storage for IoT sensor data and metrics with automatic bucketing and compression. Official drivers exist for Python, Node.js, Java, Go, C#, C++, Rust, Swift, and PHP, with MongoDB Compass providing a GUI for visual schema exploration and query building. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL v1 licensed.
Sourcebot
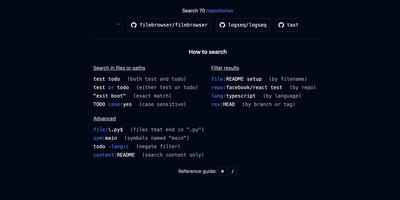
Point Sourcebot at your GitHub, GitLab, Bitbucket, Azure DevOps, Gerrit, or Gitea repositories and get regex, symbol, and filtered search results in under a second across thousands of repos and branches. Backed by Y Combinator with production deployments at NVIDIA, Shutterstock, SeatGeek, Arista, and Red Hat, the Zoekt-powered engine deploys as a single Docker container with zero external data transmission. Ask Sourcebot connects reasoning models like Claude Opus to your entire codebase, enabling natural language questions that return structured answers grounded with inline citations and navigable code snippets, backed by automatic tool calls that search code, follow references, and read files across all indexed repositories. Ask connectors extend this to Jira, Slack, Linear, and Confluence via MCP, pulling external context alongside code for debugging and documentation. IDE-level code navigation provides goto definition and find all references across repository boundaries without local cloning. The built-in file explorer renders any indexed file with syntax highlighting, breadcrumb navigation, and git blame showing per-line commit attribution. An analytics dashboard tracks daily, weekly, and monthly search activity. Permission syncing from GitHub and GitLab enforces access control lists so users only see repositories they are authorized to access. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Other licensed.
ChatChat
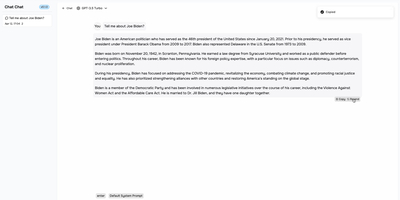
One clean interface in front of Anthropic, OpenAI, Google Gemini, Cohere, and more: Chat Chat is a Next.js front door to the major AI providers, ending the juggling of separate subscriptions, tabs, and UIs per model. Bring your own API keys, pick a provider and model per conversation, and switch between them as the task demands: Claude for long-form reasoning, GPT for code, Gemini for multimodal work - the interface stays identical. Beyond configured presets, custom providers plug in with their own API endpoints and keys, which covers OpenAI-compatible gateways and local inference servers. The design splits into two dedicated modes: a chat interface for conversational work with customizable system prompts, and a search interface that pairs AI processing with query handling for research-style questions. The stack is modern and hackable - Next.js 14, Tailwind CSS, shadcn/ui on Radix primitives, Jotai for state - with full internationalization including English, Chinese, and Japanese. Self-hosting means your conversation history and API keys live on your instance rather than a third-party wrapper service, and pay-per-token API pricing typically beats stacking multiple monthly chat subscriptions. AGPL-licensed and deliberately simple to deploy: one container, environment variables for keys, done.
Atomic
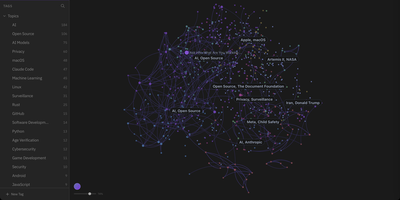
Atomic transforms collections of personal Markdown notes into an AI-augmented knowledge graph by breaking documents down into semantically linked conceptual units. Users capture thoughts, research excerpts, and web clippings as modular notes that the system automatically chunks, embeds, and categorizes with hierarchical tags. An interactive force-directed canvas maps out the entire knowledge base, positioning related ideas closer together based on embedding cosine similarity rather than manual folder hierarchies. Built-in vector search queries across text embeddings directly within SQLite, retrieving precise contextual snippets in response to natural language prompts. The automated wiki engine synthesizes disparate notes into comprehensive reference articles equipped with verifiable inline citations back to original source materials. Integrated conversational agents leverage retrieved knowledge context to answer research questions, surface contradictions across past entries, and draft structured daily briefings. External AI tools can read, search, and update stored knowledge through an embedded Model Context Protocol server endpoint. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PipesHub
Unify fragmented corporate knowledge across chat channels, documents, and cloud drives with PipesHub, an open-source workplace context platform providing permission-aware search and verifiable answers for teams and autonomous agents. Employees can query enterprise knowledge bases through a conversational interface that retrieves relevant information across Google Workspace, Microsoft 365, Slack, Confluence, Jira, and GitHub while strictly respecting individual user access permissions. Knowledge workers can verify every answer through clickable citation blocks that trace claims directly back to source documents, spreadsheet rows, or chat messages. Teams can assemble custom AI agents visually using a drag-and-drop builder, combining retrieval collections with interactive toolsets to automate multi-step operations like drafting customer responses or creating issue tickets. Autonomous agents connect via Model Context Protocol to inspect shared company knowledge and perform external actions across connected SaaS tools. Organizations can index scanned PDFs, slide decks, markdown pages, and spreadsheets with OCR and document parsing, maintaining synchronized records through automated schedules. Administrators can inspect synchronized records, monitor query history, and manage connector credentials across all integrated business applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.