1Panel
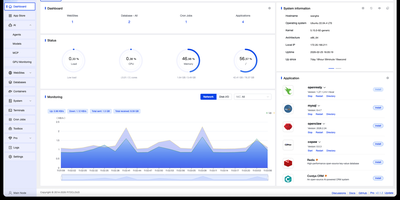
Backed by over 36,000 GitHub stars and 120 contributors with 123 releases since 2022, 1Panel has rapidly become the go-to open-source alternative to cPanel and Plesk for modern Linux server management. The platform delivers a clean Vue.js dashboard powered by a Go backend using the Gin framework, providing visual management of Docker containers, images, networks, and volumes without touching the command line. Its curated app marketplace offers one-click installation of 165+ trusted open-source applications including Nextcloud, Bitwarden, Umami analytics, WordPress, and NocoBase, each running in isolated containers for maximum security. Native AI capabilities set 1Panel apart from every competing panel: deploy Ollama LLMs directly from the dashboard, spin up OpenClaw personal agents, monitor GPU utilization, and manage AI models through a unified interface. Website management includes automatic domain binding, Let's Encrypt SSL certificate provisioning, and Nginx configuration with zero manual setup. Security runs deep with built-in firewall rules, fail2ban integration, container isolation, WAF protection, and comprehensive audit logging enabled from day one. Automated backups support AWS S3, Cloudflare R2, and local storage with one-click restore from any snapshot. The panel supports Debian, Ubuntu, CentOS, and Rocky Linux across x86_64, aarch64, armv7l, ppc64le, and s390x architectures. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Cognee
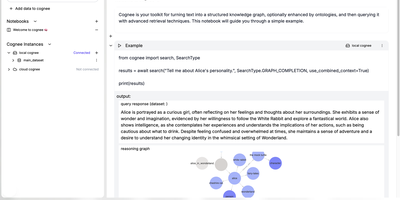
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Kong
With over 43,000 GitHub stars and adoption by companies including Nasdaq, Samsung, and Expedia, Kong Gateway is the world's most deployed open-source API gateway, processing billions of API requests daily across hybrid-cloud and multi-cloud architectures. Built on the battle-tested NGINX engine with OpenResty's LuaJIT runtime, Kong delivers sub-millisecond proxy latency while supporting REST, gRPC, GraphQL, WebSocket, SOAP, and Kafka protocols. The plugin architecture includes authentication via JWT, Basic Auth, HMAC, key authentication, OAuth 2.0, and LDAP, alongside rate limiting with configurable windows per consumer, IP address, or API key. The AI Proxy plugin provides a universal LLM API that routes across OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure AI, Databricks, Mistral, and Hugging Face through a single standardized interface, while MCP proxy capabilities convert REST APIs into MCP tools and provide traffic governance for AI agents. Kong supports declarative configuration via YAML for GitOps workflows, a RESTful Admin API for dynamic configuration, and decK CLI for version-controlled infrastructure-as-code management. Upstream health checking with active and passive probes enables automatic failover, and the ring balancer distributes traffic across upstream targets with consistent hashing, round-robin, or least-connections algorithms. The Kong Plugin Hub hosts over 100 community and official plugins covering logging, monitoring, transformation, security, and traffic control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Agentic SOC Platform
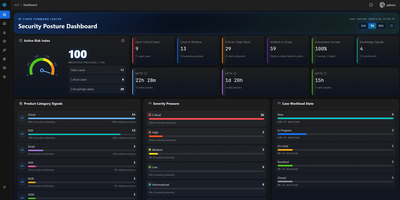
Agentic SOC Platform compresses hours of manual security analysis into seconds by deploying specialized AI agents that autonomously triage, investigate, and enrich security alerts. The Python/Django backend processes SIEM webhooks through Redis Streams into a modular pipeline where LangGraph-orchestrated agents extract IOCs, correlate signals, and generate Cases with severity, confidence, impact, priority, and structured verdicts. The built-in SIRP provides full case management with Alerts, Artifacts, Enrichments, Tickets, and a Knowledge base that accumulates institutional memory for both human analysts and LLM agents. Native Splunk and Elasticsearch/Kibana integrations deliver unified log search through a standardized interface so agents and analysts share identical security context. The playbook engine combines traditional SOAR automation with AI-powered investigation — launching threat hunting agents, knowledge extraction, threat intelligence enrichment, and CMDB lookups from a single orchestration layer. MCP Plugin support exposes ASP capabilities to Claude Code, Codex, and OpenCode, enabling external AI agents to operate cases, search logs, query threat intelligence, and write custom modules directly. Python Modules adapt new alert sources while Playbooks orchestrate LLM analysis and automated response actions, scaling the platform with your security scenarios. Deploy via Docker Compose with all data staying inside your network. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Treg
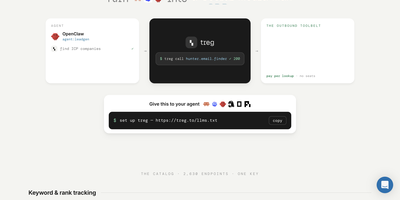
With over 330 GitHub stars and described as "OpenRouter, but for agent tools instead of models," Treg is the unified tool registry that gives your AI agent one base URL, one token, and instant access to approximately 2,800 cataloged endpoints across 56 providers — SEO and backlink analysis via Semrush and Moz, social media intelligence from TikTok and Instagram, people and company enrichment through Crunchbase and Hunter, media buying, scraping, and SERP data — all priced per call from fractions of a cent with no provider signup required. The FastAPI backend with PostgreSQL stores credential bindings and injects them server-side into every proxied request, ensuring API keys and OAuth tokens never touch the agent or local machine while every call is audit-logged. Teams register their own paid API accounts, OAuth connections, vendor CLIs like Stripe, GitHub CLI, Vercel, and gcloud, plus custom SKILL.md definitions — all callable by every teammate's agent through a single treg token with automatic credential injection. The evidence-based tool selector shows success rate, response speed, and last-seen timestamp for each provider, so agents pick tools on measured performance rather than guesswork. Bring-your-own-key routes bypass metering entirely, and the one-dollar free credit on every new team lets agents start calling immediately. The Vue.js web dashboard provides team management, audit logs, catalog browsing, and guided onboarding. Self-host with pip install tools-registry[server] on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Laminar
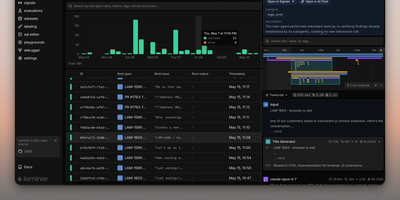
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
big-AGI
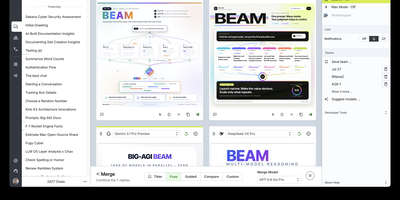
big-AGI is an open-source generative AI workspace that provides a unified, local-first interface for orchestrating multi-model reasoning, automated code execution, and custom persona workflows across private infrastructure. Users query multiple large language models simultaneously through the Beam scatter-gather engine, which prompts independent AI systems in parallel, compares candidate completions side by side, and merges optimal passages into a single refined response. Knowledge workers assemble tailored AI personas equipped with specialized system instructions, custom temperature settings, and predefined document context to handle domain-specific tasks ranging from architectural design reviews to legal contract analysis. The application renders rich multimedia outputs including interactive Mermaid sequence diagrams, LaTeX mathematical formulas, syntax-highlighted code blocks with live execution previews, and AI-generated image generation canvases. Teams integrate local inference servers like Ollama and LocalAI alongside commercial API endpoints to route confidential datasets strictly through internal networks while monitoring per-prompt token usage and operational latency. Users attach complex PDF documents, spreadsheets, and source code repositories for automatic parsing and semantic retrieval, while local-first storage engines ensure private chat transcripts and custom presets remain encrypted on host drives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
New API
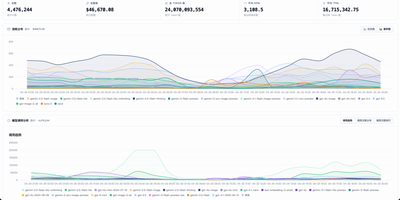
New API is a Go-powered LLM gateway that funnels over 40 AI providers, from OpenAI and Anthropic to Google Gemini, Azure, AWS Bedrock, DeepSeek, and Mistral, through a single OpenAI-compatible endpoint with intelligent routing and enterprise cost controls. Bidirectional format conversion translates between OpenAI Chat Completions, Claude Messages, and Gemini GenerateContent APIs transparently, so clients call any provider using their preferred format while the gateway handles the rest. Routing logic supports weighted random channel selection, priority-based failover, and automatic retry on provider errors to maximize uptime. The React admin dashboard shows usage charts, token consumption tracking, per-model cost breakdowns, and real-time request monitoring. Multi-tenant architecture includes three role levels, token-based authentication, per-user quota management, and a three-phase billing system with tiered pricing via a custom expression language. Multimodal support covers text completion, vision, embeddings, text-to-speech, speech-to-text, image generation, and creative task providers like Midjourney-Proxy and Suno-API. The interface ships in five languages including English, Chinese, Japanese, and French. Docker deployment runs with SQLite or MySQL for persistence. 45,000+ GitHub stars. AGPL-3.0 licensed.
AgentDesk
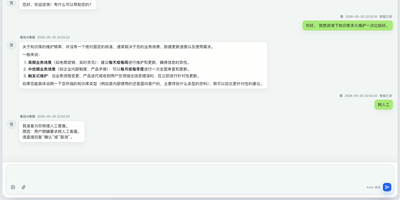
Most AI chat integrations bolt an LLM onto a text box and call it customer support; AgentDesk builds the entire helpdesk around AI agents that handle first responses, escalate to humans when they cannot answer, and track follow-up work through integrated ticket workflows. Each AI agent binds to a specific LLM configuration, one or more knowledge bases, a set of callable Skills, and MCP tool integrations, creating specialized support personas for different product lines or departments. When a customer message arrives, the agent retrieves relevant FAQ entries and document chunks through RAG-powered vector search (Qdrant), then passes retrieved context through an Answerability Gate that determines whether the knowledge base can support a reliable answer; if not, it triggers a fallback response and recommends human handoff instead of hallucinating. Human agents pick up escalated conversations in a dedicated workspace that preserves the full AI conversation history, customer profile, conversation tags, and linked tickets, so they never start from scratch. The ticket system converts conversations into tracked work items with category assignment, status flows, progress notes, and team routing. An admin dashboard provides user management, role-based access control, team scheduling, and automatic conversation assignment rules. Model configuration supports any OpenAI-compatible provider, letting you wire in LLMs, embedding models, and reranking models with per-model context limits, timeout settings, and rate controls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
LiteLLM
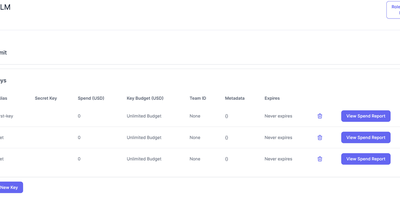
Backed by 56,000+ GitHub stars and over 240 million Docker pulls, LiteLLM delivers the open-source AI gateway trusted by Netflix, Lemonade, Rocket Money, and thousands of engineering teams to route every LLM request through one unified API. The Rust-core gateway adds sub-millisecond overhead per request with 8ms P95 latency at 1,000 RPS, 15x throughput improvement and 11x lower memory footprint compared to Python-only proxies. A single OpenAI-compatible endpoint connects to 100+ providers and 1,800+ models spanning OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure OpenAI, Vertex AI, Hugging Face, vLLM, Nvidia NIM, Ollama, and Mistral with day-zero support for new model releases. The Auto Router V2 classifies request complexity across four tiers using rule-based scoring, semantic keyword matching, and adaptive Thompson sampling to route each request to the most cost-effective model without API calls or training data. Virtual API keys enable multi-tenant governance with per-team, per-user, and per-project cost tracking, budget caps with automatic fallback rerouting, and role-based access control. Built-in guardrails provide PII masking, prompt injection detection, and model-graded evaluation before requests reach providers. The Agent Gateway extends routing from model calls to agent workflows with MCP server integration. Observability integrates with Langfuse, Arize Phoenix, OpenTelemetry, and MLflow for complete request tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Airi
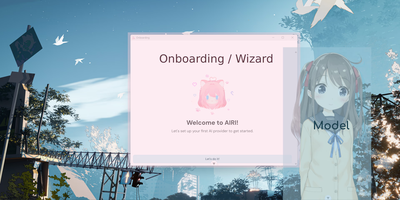
Project AIRI is the most popular open-source AI companion platform — a self-hosted recreation of Neuro-sama that brings AI-powered virtual characters into your world across web, desktop, and mobile. The system renders Live2D, Spine, and VRM 3D character models with auto-blink, eye tracking, and lip-sync driven by real-time voice synthesis, while the xsAI abstraction layer connects to 40+ LLM providers including OpenAI GPT-4, Anthropic Claude, Google Gemini, DeepSeek, and local models via Ollama and OpenRouter. Built from day one on WebGPU, WebAudio, Web Workers, WebAssembly, and WebSocket technologies, the browser version runs entirely client-side with PWA offline support while the server runtime enables persistent memory via PostgreSQL with pgvector embeddings and DuckDB WASM for client-side storage. The Minecraft agent plays autonomously using mineflayer with pathfinding, and a Factorio integration provides cooperative gameplay. Social integrations deploy your companion as a Discord bot joining voice channels, a Telegram bot, and a Twitter/X agent posting and replying autonomously. The desktop Stage Tamagotchi app provides an always-on-screen companion for Windows and macOS, while Stage Pocket brings the experience to mobile. Voice features include client-side speech recognition via VAD, multiple TTS providers including ElevenLabs, and screen vision capabilities. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vane
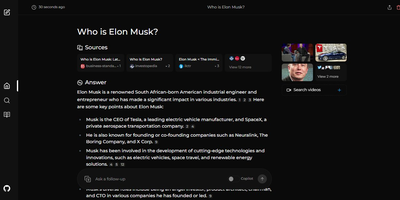
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
Deskcomm
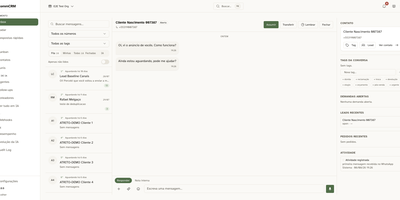
Converting inbound chat conversations into closed revenue is what Deskcomm orchestrates through an open-source sales operating system with native AI agent routing and WhatsApp integration. Sales representatives monitor incoming customer inquiries across connected WhatsApp Web sessions and official WhatsApp Cloud API channels from a real-time shared inbox with multimodal attachment previews. Autonomous AI agents qualify incoming leads, extract contact parameters, parse customer objections, and book calendar appointments before escalating complex deal negotiations to human account executives. Commercial teams organize deal progression through interactive kanban pipeline boards, where drag-and-drop movements trigger automated follow-up sequences and dynamic message templates. The built-in knowledge retrieval studio ingests internal product documentation and FAQ catalogs, allowing AI attendants to cite verified organizational knowledge during client interactions. Multi-tenant access controls enforce strict data isolation between business units with granular role assignments for managers and support operators. Administrators monitor token consumption across OpenRouter and OpenAI models while synchronizing customer records with external platforms through Model Context Protocol servers and outbound Webhooks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Morphic
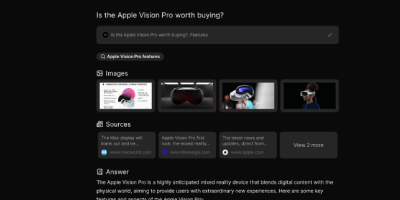
Perplexity's answer-engine experience, self-hostable and open-source: Morphic searches the web and writes cited answers. Instead of returning a list of links, it searches the web, reads the sources, and generates a complete answer with inline numbered citations. The generative UI streams rich components, source cards with thumbnails, image grids, syntax-highlighted code, and LaTeX math, rather than plain markdown. Quick mode answers fast; Adaptive mode runs deeper multi-step research. Search backends are pluggable: the Docker Compose bundle ships with a private SearXNG instance so no search API key is required, and Tavily, Brave, and Exa are supported alternatives. LLM providers include OpenAI, Anthropic, Google, Ollama, and any OpenAI-compatible endpoint, with per-mode model mapping - fast, cheap models for quick searches, stronger models for adaptive research, tuning the cost-quality trade-off per query type. An inspector panel exposes tool execution during multi-step research, and AI-suggested follow-up questions keep an investigation moving. Chat history persists in PostgreSQL, results are shareable by URL, file uploads feed context into queries, and optional Supabase authentication adds multi-user or guest access. Because the default search path is your private SearXNG instance, research topics never hit a commercial search API - and with local Ollama models the marginal cost of a query approaches zero. Built with Next.js, TypeScript, and the Vercel AI SDK under Apache 2.0.
Letta
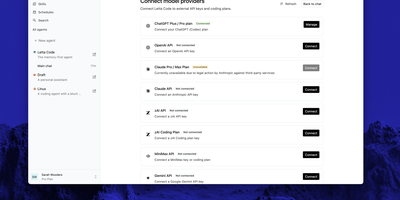
With over 24,000 GitHub stars and origins in the MemGPT research paper on virtual context management, Letta has evolved into the leading open-source platform for building AI agents that maintain persistent memory, identity, and continuity across sessions rather than operating as stateless prompt-response loops. The core architecture uses memory blocks — structured, labeled text chunks that reside permanently in the agent's context window — allowing agents to programmatically rewrite their own memory, learn new skills, and improve through a sleeptime dreaming process that runs reflection and memory organization during idle periods. The self-hosted App Server deploys via Docker and exposes a WebSocket API on port 4500, letting the TypeScript Agent SDK connect from any application using local, remote, or cloud backends. Agents support git-versioned memory through MemFS where every memory change is tracked and auditable, multi-agent communication via subagents, scheduled tasks, and integration with messaging platforms including Slack, Discord, Telegram, WhatsApp, and Signal. The platform is fully model-agnostic, routing to OpenAI, Anthropic, xAI, or self-hosted open-weight models through Ollama depending on cost, performance, and data residency requirements. The Agent File format serializes complete agent state — memory, skills, prompts, and conversation history — into portable snapshots. Desktop applications for macOS, Windows, and Linux provide native interfaces alongside the terminal CLI and web chat at chat.letta.com. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Scira
Scira is an AI search engine that breaks complex research questions into sub-tasks, retrieves grounded answers from live sources, and cites every claim with clickable links to the original evidence. Formerly known as MiniPerplx and now backed by nearly 12,000 GitHub stars, the platform implements agentic research planning where language models decompose queries, select appropriate tools, retrieve information in parallel, and synthesize responses with inline citations. Seventeen distinct search modes cover Web, Academic, Extreme, X (Twitter), Reddit, GitHub, Stocks, Crypto, YouTube, and Prediction markets, each activating a curated subset of the 28 built-in tools. The Extreme mode deploys a deep research agent with multi-step planning, parallel source retrieval, code execution in sandboxed Daytona environments, and R2 artifact storage for generated charts. Model routing spans 50+ AI providers through a unified configuration layer supporting OpenAI, Anthropic, Google, xAI Grok, and custom models, with per-mode model assignment based on task requirements. The web search tool supports Exa, Tavily, and Firecrawl as interchangeable providers via a Strategy pattern. Lookouts schedule recurring research agents on cron schedules that monitor topics, track changes, and email summaries using Upstash QStash for reliable execution. PostgreSQL stores chat history, user preferences, and custom instructions while Redis handles caching and rate limiting. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.

Vexa
Vexa is the only Apache 2.0 meeting bot API that self-hosts the complete transcription pipeline, from bot dispatch to Whisper speech-to-text to knowledge agents, with zero audio leaving your infrastructure. A single POST /bots request sends a transcription bot into any Google Meet, Microsoft Teams, or Zoom call, where it captures audio, runs speaker-attributed transcription through faster-whisper or any OpenAI-compatible endpoint, and streams results to your application via real-time WebSocket with sub-second latency. The built-in agent framework watches live transcripts and your accumulated workspace context, answering mid-call questions grounded in your own meeting history and wiki. An MCP server connects Vexa to Claude, Cursor, and other compatible AI tools, turning every captured meeting into queryable context for external agents. The Terminal, a bundled Next.js web workbench, lets you send bots, watch live transcripts, manage users and API tokens, and chat with your meeting archive from a browser. Docker Compose brings the full stack up on one Linux host in five minutes; the Helm chart scales to thousands of users on Kubernetes with a Pod-per-bot architecture and built-in RBAC. Recordings persist in MinIO or any S3-compatible store, transcripts in Postgres, with Redis handling queues and scheduling. Deploy on RepoCloud for a dedicated VPS with full root SSH access and browser console. Apache 2.0 licensed.
PentaGI
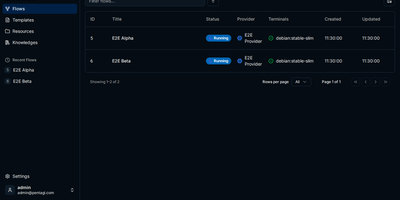
Autonomous red team execution without manual script coordination is what PentaGI delivers through a multi-agent penetration testing platform engineered for automated security assessments. Security engineers configure testing scopes, target IP ranges, domain lists, and rules of engagement through an interactive web console with real-time execution graphs. Autonomous agent personas break down high-level assessment goals into discrete tactical phases, orchestrating network port discovery, service banner fingerprinting, web application crawling, and CVE verification. Specialized agents query integrated Graphiti knowledge graphs and local vulnerability repositories to synthesize attack paths, validate exploitability, and confirm finding veracity before issuing alerts. Operators monitor live agent terminal streams, inspect sandboxed tool executions, and adjust active LLM provider routes across OpenAI, Anthropic, or local Ollama endpoints. The template editor allows red teams to compose reusable testing playbooks with customizable security prompt chains, safety constraints, and automated remediation reporting. Audit logs capture full command histories, raw tool outputs, and LLM reasoning steps to generate compliance-ready technical documentation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.