Glance
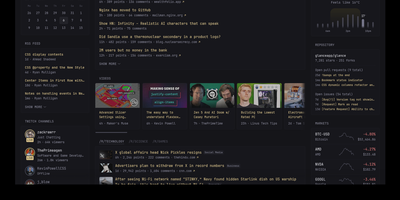
With over 35,000 GitHub stars in just two years, Glance has become the most popular self-hosted dashboard project on GitHub, outpacing established alternatives like Homarr and Homepage. Built as a single Go binary under 20MB with minimal JavaScript and zero external dependencies, Glance delivers a blazing-fast personal information dashboard that consolidates your entire digital morning routine into one beautiful page. Configure everything through clean YAML files that support modular includes and environment variable interpolation, with automatic hot-reload that applies changes without restarting the server. The widget ecosystem covers RSS and Atom feeds, Reddit and Hacker News frontpages, YouTube channel subscriptions, GitHub release timelines, weather forecasts from Open-Meteo, stock market quotes, Docker container status, Twitch live streams, calendar events via iCal, site monitor uptime checks, and custom HTML or iframe embeds. A community widgets repository extends functionality even further with user-contributed integrations. The theming system provides light, dark, and custom color schemes with multiple layout options including slim and wide column configurations. Authentication support added in 2025 secures access with username and password protection. Preconfigured page templates let you get started in seconds with curated layouts for development, homelab monitoring, news reading, and entertainment tracking. Deploy via Docker Compose or as a standalone binary on Linux, macOS, or Windows across AMD64 and ARM64 architectures. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Netdata
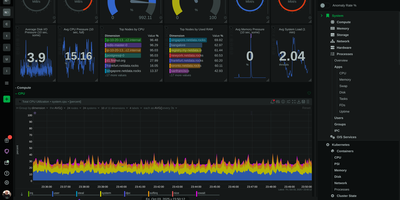
Trusted by millions of engineers and deployed on over 80,000 GitHub stars worth of community confidence, Netdata delivers true real-time monitoring at per-second granularity — 10-60x faster than Prometheus, Datadog, or any conventional monitoring stack that averages away the transient anomalies lasting 2-10 seconds where most production incidents originate. A single installation command deploys the agent with zero configuration, automatically discovering every running process, container, systemd service, network connection, disk, and application on the host within seconds. Unsupervised machine learning trains multiple models per metric directly at the edge, detecting anomalies without thresholds, baselines, or manual tuning. The distributed Parent-Child architecture scales horizontally from a single Raspberry Pi to fleets exceeding 100,000 nodes while maintaining sub-2-second visualization latency and storing metrics at approximately 0.5 bytes per sample through tiered compression. Native network monitoring provides live topology maps, NetFlow and sFlow analytics, SNMP device polling across 200+ profiles, and trap handling — capabilities that typically require a separate NPM product. Hundreds of pre-configured alerts cover systems and applications out of the box, with AI-powered root cause analysis surfacing correlated metrics through natural language via MCP-compatible AI assistants. The agent supports Linux, macOS, FreeBSD, Kubernetes, and Docker with eBPF-based kernel observability requiring no application instrumentation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL v3+ licensed.
Highlight
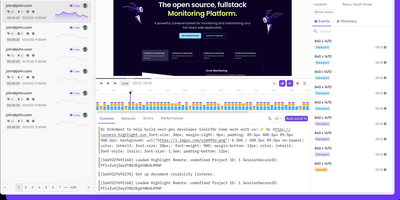
With over 9,000 GitHub stars and a focus on developer experience over legacy monitoring complexity, Highlight.io delivers a unified observability platform that correlates frontend user behavior with backend performance data in a single interface. The session replay engine captures high-fidelity DOM recordings showing exactly what users experienced, including console logs, network requests, page transitions, and user interactions, with configurable privacy redaction for sensitive content. Error monitoring automatically groups and deduplicates errors, surfaces affected user sessions, and provides full stack traces with source map support for minified production code. The logging pipeline ingests structured and unstructured logs from any backend service with automatic property extraction, full-text search, and configurable alerting thresholds. Distributed tracing tracks request flows across microservices with embedded links to associated sessions, errors, and logs for complete request lifecycle visibility. The metrics system collects custom application metrics alongside built-in web vitals and performance data for trend analysis and anomaly detection. Search across all telemetry types uses a unified query language with automatic attribute discovery and saved views for recurring investigations. Integrations connect with Slack, Discord, Linear, Jira, Vercel, and dozens of other developer tools for notification routing and workflow automation. SDKs cover React, Next.js, Vue, Angular, Python, Go, Ruby, Java, PHP, and Elixir with framework-specific instrumentation. Self-hosted deployment runs via Docker Compose with ClickHouse for analytics storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Grafana OnCall
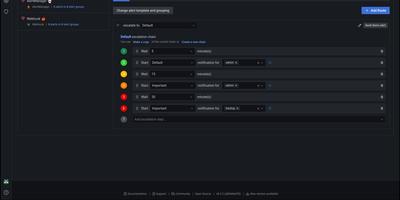
With 3,900 GitHub stars, 140 contributors, and 380 releases since its 2022 launch, Grafana OnCall delivers developer-friendly incident response that routes alerts from any monitoring system to the right engineer at the right time through the right channel. The platform accepts alerts via unique API URLs from Alertmanager, Grafana Alerting, Zabbix, Datadog, Pagerduty-compatible sources, Jira, inbound email, and generic HTTP webhooks, then applies routing templates to direct each alert to the appropriate escalation chain. Escalation chains define notification sequences — notify the primary on-call via Slack, wait 5 minutes, escalate to SMS and phone, wait 10 minutes, page the secondary on-call and notify the engineering manager — continuing until acknowledgment or resolution. On-call schedules support multi-layer rotations with overrides, shift swaps, and timezone-aware handoffs rendered directly inside Grafana dashboards. ChatOps integration publishes alert groups to Slack channels and Telegram groups with interactive buttons for acknowledge, resolve, and silence actions. Template engines based on Jinja2 control alert grouping, appearance rendering, and behavioral automation. The REST API enables programmatic management of integrations, schedules, and escalation policies. Deploy via Docker Compose with PostgreSQL, Redis, and Celery workers alongside your existing Grafana instance. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPL v3 licensed.
InfluxDB
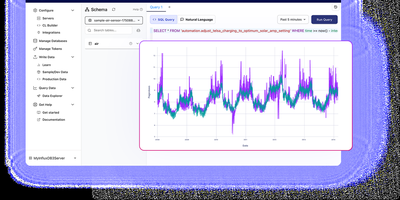
With over 31,600 GitHub stars and thousands of production deployments, InfluxDB 3 Core is the open-source time series database rebuilt in Rust on the FDAP stack — Apache Flight for high-throughput data transfer, DataFusion for vectorized SQL query execution, Arrow for columnar in-memory representation, and Parquet for compressed columnar storage. The engine delivers sub-10ms query response times on recent data and handles millions of writes per second through line protocol ingestion over HTTP, with unlimited tag cardinality eliminating the high-cardinality limitations that plagued earlier InfluxDB versions. The diskless architecture persists data as compressed Parquet files to S3-compatible object storage, Azure Blob, Google Cloud Storage, or local disk with configurable partitioning strategies, while the write-ahead log and in-memory buffer serve real-time queries against recent data before compaction. Native SQL support through DataFusion includes window functions, CTEs, subqueries, and joins, while InfluxQL maintains backward compatibility with existing InfluxDB 1.x and 2.x applications through the same query API. The embedded Python VM enables processing engine plugins and triggers that execute custom logic on write events, perform cross-database queries, and transform data in real time without external tooling. Flight SQL clients provide high-performance query access from Python, Go, Java, and Rust, and the HTTP API supports writes in line protocol format compatible with Telegraf's 300+ input plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT/Apache 2.0 dual-licensed.
VictoriaMetrics
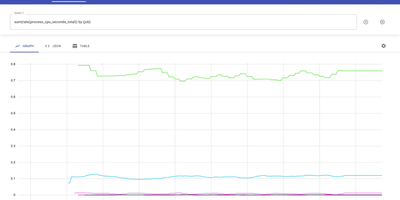
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
GoAccess
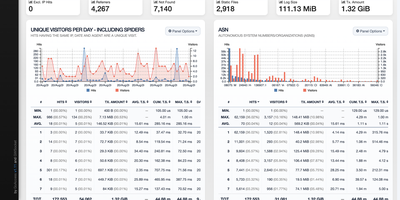
GoAccess processes millions of web log entries in seconds and renders the results as interactive dashboards that update every 200 milliseconds in the terminal or every second via WebSocket-connected HTML reports. Written entirely in C with only ncurses as a dependency, it achieves exceptional performance even on resource-constrained servers, reducing memory usage by approximately 20% and parsing time by 35% in recent releases through optimized in-memory hash tables with on-disk persistence support. The analyzer parses virtually every web log format out of the box (Apache Combined and Common, Nginx, Amazon CloudFront, Amazon S3, AWS Elastic Load Balancing, Google Cloud Storage, Squid, W3C IIS, Caddy JSON, and Traefik) while supporting fully custom log format strings for non-standard configurations. The self-contained HTML dashboard displays 15+ interactive panels covering unique visitors, requested files, static files, 404 errors, referring sites, search keyphrases, geographic location with city-level GeoIP resolution, operating systems, browsers, HTTP status codes, time distribution, and virtual host metrics. WebSocket authentication via JWT provides secure remote access, and incremental log processing ensures data continuity across daemon restarts. Docker deployment requires a single command with volume-mapped access logs. Over 20,800 stars with active development since 2010. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Pulse
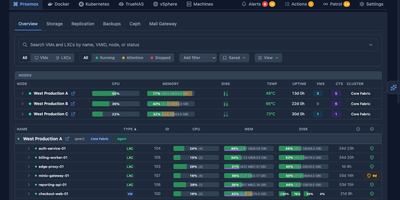
Pulse monitors your entire heterogeneous infrastructure from one screen: Proxmox VE, Proxmox Backup Server, Proxmox Mail Gateway, Docker, Podman, Docker Swarm, Kubernetes, TrueNAS SCALE/CORE, VMware vSphere, and standalone Linux/Windows/macOS machines. The Go binary embeds a SolidJS/TypeScript frontend, delivering WebSocket-driven dashboards with sub-second metric updates on port 7655. A unified agent auto-detects Docker, Podman, Kubernetes, and Proxmox on each host without manual configuration and self-updates silently, while Proxmox nodes need only API credentials with zero agent installation. Smart alerts use adaptive hysteresis-based thresholds to prevent notification floods, pushing to Discord, Slack, Telegram, Teams, email, ntfy.sh, Gotify, and generic webhooks with per-resource overrides. The standout feature is Pulse Patrol: scheduled AI health checks running every ten minutes to seven days using OpenAI, Anthropic, Gemini, or local Ollama models. Patrol catches silent backup failures, capacity creep, restart loops, unhealthy containers, and clock drift that dashboards miss when nobody is watching. Platform-specific views render Proxmox nodes, Ceph clusters, Docker Compose projects, Kubernetes workloads, TrueNAS pools, and vSphere VMs in familiar layouts. OIDC, SSO, and SAML authentication with credential encryption at rest secures access. 6,500+ stars and 441 releases since February 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Kite
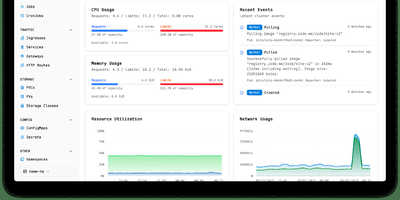
With nearly 3,000 GitHub stars and 14 releases since its June 2025 launch, Kite delivers a lightweight Kubernetes dashboard that replaces the fragmented workflow of switching between kubectl, Lens, and separate monitoring tools with a unified multi-cluster management platform. The dashboard automatically discovers clusters from kubeconfig files and supports independent Prometheus configurations per cluster, providing real-time CPU, memory, and network charts alongside live pod log streaming with filtering and search. A built-in web terminal opens shells directly into pods and nodes without kubectl port-forward, while the Monaco-based YAML editor offers syntax highlighting and validation for in-place resource editing. The integrated AI agent, powered by OpenAI or Anthropic models via native Go SDK integrations, translates natural language into precise client-go API calls — querying cluster health, analyzing pod logs, scaling deployments, patching resources, and cleaning up failed jobs — all operating strictly within the logged-in user's RBAC permissions. Enterprise governance includes OAuth 2.0 single sign-on, multi-factor authentication, FIDO2 passkeys, granular role-based access control with per-namespace permissions, and comprehensive audit logging. Helm chart management enables browsing, installing, and upgrading releases directly from the UI, while the Docker registry integration provides quick image tag selection. Deploy via a single Docker container with SQLite or use the official OCI Helm chart with PostgreSQL or MySQL for production. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Grafana Loki
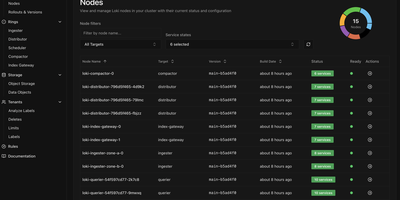
With over 28,600 GitHub stars and 450 contributors, Grafana Loki is the log aggregation system that takes the Prometheus approach to logging — indexing only metadata labels instead of full log content, making it dramatically cheaper and simpler to operate than traditional log management platforms. The label-based indexing strategy groups log streams using the same labels already applied to Prometheus metrics, enabling seamless switching between metrics and logs in Grafana dashboards without maintaining separate indexing infrastructure. Grafana Alloy, the telemetry collector replacing Promtail, scrapes and pushes logs with Prometheus-style service discovery, automatic Kubernetes Pod label extraction, and pipeline stages for parsing, filtering, and relabeling before ingestion. LogQL, the query language, combines label matchers for stream selection with regex line filters and aggregation functions, supporting rate calculations, pattern parsing, and metric generation from log data for alerting and dashboard panels. The storage architecture writes compressed log chunks and TSDB indexes to S3, GCS, Azure Blob Storage, or MinIO-compatible object stores, with configurable retention and compaction policies. Deployment modes scale from a single binary for development through monolithic high-availability mode with multiple replicas to full microservices decomposition with separate ingester, distributor, querier, query-frontend, compactor, and ruler components on Kubernetes via Helm charts. Multi-tenancy isolates data and query paths per tenant through header-based tenant ID assignment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
pgAdmin
pgAdmin 4 is the reference administration GUI for PostgreSQL, bundled by virtually every Linux distribution and supporting versions 14 through 18 including EDB Advanced Server — browse schemas in a hierarchical tree, write and optimize queries with AI assistance, design entity-relationship diagrams visually, monitor live sessions, and run backup/restore operations entirely from the browser. Built on Python Flask with a ReactJS frontend, version 9.17 delivers a comprehensive web-based platform accessible from any device. The Query Tool provides syntax highlighting, auto-completion, query history, an EXPLAIN plan visualizer with graphical node representation, AI-powered SQL generation from natural language prompts, and AI Insights for execution plan analysis that identifies performance bottlenecks. The Graph Visualiser renders query results as line charts, bar charts, stacked charts, and pie charts directly in the interface. The ERD Tool auto-generates entity-relationship diagrams from existing schemas for visual database design. The Schema Browser presents databases, schemas, tables, views, functions, sequences, roles, and extensions in a navigable hierarchy. Server monitoring dashboards display real-time active sessions, locks, transaction throughput, and vacuum status. GUI-driven backup and restore wraps pg_dump and pg_restore with format and compression options. Authentication supports internal, LDAP, Kerberos, OAuth2/OIDC, and webserver modes. The Helm chart includes an HTTPRoute template for Kubernetes Gateway API deployments. Bundled pg_dump, pg_restore, and psql utilities version 18.4. Deploy via Docker with the official dpage/pgadmin4 image. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PostgreSQL License.
Percona PMM
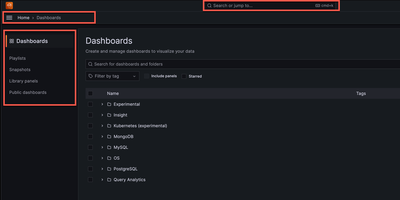
Backed by 1,080+ GitHub stars and maintained by Percona with the latest release v3.8.1 in June 2026, Percona Monitoring and Management delivers the open-source database observability platform that provides a single pane of glass across MySQL, PostgreSQL, MongoDB, Valkey, and Redis databases deployed on-premises, cloud, or hybrid environments. The Go-powered PMM Server collects metrics from lightweight PMM Client agents with minimal performance impact, storing time-series data in ClickHouse for fast querying across configurable retention periods. Query Analytics ranks every query by load across all database engines from one unified dashboard, drilling from fleet-level performance down to individual problematic queries with explain plans, per-query metrics, and anomaly detection. Real-time Query Analytics streams live MongoDB operations updated every 1-5 seconds for immediate troubleshooting of lock contention and long-running queries. Built-in Percona Advisors continuously scan connected databases for security gaps, misconfigurations, and performance problems, distilling decades of DBA expertise into automated actionable recommendations. Percona Alerting integrates with 15+ notification channels including Slack, PagerDuty, email, and webhooks to trigger on custom metric thresholds. Database-specific dashboards visualize InnoDB storage engine details, WiredTiger cache metrics, PostgreSQL tuple activity, replication lag, and cluster health with annotations for root-cause correlation. Deployment options include Docker single-container setup, Podman rootless execution, and Helm charts for Kubernetes with Ingress controller support and ConfigMap management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Nimbus
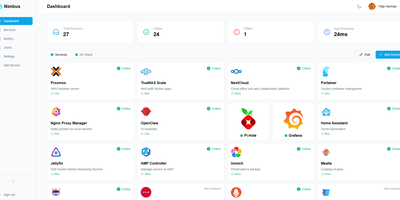
Nimbus is a self-hosted homelab dashboard that turns your scattered pile of services into a polished, organized command center with real-time health monitoring for every endpoint you care about. The dashboard displays live status cards for each registered service, tracking response times down to the millisecond and graphing uptime history so you can spot degradation before it becomes an outage. Health checks run on configurable intervals with smart self-signed certificate handling, meaning your internal services with self-issued TLS do not trigger false alarms. Multi-user support comes standard: local accounts authenticate via JWT, while OAuth2 integration with Google, GitHub, and Discord lets team members sign in with existing credentials. Role-based access control and a built-in admin panel give you granular authority over who sees what. Each user personalizes their view with custom backgrounds, light or dark mode, accent color themes, and drag-and-drop service tile arrangement. Services group into named categories and cards resize to fit your preferred layout, with both grid and list view modes available. Prometheus metrics export feeds your existing Grafana stack, and webhook notifications alert you instantly when a service goes offline. Custom service icons upload directly or auto-fetch from the Dashboard Icons collection. Zero-config Docker deployment gets you running in under 30 seconds with a single docker-compose command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
ServerBee
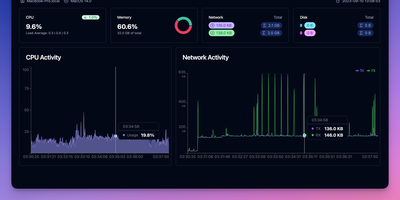
ServerBee delivers complete fleet monitoring from a single Rust binary that embeds both the server and web UI, requiring no external database or heavy runtime. Lightweight agents installed on each node stream CPU, memory, disk, network, load, temperature, GPU, and disk I/O metrics over persistent WebSocket connections to a central server backed by embedded SQLite. The real-time React dashboard presents 17 drag-and-drop widget types across custom layouts, with historical charts spanning one hour to 30 days and monthly traffic statistics with billing-cycle prediction and cost insights including burn rate and per-resource unit cost scoring. Network monitoring covers ICMP, TCP, and HTTP ping probes, service monitors for SSL certificates, DNS records, HTTP keyword matching, TCP ports, and WHOIS expiration, plus network-quality probing across 96 China 3-ISP and international presets with IP-quality and streaming-unlock detection. Remote management features include a web terminal with sandboxed file manager, Docker container stats with logs and events, firewall configuration, and agent auto-update capabilities. Public status pages display 90-day uptime timelines, while alerting supports email and webhook notifications with flexible trigger expressions. A native iOS companion app provides mobile monitoring access. Deploy via Docker or download the single binary for Linux, macOS, or Windows, running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Statping-ng
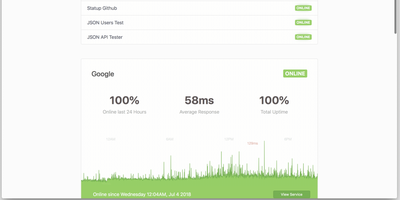
A status page and uptime monitor in one Go binary: Statping-ng - the actively maintained fork of Statping - replaces the UptimeRobot-plus-Statuspage combo with a ~20 MB Docker image using under 50 MB of RAM. It checks services over HTTP, TCP, UDP, ICMP ping, and gRPC health checks on configurable intervals, with per-service timeouts, expected status codes, POST requests with custom JSON bodies, SSL verification, and failure thresholds before alerting. The public status page is the differentiator against plain monitors: visitors see live status, uptime percentages, and latency charts grouped into service categories, with incident announcements and scheduled-maintenance messages you publish from the dashboard - and Sass-based custom styling matches the page to your brand rather than a vendor template. When something fails, notifiers fire immediately: Slack, Discord, Telegram, SMTP email, PagerDuty, Twilio SMS, Pushover, and custom webhooks, each testable before saving. Because notifiers are single Go files, the plugin system makes new channels straightforward. A RESTful API manages services and reads uptime data programmatically, and the free Statping mobile app connects to your server via QR code for on-the-go monitoring. Data persists to SQLite, MySQL, or PostgreSQL. Point it at internal services too - anything the container can reach is monitorable.
Kener
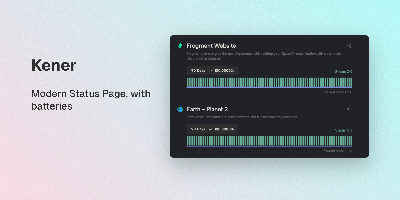
A polished public status page without Statuspage prices or a heavyweight observability suite: Kener is a status and uptime monitoring system built with SvelteKit and Node.js. It runs 11 monitor types - API, Ping, TCP, DNS, SSL certificate, SQL query, Heartbeat, gRPC, and GameDig game-server checks among them - each with configurable intervals and thresholds. Incident management covers the full lifecycle: structured timelines from investigation through resolution, acknowledgements, and subscriber-visible updates, plus maintenance windows with RRULE-based recurring schedules and automatic status transitions. Notifications reach email, Slack, Discord, and custom webhooks through trigger-based workflows with template-driven messaging. One instance can serve multiple branded status pages - per product, team, or region - with custom logos, colors, and CSS, localization into 21 languages, timezone-aware displays, and server-rendered pages that stay fast and SEO-friendly. Operations tooling includes role-based access for teams, API key management, a secrets vault, analytics integrations (Google Analytics, Plausible, Umami, and others), and a REST API with 17+ endpoints for automating incidents and monitors from CI/CD. MIT-licensed; Docker deployment with Redis, SQLite by default, PostgreSQL or MySQL for production.
CoreObs
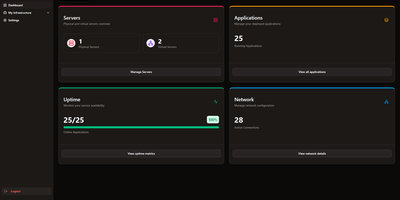
CoreObs delivers a unified self-hosted dashboard that replaces the typical combination of Uptime Kuma, Homer, and separate monitoring tools with a single interface for managing your entire server infrastructure. The Next.js frontend with shadcn components provides a modern dark-themed UI displaying server hardware metrics collected by a lightweight Go agent that leverages Glances for hardware abstraction — streaming real-time per-core CPU load, RAM utilization, NVIDIA GPU statistics, disk usage, system uptime, and load averages via WebSocket connections. The application registry tracks all self-hosted services with configurable uptime monitoring, availability history charts, and instant notifications through Discord, Telegram, Pushover, and email when services go down or recover. Quick-access links provide one-click navigation to each application's management panel directly from the dashboard. The network visualization module built on React Flow enables creating visual topology maps of your infrastructure with drag-and-drop nodes representing servers, switches, and services connected by labeled edges. Server data can be organized with tags, copied between entries, and monitored with configurable pagination and compact view modes. Deploy via Docker Compose with three containers — the Next.js web interface, the Go monitoring agent, and PostgreSQL 17 for persistent storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Tautulli
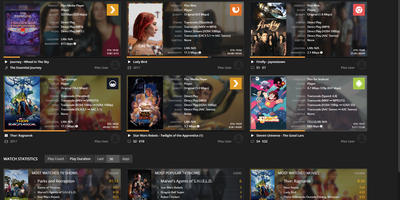
Plex's own dashboard shows current streams and forgets everything else - which is why every Plex server admin eventually installs Tautulli, the analytics layer. This Python web application (descended from PlexWatch and Headphones) logs complete watch history - what was watched, who watched it, when, where, from which device and IP, and whether it played directly or transcoded - and turns it into clean Highcharts graphs of daily plays, concurrent streams, bandwidth, and platform breakdowns. The home page surfaces top statistics over configurable windows: most-watched content, most active users, stream type ratios. For running a server shared with family and friends, this is operational truth: spot the user forcing 4K transcodes on a phone, see which libraries earn their disk space, and track sync activity across users. The notification engine triggers on server events - playback starts, transcode decision changes, recently added media, server down - through dozens of agents (Discord, Telegram, Slack, email, webhooks) with fully customizable text and conditions, plus arbitrary script execution. Scheduled newsletters email your users a styled digest of recently added content. A comprehensive API exposes every statistic for dashboards like Homarr, and an official mobile app monitors activity on the go. Themed to match Plex/Web. GPL-licensed.