Typing Mind
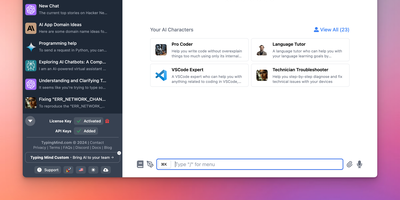
Bring your own API keys and work with OpenAI GPT models, Anthropic Claude, Google Gemini, Mistral, DeepSeek, Grok, Azure endpoints, and local models in one organized workspace: TypingMind is a unified chat frontend for large language models, replacing a browser tab per provider. Parallel chat sends the same prompt to multiple models and compares answers side by side, and models can be switched mid-conversation. A prompt library stores reusable, tagged prompts with variables, and the AI Agents system builds specialized assistants that bundle a base model, custom instructions, assigned plugins, and uploaded knowledge files for RAG. Plugins extend every connected model with web search, image generation (DALL-E, Stable Diffusion), Deep Research, URL reading via Firecrawl, and Zapier automation - plus MCP server integrations for Notion, Atlassian, and other external tools, and a JavaScript extension API for custom behavior. Chats store locally by default with optional sync. Self-hosting puts the interface on your own domain and, for teams, adds branding, member access limits, and shared prompt and agent libraries.
GPT Researcher
A question goes in; a cited, long-form report comes out - GPT Researcher is an open-source autonomous research agent. A planner agent decomposes the query into sub-questions, execution agents crawl 20+ web sources in parallel with JavaScript-enabled scraping, and a publisher aggregates findings into a 2,000+ word report with inline citations, exportable to PDF, Word, and Markdown. The Deep Research mode extends this recursively: each result yields follow-up questions that are explored to configurable breadth and depth in a tree pattern, while accumulated learnings, citations, and visited URLs are shared across branches. It also researches local documents (PDF, CSV, Word) alongside the web. LLM and search providers are pluggable, including OpenAI, Anthropic, Google, DeepSeek, and Ollama for models, and Tavily, Google, Bing, DuckDuckGo, and SearXNG for retrieval. It ships as a Python package, a FastAPI server with web frontend, a Docker image, and an MCP server for use inside Claude or Cursor. MIT-licensed.
Sage Wiki
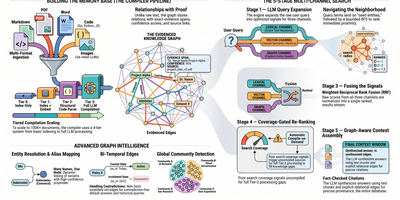
Sage Wiki turns a pile of unstructured documents into a fully interlinked, searchable wiki by running them through a five-pass LLM compiler pipeline. Inspired by Andrej Karpathy's vision of LLM-compiled knowledge bases, the pipeline processes source files through diff detection, summarization, concept extraction, image captioning, and cross-reference discovery, with parallel LLM calls and checkpoint/resume for vaults scaling to 100,000+ documents. The typed ontology graph stores entities and relations with BFS traversal, configurable relation types, multilingual synonyms, and a promotion/demotion lifecycle backed by grounding verification and consensus scoring. Multi-format ingestion handles Markdown, PDF, Word, Excel, PowerPoint, EPUB, email, CSV, images, and code files without manual tagging. LLM provider support spans Anthropic, OpenAI, Gemini, Ollama, and any OpenAI-compatible API, with per-pass model routing enabling cost optimization by assigning cheaper models to simpler tasks. The built-in MCP server exposes 17 tools over SSE transport for integration with Claude, Cursor, and any MCP-compatible agent, while native Obsidian vault overlay ensures existing note workflows remain undisrupted. Team deployment supports Git-synced shared wikis, centralized server access, and hub federation across multiple projects. Ships as a single Go binary with Docker Compose multi-arch images serving the web UI on port 3333. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Open Agent Builder
Open Agent Builder delivers a visual canvas for orchestrating AI agent workflows without writing Python scripts or managing complex codebases. The React Flow-powered drag-and-drop interface supports seven node types — Agent, Scraper, Transform, If/Else, Loop, User Approval, and MCP Tool — each configurable with provider-specific settings for Anthropic Claude (Haiku 4.5 and Sonnet 4.5), OpenAI GPT-5, Groq, or any OpenAI-compatible endpoint. The LangGraph orchestration engine handles state management, conditional routing, and human-in-the-loop approval gates while Firecrawl integration converts any website into structured, LLM-ready data through scrape, crawl, and map operations. E2B sandboxed code execution powers Transform nodes for secure data manipulation without risking host system integrity. Real-time streaming updates show execution progress node-by-node as workflows run, with Convex providing reactive database synchronization for workflow state and execution history. The TypeScript-first architecture (96.8% TypeScript) built on Next.js 16 App Router with Tailwind CSS delivers a responsive interface across devices. Clerk handles multi-user authentication with JWT integration for secure workspace isolation. Deploy via npm install and environment configuration with Firecrawl, Convex, and Clerk API keys. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Agenta
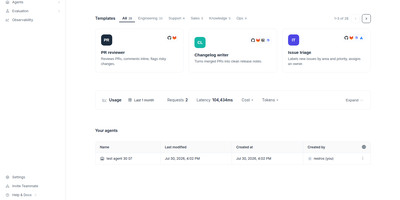
Agenta delivers a comprehensive open-source LLMOps workspace that covers the full lifecycle of AI application development — from prompt engineering through production monitoring. The platform supports 15+ model providers including OpenAI, Anthropic, Google Gemini, Mistral, Groq, Together AI, Azure, AWS Bedrock, and self-hosted models via Ollama, enabling teams to switch between providers without code changes. The prompt playground allows side-by-side comparison of different configurations, while the evaluation system offers LLM-as-a-Judge assessment, 20+ pre-built evaluators covering semantic similarity, regex matching, and factual accuracy, plus custom Python evaluators for domain-specific requirements. Teams run evaluations through both the web UI for subject matter experts and the Evaluation SDK for programmatic CI/CD integration. The observability layer captures full trace visibility across complex agentic workflows, flagging quality issues like hallucinations and off-topic responses in real time. Human annotation workflows let domain experts review and annotate LLM outputs, feeding corrections back into the evaluation loop. The architecture supports Chain of Prompts, RAG pipelines, and multi-step agent workflows, integrating with frameworks like LangChain and LlamaIndex. Self-hosting deploys via Docker Compose with Traefik for routing, requiring only a clone, environment configuration, and a single docker compose command. On RepoCloud, deploy Agenta on a dedicated VPS with root SSH access, persistent storage for evaluation datasets and traces, and complete control over model provider credentials, all under the MIT license with no usage restrictions.
Flowise
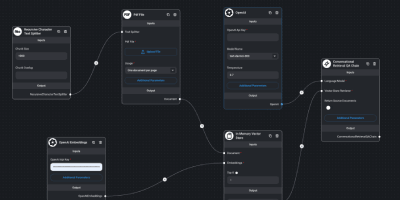
Drag nodes onto a canvas and ship an LLM app: Flowise is an open-source visual builder for AI agents and LLM applications, written in Node.js on LangChain.js and licensed Apache-2.0. You assemble flows by dragging nodes onto a canvas: models, prompts, memory, vector stores, retrievers, and tools, then wire them together and test in the built-in chat panel. Three builder types cover increasing complexity: Assistant for simple RAG chat over uploaded files, Chatflow for single-agent systems with techniques like rerankers and Graph RAG, and Agentflow for multi-agent orchestration with branching, looping, shared flow state, and human-in-the-loop checkpoints. Over 100 integrations connect data sources, vector databases, and both proprietary and open-source models, plus MCP client and server nodes for standard tool interop. Finished flows are exposed as REST APIs, embedded chat widgets, or via JS and Python SDKs - each flow gets an endpoint the moment it is saved, removing the deployment gap between a working prototype and something your application can call. Execution logs, visual step debugging, and external log streaming trace behavior, while input moderation and rate limiting act as guardrails; RBAC, SSO, and workspaces cover team deployments. Self-hosting keeps prompts, encrypted credentials, and conversation data on your own instance, which matters when flows handle internal documents or customer data - and wiring a model, prompt, memory, and vector store on the canvas replaces the boilerplate a hand-coded LangChain project would need.
MLflow
Trusted by thousands of organizations with over 30 million monthly downloads and 20,000+ GitHub stars, MLflow is the largest open-source AI engineering platform providing end-to-end lifecycle management for traditional ML models, LLMs, and AI agents. The OpenTelemetry-based tracing system captures complete request flows through any LLM provider or agent framework — including OpenAI, LangChain, DSPy, Vercel AI, PydanticAI, and smolagents — with one-line auto-instrumentation that tracks inputs, outputs, token usage, and costs at every intermediate step. MLflow's evaluation engine offers 50+ built-in metrics and LLM judges for systematic quality assessment, detecting issues across correctness, latency, adherence, relevance, and safety dimensions before code reaches production. The Prompt Registry versions, tests, and deploys prompts with full lineage tracking while automated optimization algorithms improve prompt performance using evaluation feedback. The AI Gateway provides a unified API endpoint for all LLM providers, enforcing rate limits, cost controls, and access policies across the organization. MLflow 3.0 introduces the LoggedModel abstraction linking traces, metrics, and prompts to specific model versions across Python, TypeScript, Java, and R SDKs. The model registry manages deployment workflows with automated quality gates, while experiment tracking records parameters, metrics, and artifacts across training runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
OpenUI
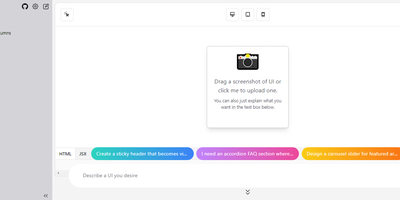
Describe a component in natural language and watch it render: OpenUI, from Weights & Biases, is an open alternative to Vercel's v0. Type a prompt like "a dark-themed dashboard with a sidebar and charts" and the LLM renders working HTML with Tailwind styling live in the browser. You then iterate conversationally, asking for changes until the design is right, and convert the result to React, Svelte, or Web Components for use in a real project. The backend is Python with LiteLLM routing, so it works with OpenAI, Anthropic, Gemini, Groq, and Mistral API keys, or fully offline against local Ollama models, including vision models like LLaVA that can generate UI from screenshot input - feed a screenshot and the model reproduces or riffs on an existing interface. Generated markup is inspectable at any point, with light and dark mode toggles, theme selection, and responsive previews across device sizes. The practical effect is compressing the mockup-review-revise loop from hours to minutes: a described layout renders in seconds and iterates through follow-up prompts, and because output converts to real framework code, prototypes feed directly into production codebases instead of staying trapped in a design tool. Self-hosting keeps unreleased product interfaces and prompts on your own server, and LiteLLM routing lets you pick the model per task - a cheap fast model for rough drafts, a stronger one for final passes, or free local models for unlimited experimentation.
OpenLLM
OpenLLM serves any large language model as an OpenAI-compatible API endpoint from a single CLI command, handling model download, backend selection, quantization, and port binding automatically. It supports the full spectrum of popular models including Llama 3.3, Qwen2.5, DeepSeek, Mistral, and Phi3, choosing between vLLM and PyTorch inference backends based on hardware capabilities. When vLLM is available, continuous batching with PagedAttention achieves up to 23x throughput improvement over naive serving, while GPTQ and bitsandbytes quantization reduces memory requirements for GPU-constrained deployments. The server exposes a RESTful API on port 3000 with full OpenAI client library compatibility, enabling drop-in replacement for commercial providers in any application using the standard chat completions format. A built-in web chat UI at the /chat endpoint provides immediate interactive testing without external clients. Custom model repositories allow teams to maintain private catalogs of fine-tuned models alongside the default repository that tracks the latest releases. Deployment workflows generate production-ready Docker images automatically, with Kubernetes manifest support for orchestrated scaling. Native integration with LangChain and LlamaIndex supports RAG pipelines, Transformers Agents enables tool-calling workflows, and HuggingFace Hub handles model discovery. Server-Sent Events enable real-time token streaming across all API endpoints. Backed by BentoML's production ML infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenSquilla
Claiming 60-80% token cost reduction compared to flat single-model deployments and backed by 6,500+ GitHub stars, OpenSquilla delivers an intelligent AI agent runtime where a local ML classifier evaluates every turn on message length, code blocks, keyword patterns, and semantic embeddings before routing it to the optimal model tier from C0 through C3. The pluggable provider layer connects natively to TokenRhythm, OpenRouter, OpenAI, Anthropic, Ollama, DeepSeek, Gemini, DashScope, Moonshot, Mistral, Groq, Zhipu, SiliconFlow, vLLM, LM Studio, and additional compatible backends with primary-plus-fallback selection. The four-tier cognitive memory architecture spans working, episodic, semantic, and raw layers with vector-semantic and BM25 retrieval powered by on-device ONNX embeddings that never leave your infrastructure. Security isolation operates at the syscall level via Bubblewrap on Linux and Seatbelt on macOS, complemented by policy-based execution controls and prompt injection protections. The unified TurnRunner executes identically across the Vue-based control console Web UI, terminal CLI, and chat channel integrations including Slack and Discord, ensuring consistent tool dispatch, retry logic, and decision logging regardless of entry point. Built-in skills cover deep research, multi-search-engine queries, document generation for DOCX, PPTX, XLSX, and PDF formats, GitHub integration, cron scheduling, and bounded subagent delegation. Per-agent workspaces with durable session storage provide transcript replay, context state management, and per-call cost tracking with automatic quota enforcement. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Laminar
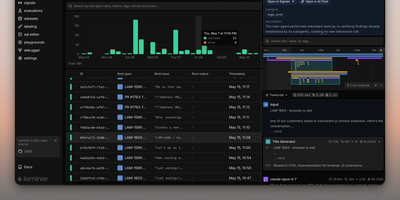
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Farfalle
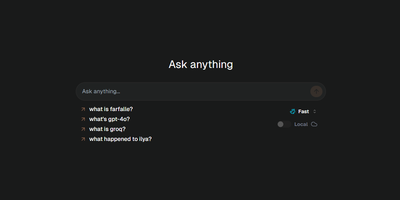
Live web search plus an LLM of your choice: Farfalle is an open-source, self-hosted answer engine in the Perplexity mold. Queries route through one of several search providers - self-hosted SearXNG for a fully independent stack, or Tavily, Serper, and Bing APIs - and the model composes a cited answer from the retrieved results. Model flexibility is the core design: run llama3, mistral, gemma, or phi3 locally through Ollama for zero per-query cost and full privacy, use cloud models like GPT-4o or Groq-hosted Llama 3 for speed, or route to any provider via LiteLLM. An Expert Search mode uses an agent that plans a multi-step search strategy and executes it for harder questions, and chat history keeps prior research sessions available. The stack is a Next.js and shadcn/ui frontend over a FastAPI backend with Redis rate limiting, shipped as a pre-built Docker image. A browser search-engine entry pointing at your instance makes it the default search from the address bar. Paired with SearXNG and Ollama, the whole pipeline runs with no external API at all.
TavernAI
Character-based chat and storywriting with large language models: TavernAI is the open-source frontend that leaves model choice to you. It generates no text itself; it connects to the backend of your choice - OpenAI (including GPT-4), Anthropic Claude, KoboldAI and KoboldCpp, Oobabooga's Text Generation Web UI, NovelAI, Ollama, and the crowdsourced Horde - so cost, model quality, and content policy are decided by your backend, not the interface. Characters are defined by portable card files in PNG or JSON format with personality, scenario, and example dialogue, and tens of thousands of community-made cards from sites like Chub.ai import directly. Conversations support group chats with multiple characters, a story mode for long-form writing, message swiping to branch between alternative responses, and full editing of any message. World Info injects lore into context when keywords trigger, keeping long roleplays consistent. Themes, custom backgrounds, and configurable generation settings round out the interface. It runs on Node.js, and the SillyTavern project began as a fork of it.
ChatChat
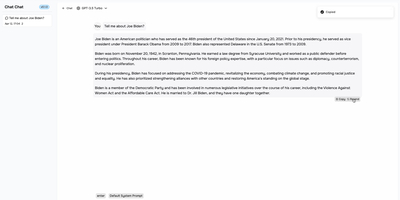
One clean interface in front of Anthropic, OpenAI, Google Gemini, Cohere, and more: Chat Chat is a Next.js front door to the major AI providers, ending the juggling of separate subscriptions, tabs, and UIs per model. Bring your own API keys, pick a provider and model per conversation, and switch between them as the task demands: Claude for long-form reasoning, GPT for code, Gemini for multimodal work - the interface stays identical. Beyond configured presets, custom providers plug in with their own API endpoints and keys, which covers OpenAI-compatible gateways and local inference servers. The design splits into two dedicated modes: a chat interface for conversational work with customizable system prompts, and a search interface that pairs AI processing with query handling for research-style questions. The stack is modern and hackable - Next.js 14, Tailwind CSS, shadcn/ui on Radix primitives, Jotai for state - with full internationalization including English, Chinese, and Japanese. Self-hosting means your conversation history and API keys live on your instance rather than a third-party wrapper service, and pay-per-token API pricing typically beats stacking multiple monthly chat subscriptions. AGPL-licensed and deliberately simple to deploy: one container, environment variables for keys, done.
Dialoqbase
Retrieval-augmented chatbots on your own knowledge base - that is the whole mission of Dialoqbase, an open-source bot-building platform. Feed it content through a broad set of data loaders - web pages and full crawls, sitemaps, PDFs, DOCX, CSV, plain text, GitHub repositories, YouTube videos, and MP3/MP4 audio - and it handles the whole RAG pipeline in one self-contained app: chunking, embedding, vector storage, and LLM querying. The distinguishing architecture choice is PostgreSQL with pgvector for embedding storage and similarity search, which removes the separate vector-database dependency, and Redis-backed Bull queues for ingesting large documents without blocking the API. Model choice is wide open: OpenAI, Anthropic Claude, Google Gemini, Cohere, Fireworks, Hugging Face, local models via Ollama, and any OpenAI-compatible endpoint, with an equally broad list of embedding providers. Finished bots embed on any website with customizable styling or deploy to Telegram, Discord, and WhatsApp, and an API creates and manages bots programmatically. Multi-user support adds registration limits and per-user bot quotas. MIT-licensed and free for commercial use.
LLemonStack
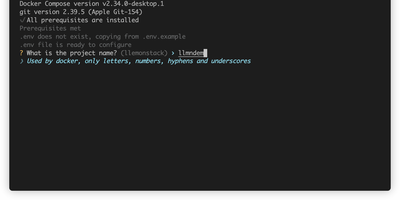
One CLI command deploys a complete AI development environment: n8n, Flowise, Supabase, Ollama, Qdrant, LiteLLM, Langfuse, Open WebUI, LightRAG, Browser-Use, Firecrawl, Crawl4AI, and more, all pre-wired with networking, credentials, and database connections. LLemonStack eliminates the hours of Docker Compose configuration that typically precede any local AI agent project. The llmn CLI initializes isolated project environments with auto-generated secure credentials, starts services in dependency order (databases first, then middleware, then apps), and displays a dashboard showing every service URL and access token. n8n brings 400+ workflow integrations, Flowise provides visual agent building, Ollama runs local LLMs like Llama and Mistral, Qdrant stores vectors at high performance, Open WebUI offers ChatGPT-style model interaction, and LiteLLM proxies requests to any provider with cost tracking. Langfuse automatically logs traces for every LiteLLM query, providing full observability. Each project maintains isolated Postgres schemas preventing data collision across parallel stacks. Firecrawl and Crawl4AI extract web content into LLM-ready formats for RAG pipelines feeding LightRAG or Qdrant. Dozzle streams live container logs for debugging. Import/export tooling migrates workflows between projects with automatic credential reconfiguration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
ScribeWizard
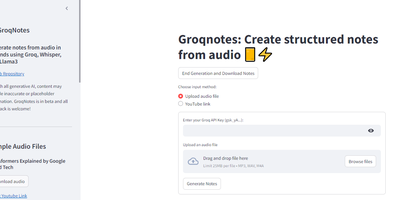
Audio lectures become structured, Markdown-formatted notes in about a minute with ScribeWizard (also known as GroqNotes). Upload an MP3, WAV, or M4A file - or paste a YouTube link - and the app runs a three-stage pipeline on Groq's LPU inference hardware: Whisper Large v3 transcribes the audio, a larger Llama model drafts a comprehensive outline of the material, and a faster Llama model fills each section with detailed content. This scaffolded prompting strategy is the core idea: the strong model handles structure where quality matters most, the fast model handles volume, and Groq's 1200+ tokens-per-second inference keeps the whole process near real time. Output renders as clean Markdown with support for tables and code blocks, and finished notes download as text or PDF. Model selection is configurable - swap in other Groq-hosted open models like Mixtral or Gemma to trade speed against quality or work around rate limits. Built as a single Streamlit app by Benjamin Klieger at Groq, it needs only a Groq API key to run, making it one of the simplest self-hosted AI tools to operate.
DispatchMail
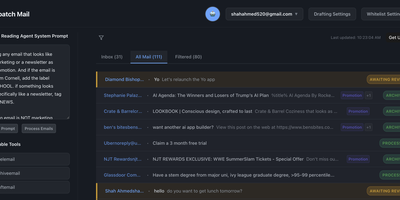
DispatchMail is an SuperHuman alternative and delivers a self-hosted AI email assistant that processes your Gmail inbox through configurable OpenAI prompts without sending data to third-party cloud services beyond the LLM API itself. The Flask backend connects to Gmail via IMAP, retrieves new messages according to your schedule, and routes them through customizable whitelist rules based on sender address, subject keywords, or natural language descriptions before AI processing begins. Two distinct prompt configurations control behavior — the Reading Prompt instructs how the AI should analyze and classify incoming messages, while the Draft Prompt defines how responses should be composed, letting you maintain consistent tone and policy across all automated replies. Whitelist filtering ensures the AI only processes messages you explicitly authorize, preventing unnecessary API costs and keeping sensitive emails out of the LLM pipeline entirely. The React web interface provides inbox management with message previews, AI-generated summaries, draft editing with human-in-the-loop approval before sending, and configuration panels for prompts and rules. Automatic labeling and archival organize processed messages into categories without manual intervention. The sender research feature uses LLM-powered deep analysis to build background profiles of email contacts. All email content, credentials, and processing results persist in a local SQLite database with zero cloud storage dependencies. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.