Chroma
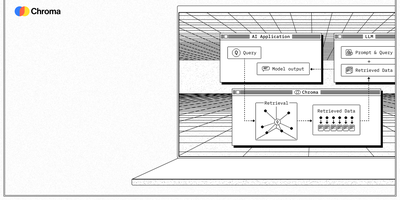
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Label Studio
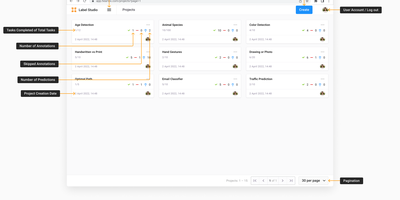
Images, text, audio, video, HTML, PDFs, and time series, labeled in one tool with a standardized output format: Label Studio is the open-source data labeling platform for building training datasets. Computer vision tasks cover classification, object detection (boxes, polygons, ellipses, keypoints), and semantic segmentation; audio work spans transcription, speaker diarization, and emotion recognition; NLP handles named entity recognition and document classification with taxonomies up to 10,000 classes; and GenAI workflows support LLM fine-tuning data and RLHF response ranking. Labeling interfaces are fully configurable with an XML-like templating language, so the UI matches the task instead of the reverse. The ML backend SDK turns any model into a connected web server for pre-annotation (model predicts, humans verify), interactive labeling (real-time predictions as annotators draw regions or highlight text), and model evaluation - cutting annotation time dramatically on large datasets. Data imports from S3, GCS, or file uploads; the Data Manager filters and explores tasks; exports convert to the format your ML library expects via label-studio-converter. Multi-user accounts tie every annotation to its author, and webhooks, a Python SDK, and REST API embed labeling into any pipeline. Self-hosting keeps proprietary training data - often a company's most sensitive asset - entirely on your infrastructure.
Redis
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
SnapOtter
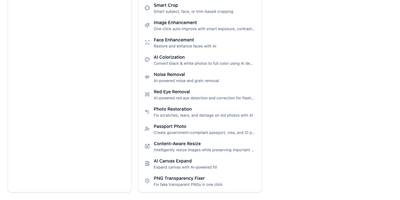
Fifty-plus image processing tools in a single Docker container, with no Redis, no Postgres, and no external dependencies: SnapOtter is a self-hosted image toolkit. The everyday operations are all here: resize, crop, compress, watermark, vectorize, meme generation, GIF creation, and format conversion spanning 55+ input formats (including 23 camera RAW formats) to 14 output formats. What sets it apart is the local AI layer: background removal, photo upscaling and restoration, object erasing, face blurring, OCR, and canvas expansion all run on locally hosted models, so no image ever leaves your server - a hard guarantee that cloud tools like remove.bg or Canva can't make. Optional NVIDIA GPU support accelerates those AI tasks substantially when hardware is available, but everything works on CPU. A built-in layer-based editor handles composition work directly in the browser, and screenshot beautification turns plain captures into polished visuals with backgrounds, shadows, and padding - useful for docs and marketing alike. Batch operations process unlimited images simultaneously, and the full REST API with OpenAPI documentation exposes every tool for pipelines and automations: thumbnail generation on upload, bulk RAW conversion, automated watermarking. For teams processing sensitive imagery or anyone tired of per-image SaaS pricing, SnapOtter replaces a stack of subscriptions with one private container.
OpenDeepWiki
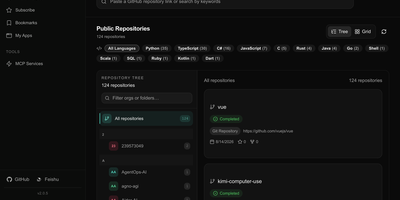
OpenDeepWiki transforms code repositories from GitHub, GitLab, Gitee, Gitea, and AtomGit into structured, searchable knowledge bases by leveraging Microsoft's Semantic Kernel for AI orchestration across OpenAI, Azure OpenAI, Anthropic, and DeepSeek providers. The three-phase Gather-Think-Write pipeline analyzes repository tree structures, generates README summaries, project overviews, wiki catalogs, and document content while producing Mermaid mind maps and optional Graphify visualization artifacts. Repository-scoped MCP endpoints at /api/mcp/{owner}/{repo} expose indexed knowledge to external AI tools, while the built-in chat assistant, embedded chat APIs, and share links provide conversational access to repository understanding. The Next.js 16 frontend serves public documentation on SEO-friendly routes with multi-language translation support, and the admin console manages repositories, users, roles, API keys, AI provider and model configuration, skills, and GitHub App imports. Background workers handle incremental updates using LibGit2Sharp to keep documentation synchronized with evolving codebases, while Polly integration provides transient failure retry handling for LLM requests. The platform supports SQLite, PostgreSQL, and MySQL database backends with Entity Framework Core providers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Zero Email
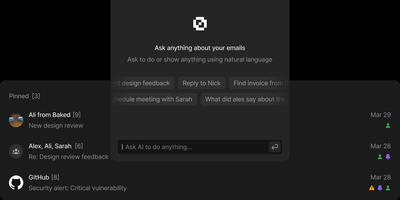
Zero unifies Gmail, Outlook, and IMAP accounts into a single AI-enhanced inbox with keyboard-driven navigation that matches premium email clients in speed. Backed by 10,000+ stars and positioned as the alternative to Superhuman, it keeps your email data in your own PostgreSQL database while LLM agents handle categorization, priority sorting, draft composition, and natural language mailbox queries. You choose whether models run locally or through cloud providers you control. The Next.js and React interface delivers customizable keyboard shortcuts for every action: reading, archiving, labeling, composing. A WorkflowEngine defines automated multi-step rules including label application, bulk archiving, and conditional routing based on sender, subject, or content analysis. Built on Drizzle ORM with Better Auth handling Google OAuth, styled with TailwindCSS and Shadcn UI components, the interface is polished without being bloated. MCP integration exposes email management tools to external AI assistants for programmatic inbox control through standardized protocols. The Nizzy CLI handles environment configuration, database synchronization, and development server orchestration. Deploys via Docker Compose with a single database initialization command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenViking
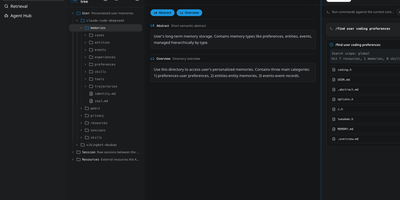
OpenViking is a self-hosted context database that gives AI agents persistent, structured memory by organizing knowledge, skills, and session history into a hierarchical virtual filesystem accessible through the viking:// URI protocol. Instead of dumping everything into a flat vector store and hoping semantic search finds the right chunks, agents navigate their context with familiar commands like ls, tree, and find, locating exactly the information they need through deterministic paths combined with semantic search. Every resource is automatically processed into three layers: a 100-token L0 abstract for quick filtering, a 2,000-token L1 overview for content navigation, and the full L2 detail loaded only when confirmed necessary. This tiered approach cuts token consumption by 83 to 96 percent compared to conventional RAG while improving task completion rates by 15 to 49 percent on benchmark tests. The built-in memory self-iteration loop automatically analyzes task execution and user feedback, updating agent memory directories so the system continuously learns and improves. You can connect to any LLM provider, including Ollama for fully local inference, OpenAI, or compatible gateways. The Web Studio UI at the /studio endpoint provides visual browsing of the entire context filesystem, and the REST API on port 1933 supports programmatic access. Deploy via Docker, Kubernetes with the included Helm chart, or as a standalone service. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
1Panel
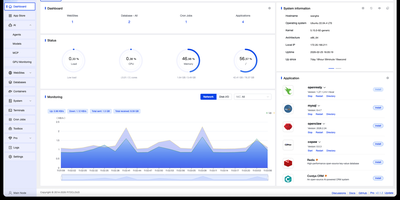
Backed by over 36,000 GitHub stars and 120 contributors with 123 releases since 2022, 1Panel has rapidly become the go-to open-source alternative to cPanel and Plesk for modern Linux server management. The platform delivers a clean Vue.js dashboard powered by a Go backend using the Gin framework, providing visual management of Docker containers, images, networks, and volumes without touching the command line. Its curated app marketplace offers one-click installation of 165+ trusted open-source applications including Nextcloud, Bitwarden, Umami analytics, WordPress, and NocoBase, each running in isolated containers for maximum security. Native AI capabilities set 1Panel apart from every competing panel: deploy Ollama LLMs directly from the dashboard, spin up OpenClaw personal agents, monitor GPU utilization, and manage AI models through a unified interface. Website management includes automatic domain binding, Let's Encrypt SSL certificate provisioning, and Nginx configuration with zero manual setup. Security runs deep with built-in firewall rules, fail2ban integration, container isolation, WAF protection, and comprehensive audit logging enabled from day one. Automated backups support AWS S3, Cloudflare R2, and local storage with one-click restore from any snapshot. The panel supports Debian, Ubuntu, CentOS, and Rocky Linux across x86_64, aarch64, armv7l, ppc64le, and s390x architectures. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Cognee
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Kong
With over 43,000 GitHub stars and adoption by companies including Nasdaq, Samsung, and Expedia, Kong Gateway is the world's most deployed open-source API gateway, processing billions of API requests daily across hybrid-cloud and multi-cloud architectures. Built on the battle-tested NGINX engine with OpenResty's LuaJIT runtime, Kong delivers sub-millisecond proxy latency while supporting REST, gRPC, GraphQL, WebSocket, SOAP, and Kafka protocols. The plugin architecture includes authentication via JWT, Basic Auth, HMAC, key authentication, OAuth 2.0, and LDAP, alongside rate limiting with configurable windows per consumer, IP address, or API key. The AI Proxy plugin provides a universal LLM API that routes across OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure AI, Databricks, Mistral, and Hugging Face through a single standardized interface, while MCP proxy capabilities convert REST APIs into MCP tools and provide traffic governance for AI agents. Kong supports declarative configuration via YAML for GitOps workflows, a RESTful Admin API for dynamic configuration, and decK CLI for version-controlled infrastructure-as-code management. Upstream health checking with active and passive probes enables automatic failover, and the ring balancer distributes traffic across upstream targets with consistent hashing, round-robin, or least-connections algorithms. The Kong Plugin Hub hosts over 100 community and official plugins covering logging, monitoring, transformation, security, and traffic control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Agentic SOC Platform
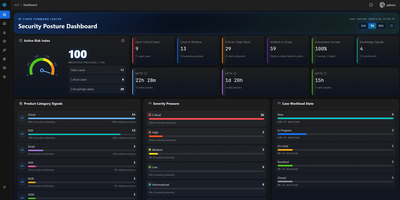
Agentic SOC Platform compresses hours of manual security analysis into seconds by deploying specialized AI agents that autonomously triage, investigate, and enrich security alerts. The Python/Django backend processes SIEM webhooks through Redis Streams into a modular pipeline where LangGraph-orchestrated agents extract IOCs, correlate signals, and generate Cases with severity, confidence, impact, priority, and structured verdicts. The built-in SIRP provides full case management with Alerts, Artifacts, Enrichments, Tickets, and a Knowledge base that accumulates institutional memory for both human analysts and LLM agents. Native Splunk and Elasticsearch/Kibana integrations deliver unified log search through a standardized interface so agents and analysts share identical security context. The playbook engine combines traditional SOAR automation with AI-powered investigation — launching threat hunting agents, knowledge extraction, threat intelligence enrichment, and CMDB lookups from a single orchestration layer. MCP Plugin support exposes ASP capabilities to Claude Code, Codex, and OpenCode, enabling external AI agents to operate cases, search logs, query threat intelligence, and write custom modules directly. Python Modules adapt new alert sources while Playbooks orchestrate LLM analysis and automated response actions, scaling the platform with your security scenarios. Deploy via Docker Compose with all data staying inside your network. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Treg
With over 330 GitHub stars and described as "OpenRouter, but for agent tools instead of models," Treg is the unified tool registry that gives your AI agent one base URL, one token, and instant access to approximately 2,800 cataloged endpoints across 56 providers — SEO and backlink analysis via Semrush and Moz, social media intelligence from TikTok and Instagram, people and company enrichment through Crunchbase and Hunter, media buying, scraping, and SERP data — all priced per call from fractions of a cent with no provider signup required. The FastAPI backend with PostgreSQL stores credential bindings and injects them server-side into every proxied request, ensuring API keys and OAuth tokens never touch the agent or local machine while every call is audit-logged. Teams register their own paid API accounts, OAuth connections, vendor CLIs like Stripe, GitHub CLI, Vercel, and gcloud, plus custom SKILL.md definitions — all callable by every teammate's agent through a single treg token with automatic credential injection. The evidence-based tool selector shows success rate, response speed, and last-seen timestamp for each provider, so agents pick tools on measured performance rather than guesswork. Bring-your-own-key routes bypass metering entirely, and the one-dollar free credit on every new team lets agents start calling immediately. The Vue.js web dashboard provides team management, audit logs, catalog browsing, and guided onboarding. Self-host with pip install tools-registry[server] on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
big-AGI
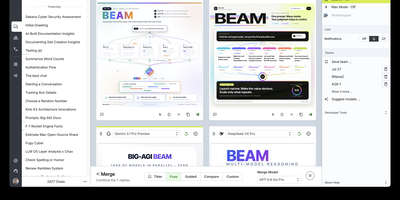
big-AGI is an open-source generative AI workspace that provides a unified, local-first interface for orchestrating multi-model reasoning, automated code execution, and custom persona workflows across private infrastructure. Users query multiple large language models simultaneously through the Beam scatter-gather engine, which prompts independent AI systems in parallel, compares candidate completions side by side, and merges optimal passages into a single refined response. Knowledge workers assemble tailored AI personas equipped with specialized system instructions, custom temperature settings, and predefined document context to handle domain-specific tasks ranging from architectural design reviews to legal contract analysis. The application renders rich multimedia outputs including interactive Mermaid sequence diagrams, LaTeX mathematical formulas, syntax-highlighted code blocks with live execution previews, and AI-generated image generation canvases. Teams integrate local inference servers like Ollama and LocalAI alongside commercial API endpoints to route confidential datasets strictly through internal networks while monitoring per-prompt token usage and operational latency. Users attach complex PDF documents, spreadsheets, and source code repositories for automatic parsing and semantic retrieval, while local-first storage engines ensure private chat transcripts and custom presets remain encrypted on host drives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
New API
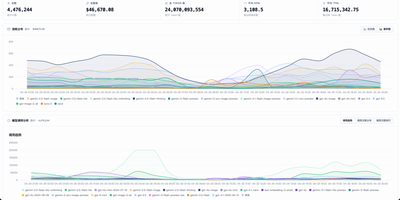
New API is a Go-powered LLM gateway that funnels over 40 AI providers, from OpenAI and Anthropic to Google Gemini, Azure, AWS Bedrock, DeepSeek, and Mistral, through a single OpenAI-compatible endpoint with intelligent routing and enterprise cost controls. Bidirectional format conversion translates between OpenAI Chat Completions, Claude Messages, and Gemini GenerateContent APIs transparently, so clients call any provider using their preferred format while the gateway handles the rest. Routing logic supports weighted random channel selection, priority-based failover, and automatic retry on provider errors to maximize uptime. The React admin dashboard shows usage charts, token consumption tracking, per-model cost breakdowns, and real-time request monitoring. Multi-tenant architecture includes three role levels, token-based authentication, per-user quota management, and a three-phase billing system with tiered pricing via a custom expression language. Multimodal support covers text completion, vision, embeddings, text-to-speech, speech-to-text, image generation, and creative task providers like Midjourney-Proxy and Suno-API. The interface ships in five languages including English, Chinese, Japanese, and French. Docker deployment runs with SQLite or MySQL for persistence. 45,000+ GitHub stars. AGPL-3.0 licensed.
AgentDesk
Most AI chat integrations bolt an LLM onto a text box and call it customer support; AgentDesk builds the entire helpdesk around AI agents that handle first responses, escalate to humans when they cannot answer, and track follow-up work through integrated ticket workflows. Each AI agent binds to a specific LLM configuration, one or more knowledge bases, a set of callable Skills, and MCP tool integrations, creating specialized support personas for different product lines or departments. When a customer message arrives, the agent retrieves relevant FAQ entries and document chunks through RAG-powered vector search (Qdrant), then passes retrieved context through an Answerability Gate that determines whether the knowledge base can support a reliable answer; if not, it triggers a fallback response and recommends human handoff instead of hallucinating. Human agents pick up escalated conversations in a dedicated workspace that preserves the full AI conversation history, customer profile, conversation tags, and linked tickets, so they never start from scratch. The ticket system converts conversations into tracked work items with category assignment, status flows, progress notes, and team routing. An admin dashboard provides user management, role-based access control, team scheduling, and automatic conversation assignment rules. Model configuration supports any OpenAI-compatible provider, letting you wire in LLMs, embedding models, and reranking models with per-model context limits, timeout settings, and rate controls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
LiteLLM
Backed by 56,000+ GitHub stars and over 240 million Docker pulls, LiteLLM delivers the open-source AI gateway trusted by Netflix, Lemonade, Rocket Money, and thousands of engineering teams to route every LLM request through one unified API. The Rust-core gateway adds sub-millisecond overhead per request with 8ms P95 latency at 1,000 RPS, 15x throughput improvement and 11x lower memory footprint compared to Python-only proxies. A single OpenAI-compatible endpoint connects to 100+ providers and 1,800+ models spanning OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure OpenAI, Vertex AI, Hugging Face, vLLM, Nvidia NIM, Ollama, and Mistral with day-zero support for new model releases. The Auto Router V2 classifies request complexity across four tiers using rule-based scoring, semantic keyword matching, and adaptive Thompson sampling to route each request to the most cost-effective model without API calls or training data. Virtual API keys enable multi-tenant governance with per-team, per-user, and per-project cost tracking, budget caps with automatic fallback rerouting, and role-based access control. Built-in guardrails provide PII masking, prompt injection detection, and model-graded evaluation before requests reach providers. The Agent Gateway extends routing from model calls to agent workflows with MCP server integration. Observability integrates with Langfuse, Arize Phoenix, OpenTelemetry, and MLflow for complete request tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Airi
Project AIRI is the most popular open-source AI companion platform — a self-hosted recreation of Neuro-sama that brings AI-powered virtual characters into your world across web, desktop, and mobile. The system renders Live2D, Spine, and VRM 3D character models with auto-blink, eye tracking, and lip-sync driven by real-time voice synthesis, while the xsAI abstraction layer connects to 40+ LLM providers including OpenAI GPT-4, Anthropic Claude, Google Gemini, DeepSeek, and local models via Ollama and OpenRouter. Built from day one on WebGPU, WebAudio, Web Workers, WebAssembly, and WebSocket technologies, the browser version runs entirely client-side with PWA offline support while the server runtime enables persistent memory via PostgreSQL with pgvector embeddings and DuckDB WASM for client-side storage. The Minecraft agent plays autonomously using mineflayer with pathfinding, and a Factorio integration provides cooperative gameplay. Social integrations deploy your companion as a Discord bot joining voice channels, a Telegram bot, and a Twitter/X agent posting and replying autonomously. The desktop Stage Tamagotchi app provides an always-on-screen companion for Windows and macOS, while Stage Pocket brings the experience to mobile. Voice features include client-side speech recognition via VAD, multiple TTS providers including ElevenLabs, and screen vision capabilities. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vane
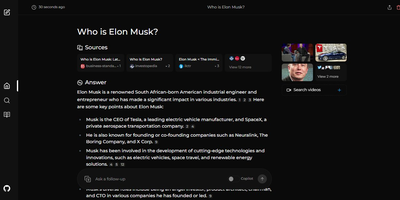
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.