Paperclip
With over 77,000 GitHub stars accumulated in under five months since its March 2026 launch, Paperclip has become the default control plane for teams running multiple AI agents in production. Rather than juggling dozens of terminal tabs with Claude Code sessions, Codex instances, and Gemini CLI workers, Paperclip organizes all agents into a company structure with org charts, reporting lines, role-based permissions, and per-agent monthly budgets that trigger hard-stops when exceeded. The platform supports any runtime through its adapter system — Process adapters manage local CLI agents like Claude Code, Codex, Cursor, Pi, and OpenCode as child processes, while HTTP adapters trigger remote agents via webhooks to OpenClaw, serverless platforms, or custom endpoints. Heartbeat-based execution wakes agents on configurable schedules, injecting goal context, budget state, and workspace paths directly into the invocation payload. The Work and Task System provides atomic checkout with execution locks, first-class blocker dependencies, and structured work products to eliminate duplicate effort. Governance features include approval workflows, decision tracking, emergency stops, and full audit trails tracing every mutation to an actor. Deployment runs as a single Node.js process with embedded PostgreSQL locally or scales to external Postgres for production, installable in one command via npx paperclipai onboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenSearch
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Vane
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
Letta
With over 24,000 GitHub stars and origins in the MemGPT research paper on virtual context management, Letta has evolved into the leading open-source platform for building AI agents that maintain persistent memory, identity, and continuity across sessions rather than operating as stateless prompt-response loops. The core architecture uses memory blocks — structured, labeled text chunks that reside permanently in the agent's context window — allowing agents to programmatically rewrite their own memory, learn new skills, and improve through a sleeptime dreaming process that runs reflection and memory organization during idle periods. The self-hosted App Server deploys via Docker and exposes a WebSocket API on port 4500, letting the TypeScript Agent SDK connect from any application using local, remote, or cloud backends. Agents support git-versioned memory through MemFS where every memory change is tracked and auditable, multi-agent communication via subagents, scheduled tasks, and integration with messaging platforms including Slack, Discord, Telegram, WhatsApp, and Signal. The platform is fully model-agnostic, routing to OpenAI, Anthropic, xAI, or self-hosted open-weight models through Ollama depending on cost, performance, and data residency requirements. The Agent File format serializes complete agent state — memory, skills, prompts, and conversation history — into portable snapshots. Desktop applications for macOS, Windows, and Linux provide native interfaces alongside the terminal CLI and web chat at chat.letta.com. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Forge
Forge intercepts failing LLM tool calls and fixes them before they derail your agent workflow, applying rescue parsing, retry nudges, response validation, and step enforcement between your AI clients and local model backends. The proxy server mode drops in as a transparent intermediary speaking both the OpenAI chat-completions API and the Anthropic Messages API, so tools like Aider, Claude Code, Continue, and opencode connect through it without configuration changes. Under the hood, the WorkflowRunner provides a complete agentic loop manager with system prompt injection, tool execution, context compaction with configurable thresholds, and VRAM budgeting for consumer GPUs with 12-32 GB. SlotWorker enables priority-queued access to shared inference slots with automatic preemption for multi-agent architectures. The guardrails middleware exposes a two-method check-and-record API that wraps into any existing orchestration loop, providing malformed tool-call rescue parsing, retry nudge generation, required step enforcement, and prerequisite ordering without taking over execution control. Backend adapters support generic OpenAI-compatible endpoints, Ollama, llama-server, Llamafile, vLLM, and Anthropic with automatic model discovery and health checking. Architecture Decision Records document every design choice. Launched February 2026, already at 2,200+ GitHub stars. MIT licensed.
BitRouter
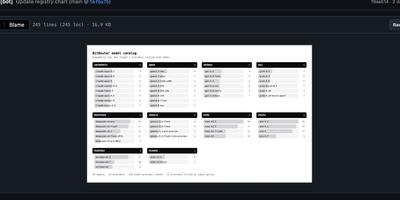
BitRouter is a context-aware LLM router that learns which model delivers the cheapest successful outcome per workflow step, cutting agent costs by up to 80% while maintaining 96% quality versus all-frontier baselines. Point any agent runtime at http://localhost:4356 with a one-line OPENAI_BASE_URL change and BitRouter routes to OpenAI, Anthropic, Google, Groq, DeepSeek, Mistral, Moonshot, MiniMax, Nvidia, and any OpenAI-compatible endpoint simultaneously, normalizing authentication, streaming, and cross-protocol translation between wire formats. The act-observe-evaluate-learn loop traces every hop with cost, tokens, and latency attribution, scores each decision against a versioned policy-lock.yaml, then tightens routes automatically with no LLM judge in the path. Native MCP gateway auto-discovers tools from connected servers and makes them routable and governed alongside model calls. Agent Client Protocol integration enables the TUI to manage Claude Code, Codex, OpenCode, OpenClaw, Gemini, and Copilot sessions in real time with inline tool-call approval and live streaming. Built-in guardrails inspect, redact, or block risky content before requests leave your network. Virtual keys scope API access per agent or user without exposing upstream credentials. Per-agent spend caps and loop guards contain runaway cost automatically. Multi-account failover reroutes mid-run so rate limits never re-pay completed work. Ships as a single Rust binary via npm or Cargo. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Label Studio
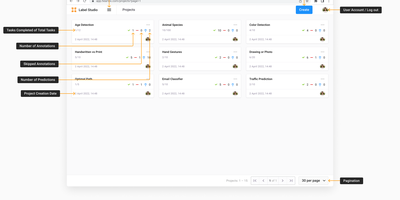
Images, text, audio, video, HTML, PDFs, and time series, labeled in one tool with a standardized output format: Label Studio is the open-source data labeling platform for building training datasets. Computer vision tasks cover classification, object detection (boxes, polygons, ellipses, keypoints), and semantic segmentation; audio work spans transcription, speaker diarization, and emotion recognition; NLP handles named entity recognition and document classification with taxonomies up to 10,000 classes; and GenAI workflows support LLM fine-tuning data and RLHF response ranking. Labeling interfaces are fully configurable with an XML-like templating language, so the UI matches the task instead of the reverse. The ML backend SDK turns any model into a connected web server for pre-annotation (model predicts, humans verify), interactive labeling (real-time predictions as annotators draw regions or highlight text), and model evaluation - cutting annotation time dramatically on large datasets. Data imports from S3, GCS, or file uploads; the Data Manager filters and explores tasks; exports convert to the format your ML library expects via label-studio-converter. Multi-user accounts tie every annotation to its author, and webhooks, a Python SDK, and REST API embed labeling into any pipeline. Self-hosting keeps proprietary training data - often a company's most sensitive asset - entirely on your infrastructure.
LibrePhotos
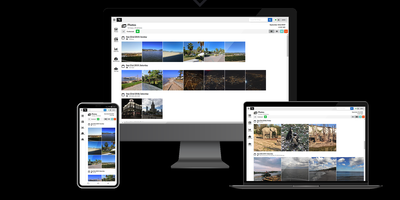
With over 8,000 GitHub stars and continuous development since 2020, LibrePhotos delivers the core intelligence of Google Photos — face recognition, object detection, semantic search, and automatic album generation — entirely on your own hardware without sending a single photo to a third-party server. The Django 5 backend processes uploaded media through a machine learning pipeline that runs face detection via the face_recognition library, clusters identified faces using scikit-learn and HDBSCAN, generates image captions through BLIP and Moondream 2, and classifies scenes using Places365 or Google's SigLIP 2 vision-language model with zero-shot classification against 900+ real-world tags. Semantic search lets you find photos by natural language queries like "sunset at the beach" without manual tagging, while metadata search filters by person, camera, lens, file type, and filesystem path. The React 18 frontend built with Vite presents a timeline view, fullscreen lightbox with slideshow mode, photo detail sidebar showing location and people, and a folder navigation view with breadcrumb paths. RAW files from any camera are converted via ImageMagick, videos processed through FFmpeg, and Live Photos paired with their RAW+JPEG counterparts as unified entries. Public album sharing via link provides fine-grained privacy controls, and duplicate detection uses perceptual hashing to identify near-identical images. Deployment runs as a single unified Docker container or via Docker Compose with Kubernetes manifests also available. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Chatterbox TTS
With 26,000 GitHub stars and consistent victories over ElevenLabs in blind evaluations, Chatterbox delivers state-of-the-art text-to-speech with zero-shot voice cloning requiring only 5 seconds of reference audio. The model family spans three architectures: Chatterbox Multilingual V3 (500M parameters, 23+ languages including Arabic, Chinese, Japanese, Korean, Hindi, French, German, Spanish, and Portuguese), Chatterbox-Turbo (350M parameters optimized for voice agents with a single-step distilled decoder achieving ~200ms time-to-first-speech), and Chatterbox-Nano (110M parameters running 3x faster than realtime on 8 CPU cores for edge deployment). Unique among open-source TTS systems, Chatterbox introduces emotion exaggeration control — adjusting intensity from monotone to dramatically expressive via a single parameter — and native paralinguistic tagging where tokens like [laugh], [cough], [chuckle], and [gasp] inject natural vocal reactions inline without post-processing. The alignment-informed inference pipeline eliminates hallucinations and repetition artifacts common in autoregressive TTS. Built-in PerTh neural watermarking embeds imperceptible forensic identifiers in generated audio for provenance tracking. Trained on 500,000 hours of cleaned speech data across all supported languages. Voice conversion scripts enable transforming existing audio into any cloned voice. Deploy via pip install with PyTorch, serve through Gradio interfaces or custom FastAPI endpoints, and expose via HTTP streaming or WebSocket for sub-200ms conversational applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Farfalle
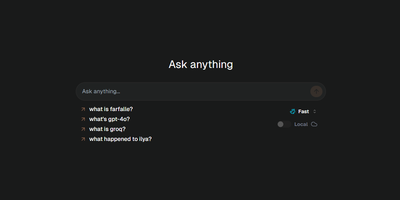
Live web search plus an LLM of your choice: Farfalle is an open-source, self-hosted answer engine in the Perplexity mold. Queries route through one of several search providers - self-hosted SearXNG for a fully independent stack, or Tavily, Serper, and Bing APIs - and the model composes a cited answer from the retrieved results. Model flexibility is the core design: run llama3, mistral, gemma, or phi3 locally through Ollama for zero per-query cost and full privacy, use cloud models like GPT-4o or Groq-hosted Llama 3 for speed, or route to any provider via LiteLLM. An Expert Search mode uses an agent that plans a multi-step search strategy and executes it for harder questions, and chat history keeps prior research sessions available. The stack is a Next.js and shadcn/ui frontend over a FastAPI backend with Redis rate limiting, shipped as a pre-built Docker image. A browser search-engine entry pointing at your instance makes it the default search from the address bar. Paired with SearXNG and Ollama, the whole pipeline runs with no external API at all.