Rancher
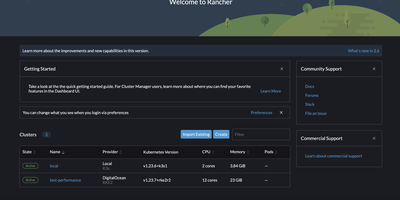
Used by over 30,000 teams and 650+ enterprise customers managing more than 5.2 million containers, Rancher has earned recognition as a Leader in the Gartner Magic Quadrant for Container Management and the Forrester Wave for Multicloud Container Platforms. The platform provides a single pane of glass for provisioning, upgrading, and securing Kubernetes clusters across Amazon EKS, Google GKE, Microsoft AKS, RKE2, K3s, and any CNCF-conformant distribution. Multi-Cluster Management enables centralized authentication via Active Directory, LDAP, SAML, GitHub, and OpenID Connect with granular role-based access control at the cluster, project, and namespace levels. Fleet, the built-in GitOps engine, delivers continuous deployment across hundreds of clusters simultaneously using Helm charts, Kustomize, or raw YAML manifests from any Git repository. The integrated app catalog provides one-click deployment of Prometheus monitoring, Grafana dashboards, Longhorn persistent storage, Istio service mesh, and hundreds of community Helm charts. Rancher supports air-gapped installations for disconnected environments, CIS benchmark scanning for security compliance, and automated backup and restoration of cluster configurations. The dashboard offers real-time workload monitoring, log aggregation, pod shell access, and namespace-scoped resource quotas. Cluster templates enforce organizational standards through Helm-based provisioning policies that ensure consistent configurations across environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Open Connector
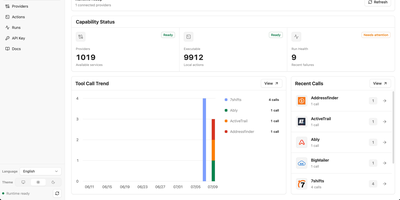
With over 5,000 GitHub stars since its June 2026 launch, OOMOL OpenConnector bridges the gap between AI agents and the real world by handling the authentication nightmare that stops LLMs from calling external APIs safely. The runtime connects to more than 1,000 SaaS providers — GitHub, Gmail, Notion, Slack, Microsoft, HubSpot, Google Workspace, and hundreds more — through 10,000+ prebuilt typed Actions that agents can discover and execute without ever touching raw credentials. OAuth2 flows, API key rotation, custom credentials, and no-auth providers are all managed centrally with AES-encrypted storage, scoped runtime tokens, and configurable action allowlists and blocklists that enforce least-privilege access. Agents interact through five access surfaces: the Model Context Protocol endpoint at /mcp for Claude and other MCP-capable hosts, a full REST API at /v1 for programmatic control, an auto-generated OpenAPI specification for code generation, a TypeScript SDK for application integration, and the oo CLI for local agent relay. The built-in Web Console provides browser-based administration for configuring OAuth apps, managing connections, inspecting action schemas, and reviewing execution logs with redacted inputs. Deploy via Docker Compose with SQLite for single-server setups, run from source on Node.js 22+, or push to Cloudflare Workers with D1 and R2 for edge deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Knowhere
With 2,600+ GitHub stars since its May 2026 open-source launch, Knowhere solves the last-mile problem of document intelligence for AI systems — transforming complex unstructured PDFs, reports, and multi-page documents into structured JSON chunks that LLMs can consume without hallucination. The platform processes documents through an AI-native parsing pipeline that handles 20+ page documents with deep hierarchies, intricate tables, and multimodal content including images with OCR, achieving 95% precision in information extraction while reducing token costs by 50% compared to raw document ingestion. The knowledge tree architecture maintains historical context across multiple documents, enabling cross-document graph navigation for agentic retrieval that goes beyond simple chunk-based RAG. Built on Python 3.11+ with MinerU as the default PDF parser, the backend API runs alongside async workers that process document ingestion, graph construction, and embedding generation. The self-hosted Docker Compose stack packages the API server, processing workers, and Next.js dashboard for managing API keys, webhooks, and document-processing jobs, backed by PostgreSQL and Redis. Both Python and Node.js SDKs provide programmatic access for integration into existing AI pipelines and agent frameworks. LLM providers include DeepSeek and Alibaba Cloud DashScope with configurable key rotation for rate-limit management. Deploy on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Arkon
With 1,200+ GitHub stars since its April 2026 launch, Arkon provides an enterprise-grade knowledge management layer that turns scattered organizational documentation into AI-accessible structured context. The platform runs as a centralized MCP server, compiling your SOPs, policies, technical docs, and institutional knowledge into a versioned wiki with draft-approval workflows, then serving that wiki to Claude Desktop, Claude.ai, Cursor, and any MCP-compatible client through a single permission-scoped endpoint. OAuth 2.1 with PKCE authentication eliminates manual token management — employees authenticate through a browser login while the system discovers endpoints automatically via RFC 8414. The RBAC v2 system supports custom roles with granular permissions, department-scoped AI Skills, workspace isolation, and comprehensive audit logging so every query and access event is traceable. RAG retrieval powered by pgvector embeddings enables AI clients to search across all organizational documents with source attribution, while the AI Skills system lets teams define reusable instruction sets scoped to specific departments or roles. The architecture runs seven Docker containers coordinated by Compose: PostgreSQL with pgvector for embeddings and metadata, Redis for caching, MinIO for document storage, a FastAPI backend, two ARQ async workers for embedding generation and document processing, and a Next.js frontend portal accessible on port 3119. API keys are encrypted at rest with Fernet, and no telemetry leaves the deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PolyForm Internal Use licensed.
Rivet
Stateful serverless actors that run indefinitely, sleep when idle, and persist state across restarts without external database round trips. Rivet provides a vendor-neutral alternative to Cloudflare Durable Objects, delivering long-running processes with co-located in-memory state and per-actor SQLite databases on any infrastructure you choose. The Rust engine comprises four packages: Pegboard for actor orchestration, Gasoline for durable execution, Guard for traffic routing via Envoy, and Epoxy implementing multi-region KV storage through EPaxos consensus. Each actor maintains instant-access in-memory state plus a dedicated SQLite database for relational queries, backed by RocksDB on single nodes or PostgreSQL with NATS pub/sub for multi-node clusters. RivetKit SDKs in TypeScript, Rust, and Python support built-in WebSocket connections, task queues, scheduling, and CRDT-based real-time collaboration. The v2.3 rewrite moved the core runtime from JavaScript to native Rust via WebAssembly, eliminating main-thread blocking across Node.js, Bun, Deno, and Cloudflare Workers. A built-in dashboard provides actor inspection with real-time Prometheus metrics. Deploys as a single Docker container on port 6420 with optional PostgreSQL for persistence. Available on RepoCloud with a dedicated VPS under the Apache 2.0 license.
xyOps
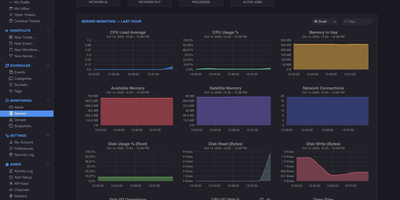
With 4,500+ GitHub stars and version 1.0.92 released August 2026, xyOps delivers a complete operations platform that unifies workflow automation, job scheduling, server monitoring, alerting, and incident response in one self-hosted system. The platform uses a distributed architecture where a central conductor coordinates lightweight xySat satellite agents running on Linux, macOS, or Windows worker nodes via persistent WebSocket connections. The visual workflow builder lets you chain events, triggers, actions, and monitors into multi-step pipelines with conditional logic, fan-out/fan-in parallelism, multiplex controllers for fleet-wide execution, and configurable resource limits. QuickMon provides per-second CPU, memory, disk, and network visibility streamed live to the web UI, while user-defined monitor plugins sample metrics every minute with time-series storage at hourly, daily, monthly, and yearly resolutions. Alert triggers evaluate expressions against live data and fire notifications via email, webhook, or custom actions, with full server snapshots attached showing every running process, network connection, and resource utilization at the moment of detection. Failed jobs and alerts automatically create tickets with linked logs, metrics history, and context for end-to-end incident tracking. The plugin marketplace supports extensions written in any language, and the Docker plugin enables container-based job execution. Deploy via Docker with persistent volumes on port 5522 for the web UI and 5523 for API access, running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD-3-Clause licensed.
OpenStatus
Trusted by Cal.com, WhiteBIT, and Documenso and backed by 8,800+ GitHub stars, OpenStatus delivers the open-source status page and uptime monitoring platform that replaces Atlassian Statuspage, Better Stack, and Instatus with a single self-hosted deployment. The monitoring engine runs Go-based probes across 28 global regions on three cloud providers checking HTTP, TCP, and DNS endpoints in parallel with configurable intervals and multi-region consensus to eliminate false-positive alerts. Status pages ship with custom domain support, password and email-domain access controls, maintenance windows, grouped monitor components, and subscriber notifications via email and RSS. Incident management provides structured status reports with investigating, identified, monitoring, and resolved timeline phases that publish automatically to affected status pages. The monitoring-as-code workflow supports YAML configuration synced through the CLI, a GitHub Actions integration for CI/CD pipelines, and a Terraform provider for infrastructure-as-code deployments. The typed ConnectRPC JSON-over-HTTP API exposes a published OpenAPI specification with a Node SDK for programmatic access, while an MCP server connects AI assistants like Claude, ChatGPT, and Cursor directly to workspace data. The tech stack combines Next.js with shadcn/ui for the dashboard, Hono for the API server, Drizzle ORM over Turso for application data, and Tinybird for analytics. Private monitoring locations deploy as a single 8.5MB Docker image behind firewalls to check internal services. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
AKB
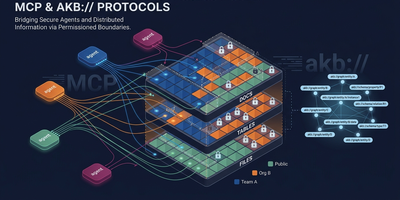
Achieving 98.4% Recall@5 on LongMemEval-S without a reranker, AKB is the agent-native knowledge infrastructure giving Claude Code, Cursor, Windsurf, and any MCP-aware agent persistent organizational memory — a drop-in replacement for Confluence or Notion where AI agents read and write directly rather than scraping human-formatted pages. Documents are stored as Markdown with YAML frontmatter in Git bare repositories (full version history, branching, diff), while PostgreSQL 16 serves as source of truth for chunk text, metadata, and BM25 vocabulary, with dense embeddings handled by a pluggable vector store (pgvector default, Qdrant optional, or managed Seahorse). Agents interact through 20+ MCP tools — akb_put, akb_search, akb_browse, akb_relations, akb_sql, akb_edit, akb_history — performing hybrid dense plus BM25 search fused via Reciprocal Rank Fusion in one call. The URI graph (depends_on, related_to, implements relations) lets agents traverse knowledge connections without external graph databases. Multi-tenant vault isolation is enforced at the PostgreSQL ACL level with per-user roles and SET LOCAL ROLE for SQL sandboxing. Event fanout streams structured events to Redis Streams for external consumers (synthesis bots, digest agents, audit trails), and a hash-chained append-only audit log integrates with enterprise SIEMs. Ships with agent plugins for Claude Code and Codex (session capture, wiki ingest, lifecycle hooks), Kubernetes kustomize manifests, and Open Knowledge Format export. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed (free under 100 seats, auto-converts to Apache 2.0 after four years).
Kubero
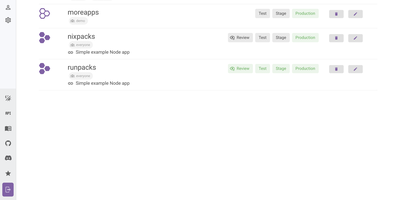
With over 4,300 GitHub stars and a v3 release adding built-in user management, team views, and multi-language support, Kubero has established itself as the most feature-complete open-source Heroku alternative running natively on Kubernetes. The platform operates as a Kubernetes operator with two containers — kubero-ui and the operator — storing all state in etcd without an external database. Developers push code via Git integration with GitHub, GitLab, Bitea, or Gitea, and Kubero automatically builds using Buildpacks, Nixpacks, Runpacks, or Dockerfiles, then deploys to the configured domain with SSL via cert-manager. CI/CD pipelines support up to four staging environments — review, test, staging, and production — with per-stage environment variable isolation and ephemeral review apps that spin up on pull request open and tear down on close. The template catalog includes over 170 pre-configured applications like WordPress, Grafana, and PostgreSQL deployable in one click, while managed add-ons provide highly available PostgreSQL, Redis, MySQL, Kafka, CouchDB, Elasticsearch, and MongoDB alongside your applications. Security features include Trivy vulnerability scanning, GitHub and OAuth2 single sign-on, basic auth, and a role-based permission system with API tokens. The NestJS backend with Vue.js and Vuetify frontend provides application metrics, real-time logs, a built-in web console for container access, scheduled cronjob management, and deployment notifications via Discord, Slack, or webhooks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
DragonflyDB
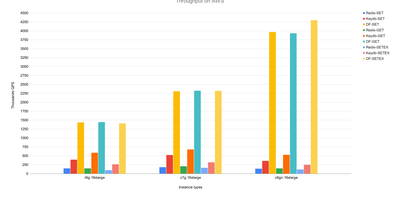
With over 30,000 GitHub stars and benchmarks showing 25x the throughput of single-threaded Redis, DragonflyDB is a modern in-memory data store that eliminates the need for complex Redis Cluster deployments by fully utilizing every CPU core on a single machine. Its shared-nothing, thread-per-core architecture written in C++ supports over 200 Redis commands and 13 Memcached commands, making it a true drop-in replacement that requires zero application code changes. A single DragonflyDB instance scales vertically from 8GB to 768GB of RAM across up to 64 cores, replacing entire Redis Cluster topologies with one process while maintaining full compatibility with Strings, Hashes, Lists, Sets, Sorted Sets, Streams, JSON, and Bloom Filters. The novel dashtable data structure and cache eviction algorithm achieve higher hit rates than LRU and LFU with zero memory overhead per entry. Forkless point-in-time snapshotting eliminates the memory spikes associated with Redis BGSAVE, while automatic backup scheduling via cron syntax supports both local disk and AWS S3 cloud storage. Primary-replica replication follows the Redis replication protocol up to version 6.2, and Prometheus-compatible metrics at the default port enable Grafana monitoring dashboards out of the box. DragonflyDB also exposes an HTTP admin interface on its main TCP port for operational monitoring. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed.
HashiCorp Consul
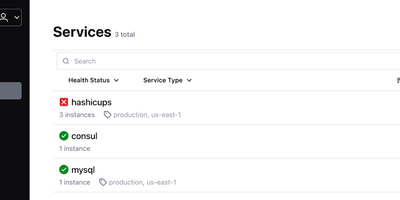
With nearly 30,000 GitHub stars and deployment across organizations including Criteo, Pandora, and Barclays, HashiCorp Consul is the industry-standard platform for service discovery, service mesh, and distributed configuration across dynamic multi-cloud and multi-datacenter infrastructure. Services register themselves and become discoverable via a built-in DNS interface on port 8600 or an HTTP API on port 8500, with health checks ensuring only healthy instances receive traffic through automatic catalog deregistration and service-level circuit breaking. The service mesh capabilities use Envoy sidecar proxies with Transparent Proxy mode to establish automatic mTLS encryption for all service-to-service communication, while identity-based intentions define fine-grained authorization rules controlling which services can communicate. The integrated API Gateway manages north-south traffic into the mesh with configurable routing rules, TLS termination, and header-based matching policies. Consul's distributed key-value store provides hierarchical configuration storage accessible via CLI, HTTP API, and the built-in web UI, with blocking queries enabling watch-based configuration updates without polling. Multi-datacenter federation connects Consul clusters across regions through WAN gossip and RPC forwarding, enabling cross-datacenter service discovery and failover with configurable prepared queries. The Raft consensus protocol provides strong consistency for the service catalog and KV store, with anti-entropy mechanisms ensuring agent state converges with the server catalog. Consul integrates natively with Kubernetes via Helm charts with automatic sidecar injection, Nomad for workload orchestration, Vault for secrets management, and Terraform for infrastructure provisioning. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BUSL 1.1 licensed.
Cockpit
Cockpit puts Linux server administration in a web browser, rendering storage, networking, containers, and virtual machines as visual panels you click through instead of command-line syntax you memorize. It ships in every major Linux distribution and activates through systemd socket activation, consuming zero resources until someone connects on port 9090. What makes it different from other admin panels: every change through the web interface appears instantly at the command line, and every terminal change reflects in the browser in real time. No abstraction layer sits between the UI and the operating system, which means no configuration drift. Storage management covers disk partitioning, RAID arrays, LUKS encryption, LVM volumes, and NFS shares. Network configuration handles bonds, bridges, VLANs, and firewall zones through visual editors. Native Podman integration pulls images, creates containers, manages pods, and provides terminal access into running processes. KVM/libvirt support handles VM creation, cloning, snapshots, and live migration with console access. A built-in terminal provides shell access when the web interface is not enough, and the journal viewer filters systemd logs by severity and unit. Multi-server management connects additional hosts over SSH, presenting a unified dashboard across your entire infrastructure from one browser tab. Runs on a dedicated RepoCloud VPS with full root SSH access and browser serial console. LGPL licensed.
Mail-in-a-Box
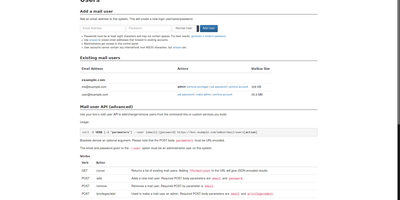
Mail-in-a-Box turns a single Ubuntu server into a fully functional email system with one setup command, installing and configuring Postfix for SMTP, Dovecot for IMAP, Roundcube for webmail, and Z-Push for Exchange ActiveSync push notifications in an automated sequence that would take days to replicate manually. The DNS server auto-configures the full suite of email authentication records: SPF, DKIM, DMARC, DNSSEC with DANE TLSA, MTA-STS, and SSHFP. Getting all of these right is what separates email that lands in inboxes from email that lands in spam, and most manual installations never achieve the complete set. Nextcloud integration adds CardDAV contact sync and CalDAV calendar sharing across devices. Let's Encrypt certificates provision and renew automatically for every hosted domain. The web control panel manages users, aliases, custom DNS records, and automated backups, protected by TOTP two-factor authentication. Daily health checks verify that services run correctly, ports remain open, TLS certificates stay valid, and DNS records resolve properly, alerting you before delivery problems develop. Multiple domains and users operate from one installation with internationalized domain name support. Built-in HTTPS static site hosting uses the TLS infrastructure already in place. Runs on a dedicated RepoCloud VPS with guaranteed resources, root SSH, and browser serial console for complete email sovereignty. CC0 public domain licensed.
Netdata
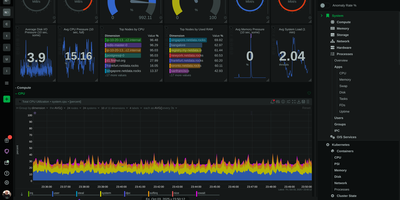
Trusted by millions of engineers and deployed on over 80,000 GitHub stars worth of community confidence, Netdata delivers true real-time monitoring at per-second granularity — 10-60x faster than Prometheus, Datadog, or any conventional monitoring stack that averages away the transient anomalies lasting 2-10 seconds where most production incidents originate. A single installation command deploys the agent with zero configuration, automatically discovering every running process, container, systemd service, network connection, disk, and application on the host within seconds. Unsupervised machine learning trains multiple models per metric directly at the edge, detecting anomalies without thresholds, baselines, or manual tuning. The distributed Parent-Child architecture scales horizontally from a single Raspberry Pi to fleets exceeding 100,000 nodes while maintaining sub-2-second visualization latency and storing metrics at approximately 0.5 bytes per sample through tiered compression. Native network monitoring provides live topology maps, NetFlow and sFlow analytics, SNMP device polling across 200+ profiles, and trap handling — capabilities that typically require a separate NPM product. Hundreds of pre-configured alerts cover systems and applications out of the box, with AI-powered root cause analysis surfacing correlated metrics through natural language via MCP-compatible AI assistants. The agent supports Linux, macOS, FreeBSD, Kubernetes, and Docker with eBPF-based kernel observability requiring no application instrumentation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL v3+ licensed.
Neon
Neon reimagines PostgreSQL with a serverless architecture that decouples storage from compute, enabling instant copy-on-write database branching, autoscaling under load, and scale-to-zero when idle with sub-second cold starts. The lakebase architecture distributes durability across three layers: stateless compute nodes running unmodified PostgreSQL, safekeepers providing Paxos-based WAL quorum replication, and a pageserver that materializes pages on demand while offloading immutable history to S3-compatible object storage via MinIO or AWS S3. Copy-on-write branching creates full database clones as metadata operations without duplicating data, enabling developers to spin up isolated test environments, run parallel CI/CD pipelines, or recover from data loss through point-in-time restore across the configurable history window. Autoscaling dynamically adjusts CPU and memory based on live traffic without manual capacity planning, while scale-to-zero ensures costs drop to storage-only during idle periods. Neon maintains 100% PostgreSQL compatibility with broad extension support including PostGIS, pg_cron, pgvector, pg_stat_statements, and hundreds more, so existing applications connect with standard PostgreSQL drivers and ORMs unchanged. The API-first control plane enables programmatic provisioning, branch management, and multi-tenant fleet operations for platform builders and AI agent integrations. Acquired by Databricks in May 2025 and backed by over 22,800 GitHub stars. Deploys via Docker Compose with pageserver, safekeepers, storage broker, and compute nodes backed by MinIO object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Backstage
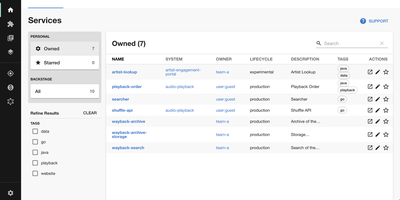
Adopted by over 3,400 companies and backed by 34,000 GitHub stars, Backstage is the open-source developer portal framework created by Spotify and now hosted by the Cloud Native Computing Foundation. The centralized Software Catalog registers every service, library, data pipeline, website, and ML model in your organization using YAML metadata files stored alongside code in GitHub, GitHub Enterprise, or GitLab, tracking ownership, lifecycle status, and dependency relationships across your entire ecosystem. Software Templates provide self-service infrastructure provisioning where developers fill out a form and Backstage automatically scaffolds new repositories, CI/CD pipelines, and cloud resources following your organization's standardized best practices. TechDocs renders Markdown documentation directly alongside the services it describes using a docs-like-code approach powered by MkDocs, with the TechDocs Addon Framework for extending the reading experience. The Search Platform indexes content across the catalog, TechDocs, Confluence, and Stack Overflow through configurable search backends. Kubernetes monitoring built specifically for service owners rather than cluster admins displays pod health, logs, and deployment status across any cloud provider or managed Kubernetes service. The plugin ecosystem includes over 230 open-source integrations covering CI/CD systems like GitHub Actions and GitLab Pipelines, monitoring platforms like Datadog and Grafana, cloud providers including AWS and Azure, plus specialized plugins for security scanning, cost management, API documentation, PagerDuty incident management, and Lighthouse website auditing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
VictoriaMetrics
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Thumbor
Born at Brazilian media giant Globo.com, Thumbor answers imaging CDNs like Imgix and Cloudinary with an HTTP service where every image variant is just a URL. Ask for /300x200/smart/your-image.jpg and Thumbor fetches the original, crops and resizes on demand, and caches the result - one source file, unlimited renditions, no batch pre-generation pipeline. The "smart" in the URL is the signature feature: OpenCV-based face detection finds people in the frame and crops around them (no more thumbnails with severed heads), and when no faces exist, feature detection finds visually important corners and computes a weighted center of mass as the focal point. Beyond cropping, a chainable filter pipeline handles brightness, contrast, grayscale, blur, red-eye removal, rounded corners, rotation, watermarks, and format conversion with quality control - applied in order via URL segments. All common image formats work out of the box, and every layer is pluggable: loaders (HTTP, local, S3), storages and result storages (local, S3, Ceph, and community backends), engines, optimizers, filters, and even custom detectors, with the awesome-thumbor list cataloging the ecosystem. URL signing prevents abuse of your processing capacity. Integrations exist for Django, Rails, Node, WordPress, and most frameworks. MIT-licensed, battle- tested for over a decade.