Undb
Undb turns a browser tab into a full-featured database with spreadsheet-style editing, auto-generated REST APIs, and five configurable views for every table. The platform organizes data through Spaces, Bases, and Tables, offering grid view for traditional editing, Kanban boards for workflow tracking, calendar for date-based planning, gallery for image-rich records, and pivot tables for analytical summaries, each with independent filtering, sorting, color coding, and field selection. An ANTLR4-powered formula engine provides Airtable-style calculated fields with proper syntax validation, variadic argument handling, and type-checked function signatures that go beyond simple string interpolation. Every table automatically generates a fully documented OpenAPI REST endpoint with Swagger UI, letting developers integrate Undb data into external applications through standard HTTP methods without additional configuration. The Drizzle ORM abstraction layer supports four database backends (SQLite, PostgreSQL, MySQL, and Turso edge-distributed SQLite) with separate migration configurations for each adapter. Authentication uses Lucia with OAuth2 via Arctic for GitHub login and Oslo for TOTP two-factor authentication. The SvelteKit 5 frontend renders through Houdini's compile-time GraphQL client and TanStack Svelte Query, while the Elysia.js backend compiles into a single executable via Bun's --compile flag, embedding all assets into one portable binary. File attachments store in any S3-compatible backend including MinIO. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Databasus
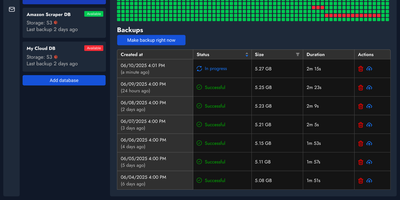
With over 7,500 GitHub stars and 1 million Docker pulls — making it the most popular open-source database backup tool on GitHub ahead of pgBackRest and WAL-G — Databasus delivers production-grade backup management through a designer-polished web interface that replaces complex configuration files and CLI-only workflows. The platform supports PostgreSQL 14-18, MySQL 5.7-8, MariaDB 10-12, and MongoDB 4.2-8 with logical backups via pg_dump and mysqldump, while PostgreSQL 17+ enables physical backups using the native pg_basebackup engine with block-level incremental support via pg_basebackup --incremental and continuous WAL streaming via pg_receivewal for Point-in-Time Recovery to any second between backups. Storage destinations include local disk, AWS S3, CloudFlare R2, Google Drive, Azure Blob Storage, SFTP, NAS, and rclone-backed targets, while built-in AES-256-GCM encryption secures both backup files and stored credentials. Restore verification runs automated recovery into throwaway Docker containers, validating backups by comparing schema counts, table structure, and row counts against the source database — proving recoverability rather than merely checking checksums. The notification system integrates with Slack, Discord, Telegram, email, and webhooks for real-time backup status alerts. Deployment options span a single Docker container, Docker Compose with Caddy for automatic HTTPS, Helm charts for Kubernetes clusters, or a one-line install script. SSH tunnel support reaches databases in closed networks through bastion hosts without public exposure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Elasticsearch
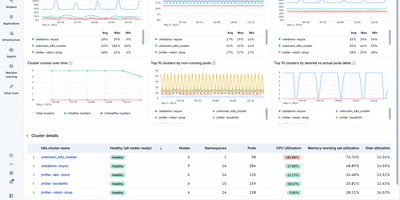
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
DragonflyDB
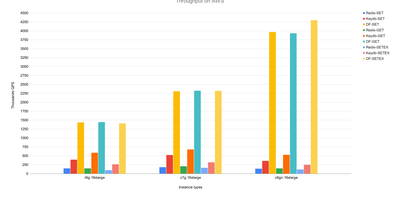
With over 30,000 GitHub stars and benchmarks showing 25x the throughput of single-threaded Redis, DragonflyDB is a modern in-memory data store that eliminates the need for complex Redis Cluster deployments by fully utilizing every CPU core on a single machine. Its shared-nothing, thread-per-core architecture written in C++ supports over 200 Redis commands and 13 Memcached commands, making it a true drop-in replacement that requires zero application code changes. A single DragonflyDB instance scales vertically from 8GB to 768GB of RAM across up to 64 cores, replacing entire Redis Cluster topologies with one process while maintaining full compatibility with Strings, Hashes, Lists, Sets, Sorted Sets, Streams, JSON, and Bloom Filters. The novel dashtable data structure and cache eviction algorithm achieve higher hit rates than LRU and LFU with zero memory overhead per entry. Forkless point-in-time snapshotting eliminates the memory spikes associated with Redis BGSAVE, while automatic backup scheduling via cron syntax supports both local disk and AWS S3 cloud storage. Primary-replica replication follows the Redis replication protocol up to version 6.2, and Prometheus-compatible metrics at the default port enable Grafana monitoring dashboards out of the box. DragonflyDB also exposes an HTTP admin interface on its main TCP port for operational monitoring. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed.
Grist
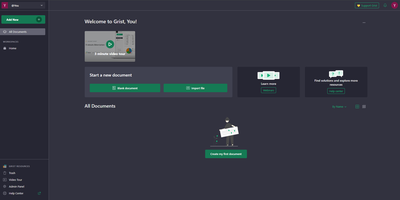
With over 11,200 GitHub stars and adoption by France's sovereign digital workspace LaSuite serving 20,000+ government users, Grist is the relational spreadsheet that ends the false choice between fragile Excel files and expensive custom database development — storing all data in portable SQLite files while providing true relational structure where VLOOKUPs become actual linked records that update instantly across entire documents. Python-powered formulas replace complex Excel syntax with clear, readable logic using the full Python standard library, while familiar Excel functions remain available for users who prefer them. Granular access rules control permissions at row, column, table, and cell levels — not just entire sheets — enabling multi-department documents where each team sees only their authorized data. The flexible layout system combines spreadsheets, card views, charts, calendars, and custom widgets on configurable dashboard pages that transform raw data into operational interfaces. Real-time collaboration lets multiple users edit simultaneously with automatic snapshot history capturing every change for full audit trails and point-in-time recovery. AI formula assistance connects to OpenAI, Llama, or any OpenAI-compatible endpoint via OpenRouter to generate formulas from natural language descriptions. The REST API and webhooks enable integration with n8n, Zapier, and custom automation, while incremental imports keep external data sources synchronized. Deployable via Docker with OIDC, SAML, and SCIM authentication support. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Redash
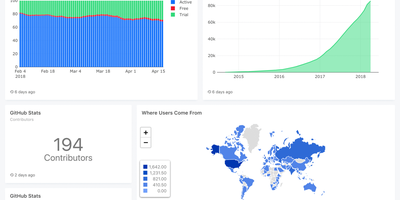
Used by millions of users at thousands of organizations worldwide and holding 29,000+ GitHub stars, Redash is the most established open-source SQL-first business intelligence tool — enabling anyone from analysts to executives to query databases, visualize results, and share dashboards without writing a single line of application code. The browser-based query editor supports SQL and NoSQL with schema browsing, auto-complete, query snippets, and parameterized queries that turn static reports into interactive data applications. Native connectors span 35+ data sources including PostgreSQL, MySQL, Amazon Redshift, Google BigQuery, Snowflake, ClickHouse, MongoDB, Elasticsearch, Databricks, Apache Presto, Microsoft SQL Server, and REST APIs — with an extensible data source API for custom integrations. Visualization types cover line, bar, area, pie, scatter, box plot, funnel, cohort, sankey, sunburst, choropleth map, and pivot tables, all draggable onto shared dashboards with cross-filtering parameters. Scheduled refreshes automatically update query results at configurable intervals, while threshold-based alerts notify teams via email, Slack, or webhook when metrics cross defined boundaries. SAML and Google OAuth SSO integration, role-based access control, API key management, and query-level permissions ensure enterprise-grade security for sensitive datasets. The self-hosted stack deploys via Docker Compose with PostgreSQL for metadata storage, Redis for job queuing, and Celery workers for background task execution. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 2-Clause licensed.
Neon
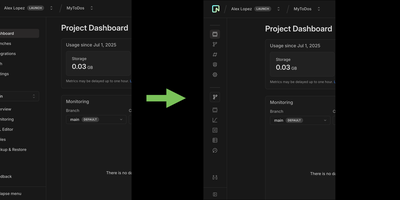
Neon reimagines PostgreSQL with a serverless architecture that decouples storage from compute, enabling instant copy-on-write database branching, autoscaling under load, and scale-to-zero when idle with sub-second cold starts. The lakebase architecture distributes durability across three layers: stateless compute nodes running unmodified PostgreSQL, safekeepers providing Paxos-based WAL quorum replication, and a pageserver that materializes pages on demand while offloading immutable history to S3-compatible object storage via MinIO or AWS S3. Copy-on-write branching creates full database clones as metadata operations without duplicating data, enabling developers to spin up isolated test environments, run parallel CI/CD pipelines, or recover from data loss through point-in-time restore across the configurable history window. Autoscaling dynamically adjusts CPU and memory based on live traffic without manual capacity planning, while scale-to-zero ensures costs drop to storage-only during idle periods. Neon maintains 100% PostgreSQL compatibility with broad extension support including PostGIS, pg_cron, pgvector, pg_stat_statements, and hundreds more, so existing applications connect with standard PostgreSQL drivers and ORMs unchanged. The API-first control plane enables programmatic provisioning, branch management, and multi-tenant fleet operations for platform builders and AI agent integrations. Acquired by Databricks in May 2025 and backed by over 22,800 GitHub stars. Deploys via Docker Compose with pageserver, safekeepers, storage broker, and compute nodes backed by MinIO object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
InfluxDB
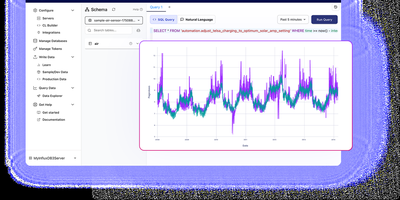
With over 31,600 GitHub stars and thousands of production deployments, InfluxDB 3 Core is the open-source time series database rebuilt in Rust on the FDAP stack — Apache Flight for high-throughput data transfer, DataFusion for vectorized SQL query execution, Arrow for columnar in-memory representation, and Parquet for compressed columnar storage. The engine delivers sub-10ms query response times on recent data and handles millions of writes per second through line protocol ingestion over HTTP, with unlimited tag cardinality eliminating the high-cardinality limitations that plagued earlier InfluxDB versions. The diskless architecture persists data as compressed Parquet files to S3-compatible object storage, Azure Blob, Google Cloud Storage, or local disk with configurable partitioning strategies, while the write-ahead log and in-memory buffer serve real-time queries against recent data before compaction. Native SQL support through DataFusion includes window functions, CTEs, subqueries, and joins, while InfluxQL maintains backward compatibility with existing InfluxDB 1.x and 2.x applications through the same query API. The embedded Python VM enables processing engine plugins and triggers that execute custom logic on write events, perform cross-database queries, and transform data in real time without external tooling. Flight SQL clients provide high-performance query access from Python, Go, Java, and Rust, and the HTTP API supports writes in line protocol format compatible with Telegraf's 300+ input plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT/Apache 2.0 dual-licensed.
VictoriaMetrics
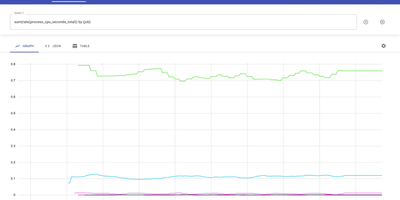
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
libSQL
libSQL bridges the gap between SQLite's legendary simplicity and the server-accessible database model developers expect from PostgreSQL and MySQL, adding network access, replication, and vector search while maintaining full file format and API compatibility. The sqld (SQL daemon) component transforms SQLite into a network-accessible database server accepting queries via HTTP with JSON payloads, WebSocket connections, and a Hrana protocol optimized for low-latency edge access. Client libraries for TypeScript, JavaScript, Rust, Go, and Python connect to sqld identically to any traditional client-server database, while the LD_PRELOAD compatibility layer enables switching existing SQLite applications from local to remote mode without code changes. Embedded replicas synchronize a local SQLite copy inside your application process with the primary server, delivering sub-millisecond read latency while maintaining consistency through streaming replication. Bottomless replication continuously backs up database state to S3-compatible object storage with generation-based snapshots and WAL page shipping, providing point-in-time recovery without manual backup scheduling. Native vector search enables semantic similarity queries directly within SQL using cosine distance functions, eliminating the need for external vector database infrastructure. Read replica support distributes query load across multiple sqld instances, and integration with mvSQLite adds multi-version concurrency for high-availability deployments. Created by Turso with 17,100+ stars and active production deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MySQL
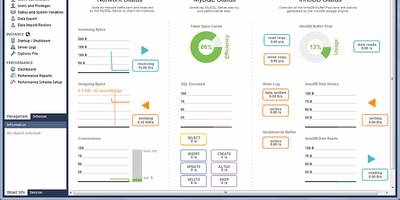
Powering Facebook, Uber, Twitter, and Booking.com, MySQL processes billions of queries daily as the world's most widely deployed open-source relational database. Its default InnoDB storage engine delivers full ACID compliance with row-level locking, crash recovery, and foreign key enforcement, making it the backbone of mission-critical e-commerce, SaaS, and financial applications. MySQL's Document Store bridges relational and NoSQL paradigms, allowing developers to work with schema-less JSON collections alongside traditional SQL tables through the X DevAPI protocol. For high availability, InnoDB Cluster combines Group Replication, MySQL Router, and MySQL Shell into an integrated solution with automatic failover, while InnoDB ClusterSet extends this across data centers for disaster recovery. The database supports multiple storage engines including MyISAM for read-heavy analytics, Memory for temporary high-speed caching, and Archive for compressed historical data. Native JSON functions like JSON_TABLE() transform document data into relational result sets, and spatial data types enable GIS applications. MySQL integrates with every major programming language through official connectors for Python, Java, Node.js, PHP, C++, and .NET, and works seamlessly with frameworks like Django, Laravel, Rails, and Spring. Replication topologies support read replicas for horizontal scaling, and the new Change Stream Applier in MySQL 26.7 enables configurable parallel transaction application with up to 1,024 workers per channel. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv2 licensed.
PostgreSQL
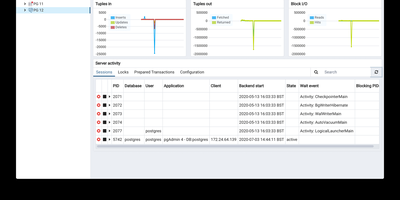
Consistently ranked the most loved and most wanted database in developer surveys, PostgreSQL powers mission-critical workloads at Apple, Instagram, Spotify, and the U.S. Federal Aviation Administration with an architecture refined over nearly four decades since its origins at UC Berkeley. Its native JSONB type stores JSON in an indexed binary format with GIN and GiST index support, enabling document-store capabilities that eliminate the need for a separate NoSQL database in many architectures. The extension ecosystem exceeds 1,000 add-ons: PostGIS provides ISO-compliant geospatial queries, pgvector enables AI embedding similarity search, TimescaleDB adds time-series hypertable compression, and Citus distributes tables across nodes for horizontal scaling. PostgreSQL supports declarative partitioning by range, list, or hash, parallel query execution across multiple CPU cores, and four transaction isolation levels including full Serializable. Streaming replication provides physical standby servers with synchronous or asynchronous modes, while logical replication enables selective table-level change data capture through the Write-Ahead Log. Stored procedures run in PL/pgSQL, PL/Python, PL/Perl, and PL/V8 JavaScript, and advanced indexing includes B-tree, GIN, GiST, SP-GiST, BRIN, and hash types. Full-text search is built in with tsvector and tsquery, and row-level security policies enforce fine-grained access control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PostgreSQL License (MIT-like permissive) licensed.
PeerDB
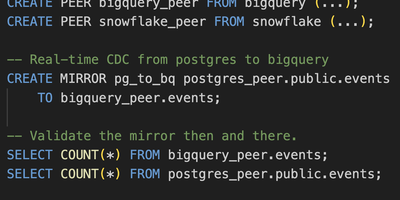
Replicate PostgreSQL to data warehouses 10x faster than conventional CDC tools, proven across 400+ companies including AutoNation and LC Waikiki collectively moving 200 TB monthly. The architecture pairs a Rust-based Nexus query layer implementing the PGWire protocol with Go-based Flow workers orchestrated by Temporal. Because Nexus speaks native Postgres wire protocol, any client tool (pgAdmin, psql, Grafana, Tableau, Flyway) can manage replication through standard SQL commands like CREATE MIRROR. Three streaming modes serve different needs: log-based CDC via logical replication slots, cursor-based streaming through timestamp or integer columns, and XMIN-based capture for tables lacking logical replication. Parallel initial load achieves consistent snapshots through transaction snapshotting and CTID range scans, reducing 100+ GB migrations from days to minutes. Native TOAST column handling processes large JSONB payloads and IoT data efficiently without row expansion penalties. Destinations include ClickHouse, Snowflake, BigQuery, Kafka, Azure Event Hubs, Google PubSub, S3, and PostgreSQL with in-flight SQL transformations. Schema change propagation, partitioned table support, and slot growth alerts ensure production reliability. Docker Compose bundles Temporal, catalog Postgres, Flow API, workers, and the Next.js monitoring UI. Deployable on RepoCloud with dedicated VPS resources under AGPL-3.0.
MongoDB
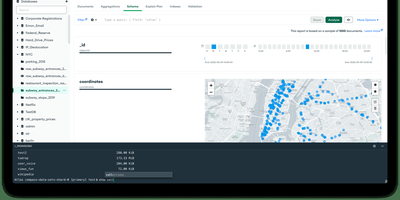
Used by over 46,800 companies including Forbes, Toyota, and Cisco, MongoDB stores data as flexible JSON-like BSON documents that eliminate rigid table schemas and support rapid application iteration. Its aggregation pipeline processes complex data transformations through composable stages including $match, $group, $lookup for joins, $unwind, and $project, operating directly within the database engine. Horizontal scaling is built in through automatic sharding, which distributes data across nodes using range-based, hashed, or zone-based shard keys, while replica sets provide automatic failover with configurable read preferences and write concerns. Multi-document ACID transactions span multiple collections and shards since version 4.0, enabling relational-style consistency guarantees within a document model. Starting with Community Edition 8.2, native full-text search and vector search are available directly in the database through $search and $vectorSearch aggregation stages, supporting RAG patterns, semantic retrieval, and hybrid search without external dependencies. Change streams provide real-time event-driven data access by tailing the oplog through the aggregation framework, enabling reactive architectures without polling. Time series collections offer optimized columnar storage for IoT sensor data and metrics with automatic bucketing and compression. Official drivers exist for Python, Node.js, Java, Go, C#, C++, Rust, Swift, and PHP, with MongoDB Compass providing a GUI for visual schema exploration and query building. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL v1 licensed.
MindsDB
Backed by 39,500+ GitHub stars and over 339 releases, MindsDB delivers the open-source federated query engine that gives AI agents a single SQL interface to read, join, and aggregate across 200+ live data sources without any ETL pipelines or data movement. The Connect-Unify-Respond architecture wires up Postgres, MySQL, MongoDB, Snowflake, BigQuery, ClickHouse, Redshift, Databricks, Salesforce, Shopify, Slack, S3, GCS, Azure Blob, and dozens more through self-contained Python handler packages merged in the open from the community. Knowledge Bases fuse structured tables with vectorized unstructured data from PDFs, emails, support tickets, and documents using hybrid search combining vector similarity with keyword matching for retrieval-augmented generation. Jobs execute queries on configurable schedules refreshing Knowledge Bases nightly or syncing derived tables hourly, while Triggers fire on data changes to automatically vectorize new rows into the appropriate store. The SQL-compatible query language extends standard SQL with constructs for creating models, defining agents, managing workflows, and searching unstructured data. The built-in web editor at port 47334 provides interactive SQL authoring, while the MySQL-compatible API at port 47335 and PostgreSQL API at port 47336 connect any database client directly. An MCP Server integration exposes MindsDB to AI assistants, and the Python SDK enables programmatic access from application code. Docker deployment runs with a single command exposing all APIs immediately. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
drawDB
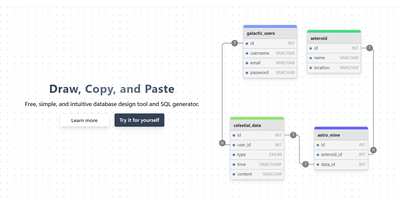
Schema design with no account and a few clicks: drawDB is the browser-based entity-relationship diagram editor and SQL generator - an AGPL-3.0 React project with over 37,000 GitHub stars. Draw tables with columns, data types, defaults, and constraints; connect fields to create foreign-key relationships; group tables into labeled subject areas; and annotate with notes. When the design is ready, one export produces CREATE TABLE DDL - with constraints, indexes, and foreign keys - targeted at MySQL, PostgreSQL, SQLite, MariaDB, SQL Server, or Oracle. Diagrams can be database-specific, unlocking every native type plus dialect features like PostgreSQL enums and composite custom types, or generic for portability across all supported flavors. The reverse direction works too: paste existing DDL into the import dialog and drawDB renders your live schema as a navigable diagram - the fastest way to document an inherited database. Versioning and migration-script generation track schema evolution, full editor ergonomics (undo/redo, copy/paste, duplicate, themes) keep iteration fast, and diagrams export as PNG, SVG, or shareable JSON. Everything runs client-side against browser storage - no backend database connection needed - so the self-hosted Docker deployment is a featherweight static app that keeps proprietary schema designs entirely on your infrastructure.
pgAdmin
pgAdmin 4 is the reference administration GUI for PostgreSQL, bundled by virtually every Linux distribution and supporting versions 14 through 18 including EDB Advanced Server — browse schemas in a hierarchical tree, write and optimize queries with AI assistance, design entity-relationship diagrams visually, monitor live sessions, and run backup/restore operations entirely from the browser. Built on Python Flask with a ReactJS frontend, version 9.17 delivers a comprehensive web-based platform accessible from any device. The Query Tool provides syntax highlighting, auto-completion, query history, an EXPLAIN plan visualizer with graphical node representation, AI-powered SQL generation from natural language prompts, and AI Insights for execution plan analysis that identifies performance bottlenecks. The Graph Visualiser renders query results as line charts, bar charts, stacked charts, and pie charts directly in the interface. The ERD Tool auto-generates entity-relationship diagrams from existing schemas for visual database design. The Schema Browser presents databases, schemas, tables, views, functions, sequences, roles, and extensions in a navigable hierarchy. Server monitoring dashboards display real-time active sessions, locks, transaction throughput, and vacuum status. GUI-driven backup and restore wraps pg_dump and pg_restore with format and compression options. Authentication supports internal, LDAP, Kerberos, OAuth2/OIDC, and webserver modes. The Helm chart includes an HTTPRoute template for Kubernetes Gateway API deployments. Bundled pg_dump, pg_restore, and psql utilities version 18.4. Deploy via Docker with the official dpage/pgadmin4 image. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PostgreSQL License.
RisingWave
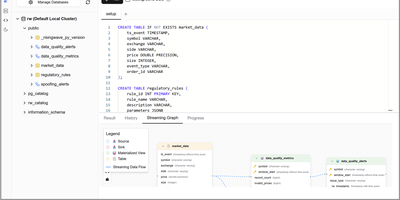
With over 9,100 GitHub stars and production deployments powering real-time analytics at companies like SHOPLINE where it reduced API latency by 76.7%, RisingWave is the PostgreSQL-compatible streaming database that collapses the traditional Debezium-plus-Kafka-plus-Flink-plus-serving-database stack into a single Rust-powered system. The platform continuously ingests data from PostgreSQL and MySQL via native CDC connectors that eliminate Debezium middleware, consumes Kafka, Redpanda, Pulsar, and Kinesis topics, accepts webhook events from SaaS applications, and batch-loads historical data from S3 and data warehouses. Standard SQL defines sources, materialized views, and sinks — no new DSL, no Java, and no custom API — while the PostgreSQL wire protocol means psql, DBeaver, pgAdmin, Grafana, Metabase, Superset, Tableau, and every PostgreSQL client library works without modification. Materialized views are incrementally maintained as events arrive, delivering point lookups in single-digit milliseconds without recomputing aggregates from scratch. For long-term retention, RisingWave writes to Apache Iceberg tables with a hosted REST catalog and automated table maintenance including compaction, small-file optimization, and snapshot cleanup, with data queryable by Spark, Trino, DuckDB, and DataFusion. The disaggregated compute-storage architecture uses S3-based state management for elastic scaling, instant failure recovery measured in seconds rather than the minutes-to-hours typical of RocksDB-based systems, and cost-efficient storage tiering. An MCP server enables AI agents to query and operate RisingWave directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.