OpenSquilla
Claiming 60-80% token cost reduction compared to flat single-model deployments and backed by 6,500+ GitHub stars, OpenSquilla delivers an intelligent AI agent runtime where a local ML classifier evaluates every turn on message length, code blocks, keyword patterns, and semantic embeddings before routing it to the optimal model tier from C0 through C3. The pluggable provider layer connects natively to TokenRhythm, OpenRouter, OpenAI, Anthropic, Ollama, DeepSeek, Gemini, DashScope, Moonshot, Mistral, Groq, Zhipu, SiliconFlow, vLLM, LM Studio, and additional compatible backends with primary-plus-fallback selection. The four-tier cognitive memory architecture spans working, episodic, semantic, and raw layers with vector-semantic and BM25 retrieval powered by on-device ONNX embeddings that never leave your infrastructure. Security isolation operates at the syscall level via Bubblewrap on Linux and Seatbelt on macOS, complemented by policy-based execution controls and prompt injection protections. The unified TurnRunner executes identically across the Vue-based control console Web UI, terminal CLI, and chat channel integrations including Slack and Discord, ensuring consistent tool dispatch, retry logic, and decision logging regardless of entry point. Built-in skills cover deep research, multi-search-engine queries, document generation for DOCX, PPTX, XLSX, and PDF formats, GitHub integration, cron scheduling, and bounded subagent delegation. Per-agent workspaces with durable session storage provide transcript replay, context state management, and per-call cost tracking with automatic quota enforcement. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
MLflow
Trusted by thousands of organizations with over 30 million monthly downloads and 20,000+ GitHub stars, MLflow is the largest open-source AI engineering platform providing end-to-end lifecycle management for traditional ML models, LLMs, and AI agents. The OpenTelemetry-based tracing system captures complete request flows through any LLM provider or agent framework — including OpenAI, LangChain, DSPy, Vercel AI, PydanticAI, and smolagents — with one-line auto-instrumentation that tracks inputs, outputs, token usage, and costs at every intermediate step. MLflow's evaluation engine offers 50+ built-in metrics and LLM judges for systematic quality assessment, detecting issues across correctness, latency, adherence, relevance, and safety dimensions before code reaches production. The Prompt Registry versions, tests, and deploys prompts with full lineage tracking while automated optimization algorithms improve prompt performance using evaluation feedback. The AI Gateway provides a unified API endpoint for all LLM providers, enforcing rate limits, cost controls, and access policies across the organization. MLflow 3.0 introduces the LoggedModel abstraction linking traces, metrics, and prompts to specific model versions across Python, TypeScript, Java, and R SDKs. The model registry manages deployment workflows with automated quality gates, while experiment tracking records parameters, metrics, and artifacts across training runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
Pixelle Video
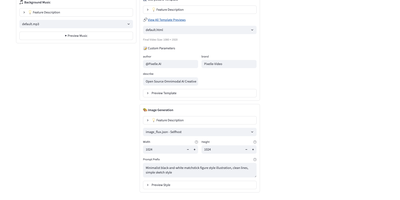
Backed by Alibaba's AIDC team and carrying over 27,700 GitHub stars, Pixelle-Video turns a single text prompt into a publish-ready short video in approximately three minutes — handling scriptwriting, image generation, voice narration, music selection, subtitle overlay, and final MP4 export in one automated pipeline. The engine supports multiple LLM backends for script generation including GPT-4, Qwen, DeepSeek, and local Ollama deployments, while image and video creation routes through either self-hosted ComfyUI workflows, cloud-based RunningHub pipelines, or direct API connections to DashScope Wan, OpenAI, Seedream, Seedance, and Kling AI. Text-to-speech synthesis uses Edge-TTS, Index-TTS, and other mainstream engines with multi-language voice profiles. Five distinct pipelines cover Quick Create, Standard, Digital Human Avatar broadcasting, Image-to-Video transformation, and Motion Transfer from reference video. The Streamlit web UI on port 8501 provides a visual workflow builder with template selection across portrait (1080x1920), landscape (1920x1080), and square formats, while the FastAPI server on port 8000 exposes a REST API with endpoints for async video generation, task polling, content scripting, TTS and image generation, template listing, and health checks. History persistence tracks all completed generations. HTML-based visual templates support static, image-overlay, and AI-video styles with customizable prompt prefixes. The modular architecture lets operators swap any atomic capability — image model, video model, TTS engine, or VLM — by editing a workflow JSON file without touching Python code. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
LibreDesk
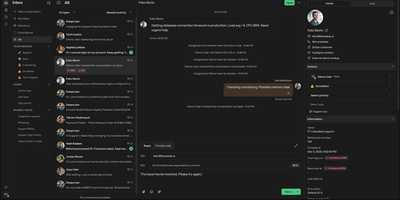
LibreDesk unifies live chat, email, and future channel integrations into a single agent inbox where every customer conversation converges regardless of origin, replacing per-seat-priced tools like Zendesk, Intercom, and Freshdesk with a zero-cost alternative that has surpassed 2,000 GitHub stars. Built on a Go backend with a Vue.js 3 and ShadcN UI frontend, it ships as a single binary requiring only PostgreSQL and Redis. The embeddable live chat widget drops onto any website with a snippet, while the AI assistant handles initial customer queries using answers grounded in your knowledge base before escalating to human agents when needed. Agent copilot drafts replies, summarizes conversation threads, and rewrites messages for tone adjustment directly within the inbox interface. Automation rules trigger on conversation events to tag, assign, and route tickets based on configurable conditions, while auto-assignment distributes workload by agent capacity or custom criteria. SLA management tracks response and resolution time targets with breach notifications, and automated CSAT surveys measure satisfaction after conversation closure. Macros save frequently sent responses as reusable templates that simultaneously set tags and assign conversations. Role-based access control provides granular per-action permissions for teams and individual agents, and SSO supports Google, Microsoft, and any OIDC provider. The HTTP/JSON API and webhook system enable custom integrations with external tools. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Anakin
Backed by Y Combinator and powering scraping infrastructure across 195 countries, Anakin delivers a production-grade web scraping API purpose-built for AI agents and RAG pipelines that need clean, structured data from sites that actively block conventional scrapers. The single Go binary server handles JavaScript-heavy SPAs through its Camoufox anti-detect browser service with automatic fingerprint rotation, while the HTTP-first handler chain tries lightweight extraction before escalating to full browser rendering — keeping response times under 2 seconds for static pages. The built-in React 19 dashboard provides visual scraping with live results, job tracking with status filters, domain configuration management with handler chain CRUD, and proxy performance monitoring via Thompson Sampling scoring. Structured JSON extraction leverages Gemini AI to transform raw HTML into typed schemas without manual selector maintenance. SDKs span Python, TypeScript, Go, .NET, Java, and Ruby, while the MCP server exposes all 21 tools directly to Claude, Cursor, Windsurf, and any Model Context Protocol-compatible agent. The hosted platform extends the open-source engine with AI web search returning full page content with citations, multi-source agentic research across 20+ sources per query, Wire pre-built actions covering 944 websites with 5,201 structured endpoints, persistent browser sessions for authenticated scraping, and website change monitoring with scheduled alerts. Deploy via Docker Compose with three containers or run the binary directly with optional PostgreSQL persistence. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Bifrost
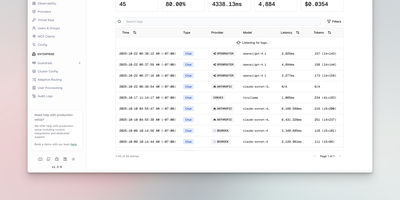
Bifrost is an open-source AI gateway that unifies 23+ LLM providers into a single OpenAI-compatible endpoint with automatic failover, semantic caching, and built-in cost governance, so one provider going down never takes your production AI application with it. Point your existing OpenAI or Anthropic SDK at Bifrost's local endpoint and gain access to OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Groq, Mistral, and Ollama without changing application code. Define fallback chains that automatically switch providers when one returns errors or exceeds latency thresholds, keeping response times stable during outages. The built-in web dashboard at port 8080 lets you configure providers, create virtual API keys, monitor live request traffic, and review analytics without editing configuration files. Semantic caching combines exact hash matching with vector similarity search via Weaviate, serving cached responses for identical or paraphrased prompts in sub-millisecond time to cut costs on repetitive workloads. The MCP gateway connects AI agents to external tools like filesystems, databases, and web APIs, exposing them to clients such as Claude Desktop and Cursor with per-key allow-lists. Four-tier budget hierarchy at customer, team, virtual key, and provider levels enforces spend caps, rate limits, and model restrictions across your organization. Extend functionality through custom Go plugins for analytics, monitoring, or security middleware. Native Prometheus metrics and OpenTelemetry distributed tracing give operations teams full production observability. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Apache APISIX
With 17,000 GitHub stars, 460+ contributors, and deployments across telecommunications, automotive, and financial services running on over 10,000 CPU cores at the largest known installations, Apache APISIX delivers a fully dynamic API gateway achieving 140,000 QPS on eight cores with sub-millisecond latency through NGINX's event-driven architecture and LuaJIT-compiled plugin execution. The 100+ open-source plugins cover authentication (JWT, OAuth 2.0, OIDC, Keycloak, LDAP), observability (Prometheus, Datadog, SkyWalking, OpenTelemetry), traffic management (rate limiting, circuit breaking, canary releases, traffic splitting), and security (CORS, IP restriction, CSRF protection) — all hot-reloadable without process restarts via etcd-based real-time configuration synchronization. Multi-protocol support handles HTTP, gRPC, MQTT, TCP, UDP, and WebSocket traffic for both north-south API access and east-west service mesh communication. AI gateway capabilities proxy requests to 20+ LLM providers with semantic caching, token-aware rate limiting, provider failover routing, and content moderation. Custom plugins extend the gateway in Lua, Go, Java, Python, or WebAssembly. Radixtree route matching handles 100,000+ routes without performance degradation. Functions as a Kubernetes ingress controller with native service discovery for Consul, Nacos, and Eureka. Deploy via Docker or Helm charts with horizontal scaling through etcd cluster coordination. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OctoBot
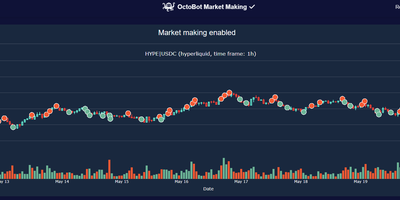
OctoBot provides a free and fully configurable cryptocurrency trading platform that runs on your own server. The bot automates investment strategies across 15+ exchanges including Binance, Coinbase, MEXC, Hyperliquid, Kucoin, OKX, and Bybit, supporting spot, futures, and perpetual markets. The AI trading system connects to any OpenAI-compatible API or local Ollama server, enabling strategies powered by ChatGPT, Llama, Mistral, or any custom model for market analysis and signal generation. TradingView integration accepts PineScript indicator signals and strategy alerts via webhooks, while built-in technical analysis covers RSI, Moving Averages, MACD, Bollinger Bands, and other standard indicators. The modular tentacle architecture allows community-developed plugins to extend strategy logic, evaluators, data sources, and exchange interfaces. The backtesting engine replays historical market data against any configured strategy, reporting profit and loss, drawdown, win rate, and trade-by-trade breakdown before committing real funds. Paper trading provides risk-free live simulation with the same execution logic as production. The web dashboard displays real-time portfolio value, open positions, trade history, and strategy performance with interactive charts. Telegram bot integration enables remote monitoring, notifications, and command execution from mobile devices. Docker deployment runs the full stack in a single container with persistent volume storage for configuration and trade data. On RepoCloud, deploy OctoBot on a dedicated VPS with root SSH access, persistent storage for your trading data and strategy configurations, and complete control over exchange API keys and AI model connections, all under the GPL-3.0 license.
GitNexus
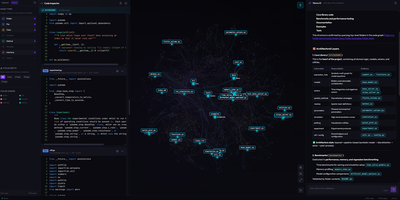
GitNexus turns any codebase into an interactive knowledge graph that maps every dependency, call chain, functional cluster, and execution flow, giving AI coding assistants the deep structural awareness they need to stop breaking things. Drop a repository URL or ZIP file into the browser-based explorer and watch Tree-sitter parsers decompose your code into a navigable property graph you can zoom, click, and query. The MCP server integrates directly with Cursor, Claude Code, Codex, Antigravity, and other editors through 16 specialized tools covering architectural queries, impact analysis, safe multi-file renames, change detection, and cross-repo contract matching. Need to know the blast radius before touching a shared utility? The impact analyzer traces every caller, implementer, and downstream consumer in milliseconds. Teams reviewing pull requests get automated blast-radius annotations powered by the same graph. The registry architecture lets a single MCP server manage multiple indexed repositories simultaneously, so switching between projects requires zero re-indexing. For visual exploration, the web interface renders interactive community-clustered graphs where you can trace execution paths, browse file trees, and chat with an AI agent grounded in the graph's structural data rather than raw file snippets. Everything runs locally; your source code never leaves the machine. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PolyForm Noncommercial 1.0.0 licensed.
Archon
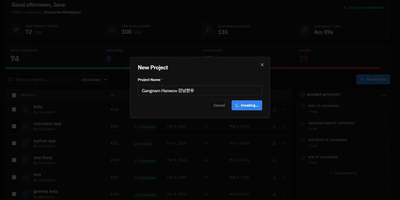
Stop hoping your AI coding assistant remembers to plan before it codes, test after it implements, and review before it ships. Archon wraps Claude Code, OpenAI Codex, and other AI agents inside structured YAML workflows that enforce the same development process every single time. Define your pipeline as a directed acyclic graph of nodes (AI tasks, shell scripts, approval gates, loops) and Archon handles the orchestration: resolving dependencies, running independent nodes in parallel, passing artifacts between steps, and isolating every run in its own git worktree so five bug fixes can proceed simultaneously without conflicts. Ship with 17 pre-built workflows covering everything from "idea to merged PR" to automated conflict resolution, or author your own by committing YAML files to your repository's .archon/workflows/ directory. The web dashboard, launched with archon serve, provides a conversation interface with real-time streaming, a visual drag-and-drop workflow builder for creating DAG pipelines, step-by-step progress monitoring for every run, and a unified sidebar aggregating conversations from CLI, Slack, Telegram, and GitHub into one view. An NLP router parses natural language requests and automatically selects the right workflow. Structured JSON output schemas let you enforce typed responses from AI nodes, with validation and auto-repair for providers that lack native schema support. Every workflow file is version-controlled, portable, and reviewable in pull requests, so your entire team runs identical processes from day one. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Casibase
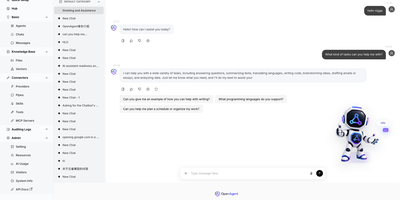
Casibase lets organizations build AI-powered knowledge bases that answer questions from their own documents, connecting to 30+ model providers through a unified admin interface with RAG retrieval and multi-agent orchestration via MCP and A2A protocols. The platform plugs into OpenAI GPT-4o, Anthropic Claude, Meta Llama, Google Gemini, DeepSeek, Ollama local models, HuggingFace, Azure OpenAI, and additional providers, while embedding APIs from OpenAI Ada and Baidu handle vector representation of ingested documents. Document ingestion parses TXT, Markdown, DOCX, PDF, CSV, XLSX, and PPTX files with intelligent chunking strategies for optimal retrieval accuracy. The built-in chat interface provides real-time AI conversations with manual session handover for human agent escalation, and comprehensive chat session logging enables audit trails for compliance. Enterprise identity management integrates Casdoor for Single Sign-On supporting GitHub, Google, WeChat, and OIDC providers with fine-grained access control via the Casbin permission engine. The multi-tenant architecture supports isolated knowledge bases per organization with role-based user management and configurable storage, model, and embedding providers per tenant. The React frontend with Ant Design v5 provides a polished admin dashboard for managing providers, knowledge stores, chat sessions, and user access, while the Go backend with Beego framework handles API logic with MySQL or MariaDB persistence. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Keep
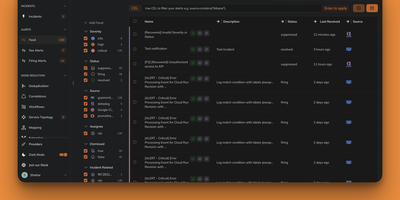
Keep is an open-source AIOps and alert management platform built with Python FastAPI and Next.js. It provides a single pane of glass for monitoring alerts from 110+ integrations, alert deduplication, correlation, enrichment, and filtering, YAML-based workflow automation similar to GitHub Actions, AI-powered correlation and summarization, and customizable dashboards for incident management. With 12,100+ GitHub stars, Y Combinator backing, and an Elastic partnership, Keep is the open-source AIOps platform that centralizes alert management across your entire monitoring stack into a single customizable dashboard. Alert deduplication identifies duplicate notifications across providers, correlation groups related alerts into incidents based on rules or AI-powered semantic analysis using pluggable LLM backends supporting OpenAI, Anthropic, and local models via Ollama, and enrichment adds context from external sources like CMDBs and databases. Workflow automation follows a GitHub Actions paradigm with declarative YAML files defining triggers, conditions, and actions that can query MySQL, update Jira tickets, send Slack messages, execute Python scripts, or call REST APIs. Authentication supports no-auth, database, Auth0, Keycloak, OAuth2 Proxy, Okta, and OneLogin. The Common Expression Language enables advanced alert querying, slicing, and rule-based grouping to reduce noise. On RepoCloud, deploy Keep on a dedicated VPS with Docker Compose, root SSH access, and complete control over your alert infrastructure, all under the MIT license.
Khoj
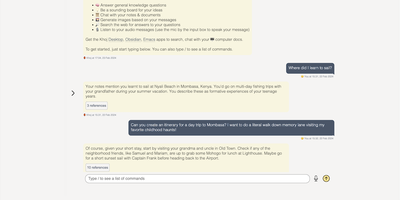
A self-hosted "second brain": Khoj indexes your own files and answers questions from them, parsing Markdown (whole Obsidian vaults included), org-mode, PDF, Word, plain text, Notion pages, GitHub repositories, and images described by a vision model, then embedding everything with sentence-transformers into a vector index for semantic search and RAG with cited sources. Any LLM backend works: local models like Llama, Qwen, or Mistral via Ollama, or cloud models like GPT, Claude, and Gemini. You can build custom agents, each with its own persona, scoped knowledge base, chat model, and tools such as web search and code execution. Scheduled automations run recurring research and deliver newsletters or notifications to your inbox, and research mode performs multi-hop web searches with inline citations. Access it from a browser, the Obsidian plugin, Emacs, desktop, or WhatsApp - all clients connect to the same self-hosted instance, making Khoj one of the few AI assistants Emacs users can point at decades of org files. Semantic search means recall works without exact keywords: "that paper about forecasting with transformers" surfaces the right PDF even when you cannot remember its title. Switching LLM backends never requires re-indexing your documents, and with a local model via Ollama, even inference stays on hardware you control - journals, research, and private notes are never sent anywhere. Python/FastAPI stack, AGPL-licensed, with PostgreSQL storage.
Open Notebook
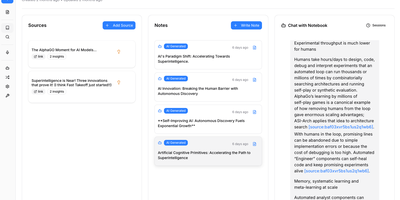
The most feature-complete open-source alternative to Google's NotebookLM — a self-hosted research platform where you upload PDFs, videos, audio files, and web pages into organized notebooks, then chat with your content, generate multi-speaker podcasts, and run semantic search across everything without sending a single byte to Google's servers. The podcast engine supports 1-4 fully customizable speakers with backstories, personalities, and expertise profiles, generating professional audio dialogue through OpenAI, ElevenLabs, Google TTS, or completely local text-to-speech via Kokoro for maximum privacy. Content processing uses token-based chunking with RAG-powered retrieval grounded in your uploaded sources, while both full-text keyword search and semantic vector search via SurrealDB enable conceptual discovery across all notebooks. The 18+ supported AI providers include OpenAI, Anthropic, Google Gemini, Groq, Ollama, LM Studio, and more — configurable per task so you can route cheap models to summarization and powerful models to analysis. Content transformations extract insights, generate summaries, create study guides, and produce structured outputs from any source material. The MCP integration connects Open Notebook to Claude Desktop, VS Code, and other MCP clients for seamless workflow integration. A full REST API on port 5055 enables complete automation of notebook management, source upload, and podcast generation. Deploy via Docker Compose with the application container, SurrealDB v2 on RocksDB, and optional TTS containers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Plane
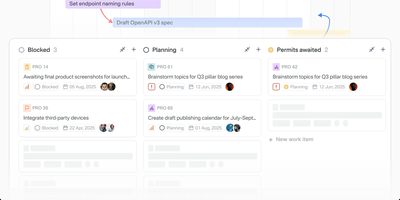
The most-starred open-source project management platform on GitHub with over 55,000 stars, Plane delivers what Jira, Linear, Monday, and ClickUp charge thousands per year for — issue tracking, sprint planning, documentation, and AI-powered workflows in one unified workspace that you own and control entirely. Work items feature a rich text editor with file uploads, sub-properties, custom states, priorities, labels, assignees, and cross-referencing, organized across five customizable layout views (list, board, table, spreadsheet, Gantt) with Command-K navigation for instant access to anything. Time-boxed Cycles provide sprint planning with automatic burn-down charts, velocity tracking, and scope change detection, while Modules break complex projects into manageable deliverables with progress aggregation. Built-in Pages combine AI-powered documentation with rich formatting, image embedding, and one-click conversion of notes into actionable work items. The AI layer reads across every project, cycle, document, and thread in the workspace — agents take real assignments, triage incoming requests, assign owners, track blockers, and ship status updates automatically. Native integrations connect GitHub, GitLab, Slack, Sentry, Figma, and 50+ tools with bidirectional issue sync and PR tracking, while import pipelines migrate entire workspaces from Jira, Linear, Asana, ClickUp, or Monday in minutes. The REST API with OAuth 2.0, HMAC-signed webhooks, typed SDKs in Node.js and Python, and a native MCP server enable custom automations. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
FalkorDB
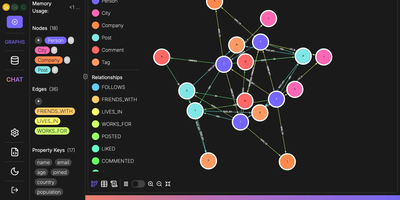
FalkorDB is the first queryable property graph database to leverage sparse adjacency matrices and linear algebra for graph traversal, replacing traditional pointer-chasing with GraphBLAS-accelerated computation. Originally the RedisGraph engine, it was relaunched as FalkorDB in 2023 and rewritten from C to Rust in 2026 for improved memory safety and performance. The database supports the OpenCypher query language with proprietary extensions, translating queries into linear algebra expressions that exploit AVX hardware acceleration. Indexing options include full-text search, vector similarity for embedding-based retrieval, and range indexing, while connectivity supports both the RESP protocol for Redis clients and the Bolt protocol for Neo4j-compatible tooling. The GraphRAG SDK enables ingestion of documents in text, PDF, and Markdown formats into knowledge graphs, with schema-guided entity extraction, hybrid retrieval combining vector and graph traversal, relationship expansion, and cited answers for LLM applications. Official client libraries cover Python, Node.js, Java, Rust, Go, PHP, and C#. Multi-tenant support handles over 10,000 concurrent graphs with zero overhead and full isolation. Docker deployment runs the falkordb/falkordb image on ports 6379 for the database server and 3000 for the built-in browser UI, with persistent volume storage and optional authentication. A production falkordb-server image excludes the browser for lighter deployments. On RepoCloud, deploy FalkorDB on a dedicated VPS with root SSH access, persistent storage for your graph data, and complete control over authentication, thread count, and memory configuration, all under the SSPLv1 license.
DeepTutor
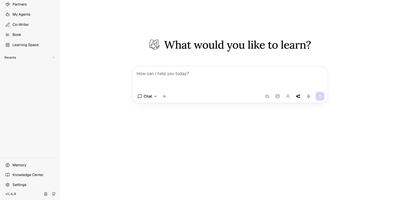
With 34,000+ GitHub stars and a v1.5 release driven by 36 merged community pull requests, DeepTutor from Hong Kong University's Data Science Lab delivers a full agent-native learning workspace that goes far beyond chatbot wrappers. Eight integrated surfaces — Chat, Deep Solve, Quiz Generation, Deep Research, Math Animator, Co-Writer, Book generation, and Mastery Practice — share a unified context so the objective follows the learner, not the tool. The platform's three-layer memory architecture (L1 working, L2 session, L3 long-term) makes personalization inspectable rather than opaque, letting users see exactly what the system remembers and why. Knowledge retrieval operates across five pluggable engines — LlamaIndex with FAISS vectors, PageIndex for page-level citations, GraphRAG for knowledge-graph traversal, LightRAG for local or server-offloaded retrieval, and linked Obsidian vaults — with document parsing via MinerU, Docling, markitdown, or PyMuPDF4LLM. Partners extend the tutoring brain to 15+ messaging platforms including Slack, Discord, Telegram, Matrix with E2EE, and Mattermost, each carrying private memory with branch, resume, and replay capabilities. Subagent integration brings Claude Code, Codex, Gemini, and Kimi directly into learning sessions. The system supports 30+ LLM providers from OpenAI and Anthropic to Ollama for fully local operation, with multi-user isolation, admin controls, and a full CLI interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenLIT
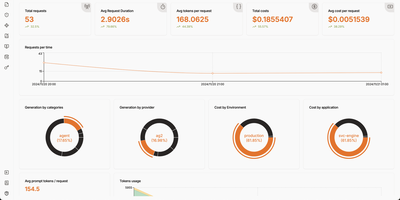
Your AI application is burning through API tokens faster than you can refresh the billing page, and you have no idea which prompt template is responsible. OpenLIT plugs that visibility gap with a self-hosted observability platform built specifically for LLM workloads. Add one line of code to instrument 90+ LLM providers, agent frameworks, and vector databases, then watch every request flow through a tracing dashboard that shows tokens consumed, latency measured, and dollars spent per call, per model, per environment. The requests view lists every LLM interaction with provider, model, cost, and token breakdown in a filterable table, while the trace detail panel lets you drill into individual spans to read the exact prompt sent and response received. Prompt Hub turns prompts into versioned artifacts you deploy, rollback, and A/B test without touching application code. OpenGround compares models side by side on the same input, so you can evaluate cost-versus-quality tradeoffs before committing to a provider. Automated evaluations run LLM-as-a-judge scoring on live production traces, flagging hallucinations, bias, and toxicity in real time. The Vault stores and rotates API keys centrally so secrets stay out of your codebase. Custom dashboards let you build drag-and-drop monitoring views with charts, stat cards, and tables backed by SQL queries against ClickHouse. GPU utilization, memory, temperature, and power metrics feed into the same platform for end-to-end infrastructure visibility. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.