Highlight
With over 9,000 GitHub stars and a focus on developer experience over legacy monitoring complexity, Highlight.io delivers a unified observability platform that correlates frontend user behavior with backend performance data in a single interface. The session replay engine captures high-fidelity DOM recordings showing exactly what users experienced, including console logs, network requests, page transitions, and user interactions, with configurable privacy redaction for sensitive content. Error monitoring automatically groups and deduplicates errors, surfaces affected user sessions, and provides full stack traces with source map support for minified production code. The logging pipeline ingests structured and unstructured logs from any backend service with automatic property extraction, full-text search, and configurable alerting thresholds. Distributed tracing tracks request flows across microservices with embedded links to associated sessions, errors, and logs for complete request lifecycle visibility. The metrics system collects custom application metrics alongside built-in web vitals and performance data for trend analysis and anomaly detection. Search across all telemetry types uses a unified query language with automatic attribute discovery and saved views for recurring investigations. Integrations connect with Slack, Discord, Linear, Jira, Vercel, and dozens of other developer tools for notification routing and workflow automation. SDKs cover React, Next.js, Vue, Angular, Python, Go, Ruby, Java, PHP, and Elixir with framework-specific instrumentation. Self-hosted deployment runs via Docker Compose with ClickHouse for analytics storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Laminar
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Beszel
Reaching 24,000 GitHub stars within two years of its first commit in July 2024, Beszel delivers Netdata-grade monitoring dashboards from a single Docker container with no Prometheus stack, no external database, and no complex configuration — just a one-binary hub on PocketBase (SQLite embedded) and a sub-15 MB agent per host that auto-discovers Docker and Podman containers on contact. The agent connects outbound via WebSocket or SSH tunnel, requiring zero open ports on monitored servers and zero manual network configuration. Per-host metrics cover CPU usage, memory with swap and ZFS ARC breakdown, disk I/O across multiple partitions, network throughput, load average, sensor temperatures, battery charge, and GPU utilization with power draw for Nvidia, AMD, and Intel cards — features that competitors lock behind paid tiers. S.M.A.R.T. disk health including eMMC wear indicators and Linux mdraid array status surface hardware degradation before failures occur. Container statistics track CPU, memory, and network history per container with automatic discovery as new containers start. Configurable threshold alerts notify via email, Discord, Telegram, ntfy, Pushover, Gotify, Matrix, Mattermost, Signal, Slack, Microsoft Teams, and Twilio when metrics exceed defined limits. Multi-user accounts with OAuth/OIDC authentication let teams share monitored systems with role-based access, while automatic backups persist data to disk or S3-compatible storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Zabbix
Monitoring everything from network switches to Kubernetes clusters since 2001 with over 6,200 GitHub stars and deployments exceeding 100,000 devices per installation, Zabbix has established itself as one of the most mature and feature-rich open-source monitoring platforms available, trusted by organizations including Dell, Salesforce, ICANN, and T-Mobile. The platform collects metrics from virtually any source using Zabbix Agent written in C, Zabbix Agent 2 written in Go with native plugin support, SNMP v1/v2c/v3 polling and trapping, IPMI for hardware health, JMX for Java applications, SSH and Telnet checks, HTTP/HTTPS polling, and ODBC database queries. Version 7.0 LTS introduced synthetic browser monitoring that executes user-defined JavaScript via WebDriver to simulate multi-step user interactions on websites, proxy load balancing with automatic host redistribution across proxy groups for high availability, in-memory proxy data buffering delivering up to 100x performance improvement, native multi-factor authentication with TOTP and Duo support, and just-in-time user provisioning from SAML and LDAP. Low-level discovery automatically detects file systems, network interfaces, SNMP OIDs, VMware resources, and Kubernetes pods, creating monitoring items and triggers dynamically. The alerting engine correlates events with configurable escalation chains, sending notifications through Slack, Microsoft Teams, PagerDuty, Jira, email, and SMS with customizable message templates. Over 1,000 official templates provide instant monitoring for Linux, Windows, VMware, AWS, Azure, Docker, PostgreSQL, MySQL, Apache, Nginx, and hundreds more. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
OpenSearch
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Sentry
Backed by 44,000 GitHub stars and trusted by over four million developers, Sentry is the debugging platform that captures errors, traces, replays, profiles, and metrics from your applications and connects them all through distributed tracing. The error tracking engine captures full stack traces with source context, breadcrumbs, and automatic demangling for native crashes, while intelligent grouping consolidates duplicate events into actionable issues with regression detection and automatic assignment. Performance monitoring instruments your frameworks automatically, capturing every database query, API call, cache hit, and queue operation as spans within distributed traces that flow across frontend, backend, and mobile boundaries. Session Replay produces video-like recordings of real user sessions showing DOM interactions, network requests, console messages, and errors on a synchronized timeline, with AI-powered summaries that describe what happened without watching the full replay. Continuous profiling captures CPU execution data at the function and line level for Node.js, Python, iOS, and Android, linking slow spans directly to the exact code responsible. Cron monitoring tracks scheduled jobs for failures, missed runs, and duration anomalies. The alerting engine fires notifications through Slack, PagerDuty, Opsgenie, and webhooks on new issues, regressions, error spikes, or when latency and crash-free session rate thresholds are crossed. Self-hosted deployment runs as a Docker Compose stack with PostgreSQL, ClickHouse, Kafka, Redis, and Relay. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FSL licensed.
OneUptime
With 7,400+ GitHub stars and a feature set that replaces seven separate SaaS subscriptions — Pingdom for monitoring, StatusPage.io for status pages, PagerDuty for on-call, Incident.io for incident management, Datadog for APM, Loggly for logs, and Sentry for error tracking — OneUptime delivers every tool your reliability team needs in a single open-source platform that is genuinely 100% open source under Apache 2.0 (not open-core). Uptime monitoring runs synthetic checks against websites, APIs, ports, SSL certificates, and DNS records from distributed global probes with configurable intervals and thresholds. Branded status pages publish automatically when monitors detect issues, notifying subscribers via email, SMS, webhook, or RSS without manual intervention during an outage. On-call scheduling routes alerts through escalation policies to the right engineer via phone call, SMS, push notification, Slack, or Microsoft Teams. The incident management workflow handles declaration, triage, communication, resolution, and post-mortem generation in a unified timeline. APM collects traces and metrics via native OpenTelemetry integration — no proprietary agents required — while log management provides full-text search and alerting. An AI agent continuously monitors telemetry data, identifies root causes, and opens GitHub pull requests with proposed fixes for review. Deploy via Docker Compose or Kubernetes Helm charts with a Terraform provider for infrastructure-as-code configuration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Maintenant
Maintenant replaces three to five separate monitoring tools with a single Go binary that consolidates container discovery, endpoint monitoring, SSL tracking, resource metrics, and public status pages without requiring any external database. The embedded Vue 3 frontend serves on port 8080 immediately after deployment, auto-discovering Docker containers and Kubernetes pods through direct socket and API access without configuration. HTTP and TCP endpoint monitoring validates availability with configurable intervals, while TLS certificate tracking alerts before expiration across all monitored domains. Resource metrics collect CPU, RAM, network throughput, and disk usage per container with real-time Server-Sent Events streaming to the dashboard. Heartbeat and cron monitoring accepts pings from external scheduled jobs, triggering alerts on missed check-ins via webhook callbacks and Discord notifications. The built-in alert engine supports escalation rules and notification batching. Public status pages expose component health to end users without authentication, customizable per monitored service. Network security insights analyze exposed ports, container privilege levels, and host configuration to produce a posture score. Update intelligence scans OCI registries to detect available container image updates with digest comparison. The REST API with SSE broker enables automation, and the integrated MCP server provides tooling for AI assistant integration. SQLite in WAL mode stores all data with zero operational overhead. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
BitRouter
BitRouter is a context-aware LLM router that learns which model delivers the cheapest successful outcome per workflow step, cutting agent costs by up to 80% while maintaining 96% quality versus all-frontier baselines. Point any agent runtime at http://localhost:4356 with a one-line OPENAI_BASE_URL change and BitRouter routes to OpenAI, Anthropic, Google, Groq, DeepSeek, Mistral, Moonshot, MiniMax, Nvidia, and any OpenAI-compatible endpoint simultaneously, normalizing authentication, streaming, and cross-protocol translation between wire formats. The act-observe-evaluate-learn loop traces every hop with cost, tokens, and latency attribution, scores each decision against a versioned policy-lock.yaml, then tightens routes automatically with no LLM judge in the path. Native MCP gateway auto-discovers tools from connected servers and makes them routable and governed alongside model calls. Agent Client Protocol integration enables the TUI to manage Claude Code, Codex, OpenCode, OpenClaw, Gemini, and Copilot sessions in real time with inline tool-call approval and live streaming. Built-in guardrails inspect, redact, or block risky content before requests leave your network. Virtual keys scope API access per agent or user without exposing upstream credentials. Per-agent spend caps and loop guards contain runaway cost automatically. Multi-account failover reroutes mid-run so rate limits never re-pay completed work. Ships as a single Rust binary via npm or Cargo. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
HyperDX
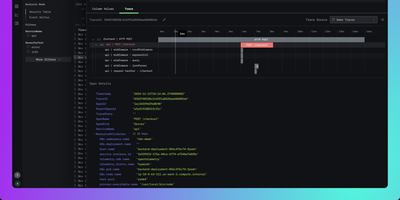
HyperDX correlates logs, metrics, traces, session replays, and errors in a single interface so engineers can resolve production incidents in minutes instead of hours. Nearly 10,000 GitHub stars reflect its role as the integrated UI layer for the ClickStack blueprint endorsed by ClickHouse. The platform connects to any ClickHouse cluster as its storage backend, working with existing table structures without requiring data migration or proprietary ingestion formats. An intuitive Lucene-like search syntax supports full-text queries and property filtering like level:err or service.name:api without needing SQL, while native JSON string querying and event delta analysis surface anomalies in high-cardinality datasets. One-click cross-signal correlation lets you jump from a log line to its distributed trace, from a slow span to associated logs, or from a frontend session replay to the backend errors it triggered. The OpenTelemetry Collector accepts telemetry via OTLP on gRPC port 4317 and HTTP port 4318, supporting automatic instrumentation for Node.js, Python, Java, Go, Ruby, and browser applications. APM tracks HTTP request latency, database query duration, and external service calls with trace waterfall visualizations. Configurable alerts trigger via webhook, Slack, PagerDuty, or email when thresholds are breached. Deploys via Docker Compose with ClickHouse, MongoDB, Redis, and the OpenTelemetry Collector. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Jaeger
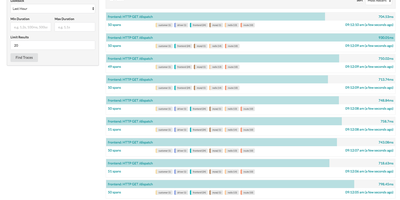
Created by Uber Technologies and graduated as the seventh CNCF top-level project in October 2019 with over 23,000 GitHub stars, Jaeger has become one of the most widely deployed open-source distributed tracing platforms, processing billions of spans per day in production environments at organizations including Uber, Red Hat, and Shopify. Version 2 rebuilt the platform on the OpenTelemetry Collector framework, inheriting its extensible pipeline architecture while implementing Jaeger-specific features as extensions and components, enabling seamless integration with the OpenTelemetry ecosystem through native OTLP protocol support. The platform stores traces in Cassandra 4.0+, Elasticsearch 7.x/8.x, OpenSearch 1.0+, ClickHouse, or the embedded Badger database for development setups. Three sampling strategies control trace volume: head-based sampling with constant, probabilistic, and rate-limiting modes, tail-based sampling using the OpenTelemetry Collector processor that evaluates complete traces before storage decisions, and adaptive sampling that dynamically adjusts probabilities based on observed traffic patterns. Service Performance Monitoring computes RED metrics directly from spans, displaying request rates, error rates, and latency percentiles in the Monitor tab with drill-down from aggregate service views to individual traces. The web UI provides trace search with multi-field filtering, trace detail views with span timeline visualization, trace comparison across services, and dependency graphs mapping service relationships from actual traffic. Deployment options range from a single all-in-one binary for development to distributed collector-ingester-query configurations with Kafka intermediate buffering for production scale. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Coroot
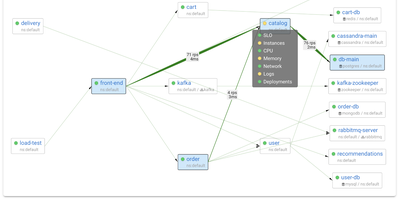
Coroot uses eBPF to capture metrics, distributed traces, logs, and continuous CPU profiles directly from the Linux kernel, delivering full observability without any application code changes, SDKs, or sidecars. From the first minute of deployment, an automatically generated service map covers every microservice, database, message queue, and external dependency with request rate, error rate, and latency measurements. When a service breaches its SLO, AI-powered inspections analyze telemetry across all dimensions to pinpoint the root cause and send a single consolidated alert with findings, replacing the flood of fragmented notifications typical of traditional monitoring. Deployment tracking automatically discovers Kubernetes rollouts and compares each release against the previous one to detect performance regressions, resource spikes, and cost impacts without CI/CD pipeline integration. Continuous profiling captures CPU flame graphs down to the line of code with negligible overhead. Integrated cost monitoring tracks cloud spending across AWS, GCP, and Azure, attributing expenses to individual services and deployments. Coroot supports Prometheus, OpenTelemetry, and ClickHouse as data sources and works identically on Kubernetes clusters, virtual machines, and bare-metal hosts. 7,700+ GitHub stars. Apache-2.0 licensed.
Graylog
Trusted by over 60,000 organizations worldwide with more than 8,100 GitHub stars since 2010, Graylog has established itself as one of the fastest paths from raw log data to operational visibility, delivering centralized log management, security analytics, and compliance auditing through a purpose-built web interface with sub-second search at scale. The platform ingests logs from virtually any source via syslog, GELF, Beats, raw TCP/UDP, HTTP, CEF, IPFIX, and Netflow protocols, processing each message through configurable pipelines that parse fields, apply transformations, enrich events with GeoIP data from MaxMind or IPinfo lookup tables, and route messages to appropriate streams based on content rules. OpenSearch handles full-text indexing and storage with dynamic shard sizing that automatically calculates appropriate sizes from available node memory, while MongoDB stores configuration metadata including user accounts, roles, dashboards, alert rules, and pipeline definitions. The alerting system integrates with Slack, PagerDuty, and email with customizable notification templates and Replay Search links for immediate investigation context. Version 7.0 introduced MCP server integration for connecting preferred LLMs to perform AI-assisted log analysis and automation, while version 7.1 added Sigma detection rule import from private GitHub, GitLab, and Bitbucket repositories for detection-as-code workflows. The Sidecar agent management system centrally configures and deploys Filebeat, Winlogbeat, and nxlog collectors across infrastructure from the Graylog web interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL licensed.
Quickwit
With over 11,000 GitHub stars and now backed by Datadog while remaining fully Apache 2.0 licensed, Quickwit delivers the search performance Elasticsearch users expect at a fraction of the infrastructure cost by moving the index to object storage instead of expensive local SSDs. The Rust-based engine, built on the Tantivy search library with SIMD-accelerated vectorized processing and zero garbage collection overhead, achieves sub-second search latency directly against Amazon S3, Azure Blob Storage, Google Cloud Storage, or any S3-compatible backend like MinIO and Ceph. The Elasticsearch-compatible REST API covers ingest, search, query DSL, and aggregations, enabling existing log shippers including Vector, Fluent Bit, and Syslog to migrate without rewriting configurations. Native OpenTelemetry Protocol endpoints accept logs and traces via gRPC, while Jaeger integration provides a drop-in distributed tracing backend. Ingestion from Apache Kafka, Amazon Kinesis, and Apache Pulsar supports streaming pipelines with multi-index partitioning, and the schemaless JSON indexing mode eliminates the need for upfront schema definitions. Stateless searchers and indexers scale horizontally on Kubernetes or bare metal, with a control plane that distributes indexing tasks and a janitor that manages retention policies and GDPR-compliant deletions. The built-in web UI displays search results and cluster state, while the official Grafana data source enables log exploration dashboards. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Parseable
Parseable replaces expensive Elasticsearch clusters and fragmented monitoring stacks with a single Rust binary that ingests, queries, and stores logs, metrics, and traces on commodity object storage at a fraction of the cost. The data lake architecture decouples stateless compute from S3-compatible storage, enabling independent scaling of ingestion throughput and query capacity while cutting storage costs by up to 90% compared to indexed alternatives. OpenTelemetry-native OTLP ingestion accepts telemetry from existing OTel collector pipelines, Prometheus Remote Write endpoints, Kafka consumers, eBPF probes, and popular logging agents including Fluentd, Fluent Bit, and Vector without proprietary format conversions. The SQL-first query interface enables cross-signal analysis across all telemetry types, while native PromQL support with 50+ functions and 12 aggregation operators provides Prometheus-compatible metrics querying that works directly with Grafana dashboards. Built-in features include customizable dashboards, real-time alerting with Webhook, Slack, and Alertmanager targets, role-based access control, OpenID single sign-on integration, LogIQ automatic unstructured-to-structured log transformation, smart caching for frequently accessed data, and retention policies for lifecycle management. AI-powered Keystone Q&A provides natural language to SQL conversion and dataset summarization. All data stored as standard Apache Parquet on object storage remains accessible to any Parquet-compatible engine (DuckDB, Spark, Trino), ensuring zero vendor lock-in. Deploys on AWS S3, Azure Blob, Google Cloud Storage, MinIO, Wasabi, and DigitalOcean Spaces. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Moneat
Moneat is the open-source observability platform that unifies error tracking, session replay, performance monitoring, logging, uptime checks, synthetics, product analytics, and AI observability into a single self-hosted application — replacing Sentry, Datadog, and Statuspage with one deployment. The Sentry SDK compatibility layer accepts data from @sentry/browser, @sentry/node, @sentry/react, @sentry/nextjs, sentry-sdk for Python, sentry-kotlin, sentry-java, sentry-android, sentry-cocoa, sentry-go, sentry-ruby, and Sentry.NET by updating one DSN endpoint. Datadog Agent compatibility redirects existing fleets by setting dd_url, and native OpenTelemetry OTLP ingestion accepts logs, traces, and metrics from any exporter or Collector. Error monitoring groups exceptions with smart deduplication, session replay records DOM-based user interactions linked to errors, distributed tracing visualizes transaction and span breakdowns with live service maps, and continuous profiling renders flamegraphs in pprof, JFR, and Sentry formats. Uptime monitoring runs HTTP, TCP, and ping checks with public status pages, while synthetics executes API tests, multi-step workflows, SSL checks, and DNS probes. Custom dashboards support drag-and-drop widgets with Grafana import, product analytics provides funnels and retention cohorts, release tracking surfaces crash-free rates with source map upload, and AI observability traces LLM calls end to end. Built on Kotlin and Java with ClickHouse for analytical storage, PostgreSQL for relational data, and Redis for caching, deployment uses Docker Compose with an interactive installer automating secrets and service orchestration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Grafana OnCall
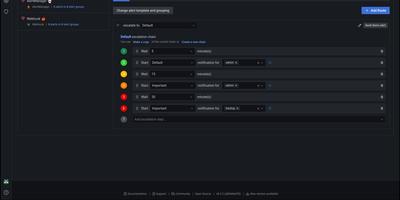
With 3,900 GitHub stars, 140 contributors, and 380 releases since its 2022 launch, Grafana OnCall delivers developer-friendly incident response that routes alerts from any monitoring system to the right engineer at the right time through the right channel. The platform accepts alerts via unique API URLs from Alertmanager, Grafana Alerting, Zabbix, Datadog, Pagerduty-compatible sources, Jira, inbound email, and generic HTTP webhooks, then applies routing templates to direct each alert to the appropriate escalation chain. Escalation chains define notification sequences — notify the primary on-call via Slack, wait 5 minutes, escalate to SMS and phone, wait 10 minutes, page the secondary on-call and notify the engineering manager — continuing until acknowledgment or resolution. On-call schedules support multi-layer rotations with overrides, shift swaps, and timezone-aware handoffs rendered directly inside Grafana dashboards. ChatOps integration publishes alert groups to Slack channels and Telegram groups with interactive buttons for acknowledge, resolve, and silence actions. Template engines based on Jinja2 control alert grouping, appearance rendering, and behavioral automation. The REST API enables programmatic management of integrations, schedules, and escalation policies. Deploy via Docker Compose with PostgreSQL, Redis, and Celery workers alongside your existing Grafana instance. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPL v3 licensed.
GlitchTip
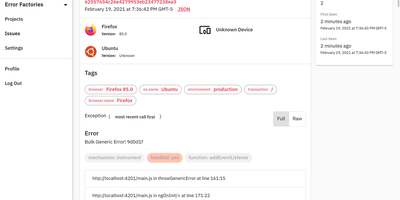
GlitchTip speaks Sentry's protocol without Sentry's operational weight - open-source error tracking that your existing SDKs already understand. The pitch is pragmatic: instrument your application with the official Sentry SDKs you already know - any language they cover - and point the DSN at your own GlitchTip instance instead. Errors, exceptions, log messages, and Content Security Policy violations flow into one place for triage, grouped into issues with stack traces, with alerts delivered by email or webhook the moment things break. Where self-hosted Sentry has ballooned into a docker-compose stack of twenty-plus containers, GlitchTip is a deliberately lean Django and PostgreSQL application a small team can actually run. Beyond errors, it bundles three more monitoring concerns: performance monitoring takes a works-out-of-the-box approach - no dashboard building, just your slowest web requests, database queries, and transactions surfaced automatically; uptime monitoring pings your sites and alerts on failures, or runs in reverse as a dead-man's-switch heartbeat for cron jobs that must check in on schedule; and log search puts application logs alongside errors for faster debugging. Unlimited projects and team members, MIT-licensed, built by Burke Software - your event volume is limited only by your own hardware.