Grafana Loki
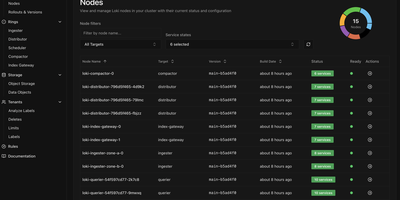
With over 28,600 GitHub stars and 450 contributors, Grafana Loki is the log aggregation system that takes the Prometheus approach to logging — indexing only metadata labels instead of full log content, making it dramatically cheaper and simpler to operate than traditional log management platforms. The label-based indexing strategy groups log streams using the same labels already applied to Prometheus metrics, enabling seamless switching between metrics and logs in Grafana dashboards without maintaining separate indexing infrastructure. Grafana Alloy, the telemetry collector replacing Promtail, scrapes and pushes logs with Prometheus-style service discovery, automatic Kubernetes Pod label extraction, and pipeline stages for parsing, filtering, and relabeling before ingestion. LogQL, the query language, combines label matchers for stream selection with regex line filters and aggregation functions, supporting rate calculations, pattern parsing, and metric generation from log data for alerting and dashboard panels. The storage architecture writes compressed log chunks and TSDB indexes to S3, GCS, Azure Blob Storage, or MinIO-compatible object stores, with configurable retention and compaction policies. Deployment modes scale from a single binary for development through monolithic high-availability mode with multiple replicas to full microservices decomposition with separate ingester, distributor, querier, query-frontend, compactor, and ruler components on Kubernetes via Helm charts. Multi-tenancy isolates data and query paths per tenant through header-based tenant ID assignment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Glance
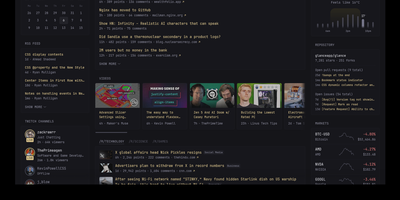
With over 35,000 GitHub stars in just two years, Glance has become the most popular self-hosted dashboard project on GitHub, outpacing established alternatives like Homarr and Homepage. Built as a single Go binary under 20MB with minimal JavaScript and zero external dependencies, Glance delivers a blazing-fast personal information dashboard that consolidates your entire digital morning routine into one beautiful page. Configure everything through clean YAML files that support modular includes and environment variable interpolation, with automatic hot-reload that applies changes without restarting the server. The widget ecosystem covers RSS and Atom feeds, Reddit and Hacker News frontpages, YouTube channel subscriptions, GitHub release timelines, weather forecasts from Open-Meteo, stock market quotes, Docker container status, Twitch live streams, calendar events via iCal, site monitor uptime checks, and custom HTML or iframe embeds. A community widgets repository extends functionality even further with user-contributed integrations. The theming system provides light, dark, and custom color schemes with multiple layout options including slim and wide column configurations. Authentication support added in 2025 secures access with username and password protection. Preconfigured page templates let you get started in seconds with curated layouts for development, homelab monitoring, news reading, and entertainment tracking. Deploy via Docker Compose or as a standalone binary on Linux, macOS, or Windows across AMD64 and ARM64 architectures. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Web-Check
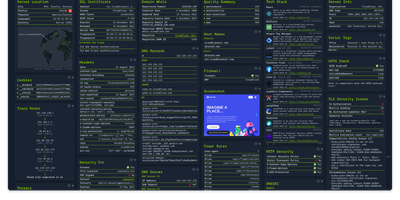
Enter a URL and get a dashboard of everything publicly discoverable about its security posture, server architecture, and technology stack: Web-Check is an all-in-one OSINT tool for analyzing any website. One scan surfaces IP info and server location, the full SSL certificate chain with issuing authority and validity, DNS records (A, MX, NS, CNAME, TXT) with DNSSEC status, HTTP response headers interpreted for security directives like HSTS, CSP, and X-Frame-Options, cookies and their flags, WHOIS domain info, robots.txt crawl rules, a sitemap-derived page map, the redirect ledger, open ports, traceroute, detected technologies, third-party trackers, associated hostnames, site performance, and even carbon footprint. Each card explains what the data means and why it matters, which makes the tool double as a security education resource - junior engineers learn headers and attack surfaces by scanning real sites. Practical uses span pre-deployment security audits (catch missing headers and misconfigurations before they ship), privacy compliance checks (identify trackers and cookie behavior for GDPR work), competitive tech-stack research, and network debugging via DNS and redirect inspection. Built by Lissy93 in TypeScript, it deploys as a single Docker container, and self-hosting keeps your reconnaissance targets and audit activity off third-party services.
OpenLIT
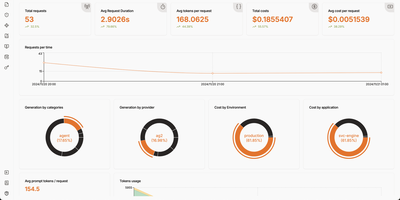
Your AI application is burning through API tokens faster than you can refresh the billing page, and you have no idea which prompt template is responsible. OpenLIT plugs that visibility gap with a self-hosted observability platform built specifically for LLM workloads. Add one line of code to instrument 90+ LLM providers, agent frameworks, and vector databases, then watch every request flow through a tracing dashboard that shows tokens consumed, latency measured, and dollars spent per call, per model, per environment. The requests view lists every LLM interaction with provider, model, cost, and token breakdown in a filterable table, while the trace detail panel lets you drill into individual spans to read the exact prompt sent and response received. Prompt Hub turns prompts into versioned artifacts you deploy, rollback, and A/B test without touching application code. OpenGround compares models side by side on the same input, so you can evaluate cost-versus-quality tradeoffs before committing to a provider. Automated evaluations run LLM-as-a-judge scoring on live production traces, flagging hallucinations, bias, and toxicity in real time. The Vault stores and rotates API keys centrally so secrets stay out of your codebase. Custom dashboards let you build drag-and-drop monitoring views with charts, stat cards, and tables backed by SQL queries against ClickHouse. GPU utilization, memory, temperature, and power metrics feed into the same platform for end-to-end infrastructure visibility. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Bugsink
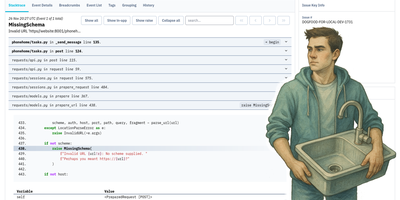
Bugsink has earned over 1,800 GitHub stars as the lightweight self-hosted error tracking platform that replaces Sentry without per-event billing by accepting error reports from any Sentry-compatible SDK across Python, JavaScript, Node.js, Ruby, Java, PHP, Go, and every other language Sentry supports. Simply update the DSN in your existing Sentry configuration and Bugsink captures the same stack traces, local variables, request context, and breadcrumbs that Sentry processes, displayed through a focused interface designed for debugging rather than dashboarding. Automatic issue grouping collapses duplicate error events into single actionable issues based on exception type, message, and stack frame context, turning thousands of raw events into a manageable list. Issue status tracking supports resolved, resolved-in-next-release, and muted states with automatic regression detection when resolved issues recur. Release tracking associates events with deploy versions to correlate error spikes with specific rollouts. Tag-based search filters issues by environment, release, user, browser, operating system, or any custom key-value pair sent by the SDK. Alerting notifies your team through Slack, Discord, Mattermost, and email when new issues appear or resolved issues regress, with per-project webhook configuration and user-level notification preferences. Per-project retention policies with automatic event eviction manage storage growth. A REST API with OpenAPI documentation enables custom integrations and dashboards. Source map support links minified JavaScript to original source. Deploy via Docker with the bugsink/bugsink image. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PolyForm Shield licensed.
Tianji
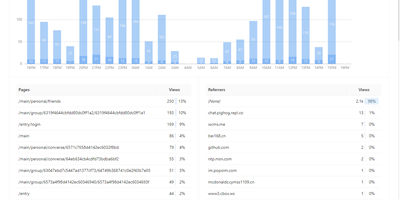
Website analytics, uptime monitoring, and server status - three tools most teams run separately - combined in Tianji, an open-source observability platform. The analytics layer tracks page views, unique visitors, referrers, and UTM parameters with a lightweight cookie-less script, which keeps collection GDPR and CCPA friendly. The uptime monitor checks availability and latency on configurable intervals, accepts passively reported results, and publishes public status pages for incident communication. Server status agents report CPU, memory, disk, and network metrics with threshold-based alerts, and notifications route through webhooks, Slack, Telegram, and other channels with noise control. It also includes anonymous telemetry for tracking deployments of your own open-source projects, surveys, waitlists, team collaboration, and an OpenAPI interface for integrations and exports. The consolidation is the point: traffic analytics, uptime checks, and server metrics share one interface and one alerting layer, so diagnosing an incident does not mean hopping between Google Analytics, Uptime Kuma, and Prometheus - and the built-in public status pages replace a separate paid Statuspage-style subscription. Because collection uses no cookies with IP truncation and aggregation by default, basic traffic measurement requires no consent banner. Built in TypeScript under the Apache 2.0 license and inspired by Umami and Uptime Kuma, it is deliberately right-sized for independent developers and small SaaS teams whose monitoring needs are real but lightweight.
Headlamp
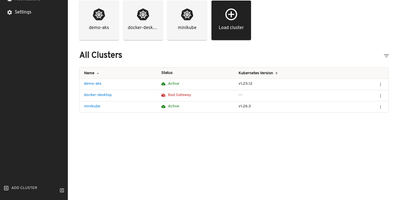
The Kubernetes project's own answer to cluster management UIs: maintained under SIG UI governance, Headlamp's roadmap tracks Kubernetes releases and its design philosophy reflects community needs rather than a vendor's product strategy. The React interface provides full read-write capabilities adapted to each user's RBAC permissions — delete, scale, edit, and restart buttons appear only when the authenticated user holds the corresponding cluster role, preventing accidental unauthorized actions. Multi-cluster support surfaces workloads across development, staging, and production from a single view without context switching. The plugin architecture drives extensibility through a curated catalog: an AI Assistant plugin answers natural-language cluster queries and performs operations via configurable LLM keys, Flux handles GitOps, Karpenter manages nodes. Integrated terminals provide browser-based exec access to running pods, live log streaming follows container output with filtering, and the YAML editor displays inline Kubernetes API documentation alongside resource definitions. Deployment creation forms let you configure containers, environment variables, volumes, and replicas without writing manifests. Side-by-side cluster comparison views surface differences in workload distribution. Works with any distribution: EKS, GKE, AKS, Minikube, Docker Desktop. Helm chart installation via the Headlamp repository with images on GitHub Container Registry. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Percona PMM
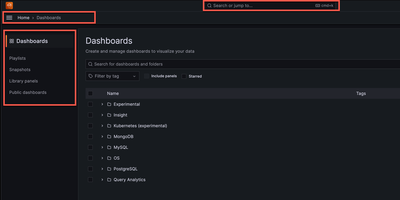
Backed by 1,080+ GitHub stars and maintained by Percona with the latest release v3.8.1 in June 2026, Percona Monitoring and Management delivers the open-source database observability platform that provides a single pane of glass across MySQL, PostgreSQL, MongoDB, Valkey, and Redis databases deployed on-premises, cloud, or hybrid environments. The Go-powered PMM Server collects metrics from lightweight PMM Client agents with minimal performance impact, storing time-series data in ClickHouse for fast querying across configurable retention periods. Query Analytics ranks every query by load across all database engines from one unified dashboard, drilling from fleet-level performance down to individual problematic queries with explain plans, per-query metrics, and anomaly detection. Real-time Query Analytics streams live MongoDB operations updated every 1-5 seconds for immediate troubleshooting of lock contention and long-running queries. Built-in Percona Advisors continuously scan connected databases for security gaps, misconfigurations, and performance problems, distilling decades of DBA expertise into automated actionable recommendations. Percona Alerting integrates with 15+ notification channels including Slack, PagerDuty, email, and webhooks to trigger on custom metric thresholds. Database-specific dashboards visualize InnoDB storage engine details, WiredTiger cache metrics, PostgreSQL tuple activity, replication lag, and cluster health with annotations for root-cause correlation. Deployment options include Docker single-container setup, Podman rootless execution, and Helm charts for Kubernetes with Ingress controller support and ConfigMap management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Healthchecks
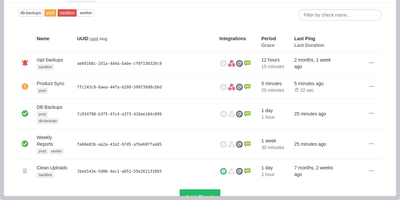
With 10,100+ GitHub stars and 75 releases over a decade of continuous development, Healthchecks is the open-source cron job monitoring service that catches failures your other monitoring tools miss — the jobs that silently stop running, the backups that never completed, the nightly reports that disappeared without error. The dead man's switch architecture requires zero agent installation: your cron jobs, scripts, and services ping a unique URL via HTTP request or email, and Healthchecks alerts you only when a ping does not arrive within the configured Period and Grace Time window. Each check supports cron expression scheduling, optional start, success, and failure signals for measuring execution time, and HTTP body keyword filtering for intelligent alert routing. Twenty-five notification integrations cover every channel teams actually use: Slack, Discord, Microsoft Teams, PagerDuty, Opsgenie, Splunk On-Call, Telegram, Signal, WhatsApp, SMS, email, webhooks, GitHub Issues, Pushover, ntfy, Gotify, Matrix, Mattermost, Zulip, Pushbullet, PagerTree, Spike.sh, and Trello. The web dashboard provides a visual grid showing real-time status with color-coded badges and per-check integration toggles. Monthly, weekly, and daily email reports summarize uptime trends with checks sorted by downtime duration. Team management supports projects with member roles and read-only access. Prometheus metrics expose check health and grace state for Grafana dashboards. WebAuthn and TOTP two-factor authentication secure accounts. Deploy via Docker images available for amd64, arm/v7, and arm64 architectures. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
Exceptionless
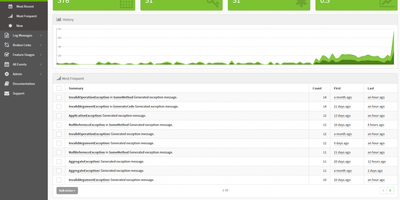
Exceptionless has earned over 2,400 GitHub stars and has been processing production errors since 2014 as the real-time event monitoring platform that captures far more than crashes. Built with ASP.NET Core on Elasticsearch for storage and Redis for caching, Exceptionless ingests exceptions, log messages, feature usage events, broken links, and custom event types through official SDKs for JavaScript, Node.js, .NET Core, ASP.NET, WPF, Web API, WebForms, Console apps, and React Native. Automatic event stacking groups related occurrences by exception type, message, and call stack into single actionable items, while manual stacking keys let developers create custom groupings for specific features or workflows. The real-time dashboard displays Most Frequent, Most Recent, and New event views with filtering by project, date range, environment, and custom tags. Stack management tracks resolution status with version-aware regression detection that automatically reopens resolved issues when the same error surfaces in a newer release. Webhook integrations connect to Slack, Discord, and external services through Zapier for automated issue tracking in GitHub Issues and Jira. Per-project notification settings control email and chat alerts for new errors, regressions, and critical events. OpenTelemetry support captures distributed traces alongside error data. The v8.6.0 release introduced a hosted Model Context Protocol server at the /mcp endpoint, enabling AI tools to query error data via OAuth-authenticated access. Deploy via Docker with the exceptionless/exceptionless image alongside Elasticsearch and Redis. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Grafana
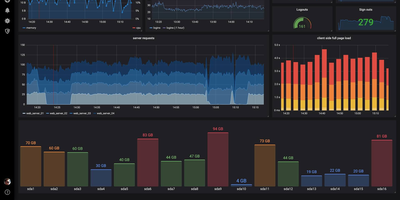
The de facto dashboard of observability: Grafana is the open-source frontend that turns the data stores you already run into interactive graphs. It does not store metrics itself; it connects to the data stores you already run and turns their contents into interactive dashboards. Supported sources number over 150 via plugins: Prometheus, Loki, Tempo, InfluxDB, Elasticsearch, MySQL, PostgreSQL, Microsoft SQL Server, AWS CloudWatch, Azure Monitor, Google Cloud Monitoring, and many more. Dashboards are built from a large library of panel types (time series, heatmaps, tables, gauges, logs) with template variables for reusable, parameterized views. Unified alerting evaluates rules against any connected data source, not just Prometheus, and routes notifications to Slack, PagerDuty, email, and other channels with grouping and silencing - unlike Prometheus Alertmanager, a single rule can combine a Loki log pattern, a PostgreSQL query result, and a CloudWatch metric. Dashboards serialize to JSON and data sources configure via provisioning files, so the entire observability setup can live in Git and deploy repeatably across environments. Explore mode adds ad-hoc querying outside dashboards, with split view for correlating a metric spike against the matching log lines, and access control spans organizations, teams, folder permissions, and OAuth, LDAP, and SAML integration. Written in Go and TypeScript, AGPL-licensed. Self-hosting gives you unlimited users, dashboards, and queries at flat hosting cost, without Grafana Cloud's usage-based pricing.
Change Detection
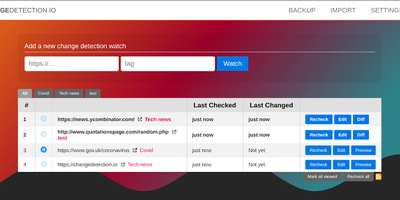
Price drops, restocks, job postings, government announcements, competitor edits - changedetection.io watches web pages and alerts you the moment anything changes, down to PDF text and checksums. Point it at a URL, set a check interval, and precise filters decide what counts as a change: a Visual Selector targets page elements by pointing and clicking, CSS selectors and XPath narrow scope, trigger-text and ignore-text rules (with regex support) cut noise, and JSONPath or jq handles API responses. A dedicated re-stock and price detection mode extracts product metadata and fires on thresholds - alert only when the price drops below your target or the percentage change exceeds a limit. JavaScript-heavy sites render through a real Chrome browser via Playwright, with the ability to execute JS steps first (log in, click, scroll) before extracting text. Notifications reach 85+ services through Apprise - Discord, Slack, Telegram, email, webhooks - optionally with a screenshot of the changed page, and AI-powered summaries (any OpenAI-compatible endpoint, including local Ollama) describe what changed. Per-watch proxies, custom headers, and POST/GET control cover hostile targets. Apache-2.0 licensed with local file-based storage: the URLs you monitor and why stay entirely your business.
QuestDB
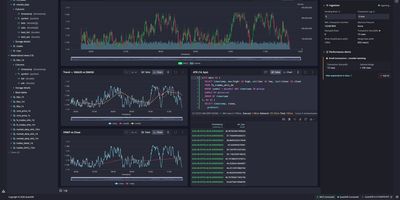
Powering trading floors at firms processing millions of market data events per second and trusted by organizations including Airbus, Yahoo, and Copenhagen Atomics, QuestDB has earned over 17,000 GitHub stars as the time-series database that refuses to make you choose between ingestion speed and query latency. The column-oriented, time-partitioned storage engine processes millions of rows per second on ingest through write-ahead logging with instant durability, while SIMD-accelerated parallel execution returns analytical queries over billions of rows in milliseconds. Time-series SQL extensions add ASOF JOIN for point-in-time lookups across tables with misaligned timestamps, SAMPLE BY for downsampling at arbitrary time intervals, LATEST ON for last-value queries, and WINDOW JOIN for sliding window aggregations — all through standard SQL syntax accessible via the PostgreSQL wire protocol, REST API, or the QuestDB Wire Protocol (QWP) that streams Apache Arrow at 220 million rows per second. Multi-tier storage automatically moves data from the WAL through native columnar format to Parquet files on S3-compatible object storage, keeping hot data fast and cold data portable without manual tiering. The built-in web console provides an interactive SQL editor with syntax highlighting, autocomplete, and charting for quick data exploration. Views, materialized views, and n-dimensional arrays support real-time analytics, while native Parquet export enables direct integration with Python, DuckDB, and AI/ML frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
UptimeKuma
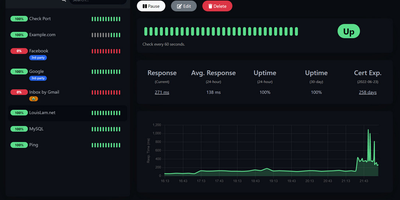
Sixty-thousand-plus GitHub stars make Uptime Kuma the most popular self-hosted monitoring tool - MIT-licensed, Node.js, and the standard replacement for UptimeRobot, Pingdom, and Freshping. It watches a dozen monitor types: HTTP(S) endpoints with keyword and JSON-query content validation, TCP ports, ICMP ping, DNS records, WebSockets, Docker containers via the socket, Steam game servers, MQTT brokers, gRPC services, and push-based heartbeats for cron jobs and internal workers. Checks run at intervals as tight as 20 seconds - versus UptimeRobot's 5-minute free tier - with unlimited monitors and unlimited data retention. When something fails, alerts fan out through 90+ notification channels: Slack, Discord, Telegram, email with LiquidJS templating, PagerDuty, OpsGenie, ntfy, Gotify, Matrix, and dozens more via native providers plus the Apprise library. Unlimited public or password-protected status pages - mappable to specific domains and organized into monitor groups - communicate health to customers, with maintenance windows that suppress alerts during planned work. The reactive dashboard graphs response times, tracks SSL certificate expiry with advance warnings, supports proxies and 2FA, and ships in dozens of languages. One Docker container with a SQLite volume covers an entire infrastructure.
Dashy
Every service you run, behind one polished start page: Dashy is the most customizable homelab dashboard, built as a Vue.js homepage. Configuration lives in a single YAML file, but you never have to hand-edit it: an integrated UI editor with real-time validation writes changes back to disk, so both config-as-code and point-and-click camps are served. Status indicators put a live health dot next to every app - HTTP checks or pings on custom intervals, with response time and status details on hover - giving you an at-a-glance uptime overview before anything breaks. Over 50 built-in widgets pull dynamic content from the services you already run: Pi-hole and AdGuard block stats, Proxmox lists, Nextcloud status, Netdata CPU/memory history, Prometheus data, plus weather, RSS, crypto prices, and generic iframe/API-response widgets for anything with an endpoint. Instant fuzzy search launches any app as you type, with customizable hotkeys and web-search fallthrough. Theming is deep: dozens of built-in themes, a UI color palette editor, and custom CSS over CSS variables. Alternate views include a fast-loading minimal startpage and a workspace view that embeds apps side-by-side without leaving the dashboard. Icons resolve from Font Awesome, homelab icon packs, emojis, or auto-fetched favicons. Built-in authentication, multi-page support, cloud backup/sync, and multi-language round out an MIT project with a massive community.
Langfuse
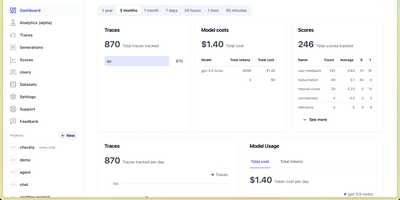
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Highlight
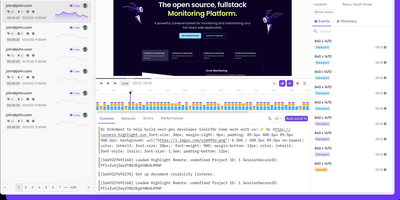
With over 9,000 GitHub stars and a focus on developer experience over legacy monitoring complexity, Highlight.io delivers a unified observability platform that correlates frontend user behavior with backend performance data in a single interface. The session replay engine captures high-fidelity DOM recordings showing exactly what users experienced, including console logs, network requests, page transitions, and user interactions, with configurable privacy redaction for sensitive content. Error monitoring automatically groups and deduplicates errors, surfaces affected user sessions, and provides full stack traces with source map support for minified production code. The logging pipeline ingests structured and unstructured logs from any backend service with automatic property extraction, full-text search, and configurable alerting thresholds. Distributed tracing tracks request flows across microservices with embedded links to associated sessions, errors, and logs for complete request lifecycle visibility. The metrics system collects custom application metrics alongside built-in web vitals and performance data for trend analysis and anomaly detection. Search across all telemetry types uses a unified query language with automatic attribute discovery and saved views for recurring investigations. Integrations connect with Slack, Discord, Linear, Jira, Vercel, and dozens of other developer tools for notification routing and workflow automation. SDKs cover React, Next.js, Vue, Angular, Python, Go, Ruby, Java, PHP, and Elixir with framework-specific instrumentation. Self-hosted deployment runs via Docker Compose with ClickHouse for analytics storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Laminar
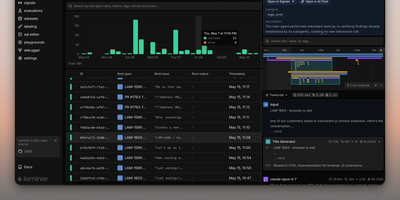
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.