Bifrost
Bifrost is an open-source AI gateway that unifies 23+ LLM providers into a single OpenAI-compatible endpoint with automatic failover, semantic caching, and built-in cost governance, so one provider going down never takes your production AI application with it. Point your existing OpenAI or Anthropic SDK at Bifrost's local endpoint and gain access to OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Groq, Mistral, and Ollama without changing application code. Define fallback chains that automatically switch providers when one returns errors or exceeds latency thresholds, keeping response times stable during outages. The built-in web dashboard at port 8080 lets you configure providers, create virtual API keys, monitor live request traffic, and review analytics without editing configuration files. Semantic caching combines exact hash matching with vector similarity search via Weaviate, serving cached responses for identical or paraphrased prompts in sub-millisecond time to cut costs on repetitive workloads. The MCP gateway connects AI agents to external tools like filesystems, databases, and web APIs, exposing them to clients such as Claude Desktop and Cursor with per-key allow-lists. Four-tier budget hierarchy at customer, team, virtual key, and provider levels enforces spend caps, rate limits, and model restrictions across your organization. Extend functionality through custom Go plugins for analytics, monitoring, or security middleware. Native Prometheus metrics and OpenTelemetry distributed tracing give operations teams full production observability. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
MLflow
Trusted by thousands of organizations with over 30 million monthly downloads and 20,000+ GitHub stars, MLflow is the largest open-source AI engineering platform providing end-to-end lifecycle management for traditional ML models, LLMs, and AI agents. The OpenTelemetry-based tracing system captures complete request flows through any LLM provider or agent framework — including OpenAI, LangChain, DSPy, Vercel AI, PydanticAI, and smolagents — with one-line auto-instrumentation that tracks inputs, outputs, token usage, and costs at every intermediate step. MLflow's evaluation engine offers 50+ built-in metrics and LLM judges for systematic quality assessment, detecting issues across correctness, latency, adherence, relevance, and safety dimensions before code reaches production. The Prompt Registry versions, tests, and deploys prompts with full lineage tracking while automated optimization algorithms improve prompt performance using evaluation feedback. The AI Gateway provides a unified API endpoint for all LLM providers, enforcing rate limits, cost controls, and access policies across the organization. MLflow 3.0 introduces the LoggedModel abstraction linking traces, metrics, and prompts to specific model versions across Python, TypeScript, Java, and R SDKs. The model registry manages deployment workflows with automated quality gates, while experiment tracking records parameters, metrics, and artifacts across training runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
OpenSquilla
Claiming 60-80% token cost reduction compared to flat single-model deployments and backed by 6,500+ GitHub stars, OpenSquilla delivers an intelligent AI agent runtime where a local ML classifier evaluates every turn on message length, code blocks, keyword patterns, and semantic embeddings before routing it to the optimal model tier from C0 through C3. The pluggable provider layer connects natively to TokenRhythm, OpenRouter, OpenAI, Anthropic, Ollama, DeepSeek, Gemini, DashScope, Moonshot, Mistral, Groq, Zhipu, SiliconFlow, vLLM, LM Studio, and additional compatible backends with primary-plus-fallback selection. The four-tier cognitive memory architecture spans working, episodic, semantic, and raw layers with vector-semantic and BM25 retrieval powered by on-device ONNX embeddings that never leave your infrastructure. Security isolation operates at the syscall level via Bubblewrap on Linux and Seatbelt on macOS, complemented by policy-based execution controls and prompt injection protections. The unified TurnRunner executes identically across the Vue-based control console Web UI, terminal CLI, and chat channel integrations including Slack and Discord, ensuring consistent tool dispatch, retry logic, and decision logging regardless of entry point. Built-in skills cover deep research, multi-search-engine queries, document generation for DOCX, PPTX, XLSX, and PDF formats, GitHub integration, cron scheduling, and bounded subagent delegation. Per-agent workspaces with durable session storage provide transcript replay, context state management, and per-call cost tracking with automatic quota enforcement. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Chroma
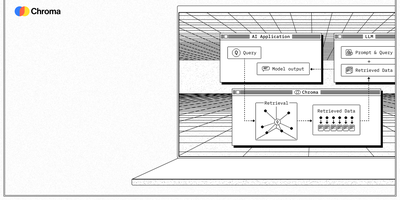
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
InvokeAI
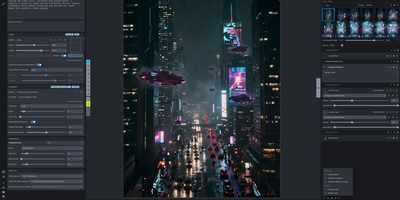
With over 27,500 GitHub stars, 350 contributors, and 220 releases since 2022, InvokeAI delivers an industry-leading creative engine that serves as the foundation for multiple commercial AI art products. The web-based UI supports an extensive model ecosystem including Stable Diffusion 1.5 through 3.5, SDXL, Flux.1 Dev, Flux.1 Schnell, Flux.1 Kontext, Flux.2 Klein 4B and 9B, CogView 4, Z-Image, Anima, and Qwen Image — plus externally-hosted models from OpenAI GPT Image, Google Gemini, BytePlus, and Alibaba Cloud via API key integration. The Unified Canvas provides a fully integrated workspace with in-painting, out-painting, brush tools, layer management, and regional guidance for compositing AI-generated content with existing artwork. The node-based Workflow Editor enables building complex generation pipelines with branching logic, connecting text encoders, VAEs, ControlNets, IP-Adapters, and LoRA weights into reusable graphs. Model management handles automatic downloading from HuggingFace and Civitai with conversion between safetensors, diffusers, and checkpoint formats. The backend runs on Python with CUDA, ROCm, and MPS acceleration supporting NVIDIA, AMD, and Apple Silicon GPUs. Multi-user accounts allow shared access to a single InvokeAI server with per-user galleries and settings. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Gorse
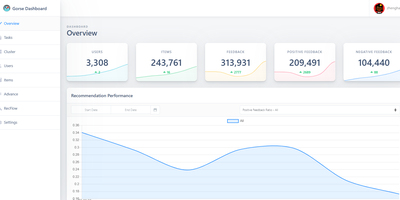
Gorse generates personalized recommendations from your application's user interaction data through automatically trained models, requiring no machine learning expertise to deploy or operate. Over 10,000 GitHub stars and production deployments processing millions of interactions validate a multi-source architecture that merges candidates from latest-item, user-to-user, item-to-item, and collaborative filtering recommenders, then ranks them using factorization machines or LLM-based rerankers with configurable query and document templates. Multimodal content support processes text, images, and video metadata via embedding vectors stored in BF16 format, with optional Qdrant, Weaviate, or Milvus integration for distributed similarity search. The visual RecFlow editor provides a drag-and-drop interface for designing recommendation pipelines, connecting data sources to recommenders and rankers without writing configuration files. A distributed cluster separates concerns across master nodes for model training and dashboard hosting, worker nodes for offline recommendation generation, and server nodes for real-time API endpoints, all scaling horizontally behind load balancers. Online evaluation analyzes recommendation quality from recent user feedback with configurable cache sizes and expiration intervals. RESTful APIs expose CRUD endpoints for users, items, and feedback alongside recommendation retrieval with category filters and API key authentication. Stores data in MySQL, PostgreSQL, MongoDB, or ClickHouse with Redis caching. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
MindsHub
Backed by $50M+ from Benchmark, Y Combinator, and NVIDIA with 800+ contributors and 39,000+ GitHub stars, MindsHub Cowork is the unified AI workspace where open-source models handle entire projects — research, reporting, internal tools, scheduled operations — and return finished, shareable deliverables. The platform runs two interchangeable open-source agent harnesses, Anton and Hermes, swappable from a dropdown without losing context. A built-in Model Router pre-wires 25+ models spanning Anthropic Claude, OpenAI GPT, Google Gemini, DeepSeek, Qwen, Kimi, Grok, and MindsHub Air with automatic failover — no per-provider API keys required. A secure credentials vault connects BigQuery, PostgreSQL, Salesforce, HubSpot, Zendesk, Gong, Gmail, Google Drive, Notion, Linear, Stripe, and Slack, keeping secrets scoped per connection so agents never see raw keys. Agent output becomes publishable artifacts — documents, dashboards, apps, and code — each deployable to a live shareable URL. Cross-session persistent memory, a reusable skill library, and a background scheduler supporting hourly, daily, and weekly cadences enable autonomous recurring workflows. The architecture separates a React/Vite frontend (shipping as both Electron desktop app and web SPA) from a FastAPI backend with a versioned REST API at /api/v1 covering conversations, projects, artifacts, schedules, and connectors. Self-host via Docker Compose with nginx on port 3000 and the API on port 26866, or deploy on-prem, in a VPC, or air-gapped. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MindsDB
Backed by 39,500+ GitHub stars and over 339 releases, MindsDB delivers the open-source federated query engine that gives AI agents a single SQL interface to read, join, and aggregate across 200+ live data sources without any ETL pipelines or data movement. The Connect-Unify-Respond architecture wires up Postgres, MySQL, MongoDB, Snowflake, BigQuery, ClickHouse, Redshift, Databricks, Salesforce, Shopify, Slack, S3, GCS, Azure Blob, and dozens more through self-contained Python handler packages merged in the open from the community. Knowledge Bases fuse structured tables with vectorized unstructured data from PDFs, emails, support tickets, and documents using hybrid search combining vector similarity with keyword matching for retrieval-augmented generation. Jobs execute queries on configurable schedules refreshing Knowledge Bases nightly or syncing derived tables hourly, while Triggers fire on data changes to automatically vectorize new rows into the appropriate store. The SQL-compatible query language extends standard SQL with constructs for creating models, defining agents, managing workflows, and searching unstructured data. The built-in web editor at port 47334 provides interactive SQL authoring, while the MySQL-compatible API at port 47335 and PostgreSQL API at port 47336 connect any database client directly. An MCP Server integration exposes MindsDB to AI assistants, and the Python SDK enables programmatic access from application code. Docker deployment runs with a single command exposing all APIs immediately. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Langfuse
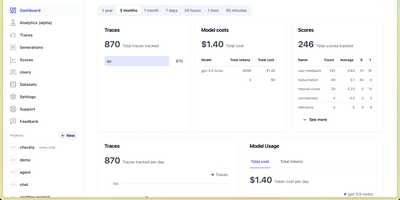
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Crawl4AI
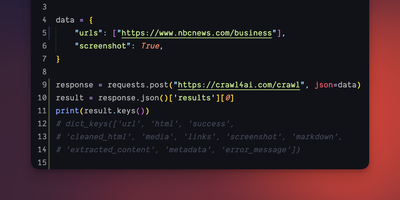
With over 77,000 GitHub stars, Crawl4AI is the most-starred open-source web crawler on GitHub and the go-to tool for converting the web into AI-ready data. Built on Python and Playwright, it transforms any website into clean Markdown with headings, tables, code blocks, and citation hints optimized for LLM ingestion, or extracts structured JSON via CSS selectors, XPath expressions, or direct LLM-based schema extraction through OpenAI, Anthropic, and Ollama providers. The self-hosted Docker server exposes a REST API on port 11235 with endpoints for crawling, streaming results, screenshots, PDF generation, JavaScript execution, and LLM-powered extraction. Version 0.9.x introduced secure-by-default operation with mandatory JWT authentication, strict request validation, declarative hooks replacing inline code, and bounded job queues. Adaptive crawling uses information foraging algorithms to determine when sufficient data has been gathered, while deep crawl mode traverses link graphs intelligently. The async browser pool manages concurrent sessions with stealth plugins, proxy rotation, custom headers, and session persistence for authenticated scraping. A built-in MCP server enables direct integration with Claude, ChatGPT, and Cursor for AI-driven web research workflows. Content filtering applies BM25 and TF-IDF relevance scoring to extract only pertinent sections from noisy pages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Kokoro FastAPI
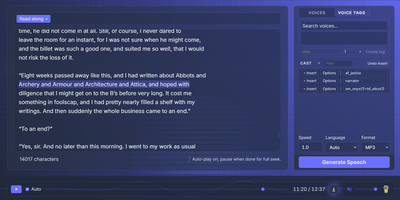
Kokoro-FastAPI turns text into natural-sounding speech across eight languages by serving the 82-million-parameter Kokoro-82M model through an OpenAI-compatible REST API, so any existing OpenAI SDK client can generate audio by just changing the base URL. With over 5,300 GitHub stars since December 2024, the fully Dockerized FastAPI server covers American English, British English, Spanish, French, Hindi, Italian, Japanese, Brazilian Portuguese, and Mandarin Chinese with language-specific phoneme processing. Inline voice mixing blends multiple profiles using weighted ratios like af_bella(2)+af_heart(1), automatically normalizing weights and caching combined voicepacks as PyTorch tensor files for reuse. Audio streams in real time over HTTP with configurable chunk sizes, or generates complete files in MP3, WAV, OPUS, FLAC, AAC, or PCM formats with speed control from 0.25x to 4.0x. Per-word timestamped captions with speaker-tagged voice labels enable subtitle generation for podcasts, audiobooks, and accessibility workflows. Pre-built Docker images support NVIDIA GPU acceleration via CUDA, experimental AMD GPU inference via ROCm, and CPU-only deployment on linux/amd64 and linux/arm64 architectures, with Apple Silicon MPS support available through direct UV execution. The integrated web interface at port 8880 provides browser-based speech generation, while the Swagger UI at /docs exposes the full API reference. Debug endpoints report system statistics for monitoring inference load. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Cognee
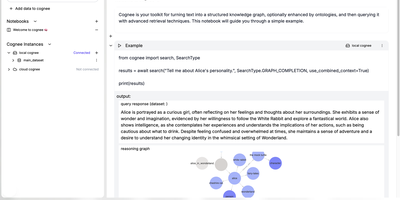
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Inference Gateway
Inference Gateway puts a single OpenAI-compatible API endpoint in front of OpenAI, Anthropic, Groq, Cohere, Ollama, DeepSeek, Google, Mistral, MiniMax, Moonshot, Nvidia, and llama.cpp, so your application code never changes when you switch models or providers. The Go binary starts on port 8080 and normalizes authentication, streaming protocols, and response formats across all backends transparently. Native Model Context Protocol support auto-discovers tools from connected MCP servers and injects them into LLM requests without client-side management, enabling server-side tool execution across any provider that supports function calling. Agent-to-Agent protocol integration allows distributed agent communication through a declarative Agent Definition Language that generates production-ready Go or Rust servers from a single YAML manifest. The dedicated Kubernetes Operator manages Gateway, Agent, MCP, and Orchestrator custom resources with automatic HPA scaling, OIDC authentication, and service discovery that rebuilds MCP configurations when the discovered server set changes. Prometheus metrics and OpenTelemetry tracing provide full request-level observability across the entire inference pipeline. Middleware controls enable per-request provider selection, model routing, and fallback strategies. Official SDKs in Go, Python, TypeScript, and Rust provide typed client interfaces with streaming support. Docker Compose deployment requires only environment variables for API keys. A CNCF Sandbox applicant. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
SD WebUI Forge
With 12,800 GitHub stars and backing from the same developer who created ControlNet, Stable Diffusion WebUI Forge replaces Automatic1111's inference backend with a dynamic GPU memory management system that runs SDXL 30-75% faster while consuming significantly less VRAM — enabling 1024x1024 generation on 6GB cards where A1111 requires 8GB or more. The Gradio 4 interface provides txt2img, img2img, inpainting, and outpainting workflows with a Forge Canvas supporting pressure-sensitive input from Wacom tablets and Microsoft Surface devices. Native Flux.1 model support loads Flux Dev and Schnell checkpoints using BitsandBytes NF4 and FP8 quantization for deployment on consumer GPUs without model splitting. Built-in ControlNet integration includes all preprocessors — Canny, Depth, Normal, OpenPose, MLSD, Scribble, Segmentation, Tile, and IP-Adapter — without requiring separate extension installation. The extension ecosystem maintains full compatibility with popular Automatic1111 extensions including Adetailer for face enhancement, After Detailer, Regional Prompter, and Dynamic Prompts. LoRA loading supports standard, LyCORIS, and DoRA formats with automatic weight detection. The API provides RESTful endpoints for txt2img, img2img, extra single/batch processing, and progress monitoring enabling headless batch generation. Deploy via one-click installer package, Python virtual environment, or Docker with NVIDIA GPU passthrough. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LiteLLM
Backed by 56,000+ GitHub stars and over 240 million Docker pulls, LiteLLM delivers the open-source AI gateway trusted by Netflix, Lemonade, Rocket Money, and thousands of engineering teams to route every LLM request through one unified API. The Rust-core gateway adds sub-millisecond overhead per request with 8ms P95 latency at 1,000 RPS, 15x throughput improvement and 11x lower memory footprint compared to Python-only proxies. A single OpenAI-compatible endpoint connects to 100+ providers and 1,800+ models spanning OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure OpenAI, Vertex AI, Hugging Face, vLLM, Nvidia NIM, Ollama, and Mistral with day-zero support for new model releases. The Auto Router V2 classifies request complexity across four tiers using rule-based scoring, semantic keyword matching, and adaptive Thompson sampling to route each request to the most cost-effective model without API calls or training data. Virtual API keys enable multi-tenant governance with per-team, per-user, and per-project cost tracking, budget caps with automatic fallback rerouting, and role-based access control. Built-in guardrails provide PII masking, prompt injection detection, and model-graded evaluation before requests reach providers. The Agent Gateway extends routing from model calls to agent workflows with MCP server integration. Observability integrates with Langfuse, Arize Phoenix, OpenTelemetry, and MLflow for complete request tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Laminar
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Paperclip
With over 77,000 GitHub stars accumulated in under five months since its March 2026 launch, Paperclip has become the default control plane for teams running multiple AI agents in production. Rather than juggling dozens of terminal tabs with Claude Code sessions, Codex instances, and Gemini CLI workers, Paperclip organizes all agents into a company structure with org charts, reporting lines, role-based permissions, and per-agent monthly budgets that trigger hard-stops when exceeded. The platform supports any runtime through its adapter system — Process adapters manage local CLI agents like Claude Code, Codex, Cursor, Pi, and OpenCode as child processes, while HTTP adapters trigger remote agents via webhooks to OpenClaw, serverless platforms, or custom endpoints. Heartbeat-based execution wakes agents on configurable schedules, injecting goal context, budget state, and workspace paths directly into the invocation payload. The Work and Task System provides atomic checkout with execution locks, first-class blocker dependencies, and structured work products to eliminate duplicate effort. Governance features include approval workflows, decision tracking, emergency stops, and full audit trails tracing every mutation to an actor. Deployment runs as a single Node.js process with embedded PostgreSQL locally or scales to external Postgres for production, installable in one command via npx paperclipai onboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenSearch
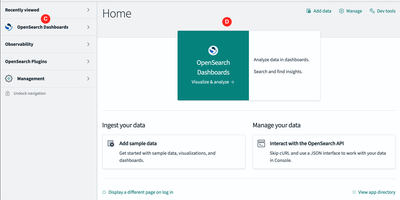
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.