Utopia
The first open-source substrate for enterprise knowledge engineering that learns passively and governs itself. The Rust-built backend paired with PostgreSQL and pgvector delivers a bitemporal knowledge graph where every fact carries two timelines: when it held in the real world and when the system came to believe it — enabling full audit trail replay of how understanding evolved. Document ingestion handles PDF, DOCX, PPTX, XLSX, CSV, Markdown, HTML, and plain text with legacy encoding detection, while scheduled syncing pulls from web pages, RSS feeds, GitHub, Jira, Notion, WebDAV, and S3-compatible buckets. Search fuses Tantivy full-text indexing with pgvector semantic vectors using Reciprocal Rank Fusion, streaming answers with inline citations that link directly to source passages. The built-in agent harness drives agentic RAG through conversation — searching documents, walking the knowledge graph at any historical date, and querying mounted databases via Ontology2SQL which achieves state-of-the-art results on BIRD Mini-Dev benchmarks. Five ontology packs ship inside the binary (schema.org, W3C Org, PROV-O, FOAF, IOF Core) with forward-chaining reasoning for transitivity, symmetry, inverses, and relation hierarchy. Entity resolution operates in three stages: exact name matching, embedding similarity, then model-based judgment with every merge reversible. Any OpenAI-compatible endpoint works including DeepSeek, Qwen, Ollama, and vLLM for fully air-gapped deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Khoj
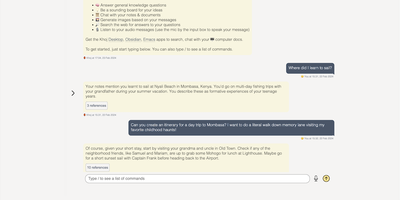
A self-hosted "second brain": Khoj indexes your own files and answers questions from them, parsing Markdown (whole Obsidian vaults included), org-mode, PDF, Word, plain text, Notion pages, GitHub repositories, and images described by a vision model, then embedding everything with sentence-transformers into a vector index for semantic search and RAG with cited sources. Any LLM backend works: local models like Llama, Qwen, or Mistral via Ollama, or cloud models like GPT, Claude, and Gemini. You can build custom agents, each with its own persona, scoped knowledge base, chat model, and tools such as web search and code execution. Scheduled automations run recurring research and deliver newsletters or notifications to your inbox, and research mode performs multi-hop web searches with inline citations. Access it from a browser, the Obsidian plugin, Emacs, desktop, or WhatsApp - all clients connect to the same self-hosted instance, making Khoj one of the few AI assistants Emacs users can point at decades of org files. Semantic search means recall works without exact keywords: "that paper about forecasting with transformers" surfaces the right PDF even when you cannot remember its title. Switching LLM backends never requires re-indexing your documents, and with a local model via Ollama, even inference stays on hardware you control - journals, research, and private notes are never sent anywhere. Python/FastAPI stack, AGPL-licensed, with PostgreSQL storage.
DeepTutor
With 34,000+ GitHub stars and a v1.5 release driven by 36 merged community pull requests, DeepTutor from Hong Kong University's Data Science Lab delivers a full agent-native learning workspace that goes far beyond chatbot wrappers. Eight integrated surfaces — Chat, Deep Solve, Quiz Generation, Deep Research, Math Animator, Co-Writer, Book generation, and Mastery Practice — share a unified context so the objective follows the learner, not the tool. The platform's three-layer memory architecture (L1 working, L2 session, L3 long-term) makes personalization inspectable rather than opaque, letting users see exactly what the system remembers and why. Knowledge retrieval operates across five pluggable engines — LlamaIndex with FAISS vectors, PageIndex for page-level citations, GraphRAG for knowledge-graph traversal, LightRAG for local or server-offloaded retrieval, and linked Obsidian vaults — with document parsing via MinerU, Docling, markitdown, or PyMuPDF4LLM. Partners extend the tutoring brain to 15+ messaging platforms including Slack, Discord, Telegram, Matrix with E2EE, and Mattermost, each carrying private memory with branch, resume, and replay capabilities. Subagent integration brings Claude Code, Codex, Gemini, and Kimi directly into learning sessions. The system supports 30+ LLM providers from OpenAI and Anthropic to Ollama for fully local operation, with multi-user isolation, admin controls, and a full CLI interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Open Notebook
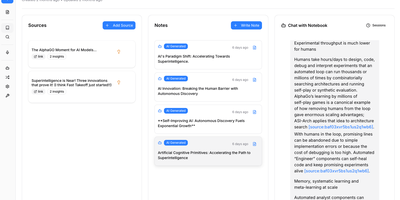
The most feature-complete open-source alternative to Google's NotebookLM — a self-hosted research platform where you upload PDFs, videos, audio files, and web pages into organized notebooks, then chat with your content, generate multi-speaker podcasts, and run semantic search across everything without sending a single byte to Google's servers. The podcast engine supports 1-4 fully customizable speakers with backstories, personalities, and expertise profiles, generating professional audio dialogue through OpenAI, ElevenLabs, Google TTS, or completely local text-to-speech via Kokoro for maximum privacy. Content processing uses token-based chunking with RAG-powered retrieval grounded in your uploaded sources, while both full-text keyword search and semantic vector search via SurrealDB enable conceptual discovery across all notebooks. The 18+ supported AI providers include OpenAI, Anthropic, Google Gemini, Groq, Ollama, LM Studio, and more — configurable per task so you can route cheap models to summarization and powerful models to analysis. Content transformations extract insights, generate summaries, create study guides, and produce structured outputs from any source material. The MCP integration connects Open Notebook to Claude Desktop, VS Code, and other MCP clients for seamless workflow integration. A full REST API on port 5055 enables complete automation of notebook management, source upload, and podcast generation. Deploy via Docker Compose with the application container, SurrealDB v2 on RocksDB, and optional TTS containers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Trilium Notes
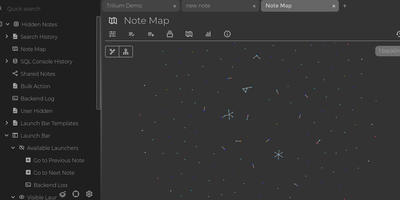
For people whose notes number in the tens of thousands, Trilium Notes is the hierarchical note-taking application built specifically for large personal knowledge bases - actively maintained as TriliumNext. Notes arrange into arbitrarily deep trees where every note is both content and container, and cloning lets a single note live in multiple places at once - bash notes belong under both Linux and Scripting, and Trilium refuses to make you choose. A WYSIWYG editor handles rich text, tables, math, and syntax-highlighted code blocks with Markdown-style shortcuts, while dedicated note types cover Excalidraw sketches, mind maps, geo maps with GPX tracks, relation maps that visualize connections between notes, and tables with typed columns. The attribute system is the power layer: labels attach queryable metadata (#year=1999, #author), relations create named links between notes, and both inherit down the tree - feeding full-text search, saved queries, and scripting. Scripting is Trilium's deepest differentiator: JavaScript code notes run on events like note changes or hourly schedules, build custom widgets, and add server-side logic, turning the knowledge base into a programmable platform. Protected notes encrypt sensitive content, note hoisting focuses on subtrees, and the self-hosted server syncs desktop clients across devices.
LinkWarden
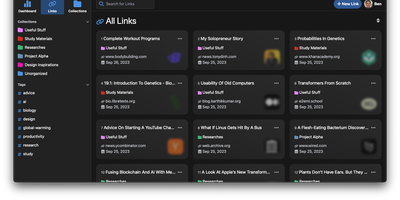
Links rot - the hard truth Linkwarden is built around, as a collaborative bookmark manager that preserves what it saves. Every page you save is fully preserved - a screenshot, a PDF, a self-contained single-file HTML archive (generated by the Monolith Rust binary), and a clean reader view - so the content survives even after the original site disappears. Think of it as a private Wayback Machine you own, with an optional one-click snapshot to archive.org on top. The reading experience matches the archival rigor: a distraction- free reader view supports text highlighting and annotation, and full-text search across everything you have saved is powered by Meilisearch. Optional AI tagging analyzes page content and auto-assigns tags - generate new ones, pick from your existing set, or constrain to predefined tags - with providers ranging from local Ollama models (fully private) to OpenAI, Anthropic, and OpenRouter. Organization is collections, sub-collections, and multiple tags per link; teams collaborate on shared collections with per-member permissions, and public collections share curated link sets (with preserved copies) to anyone. The stack is Next.js/React on TypeScript with PostgreSQL via Prisma, NextAuth supporting credentials, OAuth2, and SAML SSO, and a Playwright-driven headless Chromium worker doing the capture. Native iOS and Android apps and browser extensions feed it from anywhere.
Siftly
Siftly transforms your Twitter/X bookmarks from a chaotic pile of saved tweets into a searchable, AI-categorized knowledge base with an interactive visual mindmap. With over 2,700 GitHub stars since March 2026, the platform runs a four-stage enrichment pipeline on each bookmark: entity extraction mines hashtags, URLs, @mentions, and 100+ known tool domains without API calls; vision analysis generates 30-40 visual tags per image using the Anthropic SDK; semantic tagging produces 25-35 searchable descriptors; and categorization assigns one to three categories with confidence scores. Search combines SQLite FTS5 full-text indexing with Claude-based semantic reranking, narrowing candidates through keyword matching, category-intent detection, and deduplication before sending a bounded set for LLM relevance scoring, letting you find bookmarks by meaning rather than exact keywords. The interactive mindmap built on @xyflow/react renders your entire collection as a force-directed graph organized by category with expandable nodes, color-coded legends, and direct links to original tweets. Import bookmarks through a built-in bookmarklet or console script without browser extensions, then browse in grid or list view with filters for category, media type, and date range. Export as CSV, JSON, or category-grouped ZIP archives. Prisma 7 manages the local SQLite database with FTS5 built in, requiring zero external database setup. A bundled CLI provides JSON-output commands for stats, search, and category management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Wallabag
With 12,800+ GitHub stars and over a decade of active development since 2013, wallabag is the most established open-source read-it-later application — built for readers who want complete ownership of their article archive without depending on services that shut down (RIP Pocket). The Symfony-based PHP application extracts clean article content using Graby and php-readability, stripping advertisements, pop-ups, and tracking scripts to deliver a distraction-free reading experience optimized for both desktop and mobile screens. Save articles via Chrome, Firefox, or Safari browser extensions, Android and iOS native apps, REST API, or the built-in bookmarklet — all syncing to your self-hosted instance. Organize your library with tags, automated tagging rules that classify articles by content patterns, starred favorites, and archived collections. The annotation system enables highlighting extracts and attaching notes directly within articles for research and reference workflows. Import your existing reading lists from Pocket, Omnivore, Instapaper, Pinboard, Readability, and browser bookmarks. Export articles in PDF, ePUB, MOBI, JSON, CSV, TXT, or HTML for offline reading on Kindle, Kobo, and other e-readers. Full-text search with filters by reading time, domain, language, and creation date makes retrieval instant across thousands of saved articles. RSS feed output integrates with feed readers and automation services. Docker deployment with SQLite, MySQL, or PostgreSQL persistence backends takes under five minutes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hoarder
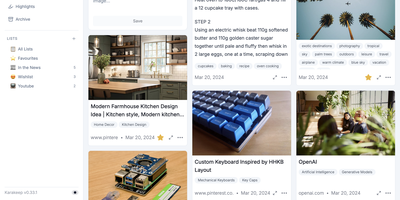
Hoarder (now Karakeep) is a bookmark manager that actually fights link rot: every page you save gets archived at capture time using Monolith, so the content survives even when the original URL dies. Beyond archival, an AI layer powered by OpenAI or local Ollama models auto-tags everything by analyzing page content. Prefer full privacy? Ollama keeps all inference on your server with zero external API calls. Full-text search through Meilisearch indexes the actual scraped content of every bookmark, not just titles and tags, so you find articles by what they say rather than labels you half-remember. Save links with automatic metadata extraction, plain text notes, uploaded images, and PDF documents, all organized into shareable lists with collaborative access. Browser extensions for Chrome and Firefox make saving a one-click operation from any page. Migrating is painless with importers for Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. LLM summarization condenses saved pages into brief overviews for quick scanning. The AI layer is entirely optional: Hoarder works perfectly as a manual bookmark manager, with intelligence adding convenience rather than imposing a requirement. SSO integration and responsive dark mode round out the package.
Usermemos
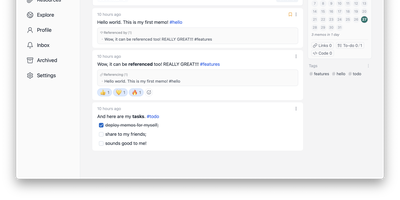
Memos, the lightweight open-source note service from the usememos project, packaged as a containerized deployment for multi-architecture Docker hosts (x86-64 and arm64): that is Usermemos. The model is frictionless capture: no folders or titles, just a chronological stream of Markdown notes with code blocks, task lists, tables, and file attachments, organized by #hashtags pulled automatically from the text. Per-memo visibility - private, protected for logged-in users, or public - lets a single instance serve as a personal journal, a shared team log, or a public microblog simultaneously. Multi-user support with authentication makes it workable for small teams, and full REST and gRPC APIs open capture and retrieval to CLIs, bots, and automation tools. The runtime is a single Go binary with a React frontend that idles around 50 MB of memory and stores content as plain Markdown in SQLite by default, with MySQL and PostgreSQL available for heavier deployments. Configuration happens through environment variables, access works over HTTP or HTTPS behind a reverse proxy, and there is no telemetry - notes stay on your server in a portable format.
Grimoire
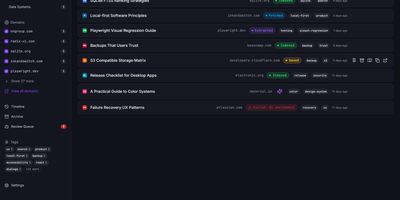
Grimoire captures, extracts, and indexes the content behind your bookmarks so you can search what pages actually say, not just their titles and URLs. The ingestion pipeline accepts links from the web UI, REST API, MCP server, browser bookmarklet, or bulk import, then fetches each page and extracts readable content using specialized parsers for GitHub repos, GitHub issues, StackOverflow threads, YouTube transcripts, PDFs, and standard web articles. Everything stores locally in SQLite with file-based content archives. Search operates in three modes: FTS5 keyword matching for exact terms, semantic embedding search for meaning-based retrieval using vector similarity, or a hybrid ranking mode combining both. Optional AI providers including OpenAI, Ollama, Anthropic, DeepSeek, and any OpenAI-compatible endpoint generate automatic tags, summaries, and embeddings without being required for core functionality. The interface built with React 18, Vite, TypeScript, Tailwind CSS, and Radix UI supports categories, nested tags, notes, archive and trash states, read-later flags, and multi-user isolated spaces. A single Bun-powered Hono process serves both the compiled frontend and the REST API on port 3210, requiring only one Docker container and a SQLite volume. Backup and restore export bookmarks, content, settings, and metadata as portable ZIP archives. Nearly 3,000 GitHub stars reflect growing adoption among developers and researchers. Running on a VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Logseq
Every line an indentable bullet, every bullet a first-class block that can be referenced, embedded, and queried anywhere: Logseq is a privacy-first, local-first knowledge platform built around the block outliner. The daily journal is the system's beating heart - each day opens a fresh date-stamped page where tasks, meeting notes, and fleeting ideas land as blocks without filing decisions, then connect later through [[wikilinks]] with automatic bidirectional backlinks and ((block references)) that transclude any bullet into any page. Everything persists as plain Markdown or Org-mode files on disk - git-friendly, greppable, and owned forever, with sync via iCloud, Dropbox, Syncthing, Git, or an optional end-to-end encrypted service. Built-in tooling goes beyond notes: TODO/DOING task states with scheduling, native PDF annotation with area highlights, spaced-repetition flashcards, whiteboards for visual thinking, Zotero integration for researchers, and Datalog-powered queries that build dynamic views across the entire graph. A marketplace of hundreds of community plugins and themes adds AI chat, Ollama local-model integration, and custom workflows. Written in Clojure/ClojureScript, AGPL-3.0 licensed with 320+ contributors, and completely free - the local-first Roam for people who refuse subscriptions and lock-in.
AppFlowy
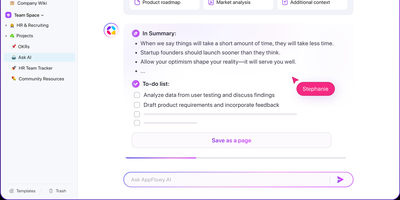
With over 75,000 GitHub stars and native apps across macOS, Windows, Linux, iOS, and Android, AppFlowy is the most widely adopted open-source alternative to Notion — delivering the same block-based workspace model with full data sovereignty. The Flutter frontend renders natively on every platform while a Rust backend powered by Actix-web and Tokio handles CRDT-based real-time collaboration, ensuring sub-second sync across devices with conflict-free concurrent editing. Relational databases support grid, board, kanban, calendar, and gallery views over the same dataset, with two-way relations, rollups, advanced filters, sorts, and formula calculations that cover the majority of Notion's database workflows. The block editor supports 40+ content types including nested pages, toggles, callouts, code blocks with syntax highlighting, embeds, and slash-command insertion. AI integration connects to OpenAI, Anthropic, or local models via Ollama for writing assistance, summarization, and translation — all without sending data off-premises when using on-prem LLMs. Team spaces with workspace-level and per-page permissions, OAuth and SSO authentication through GoTrue, and S3-compatible object storage via MinIO provide enterprise-grade access control and file management. The self-hosted stack deploys through Docker Compose with PostgreSQL for metadata, Redis for caching and pub/sub, and a dedicated background worker for imports and email notifications. Offline-first architecture ensures the desktop app functions without connectivity, syncing changes when the connection resumes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Documize
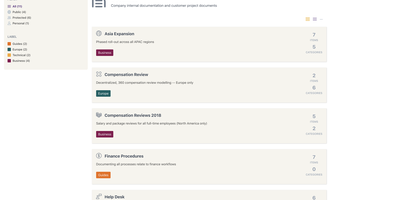
Enterprise documentation discipline without enterprise infrastructure: Documize Community is the Confluence alternative built on exactly that trade. The entire platform - Go backend, Ember.js frontend - compiles to a single executable binary for Linux, Windows, and macOS with zero runtime dependencies: no Elasticsearch, no Redis, no JVM. Point it at PostgreSQL, MySQL, MariaDB, Percona, or Microsoft SQL Server (rare in open source, decisive in Microsoft shops), and schema migrations run on launch with native full-text search on whichever engine you chose. Content organization rejects nested-folder sprawl for Spaces, categories, and labels, and the section-based composable editor mixes rich text, Markdown, code blocks, PDFs, diagrams, and embedded Jira or Trello content in one document, with reusable blocks and templates so teams start from standards rather than blank pages. It deliberately unifies internal team docs and customer-facing documentation in one system with granular space-, document-, and action-level permissions deciding who sees what. Where wikis stop, Documize continues: content approval workflows (draft, review, approve, publish), version management, lifecycle control, feedback capture, PDF export, analytics showing what gets read and ignored, activity streams, and audit logs. Keycloak, LDAP, and SSO integrate for enterprise auth. AGPL-licensed.
Tiddlywiki
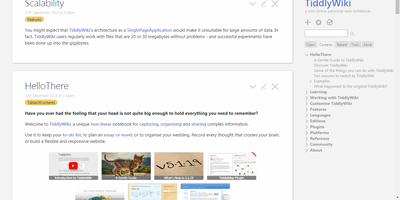
The entire wiki - content, code, and interface - is built from "tiddlers," small addressable units of information that link, transclude, tag, and filter into each other: TiddlyWiki is a non-linear personal notebook with a design philosophy unlike anything else in this catalog. Instead of pages in a hierarchy, you compose views by pulling tiddlers together on demand, which is why researchers, zettelkasten practitioners, and GTD devotees have sworn by it for two decades. The whole application is JavaScript, and the UI itself is written in hackable WikiText - customization goes as deep as rewriting the interface from inside the wiki. Self-hosting runs the Node.js version, which upgrades the classic single-HTML-file architecture in the ways that matter for a server: every tiddler is stored as an individual text file (Git-friendly, organizable), edits save through the HTTP API from any modern browser including phones, and one installation can serve multiple wikis blending shared and unique content. The plugin ecosystem covers graph visualizations, themes, languages, and hundreds of community extensions, declared per-wiki in a simple tiddlywiki.info file; the newer MultiWikiServer plugin adds multi-user accounts and tiddler sharing. Your notes stay usable for decades, independent of any corporation - the project's founding promise. BSD-licensed.
Shaarli
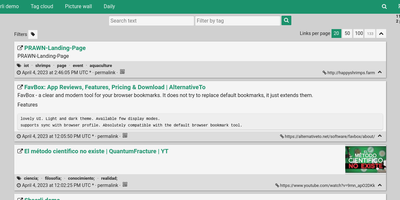
Personal, minimalist, database-free bookmarking - Shaarli is a philosophy as much as an app. Everything lives in a single compressed datastore file inside data/: no MySQL, no PostgreSQL, backup by copying one directory. That write-once/read-many file is usually served straight from OS disk caches, which is why a decade-old Shaarli instance with tens of thousands of links still responds instantly. Designed deliberately single-user, it saves URL, title, unlimited-length description, and tags (with autocomplete, renaming, and merging), marks entries public or private, and automatically strips utm_source and fb tracking parameters from saved URLs. That description field is why the community uses Shaarli as far more than bookmarks: a microblog, read-it-later queue, code-snippet base, pastebin, and shared clipboard between machines. Sharing is one click via bookmarklet or Android apps; consumption is per-tag RSS/Atom feeds plus a daily digest feed; search is full-text with tag filtering. A REST API opens it to any client, a plugin and theme system extends the PHP core (Markdown rendering, thumbnails), and import/export uses browser-standard Netscape HTML - your data enters and leaves freely. LDAP login is supported, no telemetry is sent anywhere, and the UI degrades gracefully without JavaScript. The anti-cloud Delicious.
Affine Pro
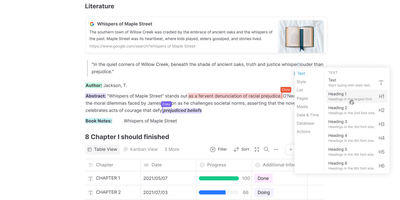
Gaining over 71,000 GitHub stars as one of the fastest-rising knowledge management platforms, AFFiNE merges the document editing capabilities of Notion, the infinite canvas of Miro, and the structured data of Airtable into a single cohesive workspace. The block-based editor built on the custom BlockSuite framework supports rich text, code blocks, embeds, tables, kanban boards, and database views with drag-and-drop composition. The whiteboard mode provides an infinite canvas where users can freely mix documents, sticky notes, shapes, connectors, and hand-drawn elements, enabling visual thinking alongside structured note-taking. Real-time collaboration allows multiple users to edit documents and whiteboards simultaneously with cursor presence, comment threads, and version history. The local-first architecture stores all data on your device by default using CRDT-based synchronization, ensuring offline access and data sovereignty, with optional cloud sync for cross-device availability. Workspaces organize content into hierarchical page trees with full-text search, favorites, tags, and trash management. The platform supports Markdown import and export, PDF export, and HTML export for interoperability. AI features powered by configurable LLM providers enable writing assistance, summarization, translation, and content generation directly within documents. The theming system supports light and dark modes with customizable accent colors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Licensed under MIT with an open-source self-hosted edition.
Faved
Large link collections stay fast and organized in Faved, a private, self-hosted bookmark manager built for exactly that job. Its core is a nested tagging system that outgrows flat folders: place Go and Python under Programming Languages, color-code tags, add descriptions, pin frequent ones to the top of the sidebar, and optionally roll up child-tag items into parent views. Saving is frictionless - a lightweight bookmarklet works in any desktop or mobile browser without extensions, and Apple devices can send links through the native Share menu. Faved fetches titles, descriptions, and preview images automatically, keeps that metadata fresh over time, and flags duplicates as you save. Instant as-you-type search, flexible sorting, and bulk actions (retag, delete, refetch) keep collections of any size manageable, while customizable layouts - card, list, or table - plus a system-synced dark mode adapt the interface to your workflow. Migration is first-class: import from Chrome, Safari, Firefox, or Edge with folder structure preserved, or move from Pocket and Raindrop.io keeping tags and collections. The stack is deliberately light - PHP 8 with SQLite behind a React/Tailwind frontend - deploying via Docker with no external dependencies. All data stays local: no ads, no tracking, and no risk of your library vanishing with a discontinued service.